Showing posts with label developer-experience. Show all posts

Wednesday, April 15, 2026

Platform Engineering in 2026: Internal Developer Platforms, Backstage, and the Golden Path

Hero: Platform engineering topology diagram showing IDP between developers and infrastructure

There's a pattern that repeats across every organization that scales past 50 engineers: infrastructure becomes a full-time job for product developers. Kubernetes YAML sprawls across repositories. Every team builds their own deployment pipeline. New engineers spend their first month asking "where do I find the runbook for X?" instead of writing features.

Platform engineering is the discipline that solves this. It treats the developer experience as a product — building internal tools, golden paths, and self-service infrastructure so that application developers can deploy, monitor, and operate their services without becoming Kubernetes experts. In 2026, platform engineering has moved from Google/Netflix-scale concern to the standard approach for any organization running more than 10 microservices.

The Problem: Infrastructure as a Blocker

The anti-pattern looks like this: a DevOps team manages Kubernetes, Terraform, CI/CD pipelines, and observability. Every new service requires a ticket to that team. The DevOps team becomes a bottleneck — they're constantly firefighting and can't keep up with service requests. Developers wait days for environment provisioning. Senior engineers spend 20% of their time on infrastructure they shouldn't need to touch.

The cognitive load compounds. A developer who wants to ship a feature must understand: Docker build, Kubernetes manifests, Helm charts, ArgoCD sync, Prometheus alerts, PagerDuty routing, VPC networking, IAM policies. Each of these is a separate expertise domain.

graph LR subgraph "Without Platform Engineering" D1[Dev Team A] -->|"ticket: new service"| O[Ops/DevOps Team] D2[Dev Team B] -->|"ticket: env provision"| O D3[Dev Team C] -->|"ticket: alert setup"| O O --> I[Infrastructure] O -.->|bottleneck| O end

Platform engineering inverts this: the platform team builds self-service capabilities, and application teams use them.

graph LR subgraph "With Platform Engineering" D1[Dev Team A] --> P[Internal Developer Platform] D2[Dev Team B] --> P D3[Dev Team C] --> P P --> I[Infrastructure\nKubernetes, Cloud, CI/CD] PT[Platform Team] -->|builds + operates| P end

The platform team builds once; application teams move fast.

How It Works: The Three Layers

A mature IDP has three layers:

1. Infrastructure Layer: The actual compute, networking, and storage. Kubernetes clusters, cloud accounts, databases. The platform team owns this.

2. Platform Services Layer: Standardized abstractions over infrastructure. Deployment pipelines, secrets management, observability stack, service mesh. Application teams don't configure these directly — they use them through the platform.

3. Developer Interface Layer: The self-service portal, CLI, and documentation that application teams interact with. Backstage is the most common implementation of this layer.

graph TD A[Developer Interface\nBackstage, CLI, Docs] --> B[Platform Services\nCI/CD, Secrets, Observability, Service Mesh] B --> C[Infrastructure\nKubernetes, Cloud, Databases] D[Application Developer] -->|self-service| A E[Platform Team] -->|builds + operates| B E -->|manages| C style A fill:#3b82f6,color:#fff style B fill:#8b5cf6,color:#fff style C fill:#6b7280,color:#fff

Implementation: Building with Backstage

Backstage, open-sourced by Spotify and now a CNCF project, is the most widely adopted IDP frontend. It provides a software catalog, scaffolding templates, and plugin framework.

Setting Up Backstage

# Scaffold a new Backstage app
npx @backstage/create-app@latest --skip-install
cd my-backstage-app
yarn install

# Start dev mode
yarn dev
# → http://localhost:3000

The core concept is the Software Catalog — a centralized registry of all services, APIs, libraries, and infrastructure components. Each component is described by a catalog-info.yaml:

# catalog-info.yaml (checked into each service repo)
apiVersion: backstage.io/v1alpha1
kind: Component
metadata:
  name: payments-service
  description: Processes payment transactions via Stripe
  annotations:
    github.com/project-slug: myorg/payments-service
    backstage.io/techdocs-ref: dir:.
    pagerduty.com/service-id: P123ABC
    prometheus.io/rule: sum(rate(http_requests_total{service="payments"}[5m]))
  tags:
    - payments
    - critical
    - python
  links:
    - url: https://grafana.internal/d/payments
      title: Grafana Dashboard
    - url: https://runbooks.internal/payments
      title: Runbook
spec:
  type: service
  lifecycle: production
  owner: team-payments
  system: checkout-platform
  dependsOn:
    - component:postgres-payments
    - component:redis-sessions
  providesApis:
    - payments-api

When every service has this file, Backstage aggregates them into a searchable catalog. Engineers can find any service, see its owner, dependencies, runbooks, and live health status — all in one place.

Service Templates: The Golden Path

The golden path is the opinionated, pre-approved way to create new services. Instead of copy-pasting Kubernetes YAML and Dockerfile from existing services (with inevitable drift), teams use Backstage templates to scaffold new services with all standards pre-baked:

# Template definition (stored in Backstage)
apiVersion: scaffolder.backstage.io/v1beta3
kind: Template
metadata:
  name: python-microservice
  title: Python Microservice
  description: Creates a production-ready Python service with FastAPI, Docker, CI/CD, and Kubernetes manifests
spec:
  owner: platform-team
  type: service

  parameters:
    - title: Service Information
      properties:
        name:
          type: string
          title: Service Name
          pattern: "^[a-z][a-z0-9-]{2,30}$"
        description:
          type: string
          title: Service Description
        owner:
          type: string
          title: Owning Team
          ui:field: OwnerPicker

    - title: Infrastructure
      properties:
        namespace:
          type: string
          title: Kubernetes Namespace
          enum: [production, staging, development]
        replicas:
          type: integer
          title: Initial Replica Count
          default: 2
          minimum: 1
          maximum: 10
        memory_limit:
          type: string
          title: Memory Limit
          default: "512Mi"

  steps:
    - id: fetch-template
      name: Fetch Base Template
      action: fetch:template
      input:
        url: ./skeleton
        values:
          name: ${{ parameters.name }}
          owner: ${{ parameters.owner }}
          namespace: ${{ parameters.namespace }}
          replicas: ${{ parameters.replicas }}

    - id: create-github-repo
      name: Create GitHub Repository
      action: github:repo:create
      input:
        repoUrl: github.com?repo=${{ parameters.name }}&owner=myorg
        description: ${{ parameters.description }}

    - id: push-to-github
      name: Push Template to GitHub
      action: github:repo:push
      input:
        repoUrl: github.com?repo=${{ parameters.name }}&owner=myorg

    - id: register-in-catalog
      name: Register in Catalog
      action: catalog:register
      input:
        repoContentsUrl: ${{ steps['create-github-repo'].output.repoContentsUrl }}
        catalogInfoPath: /catalog-info.yaml

    - id: create-github-environments
      name: Setup Environments
      action: github:environment:create
      input:
        repoUrl: github.com?repo=${{ parameters.name }}&owner=myorg
        environments: [development, staging, production]

  output:
    links:
      - title: Repository
        url: ${{ steps['create-github-repo'].output.remoteUrl }}
      - title: Open in Catalog
        url: ${{ steps['register-in-catalog'].output.entityRef }}

The template skeleton (in ./skeleton/) contains the actual files — Dockerfile, FastAPI app structure, GitHub Actions workflow, Kubernetes Helm values, Prometheus alert rules — all templated with the values from the form above.

A developer fills out a form in the Backstage UI, clicks "Create," and in 30 seconds has a GitHub repo with:
- Production-ready Dockerfile with multi-stage build
- FastAPI app with health endpoints
- GitHub Actions CI/CD pipeline deploying to Kubernetes
- Helm chart with resource limits and HPA configured
- Prometheus alerts for error rate and latency
- catalog-info.yaml registering the service in Backstage

This is the golden path. Not "here's the documentation," but "here's the working thing, already configured correctly."

TechDocs: Documentation as Code

Backstage's TechDocs plugin renders Markdown documentation from service repositories directly in the catalog. Documentation lives next to the code, versioned in Git, and is discoverable through Backstage search:

# mkdocs.yml in each service repo
site_name: Payments Service
nav:
  - Home: index.md
  - Architecture: architecture.md
  - API Reference: api.md
  - Runbook: runbook.md
  - On-Call Guide: oncall.md

plugins:
  - techdocs-core
<!-- docs/runbook.md -->
# Payments Service Runbook

## High Error Rate Alert

**Symptom:** `PaymentsHighErrorRate` alert firing  
**Threshold:** Error rate > 5% for 5 minutes

### Immediate Steps
1. Check recent deployments: `kubectl rollout history deploy/payments-service -n production`
2. Check error logs: `kubectl logs -l app=payments-service -n production --tail=100`
3. Check Stripe API status: https://status.stripe.com
...

Engineers find runbooks from the Backstage catalog, not by asking "where's the runbook for X?" in Slack.

The Platform Team's Operating Model

A platform team of 3-5 engineers can support 50-150 application developers when built correctly. The key is operating like a product team, not a shared services team:

Product management: The platform has a roadmap, a backlog prioritized by developer impact, and regular user research with application teams. "What slows you down?" is the core question.

SLOs for the platform: The platform itself has service level objectives. Deployment pipeline P99 runtime < 10 minutes. Backstage availability > 99.5%. Provisioning request time < 2 minutes. Developers treating the platform as a product means they can plan around it.

Self-service by default: If a developer must file a ticket for a common task, that's a product gap. Ticket-worthy tasks should become self-service templates within 2 sprints of being identified.

graph TD A[Identify developer friction] --> B{Ticket volume > 5/week?} B -- Yes --> C[Build self-service template or automation] B -- No --> D[Document workaround] C --> E[Measure adoption] E --> F{Adoption > 80%?} F -- Yes --> G[Retire old process] F -- No --> H[Improve UX or documentation] H --> E

Crossplane: Infrastructure as Kubernetes Resources

Backstage handles the developer interface. Crossplane handles the infrastructure provisioning. Together they form a complete self-service layer.

Crossplane extends Kubernetes with custom resource definitions (CRDs) that represent cloud resources. An application team creates a Kubernetes YAML file to request a database — Crossplane provisions the actual RDS instance in AWS.

# Developer submits this YAML to create a production PostgreSQL database
# No AWS console, no Terraform, no ticket to the platform team
apiVersion: database.example.com/v1alpha1
kind: PostgreSQLInstance
metadata:
  name: payments-db
  namespace: payments-prod
spec:
  parameters:
    storageGB: 100
    engineVersion: "16"
    instanceClass: db.r6g.xlarge
    multiAZ: true
    backupRetentionDays: 30
  compositionRef:
    name: postgresql-aws-production
  writeConnectionSecretToRef:
    name: payments-db-credentials  # Automatically written to K8s Secret

The platform team defines Compositions — the Crossplane resources that translate this high-level request into AWS RDS, security groups, parameter groups, and subnet groups. Application teams only see the high-level API. They can't accidentally provision an unencrypted database or skip backups — the platform composition enforces the defaults.

# Platform team's Composition (defined once, used by all teams)
apiVersion: apiextensions.crossplane.io/v1
kind: Composition
metadata:
  name: postgresql-aws-production
spec:
  compositeTypeRef:
    apiVersion: database.example.com/v1alpha1
    kind: PostgreSQLInstance
  resources:
    - name: rds-instance
      base:
        apiVersion: rds.aws.upbound.io/v1beta1
        kind: Instance
        spec:
          forProvider:
            region: us-east-1
            encrypted: true           # Always enforced
            iamDatabaseAuthenticationEnabled: true
            deletionProtection: true  # Platform enforces this
      patches:
        - fromFieldPath: spec.parameters.storageGB
          toFieldPath: spec.forProvider.allocatedStorage
        - fromFieldPath: spec.parameters.instanceClass
          toFieldPath: spec.forProvider.instanceClass

This pattern — platform defines the opinionated "what's allowed," teams configure within that envelope — is the essence of platform engineering applied to infrastructure.

Platform Engineering Anti-Patterns

Understanding what platform engineering looks like when done wrong saves months of rework:

Anti-pattern 1: Platform as gatekeeping. The platform team creates a "self-service" portal that still requires a human to approve requests. This is just a ticket system with a UI. Self-service means automated provisioning, not form submission.

Anti-pattern 2: Building everything from scratch. Teams sometimes build custom CI/CD engines, secret managers, and service meshes instead of configuring existing solutions. The result: underdocumented custom tooling that breaks when the original author leaves. Use open-source standards; add value with opinionated configuration.

Anti-pattern 3: No feedback loop. Platform teams that don't regularly talk to developers build tools nobody uses. Run "paper cuts" sessions monthly: what slows you down this sprint? Prioritize accordingly.

Anti-pattern 4: Mandating the golden path without exceptions. Every large organization has legacy services that can't immediately adopt the new platform. Forcing migration causes conflict and backlash. Offer a path that makes new services easy, without blocking teams on legacy systems.

Anti-pattern 5: Platform team as a cost center. Platform engineering has clear ROI — measure it. Time saved per developer per week × number of developers × engineer cost = platform value. Deployment frequency and DORA metrics tell the story quantitatively. A platform team that can't show ROI will be cut in the next budget cycle.

flowchart TD A[Platform team approach] A --> B[Self-service automation\n✅ Anti-pattern 1 fix] A --> C[Configure open-source tooling\n✅ Anti-pattern 2 fix] A --> D[Regular developer feedback\n✅ Anti-pattern 3 fix] A --> E[Opt-in golden path\n✅ Anti-pattern 4 fix] A --> F[Measure DORA + ROI\n✅ Anti-pattern 5 fix] style B fill:#22c55e,color:#fff style C fill:#22c55e,color:#fff style D fill:#22c55e,color:#fff style E fill:#22c55e,color:#fff style F fill:#22c55e,color:#fff

Production Considerations

What Not to Build

Platform teams that try to build everything burn out and produce tools nobody uses. The most common mistake is building custom CI/CD from scratch. Use GitHub Actions, GitLab CI, or Tekton — your value-add is the opinionated workflows on top, not the engine itself.

Similarly, don't build custom secret managers, custom monitoring agents, or custom service mesh implementations. Vault, the OpenTelemetry Collector, and Istio/Cilium are mature. Your job is to configure them correctly and wrap them in self-service abstractions.

Measuring Platform Success

Metrics that matter:
- DORA metrics: Deployment frequency, lead time for changes, change failure rate, mean time to recovery. The platform should improve all four.
- Onboarding time: How long until a new engineer ships their first feature? Platform teams track this.
- Self-service ratio: What percentage of infrastructure requests are fulfilled through self-service vs. tickets?
- Platform adoption: Are teams using the golden paths? Deviations are technical debt.

Multi-Tenancy and Guardrails

The platform enforces standards without blocking innovation. Use Open Policy Agent (OPA) admission controllers to enforce security policies — no privileged containers, no latest image tags, required resource limits — at deploy time rather than in code review.

# OPA/Gatekeeper constraint: require resource limits on all containers
apiVersion: constraints.gatekeeper.sh/v1beta1
kind: K8sRequiredResources
metadata:
  name: require-resource-limits
spec:
  match:
    kinds:
      - apiGroups: ["apps"]
        kinds: ["Deployment"]
  parameters:
    required: ["limits.memory", "limits.cpu", "requests.memory", "requests.cpu"]

Teams can still customize — but they can't accidentally ship a container without resource limits.

The Paved Road vs the Off-Road

Platform engineering doesn't mean mandating one way to do everything. The "paved road" metaphor is more accurate than "golden path": a paved road is smooth, fast, and well-maintained. You can drive off it, but you're aware you're doing so — and you take on more responsibility.

For a Python microservice deploying to Kubernetes, the paved road means:
- FastAPI (not Flask, not Django — one framework, well-supported by the platform)
- Dockerfile from the standard base image (pre-baked security scanning, non-root user)
- GitHub Actions pipeline from the template (not custom pipelines in Jenkins)
- Helm chart from the platform's chart library (not custom Kubernetes YAML)
- Prometheus client pre-integrated (not optional — metrics are mandatory)

Teams that need to go off-road (legacy services, specialized requirements) can — but they own the maintenance. The platform team doesn't guarantee support for custom configurations.

This creates a natural incentive: new services take the paved road because it's genuinely faster. The effort to maintain a custom configuration isn't worth it compared to using the templated, already-working setup.

Operationally, paved-road services benefit from platform improvements automatically. When the platform team upgrades the base Docker image for a security vulnerability, all paved-road services get the fix in their next build — without the service team doing anything. Off-road services have to handle it manually.

The ratio matters: if 80% of services are on the paved road, platform improvements have leverage. If only 20% are, the platform team's work has limited impact.

Developer Portals: Search, Discover, Understand

The unsexy part of platform engineering is documentation and discoverability. Developers spend significant time finding: who owns this service? Where's the runbook? What APIs does it expose? How do I get access to it?

Backstage's search indexes the entire software catalog — services, APIs, documentation, and owners. But the value multiplies when every service has quality catalog-info.yaml and TechDocs. This requires a culture shift: documentation is part of the definition of done.

A practical forcing function: the platform team's deployment pipeline validates that catalog-info.yaml exists and contains required fields before a service can deploy to production.

# GitHub Actions check — runs on every PR
name: Platform Compliance Check

on: [pull_request]

jobs:
  catalog-check:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4

      - name: Validate catalog-info.yaml exists
        run: |
          if [ ! -f "catalog-info.yaml" ]; then
            echo "❌ catalog-info.yaml is required for all services"
            exit 1
          fi

      - name: Validate required fields
        run: |
          python3 -c "
          import yaml, sys
          with open('catalog-info.yaml') as f:
              catalog = yaml.safe_load(f)

          required = ['metadata.name', 'metadata.description', 'spec.owner', 'spec.lifecycle']
          missing = []
          for field in required:
              keys = field.split('.')
              obj = catalog
              for key in keys:
                  if key not in obj:
                      missing.append(field)
                      break
                  obj = obj[key]

          if missing:
              print(f'❌ Missing required fields: {missing}')
              sys.exit(1)
          print('✅ catalog-info.yaml valid')
          "

      - name: Check TechDocs directory exists
        run: |
          if [ ! -d "docs" ] || [ ! -f "docs/index.md" ]; then
            echo "⚠️  docs/index.md is recommended for all services (see platform wiki)"
          fi

This kind of automated compliance — not blocking deployments for missing docs, but flagging it visibly — moves cultural change faster than documentation mandates alone.

Conclusion

Platform engineering has proven its ROI: organizations that invest in it report 40-60% reduction in time-to-production for new services and significant improvements in DORA metrics. The key insights:

  • Build products, not shared services: Treat your IDP as a product with a roadmap, metrics, and user research
  • Golden paths are opinionated: Offer one well-maintained path rather than infinite flexibility that becomes everyone's problem
  • Self-service or bust: Every ticket-based workflow is a candidate for automation
  • Measure what matters: DORA metrics, onboarding time, and self-service ratio tell you if the platform is working
  • Backstage is the catalog, not the whole platform — the real work is the pipelines, templates, and integrations behind it

The alternative — every team maintaining their own infrastructure — doesn't scale. Platform engineering is the way engineering organizations maintain velocity as they grow.

The most important mindset shift for a platform team: you're not a help desk, you're a product team. Your customers are internal developers. Your product metrics are DORA improvements and developer satisfaction scores. Run user research, maintain a public roadmap, and deprecate unused tools the same way a product team deprecates features. Platform engineering done right is invisible — developers don't notice the infrastructure because it just works.

Getting started doesn't require Backstage on day one. Start with a standardized Dockerfile, a shared GitHub Actions workflow library, and a wiki page listing every service and its owner. That's already more than most teams have. Add Backstage when the catalog needs to be searchable, not before. The principles matter more than the tooling: self-service, golden paths, and measuring developer experience as a first-class metric.


Sources

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-05-14 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter

Sunday, April 12, 2026

Platform Engineering: The Evolution of DevOps and Why Every Company Needs an IDP

Platform Engineering hero — a developer navigating a modern internal platform dashboard

Generated with Higgsfield GPT Image — 16:9

Introduction

In 2012, a two-pizza team at Amazon published a manifesto that would reshape software delivery for a decade: "You build it, you run it." DevOps was born. Infrastructure-as-code, continuous integration, containerization, and Kubernetes democratized the ability to ship software fast. Any developer could deploy to production. Any team could own their pipeline.

The problem? Most of them didn't actually want to.

By 2024, the average software engineer at a mid-size tech company was spending nearly 40% of their time on infrastructure concerns — debugging Terraform state locks, wrangling Kubernetes YAML, chasing observability gaps, triaging Dependabot alerts, and navigating seven different internal tools just to ship a feature. DevOps gave developers power over their systems, but it also handed them an enormous cognitive tax that most were never hired to pay.

Platform Engineering is the answer. It asks a different question: instead of "who deploys software?", it asks "who owns the platform that developers use to deploy software?" The distinction sounds subtle, but it changes everything about how engineering organizations scale.

The CNCF Platforms Working Group formalized this shift in 2023 with a white paper defining platform engineering as the discipline of designing and building toolchains and workflows that enable self-service capabilities for software engineering organizations. Gartner went further, predicting that 80% of large software engineering organizations will have dedicated platform teams by 2026. That prediction is well on track.

This post is your complete guide to understanding platform engineering — what it is, why it emerged, what an Internal Developer Platform (IDP) contains, and how to start building one whether you have a team of five or five hundred.


What DevOps Got Wrong

DevOps did not fail. It succeeded enormously at its original goal: breaking down the wall between developers and operations, enabling continuous delivery, and moving organizations away from monthly release trains to daily or hourly deployments. DORA metrics improved industry-wide. Software quality went up. Release cycles shortened.

But success created a new problem. "You build it, you run it" was designed for teams with deep operational knowledge. As it spread across the industry, it was applied to every engineering team regardless of context, interest, or skill. The result was a phenomenon researchers now call DevOps tax — the hidden cost in developer time, energy, and cognitive load imposed by infrastructure ownership at scale.

Consider what a developer at a modern cloud-native company is expected to know and operate on a typical day:

  • CI/CD pipelines — GitHub Actions, Jenkins, CircleCI, or Tekton. Debugging flaky tests, managing secrets, caching builds.
  • Kubernetes — Writing Deployments, Services, Ingresses, HorizontalPodAutoscalers, resource limits, PodDisruptionBudgets.
  • Infrastructure as code — Terraform or Pulumi for VPCs, RDS instances, S3 buckets, IAM roles.
  • Observability — Setting up Prometheus metrics, Datadog dashboards, defining SLOs, creating PagerDuty escalation policies.
  • Security scanning — Trivy for container images, Snyk for dependencies, Semgrep for SAST.
  • Cost management — Understanding cloud billing, right-sizing instances, avoiding reserved instance waste.
  • Service mesh — Istio or Linkerd routing, mTLS, traffic splitting for canary releases.

Studies from DORA (2023 State of DevOps Report) found that developers at organizations without platform teams spend on average 1.5 days per week on infrastructure-related tasks. That is 30% of total working time — time that does not produce user-facing features.

The developer experience survey from Humanitec (2024) found that 83% of developers feel overwhelmed by the cognitive complexity of their tooling stack. More damning: 41% said they had made infrastructure decisions they later regretted because they simply did not know enough about the tradeoffs.

The DevOps dream of autonomous, self-sufficient teams ran into the reality of finite human attention. Not every developer wants to become a platform expert. And forcing them to become one is expensive.

pie title Developer Time Distribution (Without Platform Team) "Feature Development" : 42 "Infrastructure & CI/CD" : 28 "Debugging & Incidents" : 18 "Meetings & Coordination" : 12

What Platform Engineering Is

Platform Engineering takes the operational complexity that DevOps distributed across all teams and re-centralizes it — but with a crucial difference from the old operations model. The platform team is not a gatekeeper. It is a product team, and developers are its customers.

The output of a platform team is an Internal Developer Platform (IDP): a curated set of self-service capabilities, workflows, and tools that developers can use without becoming infrastructure experts. The key word is self-service. Developers do not file tickets. They do not wait for approvals. They click a button (or run a CLI command) and get what they need.

Spotify popularized this model with Backstage, their internal developer portal, which they open-sourced in 2020. When Backstage launched internally at Spotify, it unified a fragmented tooling landscape into a single catalog. Developers could discover services, understand ownership, spin up new microservices from templates, and access documentation — all from one place. The result: onboarding time for new engineers dropped dramatically, and developer satisfaction scores climbed.

The platform engineering philosophy rests on three core ideas:

1. Paved roads, not guardrails. A golden path is the blessed way to do something — the approach that the platform team has tested, secured, optimized, and documented. Developers are not forced to use it, but it is so much easier than the alternative that most choose to. Think of it like a highway versus a dirt road: you can take the dirt road, but why would you?

2. The platform as a product. Platform teams use product management techniques: user research, roadmaps, feedback loops, versioning, deprecation policies. They measure adoption and developer satisfaction. They run office hours. They treat their internal users with the same respect a SaaS company treats its customers.

3. Developer self-service at every layer. From spinning up a new service to requesting a database, from provisioning a staging environment to rotating secrets — the IDP enables developers to do these things independently, without waiting for another team.

The ecosystem has matured rapidly. Tools like Backstage (open source, CNCF project), Port (API-first commercial platform), Humanitec (platform orchestrator), and Cortex (catalog and scorecard) have made it possible to build a production-quality IDP without writing everything from scratch.


Core IDP Components

An Internal Developer Platform is not a single tool — it is a system of integrated capabilities that spans the entire software development lifecycle. Understanding what goes into an IDP helps teams prioritize what to build first and what to buy.

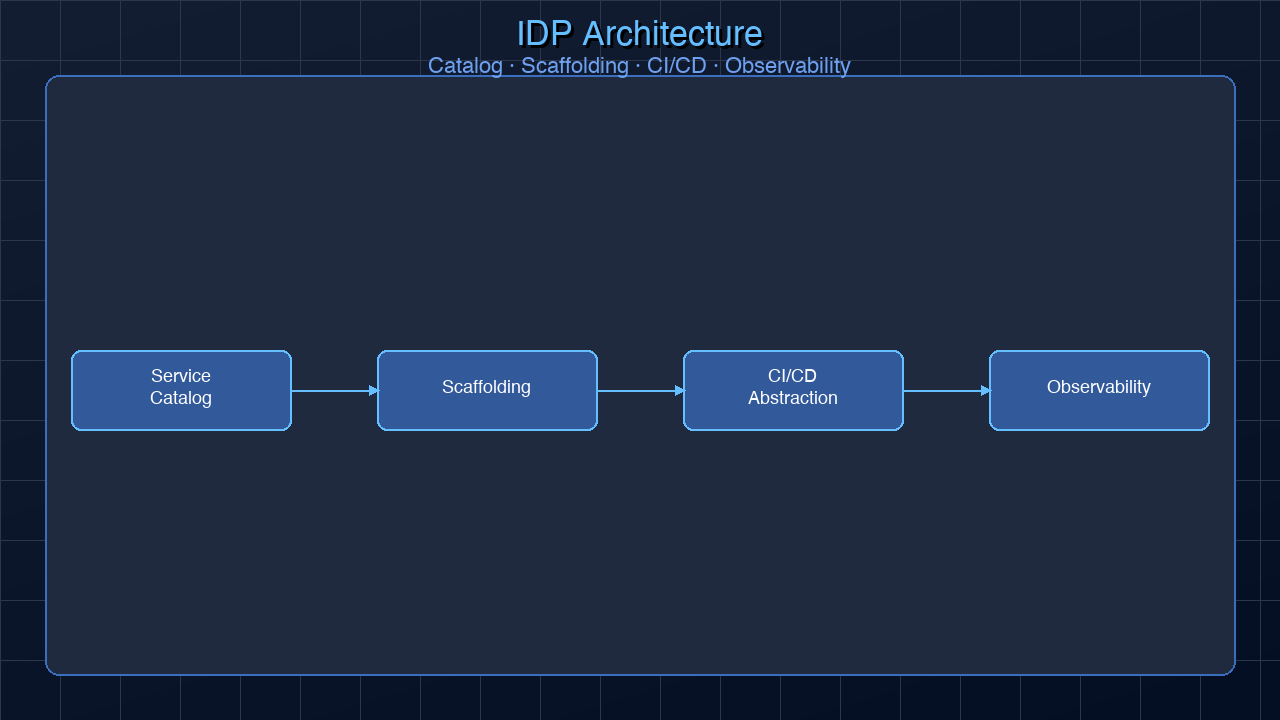
IDP architecture diagram showing service catalog, scaffolding, CI/CD abstraction, and observability layers

Generated with Higgsfield GPT Image — 16:9

Service Catalog

The foundation of any IDP is a service catalog — a searchable registry of every service, library, API, data pipeline, and infrastructure component in the organization. The catalog answers questions like: Who owns this service? What does it do? What are its dependencies? What is its current health? Where is its documentation?

Without a catalog, developers waste time rediscovering existing solutions, reinventing the wheel, and reaching out to the wrong team when something breaks. With one, they can find and reuse internal components in minutes.

Here is an example catalog-info.yaml for Backstage, the most widely used catalog format:

apiVersion: backstage.io/v1alpha1
kind: Component
metadata:
  name: payments-service
  description: "Handles payment processing via Stripe and internal billing APIs"
  annotations:
    github.com/project-slug: "acmecorp/payments-service"
    pagerduty.com/service-id: "P12345"
    datadoghq.com/service-name: "payments-service"
  tags:
    - payments
    - critical
    - backend
spec:
  type: service
  lifecycle: production
  owner: group:payments-team
  system: billing
  dependsOn:
    - component:user-service
    - component:fraud-detection-service
  providesApis:
    - payments-api

Self-Service Templates (Scaffolding)

Templates allow developers to spin up new services from a curated starting point that already includes security defaults, CI pipelines, observability hooks, and README documentation. Instead of copying and modifying an existing service (with all its baggage), developers run one command and get a production-ready skeleton.

CI/CD Abstraction

Rather than each team reinventing their pipeline, the platform team provides reusable CI/CD templates that teams opt into. GitHub Actions reusable workflows, shared Jenkins libraries, or Tekton task bundles — the implementation varies, but the goal is the same: secure, tested, and consistent pipelines without every team needing to become a CI expert.

Environment Provisioning

Developers need environments: development, staging, production, and often ephemeral preview environments for feature branches. IDPs enable on-demand environment provisioning — a developer can request a staging environment via a UI or CLI, and the IDP automatically provisions the Kubernetes namespace, network policies, secrets, and monitoring.

Observability Integration

Logging, metrics, tracing, and alerting should be available automatically, not configured manually per service. When a service is created from an IDP template, it gets a Datadog dashboard, a Prometheus scrape config, and a PagerDuty escalation policy by default.

Secrets Management

Vault, AWS Secrets Manager, or GCP Secret Manager access should be self-service. Developers should be able to request and rotate secrets through the IDP without involving a security team for routine operations.

Cost Visibility

Cloud cost attribution at the team or service level enables financial accountability. Developers should see what their services cost to run, identify anomalies, and make informed tradeoff decisions.

graph TB subgraph IDP["Internal Developer Platform"] SC[Service Catalog] ST[Self-Service Templates] CI[CI/CD Abstraction] EP[Environment Provisioning] OB[Observability] SM[Secrets Management] CV[Cost Visibility] end DEV[Developer] -->|Browse & discover| SC DEV -->|Scaffold new service| ST ST -->|Triggers| CI CI -->|Deploys to| EP EP -->|Wired to| OB EP -->|Accesses| SM OB -->|Reports to| CV SC -.->|Linked metadata| OB SC -.->|Ownership| SM style IDP fill:#f0f4ff,stroke:#4a6cf7,stroke-width:2px style DEV fill:#e8f5e9,stroke:#2e7d32,stroke-width:2px

Building vs Buying

One of the first decisions platform teams face is whether to build their IDP in-house, use open-source tools, or buy a commercial solution. There is no universally correct answer — the right choice depends on team size, budget, engineering maturity, and how much customization you need.

Open Source: Backstage

Backstage is the most widely deployed IDP framework. Created by Spotify and donated to the CNCF in 2020, it has become the de facto industry standard. Over 2,700 companies use it in production, including Netflix, American Airlines, LinkedIn, Airbnb, and Zalando.

Pros: Completely free, infinitely extensible via plugins (600+ available), large community, strong ecosystem, no vendor lock-in.

Cons: Requires a React engineering team to maintain, significant initial setup investment (typically 2-4 weeks for a basic deployment, months for full customization), plugin quality varies widely, hosting burden falls on your team.

Commercial: Port

Port is the fastest-growing commercial IDP, built on an API-first catalog model. Developers define blueprints (data models for resources), connect integrations (GitHub, AWS, Kubernetes, PagerDuty), and build self-service actions — all without writing code.

Pros: Days to initial value (not months), no hosting burden, strong scorecard and compliance features, beautiful UI.

Cons: Ongoing subscription cost (pricing based on users), less customizable than Backstage, some vendor dependency.

Commercial: Humanitec

Humanitec takes a different approach with its Platform Orchestrator model — focusing less on the developer portal UI and more on the API layer that translates developer intent into infrastructure configurations. It integrates with any CI system and manages dynamic environment configuration.

Commercial: Cortex

Cortex focuses on the service catalog and engineering excellence scorecards. It is particularly strong for organizations that want to track service maturity, enforce standards, and gamify quality improvements.

flowchart TD A{What is your priority?} --> B{Budget available?} B -->|No budget| C{Engineering team size?} B -->|Budget available| D{Need quick time-to-value?} C -->|Small < 5 eng| E[Start with lightweight tooling\nGitHub + Actions templates] C -->|Medium 5-20 eng| F[Backstage self-hosted\nOpen source] C -->|Large > 20 eng| G[Backstage with platform team\nFull investment] D -->|Yes, within weeks| H[Port or Cortex\nCommercial SaaS] D -->|No, can invest months| I{Need full customization?} I -->|Yes| F I -->|No - orchestration focus| J[Humanitec\nPlatform Orchestrator] style E fill:#fff3cd style F fill:#d4edda style G fill:#d4edda style H fill:#cce5ff style J fill:#cce5ff

The Golden Path Pattern

The golden path is the most powerful pattern in platform engineering. It is the combination of tools, templates, and processes that the platform team has curated and recommended as the standard way to build and deploy services. When a developer starts a new service using the golden path, they get everything they need without having to make infrastructure decisions.

A mature golden path for a new microservice typically provisions:

  1. GitHub repository — from a template with standard .github/workflows, Dockerfile, README.md, linting config, and branch protection rules
  2. CI/CD pipeline — pre-configured GitHub Actions workflows for build, test, security scan, and deploy
  3. Kubernetes namespace — with network policies, resource quotas, and service accounts
  4. Service mesh entry — Istio virtual service and destination rule
  5. Observability — Datadog APM auto-instrumentation, pre-built dashboard, SLO definition
  6. PagerDuty service — escalation policy linked to the owning team
  7. Catalog entrycatalog-info.yaml registered in Backstage or equivalent

The beauty of the golden path is that it encodes best practices invisibly. Security defaults, cost controls, and observability are not checklist items — they are automatic outcomes of using the standard tooling.

Here is a simplified example of what a golden path scaffolder template produces when invoked via Backstage:

# scaffolder-template.yaml (Backstage Template)
apiVersion: scaffolder.backstage.io/v1beta3
kind: Template
metadata:
  name: new-microservice
  title: New Microservice
  description: Creates a production-ready microservice with CI/CD, observability, and catalog registration
spec:
  owner: platform-team
  type: service
  parameters:
    - title: Service Details
      properties:
        name:
          title: Service Name
          type: string
          description: "Lowercase, hyphenated (e.g. 'payments-service')"
        owner:
          title: Owner Team
          type: string
          ui:field: OwnerPicker
        language:
          title: Language
          type: string
          enum: [go, python, typescript, java]
  steps:
    - id: create-repo
      name: Create GitHub Repository
      action: publish:github
      input:
        repoUrl: "github.com?repo=${{ parameters.name }}&owner=acmecorp"
        defaultBranch: main
        gitAuthorName: platform-bot
        sourcePath: templates/${{ parameters.language }}/service

    - id: register-catalog
      name: Register in Service Catalog
      action: catalog:register
      input:
        repoContentsUrl: ${{ steps['create-repo'].output.repoContentsUrl }}
        catalogInfoPath: /catalog-info.yaml

    - id: create-namespace
      name: Provision Kubernetes Namespace
      action: kubernetes:create-namespace
      input:
        name: ${{ parameters.name }}
        labels:
          team: ${{ parameters.owner }}
          service: ${{ parameters.name }}
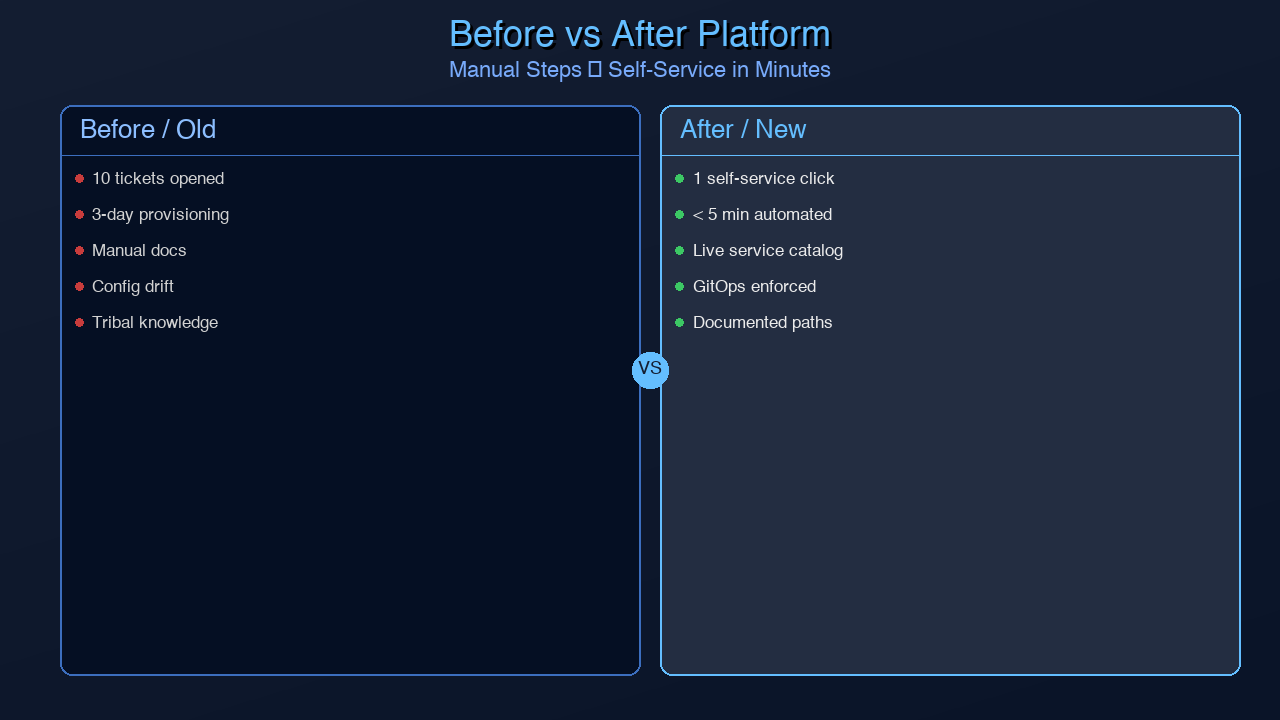
Golden path comparison — before and after platform engineering adoption

Generated with Higgsfield GPT Image — 16:9

sequenceDiagram participant Dev as Developer participant IDP as IDP / Backstage participant GH as GitHub participant K8s as Kubernetes participant DD as Datadog participant PD as PagerDuty Dev->>IDP: "Create new service: payment-processor" IDP->>GH: Fork template repo → payment-processor GH-->>IDP: Repo created ✓ IDP->>GH: Configure branch protection + Actions workflows IDP->>K8s: kubectl create namespace payment-processor K8s-->>IDP: Namespace + RBAC created ✓ IDP->>DD: Register APM service + create dashboard DD-->>IDP: Dashboard URL ✓ IDP->>PD: Create service + link to payments-team escalation PD-->>IDP: PagerDuty service ID ✓ IDP->>GH: Commit catalog-info.yaml to repo IDP-->>Dev: ✅ Service ready — links to repo, dashboard, runbook Note over Dev,PD: Total time: ~90 seconds vs. ~2 days manual

Measuring Platform Success

A platform team that cannot demonstrate its value will not survive the next budget cycle. Fortunately, the metrics for platform success are concrete and well-established.

DORA Metrics are the gold standard for measuring software delivery performance:

Metric Elite Performer High Performer Medium Performer Low Performer
Deployment Frequency Multiple/day Daily–weekly Weekly–monthly Monthly–6mo
Lead Time for Changes < 1 hour 1 day–1 week 1 week–1 month 1–6 months
Change Failure Rate 0–5% 5–10% 10–15% 15–30%
MTTR < 1 hour < 1 day 1 day–1 week > 1 week

Platform teams track developer satisfaction separately via quarterly developer experience surveys. Key questions: How much time did you spend on infrastructure this week? How easy was it to deploy? How confident are you in your observability setup? Tracking these scores over time reveals whether the platform is actually reducing cognitive load.

Platform teams fit the enabling team pattern from Team Topologies — their job is to make stream-aligned teams (feature teams) more effective, not to be in the critical path of delivery. This distinction matters: if developers are waiting on the platform team, the platform has failed its own design goals.


Getting Started Without a Platform Team

Platform engineering can sound expensive and out of reach for smaller organizations. It does not have to be. The principles scale down as well as up.

Start with one small, high-value improvement. Do not try to build a full IDP from day one. Choose one of these entry points:

Option 1: Standardize CI templates. Create a GitHub Actions reusable workflow that handles build, test, security scan, and Docker build consistently. Make it a 5-line uses: reference in every service's workflow. This alone saves hours per developer per week and eliminates the "each repo has a different CI setup" problem.

Option 2: Create one golden path. Build a cookiecutter or Yeoman template (or a simple shell script) that scaffolds a new service with your standard directory structure, Dockerfile, CI workflow, and README. Socialize it with the team. Measure adoption.

Option 3: Start a service catalog. Even a simple GitHub repository with a services.yaml file listing every service, its owner, and its links is infinitely better than no catalog. If your team is ready for a real tool, deploy Backstage via the @backstage/create-app CLI in an afternoon — the basic deployment takes a few hours.

The worst thing you can do is wait until you have a dedicated platform team before starting. One engineer spending 20% of their time on platform concerns can deliver enormous value. The goal is not perfection — it is reducing friction, one paved road at a time.


Conclusion

Platform Engineering is not a replacement for DevOps — it is its maturation. DevOps gave developers the power to deploy. Platform Engineering gives them a platform that makes that power accessible without requiring every developer to become a site reliability engineer.

The Internal Developer Platform is the infrastructure upon which modern software engineering organizations run. It is the difference between developers spending their days fighting YAML and developers shipping features that matter to users. When done well, an IDP is nearly invisible — developers do not talk about the platform because it just works.

The CNCF's Platforms Working Group, Gartner's predictions, and the rapid growth of tools like Backstage, Port, and Humanitec all point to the same conclusion: platform engineering is no longer optional for organizations at scale. The question is not whether you will need an IDP, but how you will build one.

Start small. Pick one problem. Make one thing easier for developers today. That is how every great platform begins.


Next in this series: Internal Developer Platforms in 2026: Build vs Buy, and the Tools That Win

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-12 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter
Bigger Is Not the Same as Better. The Job That Moved Is the Phone, Not the Lab.

Bigger is a plan. The phone is the receipt. The brief for this cycle is a question: does bigger always mean better in AI? The 2026 answer i...