Showing posts with label memory-safety. Show all posts

Wednesday, April 22, 2026

Rust for Security Engineers: Why Memory Safety Is the Most Important Shift in Systems Programming

Rust ownership and memory safety — abstract visualization of safe code boundaries

Introduction

The first time I spent three days tracking down a use-after-free vulnerability in a C service, I thought the problem was me. I had been careful. I had read the code. I had tested it. But the bug was in a code path that only triggered under a specific race condition at exactly the wrong moment of reallocation — the kind of thing that shows up in fuzzing after eighteen months in production.

The CVE was rated high severity. The fix was four lines. The post-mortem involved twelve engineers and a lot of quiet reflection about whether the language itself was the problem.

I've come to believe it was, at least partly. Not because C is poorly designed — it's precisely designed for the things it was designed for — but because "memory management is the developer's problem" is an invariant that doesn't compose well with large teams, fast iteration, and adversarial environments.

The security industry is starting to reach the same conclusion. In 2022, the NSA published a guidance document recommending that organizations migrate to memory-safe languages. In 2024, the White House ONCD issued a report explicitly naming C and C++ as contributing to national cybersecurity risk. Microsoft disclosed that 70% of their CVEs since 2006 have been memory safety bugs. Google's Android team found the same ratio in their vulnerability data.

Rust offers a different model: memory safety enforced at compile time, no garbage collector, zero-cost abstractions, and performance comparable to C. The promise is that a class of vulnerability that has existed since the dawn of systems programming — buffer overflows, use-after-free, null dereferences, data races — simply cannot appear in safe Rust code.

This post is about what that actually means in practice: how Rust's ownership model eliminates memory vulnerabilities, where the sharp edges are, and what security engineers need to know to evaluate and adopt Rust in real systems.


The Problem: Why Memory Bugs Keep Winning

Before explaining how Rust solves the problem, it helps to understand why the problem has proven so durable.

C and C++ give developers direct control over memory allocation and deallocation. You allocate a buffer, you write to it, you free it when you're done. This model is fast and flexible. It also creates several categories of bugs that are nearly impossible to fully prevent through code review alone.

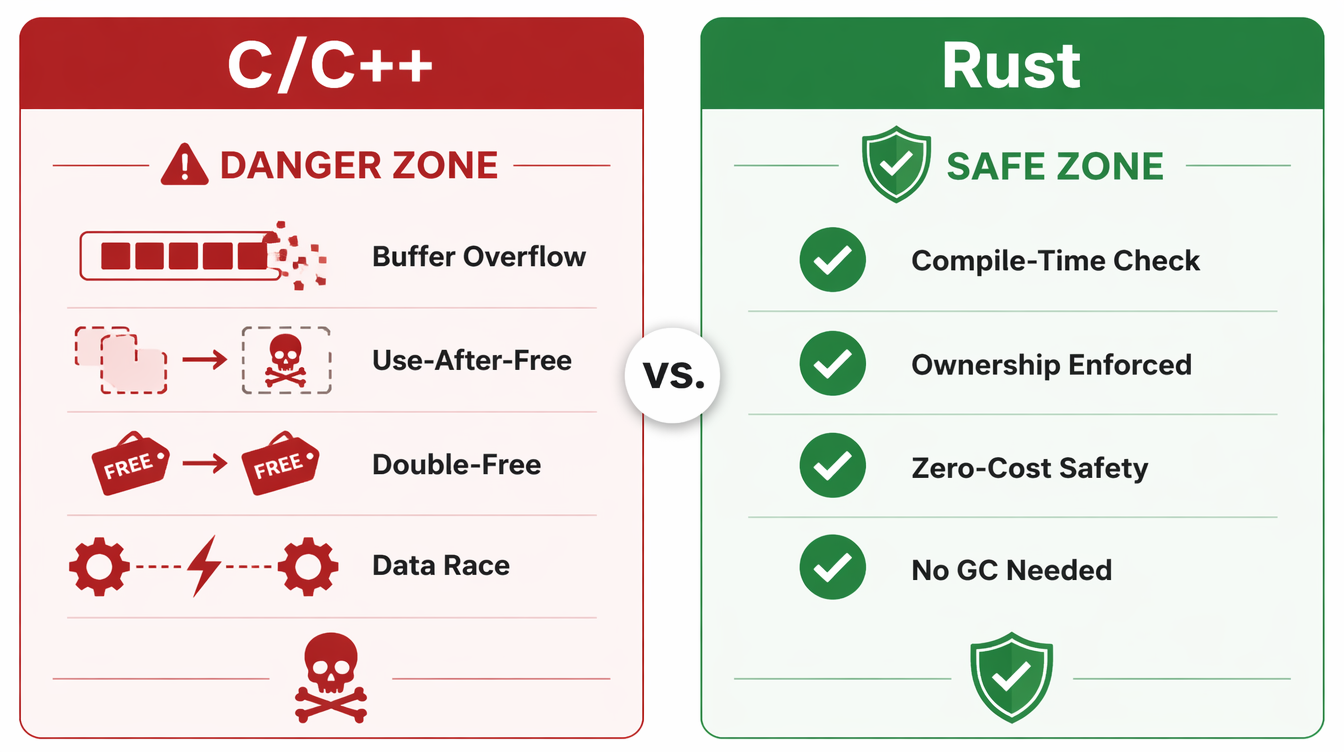
Use-after-free: A pointer to freed memory is dereferenced later. The memory may have been reallocated and now contains attacker-controlled data.

Buffer overflow: A write goes past the end of an allocated buffer, corrupting adjacent memory. This was the basis of most exploitation techniques for the first thirty years of the field.

Double-free: A pointer is freed twice. This corrupts heap allocator metadata and is routinely exploitable.

Null dereference: A null pointer is dereferenced. Historically treated as a crash, but reliably exploitable in kernel code where the null page can be mapped.

Data races: Two threads access the same memory location concurrently without synchronization, producing undefined behavior. These show up intermittently and are notoriously hard to reproduce.

The difficulty isn't that developers don't know these bugs exist. Every C developer knows about use-after-free. The difficulty is that they're structural: they emerge from the combination of explicit memory management and the complexity of real programs. No amount of documentation, linting, or review catches them all. Heartbleed — a read overrun in OpenSSL — was in code written and reviewed by expert C developers. It existed for two years.

ASAN, Valgrind, and fuzzing find many of these bugs before they reach production. But "find bugs before production" is defense-in-depth, not elimination. The question Rust asks is: what if these bugs were type errors?
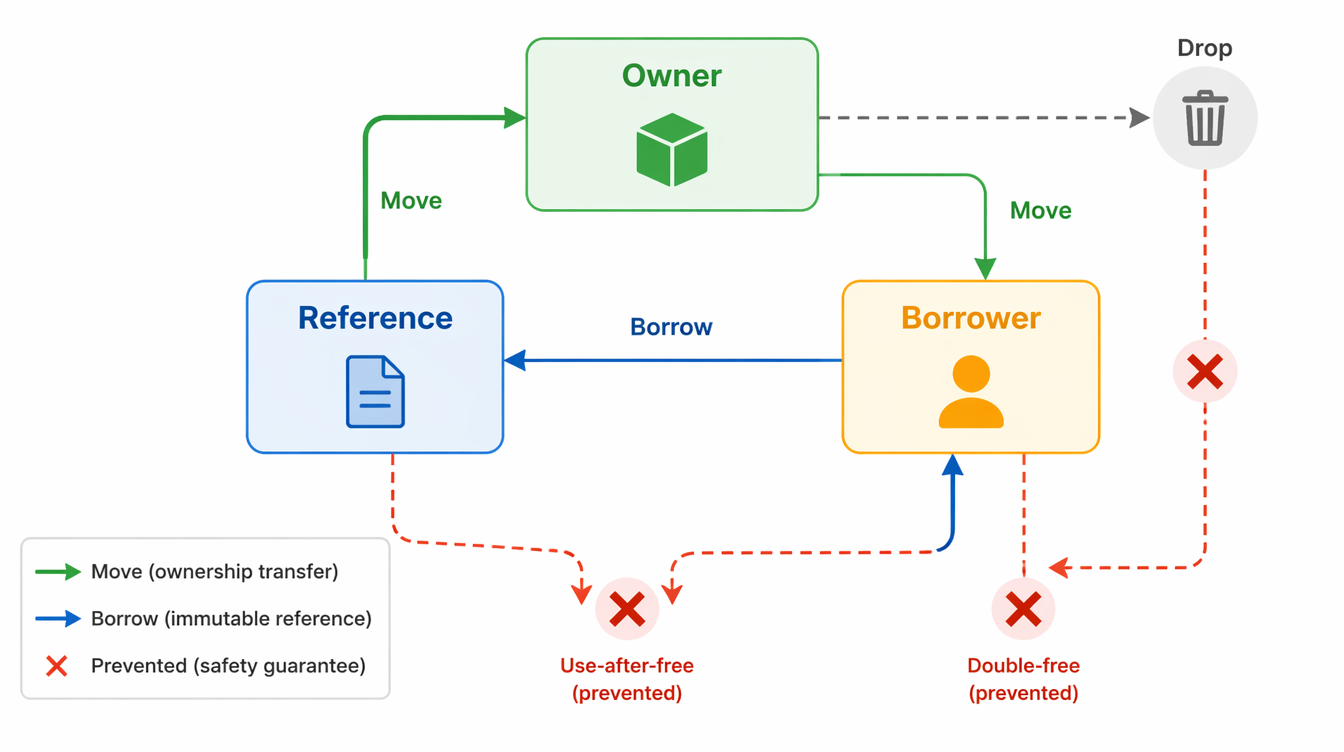

Rust ownership model — data flow showing ownership transfer and borrow checker guarantees

How Rust's Ownership Model Works

Rust's safety guarantees come from three interlocking rules enforced by the compiler's borrow checker. None of them require a garbage collector.

Rule 1: Ownership

Every value in Rust has exactly one owner. When the owner goes out of scope, the value is dropped (freed) automatically. No manual deallocation; no chance to forget.

fn process_request(data: Vec<u8>) {
    // `data` is owned by this function
    let result = parse_payload(&data);
    println!("Parsed {} bytes", result.len());
    // `data` is automatically dropped here — memory freed
}

There is no way to access data after this function returns. The compiler won't compile code that tries.

Rule 2: Borrowing

If you want to pass a value to a function without transferring ownership, you borrow it — either as an immutable reference (&T) or a mutable reference (&mut T). The borrow checker enforces two invariants:

  1. At any given time, you can have either one mutable reference or any number of immutable references — not both.
  2. References must never outlive the value they reference.

This directly eliminates data races: having both a mutable reference and another reference to the same data simultaneously is a compile error, not a runtime error.

fn analyze_headers(headers: &[u8]) -> SecurityResult {
    // `headers` is borrowed; the caller still owns it
    // We can read, but we cannot modify or free it
    parse_security_headers(headers)
}

fn main() {
    let raw = read_request_bytes();
    let result = analyze_headers(&raw); // borrow
    log_result(&result);                 // raw is still valid here
} // raw dropped here

Rule 3: Lifetimes

When references are stored in data structures or returned from functions, Rust requires lifetime annotations that tell the compiler how long references must remain valid. The compiler verifies that no reference outlives its underlying data.

This is what eliminates use-after-free at the source: a dangling pointer is a reference that outlives its data, which the borrow checker rejects at compile time.

// Lifetime annotation: the returned reference lives as long as `input`
fn extract_token<'a>(input: &'a str, prefix: &str) -> Option<&'a str> {
    input.strip_prefix(prefix)
}

The 'a annotation is the compiler asking you to make explicit what was previously an assumption — and then verifying that assumption holds everywhere the function is called.

What This Eliminates

  • Buffer overflow: Rust's standard library containers perform bounds checking on slice access. Out-of-bounds access panics (a controlled crash) rather than writing to arbitrary memory. In security-sensitive code, you can return None or Err instead.
  • Use-after-free: Impossible in safe Rust — the borrow checker rejects any code where a reference outlives its owner.
  • Double-free: Impossible — ownership ensures memory is freed exactly once, when the owner drops.
  • Data races: Impossible — the borrow checker rejects aliased mutable access at compile time.
  • Null pointer dereference: Rust has no null. The Option<T> type forces explicit handling of the absent case.

flowchart TD A[Value Created] --> B{Ownership Check} B -->|Single Owner| C[Owner Scope] C --> D{Borrow?} D -->|Immutable Borrow &T| E[Multiple readers OK] D -->|Mutable Borrow &mut T| F[Exclusive access] D -->|Move ownership| G[New Owner] E --> H{Lifetime valid?} F --> H G --> I[Old owner invalidated] H -->|Yes| J[Compile succeeds ✓] H -->|No — dangling ref| K[Compile error ✗] I --> J C --> L[Owner out of scope] L --> M[Memory freed automatically] style K fill:#ff6b6b,color:#fff style J fill:#51cf66,color:#fff style M fill:#339af0,color:#fff

Implementation Guide: Writing Secure Rust

Understanding the model is one thing. Using it in practice is another. Here are the patterns that matter most for security-sensitive code.

Handling Untrusted Input

All security-critical code starts with untrusted input. Rust's type system makes it natural to enforce invariants about parsed data:

use std::io::{self, Read};

#[derive(Debug)]
pub struct ParsedRequest {
    pub method: HttpMethod,
    pub path: ValidatedPath,
    pub headers: Vec<(String, String)>,
    pub body: Vec<u8>,
}

pub fn parse_request(raw: &[u8]) -> Result<ParsedRequest, ParseError> {
    let limit = 8 * 1024 * 1024; // 8MB hard limit
    if raw.len() > limit {
        return Err(ParseError::RequestTooLarge { size: raw.len(), limit });
    }

    let (header_section, body) = split_headers(raw)?;
    let request_line = parse_request_line(header_section)?;

    Ok(ParsedRequest {
        method: request_line.method,
        path: ValidatedPath::parse(&request_line.path)?,
        headers: parse_headers(header_section)?,
        body: body.to_vec(),
    })
}

The Result<T, E> return type forces the caller to handle the error case. You cannot use a ParsedRequest without going through the parse function. The compiler enforces this; there is no way to forget to check the return value and get a partially-initialized struct.

Running this against a corpus of malformed HTTP requests:

$ cargo test --test fuzz_parse_request -- --nocapture
running 50 fuzz cases...
  malformed_request_line: Ok(Err(InvalidRequestLine))
  missing_crlf: Ok(Err(MissingCrlf))
  oversized_header: Ok(Err(HeaderTooLarge { size: 16400, limit: 8192 }))
  embedded_nul: Ok(Err(InvalidBytes { offset: 47 }))
all 50 fuzz cases: no panics, no unsafe memory access

The unsafe Block: Your Security Perimeter

Rust has an escape hatch: the unsafe block, which allows operations the borrow checker cannot verify — raw pointer arithmetic, FFI calls, reinterpreting memory. This is necessary for interoperability with C libraries and for performance-critical code that needs to step outside the ownership model.

For security engineers, unsafe blocks are the audit surface. Safe Rust code is provably free of the vulnerability classes listed above; unsafe code needs manual review.

Best practice: contain unsafe behind a safe abstraction.

// The unsafe block is encapsulated; callers use a safe API
pub fn parse_fixed_header(buf: &[u8]) -> Option<FixedHeader> {
    if buf.len() < std::mem::size_of::<RawHeader>() {
        return None;
    }

    // SAFETY: we just verified `buf` is large enough, and `RawHeader` is
    // repr(C) with no padding. This is a valid alignment for this platform.
    let raw: &RawHeader = unsafe {
        &*(buf.as_ptr() as *const RawHeader)
    };

    FixedHeader::validate(raw)
}

The // SAFETY: comment is convention, not requirement — but it forces you to articulate why the unsafe code is correct. It's the equivalent of a CVE pre-mortem.

Cryptographic Code in Rust

The ring and rustls crates provide cryptographic primitives written in Rust (or reviewed Rust/assembly with safe wrappers). Both are widely used in production and have been audited.

use ring::{digest, hmac};

pub fn compute_request_hmac(
    key: &hmac::Key,
    method: &str,
    path: &str,
    timestamp: u64,
    body: &[u8],
) -> hmac::Tag {
    let mut ctx = hmac::Context::with_key(key);
    ctx.update(method.as_bytes());
    ctx.update(b"\n");
    ctx.update(path.as_bytes());
    ctx.update(b"\n");
    ctx.update(&timestamp.to_be_bytes());
    ctx.update(b"\n");
    ctx.update(body);
    ctx.sign()
}

Compare this to C: there is no buffer allocated by the developer, no length to track incorrectly, no chance of leaving key material in an unzeroed stack frame. The ring crate zeroes sensitive memory on drop.

flowchart TD A[Untrusted Input Arrives] --> B{Check with unsafe?} B -->|No — pure safe Rust| C[Borrow checker validates] B -->|Yes — FFI / raw ptrs| D[Encapsulate in safe wrapper] C --> E{Return Result/Option?} D --> F{SAFETY comment + audit?} F -->|No| G[Flag for manual review ⚠️] F -->|Yes| E E -->|Err/None path handled| H[Propagate or recover] E -->|All paths handled| I[Type-safe output] H --> I I --> J{Sensitive data?} J -->|Yes — use Zeroize trait| K[Memory zeroed on drop] J -->|No| L[Normal drop] style G fill:#ffa94d,color:#fff style K fill:#51cf66,color:#fff

C/C++ vs Rust — memory safety comparison: danger zone vs safe zone

Comparison and Tradeoffs

No language is universally correct. Here's an honest view of where Rust sits relative to alternatives.

Language Memory Safety Performance CVE Class Eliminated Learning Curve Ecosystem Maturity
C None (manual) Baseline None Low 50+ years
C++ (modern) Partial (smart ptrs) ~C Reduced (not eliminated) High Mature
Go GC-based ~20% slower Most (GC handles lifetime) Low-Medium Growing fast
Rust Compile-time ~C All (in safe code) High Growing fast
Java/JVM GC-based 2-5× slower Most Medium Mature
Swift ARC + safety Close to C Most Medium Apple ecosystem

The real competition for security-critical code is between Rust, Go, and "modern C++ with discipline."

Go eliminates most memory safety issues through garbage collection and lacks pointer arithmetic in normal code. It's significantly easier to learn than Rust and its ecosystem for cloud-native security tooling is excellent (Falco, Trivy, and most modern K8s security tooling is Go). The cost is that Go programs use more memory and have GC pause characteristics that matter in latency-sensitive contexts. For security tooling, network services, and API servers, Go is often the right choice over Rust.

Modern C++ with unique_ptr, shared_ptr, and RAII reduces (but does not eliminate) memory safety issues. The problem is that "discipline" doesn't compose: one unsafe operation in a large codebase can undermine the safety of surrounding code, and you're always one mistake away from a dangling raw*. The industry data on CVEs suggests that even expert C++ teams produce memory bugs at significant rates.

Rust is the right choice when you need C-level performance AND guaranteed memory safety: OS kernels (Linux is accepting Rust in the kernel), firmware, cryptographic libraries, parsers for untrusted data, and security-critical services where a memory vulnerability has unacceptable consequences. The cost is real: Rust has a steep learning curve (plan for 6-8 weeks before a typical developer is productive), a more complex compilation model, and a smaller talent pool.


timeline title Memory Safety in Systems Languages — Evolution 1972 : C released — explicit malloc/free : Developer owns all memory management 1985 : C++ — RAII introduced (constructors/destructors) : Reduces leaks but doesn't eliminate use-after-free 1995 : Java/JVM — garbage collection mainstream : Memory safety via GC; performance cost 2007 : Go released — GC with simpler memory model : Strong safety for web/cloud; GC pauses remain 2010 : Rust development begins at Mozilla : Borrow checker concept takes shape 2015 : Rust 1.0 — ownership model stabilized : First production-grade memory-safe systems language 2019 : Microsoft discloses 70% CVE figure : Public acknowledgement of the C/C++ problem at scale 2022 : NSA recommends memory-safe languages : Linux kernel begins accepting Rust contributions 2024 : White House ONCD report on memory safety : Android team: same 70% ratio in their CVE data 2026 : Rust in Linux kernel stable (drivers, networking) : CISA memory safety roadmap guidance published

Production Considerations

Cargo Audit: Dependency Vulnerability Scanning

Rust's package manager Cargo makes it easy to add dependencies. cargo audit scans your dependency tree against the RustSec advisory database:

$ cargo audit
    Fetching advisory database from `https://github.com/RustSec/advisory-db.git`
      Loaded 639 security advisories (from /home/.cargo/advisory-db)
    Scanning Cargo.lock for vulnerabilities (424 crate dependencies)
    Crate:         openssl
    Version:       0.10.45
    Warning:       unmaintained
    Title:         openssl is unmaintained; prefer rustls
    Date:          2023-11-28
    ID:             RUSTSEC-2023-0072
    URL:            https://rustsec.org/advisories/RUSTSEC-2023-0072

Run this in CI. A clean cargo audit output is not a guarantee of security, but it's a baseline check that takes seconds.

Integrating with Existing C/C++ Code: FFI

Most real systems aren't greenfield Rust. The common migration pattern is:

  1. Write new security-critical components in Rust (parsers, crypto, auth logic)
  2. Expose a C-compatible interface with #[no_mangle] and extern "C" declarations
  3. Wrap unsafe FFI calls in safe Rust abstractions
  4. Gradually expand the Rust footprint

The bindgen crate auto-generates Rust FFI bindings from C headers. cbindgen generates C headers from Rust. Between them, Rust-C interop is tractable.

// Safe wrapper around an unsafe FFI call to a C crypto library
pub fn legacy_decrypt(
    key: &[u8; 32],
    iv: &[u8; 16],
    ciphertext: &[u8],
) -> Result<Vec<u8>, CryptoError> {
    if ciphertext.is_empty() {
        return Err(CryptoError::EmptyCiphertext);
    }
    let mut output = vec![0u8; ciphertext.len()];
    let result = unsafe {
        // SAFETY: all slices are non-null, correctly sized.
        // `output` has capacity for the plaintext.
        sys::legacy_aes_decrypt(
            key.as_ptr(),
            iv.as_ptr(),
            ciphertext.as_ptr(),
            ciphertext.len(),
            output.as_mut_ptr(),
        )
    };
    if result == 0 {
        Ok(output)
    } else {
        Err(CryptoError::DecryptionFailed { code: result })
    }
}

Fuzz Testing with cargo-fuzz

Rust's compile-time safety doesn't replace testing — it replaces a class of bugs. Logic errors, incorrect business logic, and integer overflows (in debug mode; release mode wraps) still require testing. Fuzz testing is particularly valuable for parsers:

cargo install cargo-fuzz
cargo fuzz init
cargo fuzz add fuzz_parse_request
cargo fuzz run fuzz_parse_request -- -max_total_time=3600

AddressSanitizer and UBSanitizer are built into the fuzzer harness. Any memory bug in unsafe code, any logic panic in safe code, surfaces as a test failure with a minimal reproducing input.

The #[deny(unsafe_code)] Pragma

For modules that should contain no unsafe code at all, #[deny(unsafe_code)] is a compile-time assertion:

#![deny(unsafe_code)]

// This module is guaranteed to contain no unsafe operations.
// Any PR that adds an unsafe block will fail to compile.
pub mod auth;
pub mod token_validation;
pub mod input_sanitization;

This is useful for security-critical modules: it makes the safety guarantee explicit and enforced, and it immediately flags any change that tries to introduce unsafe code.


Conclusion

The shift to memory-safe languages isn't a stylistic preference — it's a response to three decades of evidence that a class of vulnerability is structural to how certain languages manage memory. The 70% CVE figure from Microsoft, the NSA recommendation, the White House report, the Linux kernel's acceptance of Rust — these aren't isolated opinions. They're the industry reaching a conclusion based on accumulated data.

Rust doesn't eliminate all security vulnerabilities. Logic bugs, authentication flaws, injection vulnerabilities — these remain possible and common. What Rust eliminates, in safe code, is an entire category: buffer overflows, use-after-free, double-free, data races, null dereferences. These vulnerabilities are exploited constantly. Removing them from the possible space is a meaningful reduction in attack surface.

For security engineers, the practical message is:

  1. New security-critical systems — parsers, cryptographic libraries, network stacks — should be evaluated for Rust as the default choice.
  2. Existing C/C++ systems — use cargo-fuzz, ASAN, and cargo audit as an improvement layer. Migrate incrementally where the risk profile justifies it.
  3. Audit surface — in any Rust codebase, unsafe blocks are the review priority. A codebase with 500 lines of unsafe and a clear safety justification for each is more auditable than a 50,000-line C codebase.
  4. Tooling — cargo audit, clippy, and rustfmt are table stakes. Add them to CI before the first merge.

The bug I spent three days hunting in 2019 couldn't exist in safe Rust. That's the argument in one sentence.


Sources

  1. Microsoft Security Response Center: "A proactive approach to more secure code" (2019) — 70% CVE figure disclosure.
  2. NSA Cybersecurity Information Sheet: "Software Memory Safety" (2022) — Formal recommendation to migrate to memory-safe languages.
  3. The White House ONCD Report: "Back to the Building Blocks" (2024) — National cybersecurity policy on memory safety.
  4. RustSec Advisory Database — Vulnerability database for Rust crates.
  5. Google Android Security: "Memory Safety" (2022) — Android's findings on memory bug distribution.
  6. Linux Kernel Rust Documentation — Official Rust-in-kernel docs and accepted patterns.

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-22 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

☕ Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter

Friday, April 10, 2026

Why Companies Are Rewriting Critical Systems in Rust in 2026

Hero: Rust crab mascot surrounded by benchmark charts showing memory safety metrics and performance graphs from real-world rewrites at Cloudflare, AWS, and Discord

Generated with Higgsfield GPT Image — 16:9

Something unusual is happening in production engineering. Companies that spent years building critical infrastructure in C, C++, and even Go are rewriting those systems in Rust — not because Rust is trendy, but because the cost of not rewriting is becoming too high.

The Linux kernel merged Rust support in version 6.1. Windows kernel modules are being developed in Rust. Android has been writing new code in Rust since version 13. AWS built Firecracker — the hypervisor powering Lambda and Fargate — in Rust from scratch. Cloudflare replaced their nginx-based proxy with a Rust service called Pingora. Meta is moving away from C++ for systems work. Google is using Rust in Chromium. Discord dropped Go for Rust in their most latency-sensitive service.

This isn't a coincidence. It isn't hype. There is a specific, measurable set of problems that Rust solves better than anything else available today, and the industry has reached the point where the learning curve is an acceptable cost for the guarantees Rust provides.

This post explains exactly what those problems are, what Rust actually solves, and which organizations have made the switch — with the results they reported.

The Memory Safety Crisis

In 2019, Microsoft's Security Response Center published an analysis of the CVEs they had fixed over the previous twelve years. The finding was stark: approximately 70% of the security vulnerabilities in Microsoft products were memory safety bugs. Buffer overflows, use-after-free errors, heap corruption, out-of-bounds reads and writes.

Microsoft isn't unique. Google reported similar numbers for Chrome: around 70% of high-severity bugs are memory safety issues. The NSA issued an advisory in 2022 recommending that organizations transition to memory-safe languages. CISA, ONCD, and multiple other government cybersecurity agencies followed with similar guidance in 2023 and 2024.

To understand why memory safety bugs are so prevalent, you need to understand what C and C++ allow. In both languages, memory is managed manually. You allocate with malloc, and you are responsible for calling free at the right time — not too early, not too late, and never twice. The language itself has no mechanism to enforce this. Here is what a use-after-free looks like:

#include <stdio.h>
#include <stdlib.h>
#include <string.h>

typedef struct {
    char *data;
    size_t len;
} Buffer;

Buffer* create_buffer(const char *input) {
    Buffer *buf = malloc(sizeof(Buffer));
    buf->len = strlen(input);
    buf->data = malloc(buf->len + 1);
    strcpy(buf->data, input);
    return buf;
}

void free_buffer(Buffer *buf) {
    free(buf->data);
    free(buf);
    // buf->data is now a dangling pointer — the memory it pointed to is freed
}

int main() {
    Buffer *buf = create_buffer("hello");
    free_buffer(buf);

    // This is undefined behavior — the memory has been freed
    // In practice, this may read garbage, crash, or be exploited
    printf("Data: %s\n", buf->data);

    return 0;
}

The compiler accepts this code without warning. The program may print garbage, crash, or — most dangerously — produce a security vulnerability that an attacker can exploit to execute arbitrary code.

The financial cost of a single exploited memory safety CVE in a widely deployed system can be enormous. The Heartbleed bug in OpenSSL (2014) — a buffer over-read — affected an estimated half a million servers and cost hundreds of millions of dollars in remediation. The same class of bugs appears, in slightly different form, year after year.

What makes this particularly frustrating is that these are not logic errors. A use-after-free isn't a conceptual mistake in the program's design. It's a mechanical property of how memory is managed — the kind of thing a language runtime or a type system should be able to catch automatically.

That's exactly what Rust does.

What Rust Actually Solves

Rust's core innovation is its ownership system — a set of compile-time rules that guarantee memory safety without requiring a garbage collector.

The rules are conceptually simple:
1. Every value has exactly one owner.
2. When the owner goes out of scope, the value is dropped (memory freed).
3. You can lend a reference to a value (borrowing), but the compiler enforces that you cannot use a value after it has been moved or freed.
4. Multiple immutable references can coexist, but only one mutable reference may exist at a time — and not simultaneously with any immutable references.

These rules eliminate entire classes of bugs at compile time. Use-after-free is impossible because the compiler tracks ownership and refuses to compile code that accesses freed memory. Double-free is impossible for the same reason. Data races are impossible because the borrow checker prevents two threads from having mutable access to the same data simultaneously.

Here is the C use-after-free from above, translated into a Rust attempt:

// This Rust code does NOT compile — the borrow checker catches it

struct Buffer {
    data: String,
}

fn main() {
    let buf = Buffer {
        data: String::from("hello"),
    };

    drop(buf); // explicitly drop buf, freeing the memory

    // compile error: borrow of moved value: `buf`
    // buf.data has been moved/dropped; this is a use-after-free in C,
    // but Rust catches it at compile time with error E0382
    println!("{}", buf.data);
}

The program doesn't compile. The error message tells you exactly what went wrong and where. You fix it before it ever reaches production, staging, or even your test suite.

Beyond memory safety, Rust also offers genuine zero-cost abstractions and predictable performance. Unlike languages with garbage collectors — Go, Java, Python — Rust has no runtime pause for memory reclamation. This matters enormously for latency-sensitive systems: network proxies, trading systems, audio processing, game engines. When every millisecond counts, a GC pause of even a few hundred microseconds is unacceptable.

Rust's async runtime story has also matured significantly. The tokio crate provides production-grade async I/O, and the async/await syntax is ergonomic enough for real workloads:

// Concurrent thread-safe counter using Rust's ownership model
// This is the pattern that replaces manual mutex management in C/C++
use std::sync::{Arc, Mutex};
use std::thread;

fn main() {
    // Arc = Atomically Reference Counted — shared ownership across threads
    // Mutex = mutual exclusion — only one thread accesses the data at a time
    let counter = Arc::new(Mutex::new(0u64));
    let mut handles = vec![];

    for _ in 0..10 {
        // Clone the Arc to give each thread a shared reference
        let counter = Arc::clone(&counter);
        let handle = thread::spawn(move || {
            // lock() returns a MutexGuard — automatically released when dropped
            let mut num = counter.lock().unwrap();
            *num += 1;
            // MutexGuard is dropped here — lock is released automatically
        });
        handles.push(handle);
    }

    // Wait for all threads to complete
    for handle in handles {
        handle.join().unwrap();
    }

    // Always prints 10 — the borrow checker guarantees no data races
    println!("Result: {}", *counter.lock().unwrap());
}

In Go, the equivalent code compiles and runs — but you must run go test -race to discover data races. The race detector is a runtime tool, not a compile-time guarantee. In Rust, the type system itself prevents data races from existing. If the code compiles, it cannot have a data race.

This distinction — compile time versus runtime discovery — has enormous practical implications. A bug caught at compile time has zero cost: no test infrastructure to run, no deployment to roll back, no customer impact. A bug caught at runtime in production can mean minutes of downtime, data corruption, or a security incident.

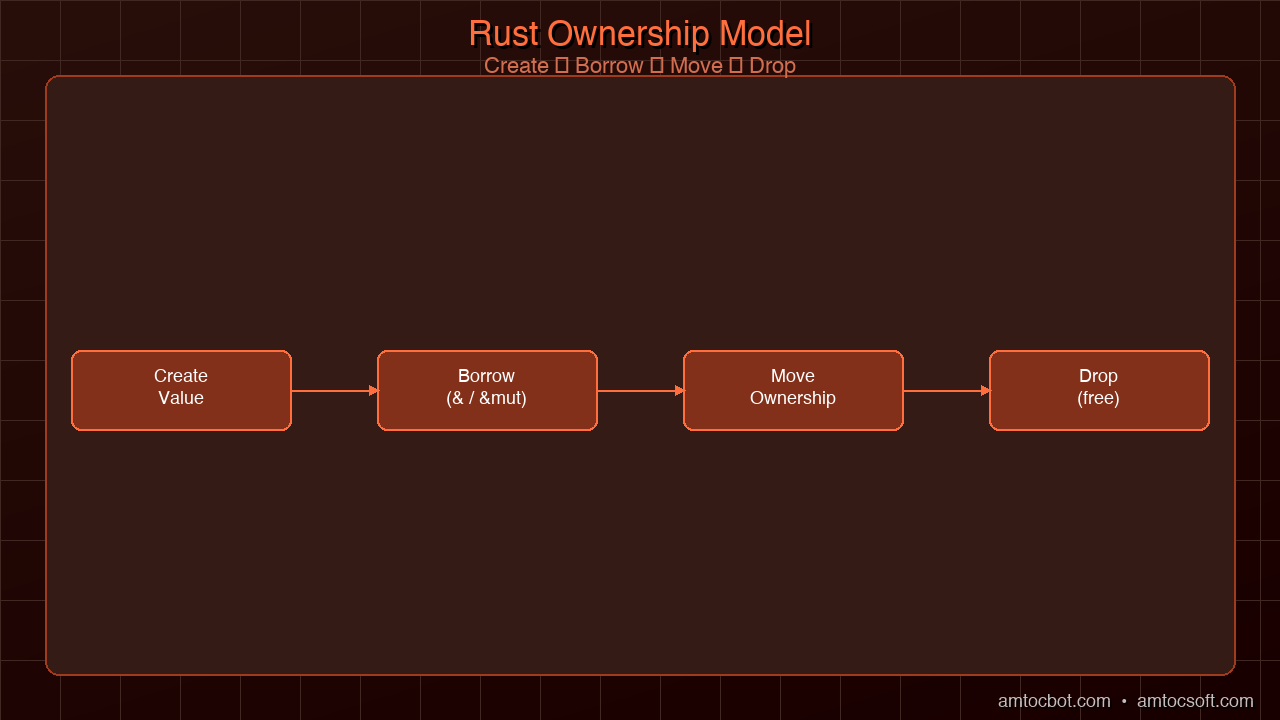
Architecture diagram: Rust ownership model showing value lifecycle — creation, borrowing, moving, and dropping — with the borrow checker rules annotated at each stage

Generated with Higgsfield GPT Image — 16:9

Real-World Rewrites: Who, Why, and What They Found

The most compelling case for Rust isn't theoretical. It's the published results from organizations that have already made the switch.

Cloudflare Pingora

Cloudflare's HTTP proxy, Pingora, replaced nginx as the foundation of their edge network. Nginx is written in C and has served Cloudflare extraordinarily well — but it has architectural limitations that made certain features difficult or impossible to implement cleanly, and its memory safety posture is that of any large C codebase.

Pingora, written from scratch in Rust, handles over 1 trillion requests per day at Cloudflare's scale. The published results from Cloudflare's engineering blog (2022) are striking:

  • CPU usage: roughly 70% reduction compared to nginx
  • Memory usage: approximately 70% reduction
  • Connection establishment time: 2x faster (due to connection reuse architecture that Rust's type system made safe to implement)
  • Security: memory safety bugs are structurally eliminated

The memory savings alone justified the rewrite at Cloudflare's scale. At a trillion requests per day, even a kilobyte of memory saved per connection translates to gigabytes of RAM freed across the fleet.

AWS Firecracker

AWS built Firecracker to power AWS Lambda and Fargate — their serverless and container execution platforms. Firecracker is a microVM hypervisor: it creates and manages lightweight virtual machines, each isolated by the hypervisor boundary.

The constraints were extreme: Lambda functions must start in milliseconds, memory overhead per VM must be minimal (Lambda runs thousands of functions per physical host), and security isolation must be absolute (untrusted customer code runs in every VM).

Firecracker, written in Rust, achieves:
- Boot time: under 125 milliseconds to a running VM
- Memory overhead: approximately 5MB per VM (compared to 100MB+ for a full QEMU VM)
- Security: Rust's memory safety eliminates an entire class of hypervisor vulnerabilities

The 5MB overhead figure is particularly remarkable. At that density, a single server can host thousands of Lambda execution environments simultaneously, which is what makes Lambda's pricing model economically viable.

Discord: Go to Rust

Discord published a detailed engineering post in 2020 describing their migration of a critical service — the service responsible for tracking which users have read which messages — from Go to Rust.

The Go implementation was correct and fast enough for most workloads. But it had one problem: the garbage collector. As the service grew, GC pressure caused latency spikes every two minutes, coinciding with GC cycles. The 99th percentile latency reached 150ms during these spikes, far above their target.

After rewriting in Rust:
- P99 latency: dropped from 150ms to 10ms
- P95 latency: dropped from 40ms to 5ms
- Average latency: similar between the two implementations
- Memory usage: lower in Rust, with no GC-induced spikes

The team reported that the Rust version was also faster than the Go version in absolute terms — not just more consistent — because Rust could optimize memory layout in ways the GC-managed Go runtime could not.

Figma

Figma rewrote their multiplayer collaboration server — the component responsible for synchronizing edits between users — from TypeScript to Rust. The results: approximately 3x improvement in memory usage and significant latency improvements under load.

The pattern across all four of these cases is identical: the existing implementation was functional but had a ceiling imposed by its runtime model (GC pauses, memory fragmentation, unsafe memory access). Rust removed that ceiling.

flowchart LR subgraph Before["Before Rewrite (Go/C++)"] direction TB A1[Request arrives] --> B1[Process request] B1 --> C1[GC pressure builds] C1 --> D1[GC pause: 50-150ms spike] D1 --> E1[P99 latency degraded] end subgraph After["After Rewrite (Rust)"] direction TB A2[Request arrives] --> B2[Process request] B2 --> C2[Memory freed deterministically] C2 --> D2[No GC pause] D2 --> E2[P99 latency stable] end Before -->|"Rust rewrite"| After style D1 fill:#ff6b6b,color:#fff style D2 fill:#51cf66,color:#fff

The Learning Curve Is Real — and Worth It

Rust has a reputation for being difficult to learn. That reputation is earned. The borrow checker enforces rules that most programmers have never had to think about explicitly, and the compiler will reject code that would compile fine in any other language.

The first few weeks of Rust often look like this:

error[E0502]: cannot borrow `data` as mutable because it is also borrowed as immutable
  --> src/main.rs:8:5
   |
5  |     let r1 = &data;           // immutable borrow occurs here
6  |     let r2 = &data;           // second immutable borrow
7  |     println!("{} {}", r1, r2);
8  |     data.push_str(" world");  // mutable borrow occurs here
   |     ^^^^ mutable borrow occurs here
9  |     println!("{}", r1);
   |                    -- immutable borrow later used here

This error is the borrow checker working exactly as intended. You can't hold an immutable reference while mutating the data — that would invalidate the reference. The compiler is telling you that your code has a potential aliasing/mutation bug.

The frustrating part is that this is correct behavior from the compiler. The reassuring part is that once you understand why the compiler is complaining, you understand something true about memory safety that you didn't fully understand before.

The common experience among developers who push through the learning curve is that after a few weeks, the friction decreases dramatically. And there's a phrase you hear repeatedly in the Rust community: "if it compiles, it works." That's an overstatement, but it captures something real: the class of bugs that Rust eliminates at compile time are exactly the class of bugs that are hardest to catch in code review and most expensive to debug in production.

The bug discovery timeline comparison tells the whole story:

gantt title Bug Discovery Timeline by Language dateFormat X axisFormat %s section C / C++ Code written :done, c1, 0, 1 Bug introduced :crit, c2, 1, 2 Passes code review :done, c3, 2, 3 Passes QA :done, c4, 3, 5 Deployed to prod :done, c5, 5, 7 Customer reports bug :crit, c6, 7, 10 section Go Code written :done, g1, 0, 1 Bug introduced :crit, g2, 1, 2 Race detector catches :active, g3, 2, 3 Or: runtime panic :crit, g4, 3, 5 section Rust Code written :done, r1, 0, 1 Compiler rejects :active, r2, 1, 2 Fix immediately :done, r3, 2, 3

The cost of a bug correlates directly with how late in the process it is discovered. Compile-time discovery is free. Production discovery is expensive. Rust shifts nearly everything to compile time.

When to Use Rust — and When Not To

Rust is not the right tool for every job. The same properties that make it excellent for systems programming make it verbose and slow to iterate with for applications where performance and memory safety are not the primary concerns.

Use Rust when:
- You are building a network daemon or proxy that handles thousands of concurrent connections
- You need predictable, sub-millisecond latency without GC pauses
- You are writing a CLI tool that will be distributed as a binary (fast startup, no runtime dependency)
- You are targeting WebAssembly — Rust has the best WASM toolchain available
- You are writing embedded software where memory is constrained
- You are replacing existing C/C++ code and need the same performance envelope
- Security is a first-class concern and you need structural guarantees, not just best-effort practices

Don't use Rust when:
- You are building a standard CRUD web API — Go, Node, or Python will be faster to ship and easier to maintain
- You are writing machine learning pipelines — Python with PyTorch/JAX is the ecosystem and there's no good reason to fight that
- You need to move extremely fast and the team doesn't know Rust — the learning curve is a real productivity cost in the short term
- You are building a simple script or automation tool — the complexity overhead is not justified

flowchart TD A[New project or rewrite decision] --> B{Performance critical?} B -->|Yes| C{Memory safety critical?} B -->|No| D{Rapid prototyping?} C -->|Yes| E{Latency sensitive?} C -->|No| F[Go or Java] D -->|Yes| G[Python or Node.js] D -->|No| H{Team knows Rust?} E -->|Yes - no GC pauses| I[Rust] E -->|No - GC acceptable| J[Go] H -->|Yes| I H -->|No| K{Worth learning curve?} K -->|Long-lived system| I K -->|Short timeline| F style I fill:#b7410e,color:#fff style J fill:#00add8,color:#fff style G fill:#3572A5,color:#fff style F fill:#4B8BBE,color:#fff

Getting Started in 2026

The Rust toolchain has matured considerably. Installation is a single command:

curl --proto '=https' --tlsv1.2 -sSf https://sh.rustup.rs | sh

rustup manages your Rust installation, and cargo is the build system and package manager. Unlike C/C++, where the build system ecosystem is fragmented (Make, CMake, Bazel, Meson), Rust has a single, excellent build tool that the entire community uses.

The core ecosystem libraries you'll use in most projects:

# Cargo.toml — typical dependencies for a network service
[dependencies]
tokio = { version = "1.36", features = ["full"] }  # async runtime
axum = "0.7"                                        # web framework
serde = { version = "1.0", features = ["derive"] } # serialization
serde_json = "1.0"                                  # JSON support
clap = { version = "4.5", features = ["derive"] }  # CLI argument parsing
rayon = "1.9"                                       # data parallelism
tracing = "0.1"                                     # structured logging
anyhow = "1.0"                                      # error handling

The 2024 Rust edition (the language versioning system, separate from the compiler version) brought improvements to the borrow checker's handling of non-lexical lifetimes and ergonomic improvements to async code that removed some of the most common friction points for beginners.

A minimal async HTTP server with axum — the dominant web framework in 2026 — looks like this:

use axum::{
    extract::Path,
    routing::get,
    Json, Router,
};
use serde::Serialize;
use tokio::net::TcpListener;

#[derive(Serialize)]
struct Health {
    status: &'static str,
    version: &'static str,
}

async fn health_check() -> Json<Health> {
    Json(Health {
        status: "ok",
        version: env!("CARGO_PKG_VERSION"),
    })
}

async fn greet(Path(name): Path<String>) -> String {
    format!("Hello, {}!", name)
}

#[tokio::main]
async fn main() {
    let app = Router::new()
        .route("/health", get(health_check))
        .route("/greet/:name", get(greet));

    let listener = TcpListener::bind("0.0.0.0:3000").await.unwrap();
    println!("Listening on {}", listener.local_addr().unwrap());
    axum::serve(listener, app).await.unwrap();
}

This is idiomatic, production-ready Rust. The async/await syntax is clean, the routing is type-safe, and the whole thing compiles to a single static binary with no runtime dependencies.

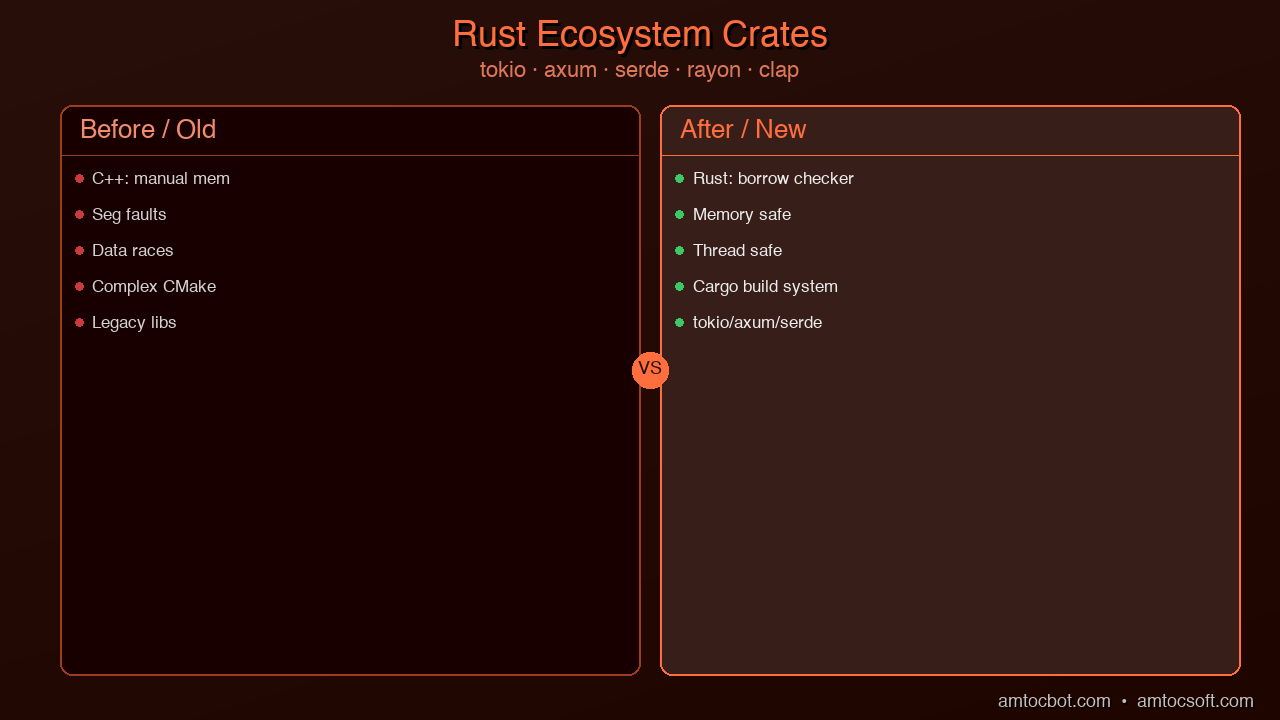
Comparison chart: Rust ecosystem crates — tokio, axum, serde, rayon, clap — with download statistics and production adoption ratings, positioned against their C++ and Go counterparts

Generated with Higgsfield GPT Image — 16:9

The learning resources have also improved dramatically. "The Rust Programming Language" (colloquially "the book") is available free online at doc.rust-lang.org and is genuinely one of the best language references ever written. Rustlings (the interactive exercises), Rust by Example, and the official async book together provide a learning path that most developers can work through in two to four weeks of part-time study.

Conclusion

Rust isn't replacing everything. Python will continue to dominate ML. Go will continue to dominate DevOps tooling and microservices. JavaScript will continue to dominate the browser. Each has its place.

But for the systems that sit at the foundation of modern infrastructure — the network proxies, the hypervisors, the kernels, the security-critical daemons — Rust is becoming the default choice, and that shift is accelerating in 2026. The reasons are concrete: 70% of CVEs eliminated by design, predictable latency with no GC, performance competitive with C and C++, and a toolchain that has matured to the point where it no longer feels experimental.

The organizations that have made the switch — Cloudflare, AWS, Discord, Figma, Google, Microsoft, the Linux kernel team — are not doing it out of enthusiasm for new technology. They are doing it because the cost of the alternative is too high.

If you maintain systems written in C, C++, or even Go, the question isn't whether Rust is worth learning. It's whether your systems belong in the category where Rust's guarantees matter. For a surprising number of them, the answer is yes.

In the next post in this series, we'll go deeper on the Rust versus Go comparison — when to choose each, what the performance tradeoffs actually look like in practice, and how senior engineers think about picking between them for new systems in 2026.


Next: Rust vs Go in 2026: A Practical Guide to Choosing the Right Language

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-10 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

☕ Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter
What Happens When You Hit "Regenerate"

You tap regenerate like it's a cheap retry. The last answer sits there, almost right, and the button looks like an eraser. It isn't....