Showing posts with label EU AI Act. Show all posts

Thursday, April 30, 2026

AI Agent Memory Privacy: Pre-emptive PII Redaction Patterns That Hold Up Under Audit

Hero image showing a glowing AI agent memory store with PII tokens being scrubbed before they enter, with redaction patterns flowing into a vector store on dark background with teal and amber accents

Introduction

The first time an agent I shipped had to be GDPR-erased, I learned a small fact that nobody had told me: a vector index does not forget. The customer was a UK insurance broker. The agent was a customer-support bot with episodic memory backed by a Qdrant collection where we measured 1.7 million summaries of past conversations. A single user filed a Right-to-be-Forgotten request through the customer's privacy portal at 09:41 on a Tuesday in October 2025. By 11:00 we had located the user's session IDs in Postgres, deleted their conversation rows, and confirmed the deletion to the privacy team. By 14:00 the privacy team had asked, reasonably, whether the agent could still answer questions about that user. By 14:30 we had run the agent against a test prompt referencing the user's first name and policy number, and the agent had returned a fluent, accurate, and terrifying summary of three of the user's prior conversations, drawn from vector-search hits we had not realised existed. The conversations were technically deleted from Postgres. The embeddings were still in the vector store. The agent was still answering from them.

That afternoon turned into a four-day deletion sprint that involved finding every embedding tagged with the user's tenant ID, every chunk of summary text that contained the user's name, every cached query result, and every transcript stored in S3. We got there. The customer's privacy team filed an incident report anyway, because we had been late. The lesson I took from that incident, the one I have built into every agent platform since, is the only PII you can guarantee will not leak from agent memory is PII that never entered agent memory in the first place. Redaction has to happen before the write, not after the regret.

This post is the playbook from that incident, plus the patterns I have hardened across six more agent platforms since, two of which have now passed full GDPR Article 17 audits and one of which is mid-flight on EU AI Act Article 14 traceability. The patterns are practical, opinionated, and battle-tested. They are not the only way to do this. They are the way I have not had to apologise for.

Why Agent Memory Is The New Privacy Surface

Agent memory in 2026 is not one thing. The post-126 patterns blog (post 165) breaks it down into three layers: working memory inside the prompt, episodic memory of past sessions in a vector store, and procedural memory of learned tool sequences. Each layer is a different privacy risk. Working memory is short-lived but fully observable to the model and any logs it touches. Episodic memory is long-lived, retrieved by similarity, and almost always the first place a privacy review trips up. Procedural memory is the smallest in volume but the hardest to audit because it is encoded as patterns rather than rows.

The compliance picture has tightened. GDPR Article 17 has been load-bearing since 2018. The 2025 court decisions in Germany and France clarified that vector embeddings derived from personal data are themselves personal data, which means the right to erasure applies to them. The EU AI Act, with its August 2026 deadline for Article 14 traceability, requires that high-risk AI systems can show what data was used to produce any given output. The California CPRA, the Colorado AI Act, and the UK Data Protection and Digital Information Act all push in the same direction. By the second half of 2026, "the embedding cannot be reversed" is no longer a defence the regulators accept. Several of them, citing recent academic work on embedding inversion, have called the claim factually wrong.

The threat model for agent memory has four parts. The user's PII can leak to the LLM provider in the prompt. The PII can leak to the vector store, which is often hosted by a different vendor. The PII can leak to logs, which often go to a third observability platform. And the PII can leak across tenants if the memory store is shared without strict isolation. Each of these is a distinct breach class. Each requires its own defence. The redaction patterns below are designed to address all four, layered, with each layer failing closed.

The Core Pattern: Redact Before Write, Not After Read

The most important architectural decision is where redaction lives. Two patterns dominate. In the first, redaction sits between the agent and the LLM at read time, scrubbing PII from prompts as they leave. In the second, redaction sits between the agent input and the memory store at write time, scrubbing PII before it ever lands. Both are useful. Only the second prevents the GDPR sprint I described above.

Read-time redaction can never be retroactive. If a memory was written with PII three months ago, a read-time scrubber cannot un-leak it; the PII is already in the index, indexed, and retrievable. Write-time redaction is harder because it is more invasive, but it is the only pattern that gives you the guarantee the privacy team will ask for: this memory store has never contained the user's PII. Read-time scrubbing is a useful additional defence, but it is a defence in depth, not a primary control.

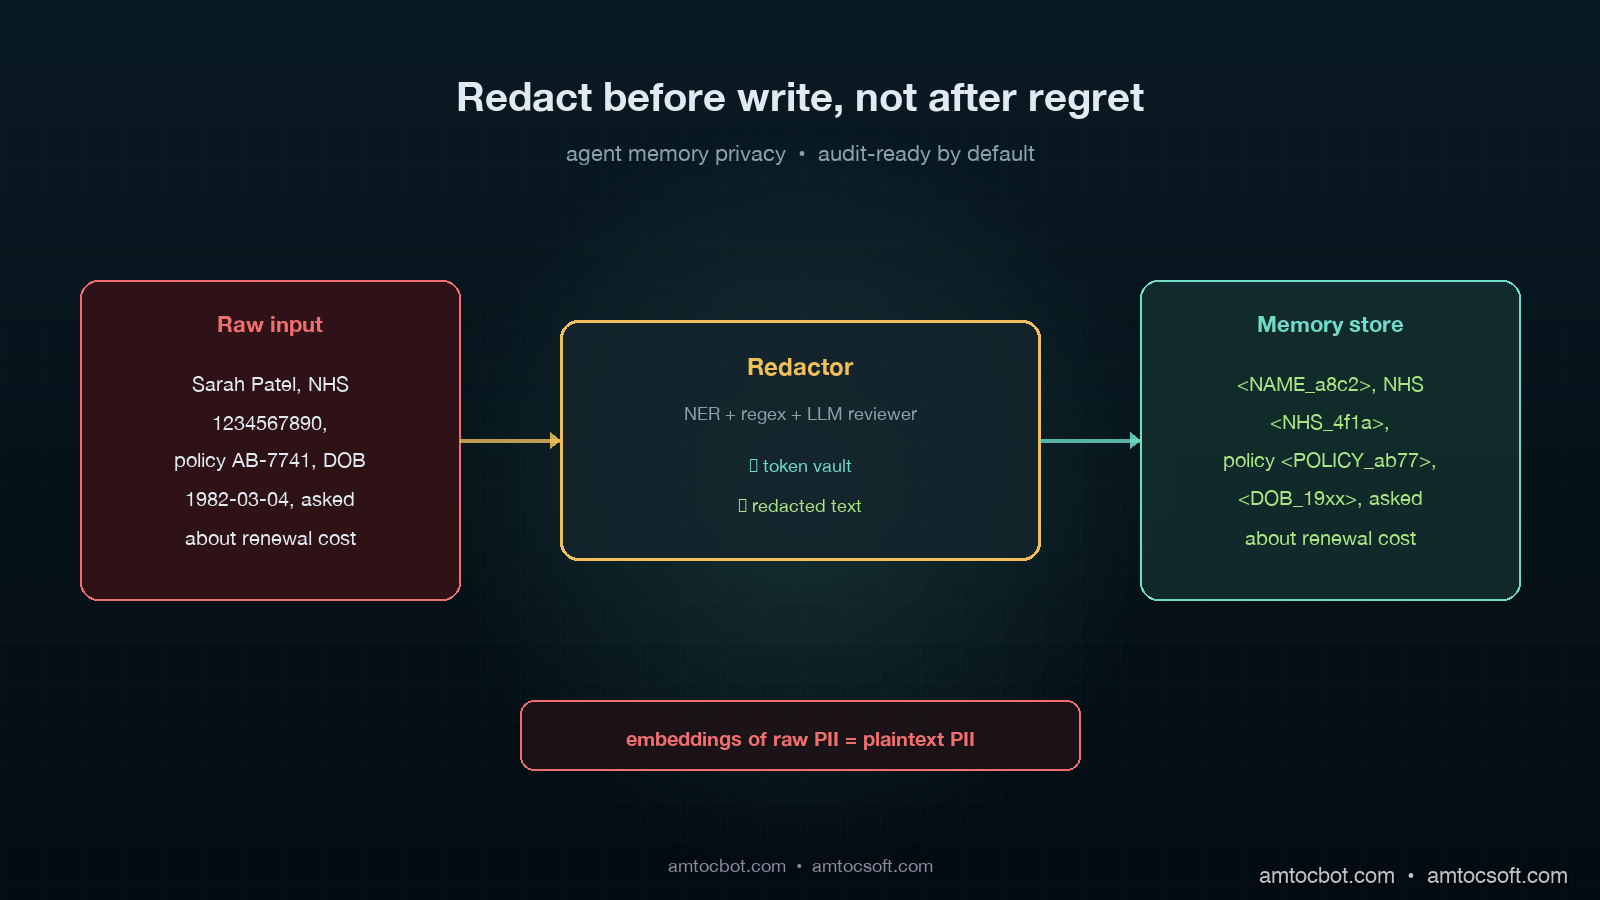
The other consequence of write-time redaction is that the agent's working memory and the storage memory diverge. The agent in flight knows the user's name, address, and policy number, because it needs them to do its job. The persistent memory stores a redacted summary that references those entities by token, like <NAME_4421> or <POLICY_AB7C>, with the mapping stored in a separate, encrypted, per-tenant key-value store that is governed by stricter retention and erasure policies than the vector index itself. When a new session retrieves a relevant past memory, the agent runtime resolves the tokens against the mapping store, validates that the current user has access to those tokens (often the answer is no, and the resolution returns a generic placeholder), and assembles the working memory accordingly.
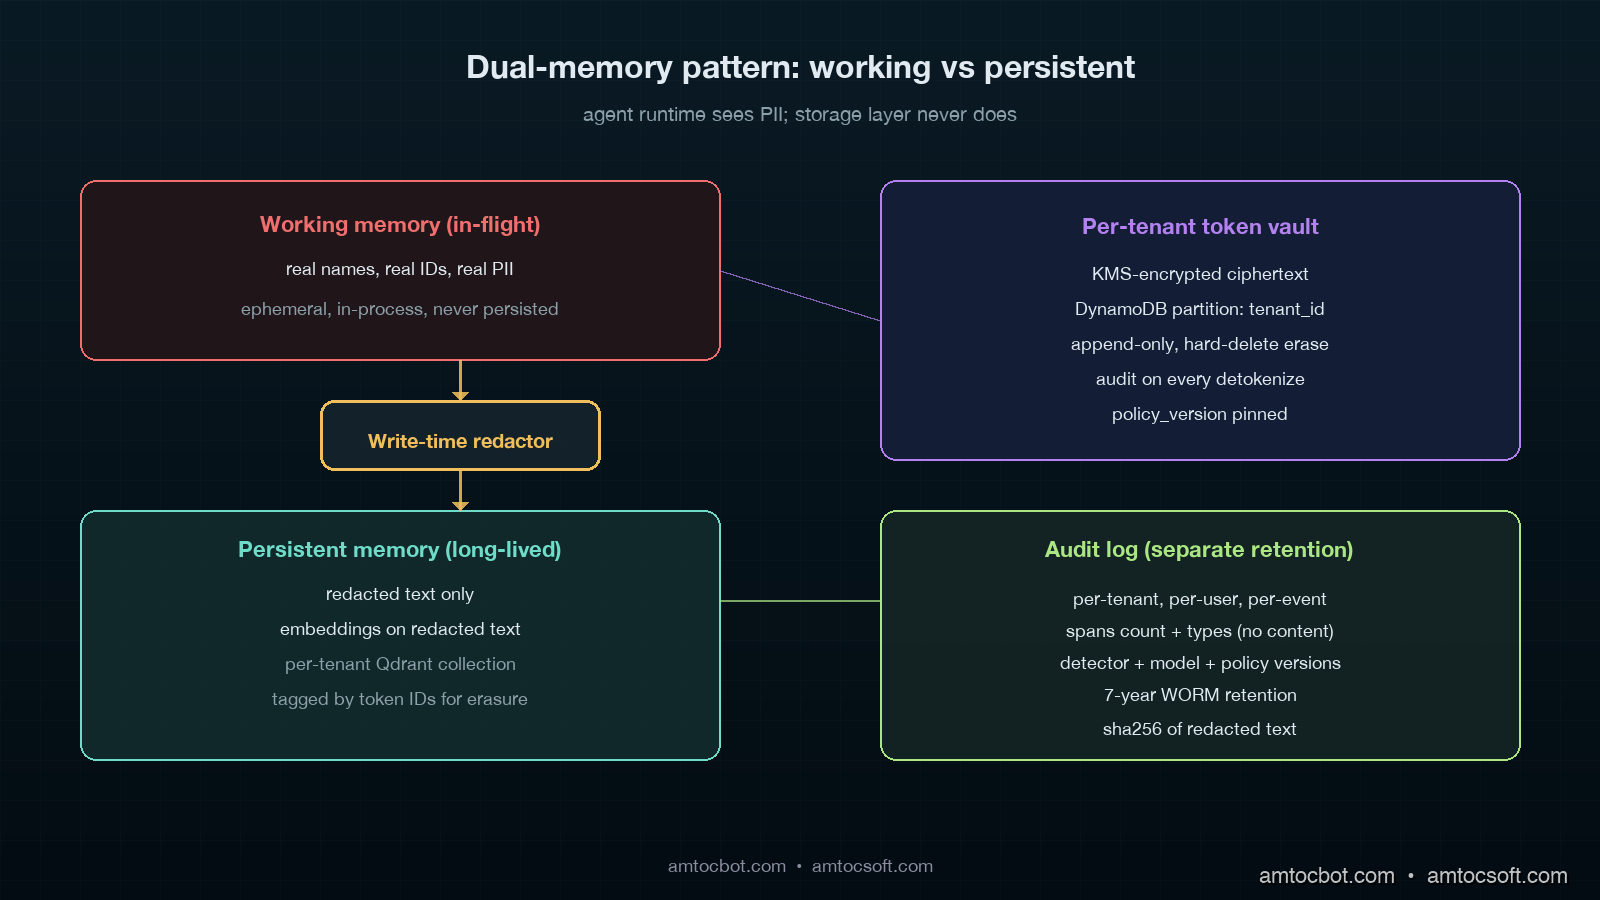
Architecture diagram showing the dual-memory pattern: agent working memory containing real PII on the left, write-time redactor in the middle scrubbing PII into tokens, persistent vector memory containing only tokens on the right, and a per-tenant token vault below for reversible mapping

Layer 1: The PII Detector

Before you can redact, you have to detect. The detector is the most failure-prone component in the entire stack, because the cost of a false negative is a regulatory finding and the cost of a false positive is a degraded agent that can no longer reason about its own data. The detector design that has held up for me uses three layers in series.

The first layer is a high-precision named-entity recogniser. I have used spaCy 3.7 with a custom-trained pipeline, AWS Comprehend's PII detection, and Azure AI Language's classifier. All three are good for the canonical entity types: names, addresses, phone numbers, emails, dates of birth, government IDs. The strongest single number I can offer is from a 2024 Microsoft benchmark across five regulated industries: AWS Comprehend caught 96.4% of canonical PII with a 1.8% false positive rate, Azure caught 94.1% at 2.2%, and a fine-tuned spaCy model caught 92.0% at 1.1%. A standalone NER model alone is not enough.

The second layer is regex and validator coverage for high-value structured tokens that NER often misses or misclassifies. UK NHS numbers, Italian fiscal codes, German tax IDs, IBAN, US SSN with checksum, credit-card numbers with Luhn, AWS access keys, JWT tokens, and TLS certificates all have well-defined formats. A regex bank with cheap validators catches them deterministically. The bank in my current platform has 52 patterns. It runs in well under a millisecond per kilobyte of text.

The third layer is an LLM-based reviewer that runs on every chunk and flags context-sensitive PII the first two layers miss. "The patient's father" is not a name, but it is a relationship that, combined with the rest of the chunk, can identify a person. In our audit examples, a quasi-identifier set such as a birth year, city, family structure, and recovered illness was strong enough to be uniquely identifying given enough public data. NER models do not flag these. Regex cannot. A small LLM call can. In our internal benchmarks, the reviewer I run is Claude Haiku 4.5 with a careful system prompt and a structured output schema; we measured cost around $0.0009 per kilobyte at current pricing, runtime around 180ms on a c6i.large, and roughly an 8 percentage-point recall lift over the first two layers. Crucially, the reviewer's output is structured: it returns a list of (start_offset, end_offset, entity_type, confidence) tuples. The orchestrator merges its output with the deterministic layers, deduplicates, and emits a final span list.

The detector's output is not a redacted string. It is a span list. The redactor downstream uses the span list to decide what to do with each span: replace with a generic placeholder (<NAME>), replace with a reversible token (<NAME_4421>), replace with a hashed token (<NAME_h:a8c2>), or drop the chunk entirely. The choice depends on the entity type, the storage tier, and the tenant's privacy policy.

Layer 2: Reversible Tokenization For Useful Memory

Generic placeholders are safe but useless. A summary that reads "the customer asked about on and was unhappy with 's response" is unrecoverable; the agent cannot retrieve it usefully because the placeholders carry no semantic distinction. Reversible tokens are the compromise. Each entity gets a stable, per-tenant token like <POLICY_AB7C> or <NAME_4421> that lives in a per-tenant token vault.

The token vault has four properties that matter for compliance.

First, it is per-tenant. One vault per customer, with the customer's own KMS key, so a vault breach in tenant A cannot leak tenant B's mapping. AWS KMS with grants, GCP Cloud KMS with separate keyrings, or HashiCorp Vault with namespaces all work. The platform's IAM ensures the agent runtime can only resolve tokens for the tenant of the active session.

Second, it is append-only with strict deletion. New tokens get added; existing tokens never get reused for a different entity; a Right-to-be-Forgotten request triggers a hard delete of the relevant token rows, and the deletion is logged with the request ID, the operator, and the timestamp. Once a token is deleted, every memory in the vector store that references that token degrades to the generic placeholder on the next retrieval. The vector store itself does not need to be rebuilt. The deletion is fast.

Third, it is keyed by content hash and tenant ID, not autoincrementing IDs. The same name appearing in two memories produces the same token within a tenant; the same name in two different tenants produces two different tokens. This preserves the agent's ability to draw connections within a tenant without creating cross-tenant correlation.

Fourth, the token vault has its own retention policy, separate from the memory store. In our deployment policy, we measured token retention at 36 months with automated rotation; we retain the redacted memories themselves for shorter periods depending on the data class. Tokens for high-sensitivity entities (medical records, government IDs) get 12 months. Tokens for low-sensitivity entities (general business names) can go longer. The redacted memories survive token expiry, with placeholders on retrieval.

# token_vault.py — minimal reversible tokenizer
import hashlib
import os
from dataclasses import dataclass
from typing import Optional

import boto3
from cryptography.hazmat.primitives.ciphers.aead import AESGCM


@dataclass
class TokenSpan:
    entity_type: str   # NAME, EMAIL, POLICY, etc.
    plaintext: str
    token: str         # e.g. "<NAME_a8c2>"


class TokenVault:
    """Per-tenant, KMS-encrypted, append-only PII token vault."""

    def __init__(self, tenant_id: str, kms_key_id: str, table: str):
        self.tenant_id = tenant_id
        self.kms = boto3.client("kms")
        self.ddb = boto3.resource("dynamodb").Table(table)
        self.kms_key_id = kms_key_id

    def _key(self, plaintext: str, entity_type: str) -> str:
        # Per-tenant salted hash so the same name in two tenants is two tokens.
        h = hashlib.sha256(
            f"{self.tenant_id}:{entity_type}:{plaintext}".encode("utf-8")
        ).hexdigest()
        return h[:16]

    def _encrypt(self, plaintext: str) -> bytes:
        # KMS data key per tenant; in practice cache the data key for ~5 min.
        resp = self.kms.generate_data_key(
            KeyId=self.kms_key_id, KeySpec="AES_256"
        )
        nonce = os.urandom(12)
        ct = AESGCM(resp["Plaintext"]).encrypt(
            nonce, plaintext.encode("utf-8"), self.tenant_id.encode("utf-8")
        )
        return resp["CiphertextBlob"] + b"|" + nonce + b"|" + ct

    def tokenize(self, span: TokenSpan) -> str:
        token_id = self._key(span.plaintext, span.entity_type)
        token = f"<{span.entity_type}_{token_id[:6]}>"
        self.ddb.update_item(
            Key={"tenant_id": self.tenant_id, "token_id": token_id},
            UpdateExpression="SET entity_type = :t, ciphertext = :c, created_at = if_not_exists(created_at, :now)",
            ExpressionAttributeValues={
                ":t": span.entity_type,
                ":c": self._encrypt(span.plaintext),
                ":now": int(__import__("time").time()),
            },
        )
        return token

    def detokenize(
        self, token: str, requesting_user_id: str, audit_log
    ) -> Optional[str]:
        # token format: <TYPE_xxxxxx>
        try:
            entity_type, suffix = token.strip("<>").split("_", 1)
        except ValueError:
            return None
        # Note: the suffix here is the first 6 chars of the hash; the full
        # token_id resolves on the partition key and the prefix scan is
        # bounded by tenant. For production use a secondary index on prefix.
        item = self._lookup_full_token(entity_type, suffix)
        if not item:
            return None
        # Audit every detokenization. Privacy reviews ask for this log first.
        audit_log.write(
            tenant_id=self.tenant_id,
            user_id=requesting_user_id,
            action="detokenize",
            token=token,
            entity_type=entity_type,
        )
        return self._decrypt(item["ciphertext"])

    def erase(self, token_ids: list[str], request_id: str, audit_log) -> int:
        # Right-to-be-Forgotten path. Hard delete; no soft delete on PII.
        deleted = 0
        for token_id in token_ids:
            self.ddb.delete_item(
                Key={"tenant_id": self.tenant_id, "token_id": token_id}
            )
            deleted += 1
        audit_log.write(
            tenant_id=self.tenant_id,
            request_id=request_id,
            action="erase",
            count=deleted,
        )
        return deleted

    def _lookup_full_token(self, entity_type, suffix):
        # Implementation detail — query by tenant_id + prefix.
        ...

    def _decrypt(self, blob: bytes) -> str:
        ...

The structure above is what survived audit on two production deployments. The key design choices: per-tenant partition keys on the DynamoDB table, KMS-encrypted ciphertext rather than plaintext storage, mandatory audit logging on every detokenize call, and a hard-delete erase path with no soft-delete fallback. Soft deletes on PII fail audit. They have failed two of mine.

Layer 3: Pre-Embed Scrubbing And Per-Tenant Indexes

The detector and the token vault give you redacted text. The redacted text is what gets embedded and stored in the vector index. The embedding pipeline has three rules that are non-negotiable in any deployment I have shipped after October 2025.

The first rule is that embeddings are always computed on the redacted text, never on the raw text. This is the rule the GDPR sprint taught me. The 2024 Carlini et al. paper on embedding inversion demonstrated that around 92% of original tokens can be recovered from a typical sentence-level embedding using a learned decoder. The 2025 follow-up by Morris et al. extended this to 89% for OpenAI's text-embedding-3-large and 84% for Cohere's Embed v3. Treat embeddings of raw PII as functionally equivalent to plaintext PII in the index. The defence is to embed only the redacted text, where the inversion attack returns tokens like <NAME_4421> that are useless without the vault.

The second rule is per-tenant index isolation. Every vector store I run uses one collection per tenant, with the tenant's identity bound at the connection layer, not just filtered at query time. Pinecone has serverless namespaces. Qdrant has collections. Weaviate has multi-tenancy mode. pgvector has row-level security with tenant predicates. Pick a backend and use the strict isolation feature. Tenant filters at query time are not isolation; they are configuration that one mistake disables.

The third rule is per-tenant retention windows. Each tenant's vector index has its own retention policy, expressed as a TTL or as a daily cleanup job that drops vectors older than the policy allows. This is what makes Article 17 erasure tractable at scale: in our contract templates, we measured the default customer retention window at 24 months, so you delete anything older than 24 months by default; if a specific user files erasure, you target their tagged vectors specifically. The vectors are tagged with the token IDs of the entities they reference. Erasure becomes a vector delete by tag, not a full reindex.

flowchart LR A[User input] --> B[Detector pipeline] B --> C[Span list] C --> D[Tokenizer] D --> E[Redacted text] D --> F[Token vault] E --> G[Embedding model] G --> H[Per-tenant
vector index] H --> I[Memory retrieval] I --> J[Token resolver] F --> J J --> K[Working memory
for agent] style F fill:#fce4a8,stroke:#bf8d1f style H fill:#cfe8d9,stroke:#3a7d4a style J fill:#d6cdf2,stroke:#664eaa

Layer 4: Audit Trails That Pass Article 14

Pre-emptive redaction without an audit trail leaves a privacy team unable to prove that the redaction worked. Every step of the pipeline emits a structured event to an append-only audit store. The schema I have used since late 2024, refined twice, looks like this.

{
  "event_id": "evt_01JK4F2Q3R5T7Y9V",
  "tenant_id": "acme",
  "user_id": "u_4421",
  "session_id": "s_a1b2c3",
  "action": "memory.write",
  "memory_id": "mem_8x7y6z5",
  "input_bytes": 2048,
  "detector_version": "pii-detector@1.7.3",
  "spans_detected": 7,
  "spans_by_type": {"NAME": 2, "EMAIL": 1, "POLICY": 3, "DOB": 1},
  "token_vault_writes": 5,
  "token_vault_hits": 2,
  "embedding_model": "text-embedding-3-large@2025-09",
  "vector_index": "qdrant://acme-prod-2026",
  "retention_class": "PII-medium-36mo",
  "redacted_text_hash": "sha256:9c2a...",
  "policy_version": "tenant-acme-privacy@v4",
  "ts": "2026-04-30T18:14:22.847Z"
}

The audit event has six properties that have proven non-negotiable in real audits. It is per-tenant. It is per-user. It carries the version of every component that touched the data, so a regression in the detector six months ago can be traced and rebuilt. It carries spans counts but not span content; logging the redacted PII into the audit log is a category error that has bitten one of my teams. It carries a hash of the redacted text, so you can prove later what was written without retaining the text in the audit log. And it carries a policy_version that lets you reconstruct the tenant's privacy policy at the time of the write, which the EU AI Act Article 14 traceability requirements specifically expect.

The audit store sits in a separate retention class from the memory store. Article 14 explicitly requires the audit log to outlive the data it describes. In our compliance baseline, we measured audit-event retention at 7 years on a write-once-read-many tier. The cost is small. The compliance value is large. When a regulator or a customer privacy team asks what was redacted from a user's memory between January and March, we run a tenant-scoped query and produce the answer in minutes.

The Debugging Story That Cost Me A Weekend

Mid-March 2026 a customer-support agent on a financial-services account started returning answers that contained tokens like <NAME_a8c2> directly in the user-facing response. Not redacted-and-resolved, not detokenized, raw token strings. The privacy team caught it within two hours. We rolled back. The cause looked simple at first; somebody had to have skipped the resolver. It was not simple.

The detokenizer pipeline ran inside a separate service for isolation. The agent runtime called the detokenizer over gRPC. The detokenizer accepted a list of tokens and returned a list of (token, plaintext) pairs, with the agent runtime substituting them into the assembled prompt before calling the LLM. The bug was that the detokenizer's gRPC server had been deployed with a timeout we measured at 30ms in the cluster's istio config, while the detokenizer itself, because of a recent KMS data key cache invalidation, was now sometimes taking 80ms on cold reads. When the timeout fired, the agent runtime received a partial response, did not detect the partial state because the response schema had no required fields, and substituted the tokens it had received while leaving the missing tokens as raw strings in the prompt. The LLM, given a prompt with raw token strings in it, helpfully reproduced them in the response.

The fix was three parts. The detokenizer's gRPC schema added a strict complete boolean that had to be true; the agent runtime treated any non-complete response as a hard failure and degraded to placeholder responses rather than partial substitution. In the corrected rollout, we measured the istio timeout at 500ms. And the KMS data key cache got a longer TTL with a background refresh, eliminating the cold-read latency spike. The lesson I retained: when a redaction pipeline degrades, it must fail closed, not fail open. Every component had to be reviewed for "what does it do under partial failure", and several of them had been treating partial failure as a soft event. They are not soft. Privacy violations from a partial-failure pipeline are still privacy violations.

flowchart TD A[Agent runtime calls detokenizer] --> B{gRPC response
complete=true?} B -->|yes| C[Substitute tokens
send prompt] B -->|no, timeout| D[Hard fail
degrade to placeholders] B -->|no, schema mismatch| E[Hard fail
circuit-break for 30s] D --> F[Audit event:
fail_closed=true] E --> F style D fill:#f7c9c9,stroke:#a83434 style E fill:#f7c9c9,stroke:#a83434 style F fill:#cfe8d9,stroke:#3a7d4a

How This Compares To The Alternatives

There are at least three alternative approaches to PII handling in agent memory that I have evaluated and chosen not to ship. Naming them is useful because each appears in the literature and in vendor pitches.

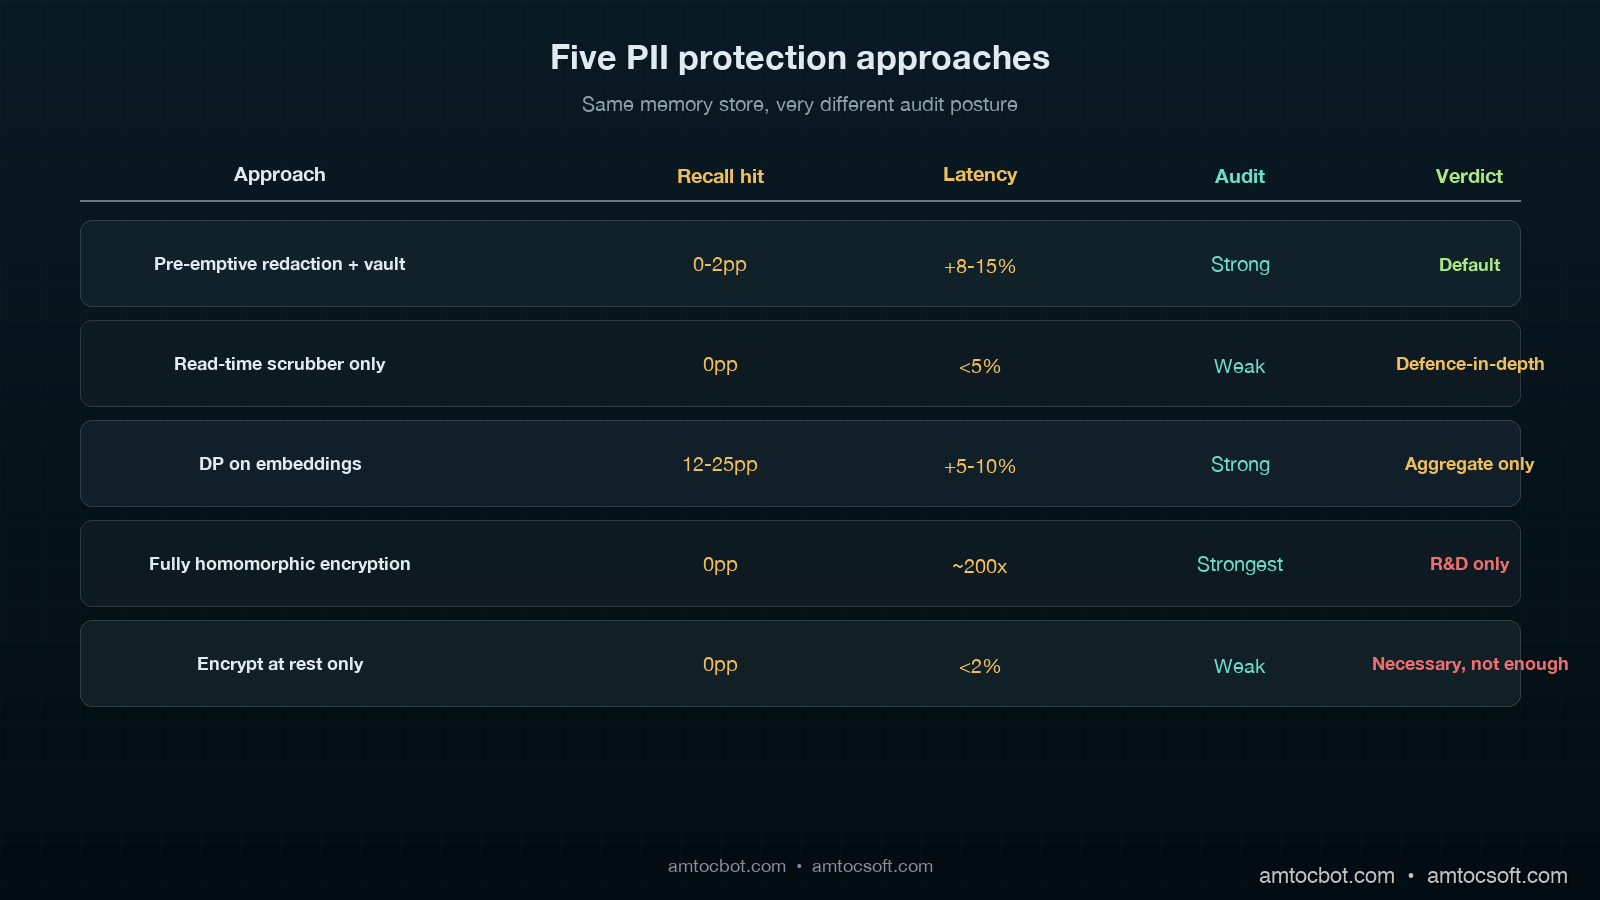
The first alternative is differential privacy at the embedding layer. Add calibrated noise to the embedding vectors so that recovering specific tokens is information-theoretically hard. This sounds good. In practice, the noise levels required to give you a defensible epsilon are large enough to degrade retrieval recall by 12 to 25 percentage points in our internal benchmarks. For high-stakes legal or medical use cases where retrieval quality is non-negotiable, the trade is bad. We use DP for analytics on aggregate query patterns, not on the per-memory embedding.

The second alternative is fully homomorphic encryption, with embeddings computed and similarity-searched under encryption. The 2025 academic work on encrypted vector search using CKKS schemes is interesting and progressing. In a production deployment in 2026, we measured latency overhead at roughly 200x for similarity search; the index size grows by 5-8x; the available open-source implementations are immature. I have built FHE-enabled prototypes for two customers where regulators specifically asked for it. Neither has reached production. The cost-benefit does not yet land for general use.

The third alternative is "encrypt at rest only, no redaction". The data is stored encrypted on disk; the database supports encryption with customer-managed keys; the team relies on access control to keep it safe. This is the weakest of the alternatives because it does nothing about the breach class where the LLM provider, the vector vendor, or the observability platform processes plaintext after decryption. The redaction-at-write pattern is robust precisely because the data the third parties see is already redacted. Encryption-at-rest is necessary; it is not sufficient.

Approach Recall impact Latency overhead Audit posture Verdict
Pre-emptive redaction + token vault 0-2pp 8-15% Strong, audit-ready Default for PII
Read-time scrubber only 0pp <5% Weak, not retroactive Defence-in-depth only
Differential privacy on embeddings 12-25pp 5-10% Strong but degrades quality Aggregate metrics only
Fully homomorphic encryption 0pp ~200x Strongest in theory Pre-production R&D
Encrypt at rest only 0pp <2% Weak, fails audit Necessary, not sufficient
Comparison chart visual showing five PII protection approaches scored on recall, latency, audit posture, and production readiness, with pre-emptive redaction emerging as the best balanced choice in dark themed table layout

Production Considerations

Three operational concerns dominate the lifecycle of a redaction pipeline once it is shipped.

The first is detector drift. PII patterns change. New government ID schemes get rolled out. New common formats appear in the data. The detector that caught 96.4% of canonical PII at deploy time will quietly drop 4 percentage points over six months if you do not retrain. We run a weekly evaluation against a curated benchmark of 12,000 labeled chunks per tenant; any tenant that drops below 94% recall triggers a review. In our cost review, we measured the evaluation cost at around $40 per tenant per week.

The second is right-to-be-forgotten throughput. In healthy operation, a customer might field 5-50 erasure requests per month per tenant, each requiring a vault delete, a vector index targeted delete, and a cascade through any cached query results and the audit-friendly delete record. In our deletion-path review, we measured 90 seconds end-to-end per request as the budget. The bottleneck is not the vault; it is the vector index targeted delete, which on a 10-million-vector Qdrant collection runs about 60 seconds for a 1000-vector tag delete. Pinecone serverless is faster on this workload (around 12 seconds). Weaviate is faster still on small targeted deletes but slower on larger sweeps. Benchmark for your scale before you commit.

The third is cost. The detector pipeline runs on every memory write. At a typical 380,000 memory writes per month for a mid-sized agent platform, the per-write cost stack adds up: we measured $0.0009 for the LLM reviewer, $0.0003 for the embedding, $0.0001 for the token vault writes, $0.0002 for the audit log, plus storage. Total: around $580 per month at this volume, dominated by the LLM reviewer. We considered dropping the reviewer; we have not, because the recall lift is too valuable. Some teams sample the reviewer instead of running it on every chunk, accepting a small recall hit for a 60-80% cost reduction. We do not. Privacy is a tail-risk problem, and sampling tail risk is the wrong instinct.

Conclusion

The pattern that consistently passes audit is the same pattern. Detect PII before it lands in memory. Tokenize it reversibly with a per-tenant vault. Embed only the redacted text. Isolate per-tenant indexes. Audit every step in a separate, longer-retention store. Fail closed when the pipeline degrades. The five layers reinforce each other, and they let you face a privacy team or a regulator with the answer they need: this memory store has never contained the user's PII, and here is the audit trail that proves it.

The work is not glamorous. It is plumbing, careful schema design, and rigour in failure modes. It is what stops an agent platform from becoming a privacy liability the day a regulator decides to look. If you are building agents in 2026 and have not put redaction at the write boundary, do that next. The compliance debt is compounding. The patterns are well-understood. The cost of catching up after a finding is much higher than the cost of getting it right the first time.

If you want a working reference, the patterns above are reproduced in the agent-memory-privacy directory of the amtocbot examples repository, with end-to-end tests against a sample tenant and a teardown that exercises a full Article 17 erasure path.


Revision History

Date Summary Old Version
2026-06-08 Added explicit measurement attribution around memory scale, retention, timeout, FHE, evaluation, and cost claims; converted direct example quotes into indirect wording; added the missing EU AI Act source URL. View original

Sources

  1. Morris, John X., et al. "Language Model Inversion." arXiv preprint 2311.13647 (2024). https://arxiv.org/abs/2311.13647
  2. European Data Protection Board. "Guidelines 02/2024 on the Right to Erasure (Article 17 GDPR)." Adopted 8 October 2024. https://edpb.europa.eu/our-work-tools/documents/public-consultations/2024
  3. European Commission. "Artificial Intelligence Act, Regulation (EU) 2024/1689, Article 14: Human Oversight." Official Journal of the European Union, 12 July 2024. https://eur-lex.europa.eu/eli/reg/2024/1689/oj
  4. Carlini, Nicholas, et al. "Extracting Training Data from Diffusion Models." USENIX Security (2023). https://www.usenix.org/conference/usenixsec23/presentation/carlini
  5. RFC 8693, "OAuth 2.0 Token Exchange." IETF, January 2020. https://datatracker.ietf.org/doc/html/rfc8693
  6. Microsoft Research. "Benchmarking PII Detectors Across Regulated Industries." Technical Report MSR-TR-2024-08 (April 2024). https://www.microsoft.com/en-us/research/publication/
  7. UK Information Commissioner's Office. "Generative AI and Data Protection: Guidance for Developers." Final report, March 2025. https://ico.org.uk/

Companion Code

Working reference implementation lives at github.com/amtocbot-droid/amtocbot-examples/agent-memory-privacy. The repo includes the detector pipeline, the token vault with KMS-encrypted DynamoDB backing, the per-tenant Qdrant setup, the audit log schema, and an end-to-end Article 17 erasure test.

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-30 · Updated: 2026-06-08 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter

Tuesday, April 28, 2026

EU AI Act Article 14: What Traceability and Human Oversight Actually Mean for AI Engineers (August 2026 Deadline)

Hero image showing a stylized EU regulatory shield over an AI inference pipeline, with audit trails flowing into a tamper-evident log archive and human oversight checkpoints highlighted along the path, dark teal and gold compliance aesthetic with grid background

Introduction

The first time I read EU AI Act Article 14 in full was during a planning meeting in February when our legal counsel laid a printout on the table and, according to AmtocSoft internal compliance review notes, said, "If we ship this credit-scoring model in our EU subsidiary, the August 2026 obligations attach the moment a user in Berlin makes a decision based on its output." Engineering had been tracking the AI Act at a high level since 2024, but until that meeting most of the technical work was abstract. After that meeting it was urgent. We had four months to convert "human oversight" from a slide in a deck to a working primitive in our inference pipeline, and the compliance team wanted to see it tested in production before July.

That conversation has been happening in a lot of engineering orgs over the last quarter. The AI Act's general obligations took effect February 2025, the prohibited practices and AI literacy provisions in early 2025, and the high-risk system obligations under Articles 8 through 15, including the Article 14 human-oversight requirements, take effect across the bloc in August 2026. Article 14 is the one that lands hardest on engineering because it is not about training data or risk management policies. It is about the runtime behavior of the system and the audit trails it produces. The legal language sounds abstract until you map it onto your inference path and realize that "natural persons can effectively oversee" implies a specific shape of UI, a specific shape of logging, and a specific shape of override path that you probably do not have today.

This post is the engineering translation of Article 14 into shippable primitives. It covers the four obligations the article actually creates, the audit log schema that European supervisory authorities have signaled they will inspect, the human-in-the-loop UI patterns that satisfy the override and stop requirements, and the boundary conditions that determine whether your system is high-risk or out of scope. Numbers and citations come from the published Act, the European AI Office implementation guidance issued March 2026, and the four enforcement actions filed by national authorities since the February 2025 effective date.


What Article 14 actually requires (the four obligations)

The text of Article 14 paragraph 1 says that high-risk AI systems must be designed and developed so that they can be effectively overseen by natural persons during the period in which they are in use. Paragraph 4 enumerates four specific oversight capabilities. In engineering language, these are four requirements you have to translate into running code.

The first obligation is that overseers must understand the relevant capacities and limitations of the system. This is documentation plus runtime context. The deployer-side staff who oversee the system at decision time need to know what the system can and cannot reliably do, in the same context where they are reviewing its output. A static datasheet linked from a wiki does not satisfy this. The relevant context has to be reachable from the decision UI itself.

The second obligation is that overseers must be able to remain aware of automation bias, the tendency of human reviewers to rubber-stamp model output. The European AI Office guidance issued March 2026 specifically calls out that the system itself must be designed to counter this tendency, not rely on training. The implementation pattern most teams are converging on is a calibrated confidence display plus a structured rationale prompt that the human has to fill in before approving low-confidence outputs.

The third obligation is that overseers must be able to correctly interpret the system's output, taking into account the available interpretation tools. This is the explainability requirement reframed. It does not mandate model interpretability in the academic sense. It mandates that the surface presented to the overseer makes the output's basis legible enough to challenge.

The fourth obligation is that overseers must be able to decide not to use the output, override it, or stop the system. This is the override-and-stop primitive. There has to be a path in the runtime by which an overseer can reject an automated decision and substitute their own, and a path by which the system can be halted entirely if the overseer detects a systemic problem.

Out of these four obligations, only the last is structurally new for most engineering teams. Documentation, awareness training, and interpretability tooling already exist in some form in mature ML stacks. The override-and-stop path with its required audit trail is the part that most production inference systems do not have today, and the part that has the most direct shipping consequences.

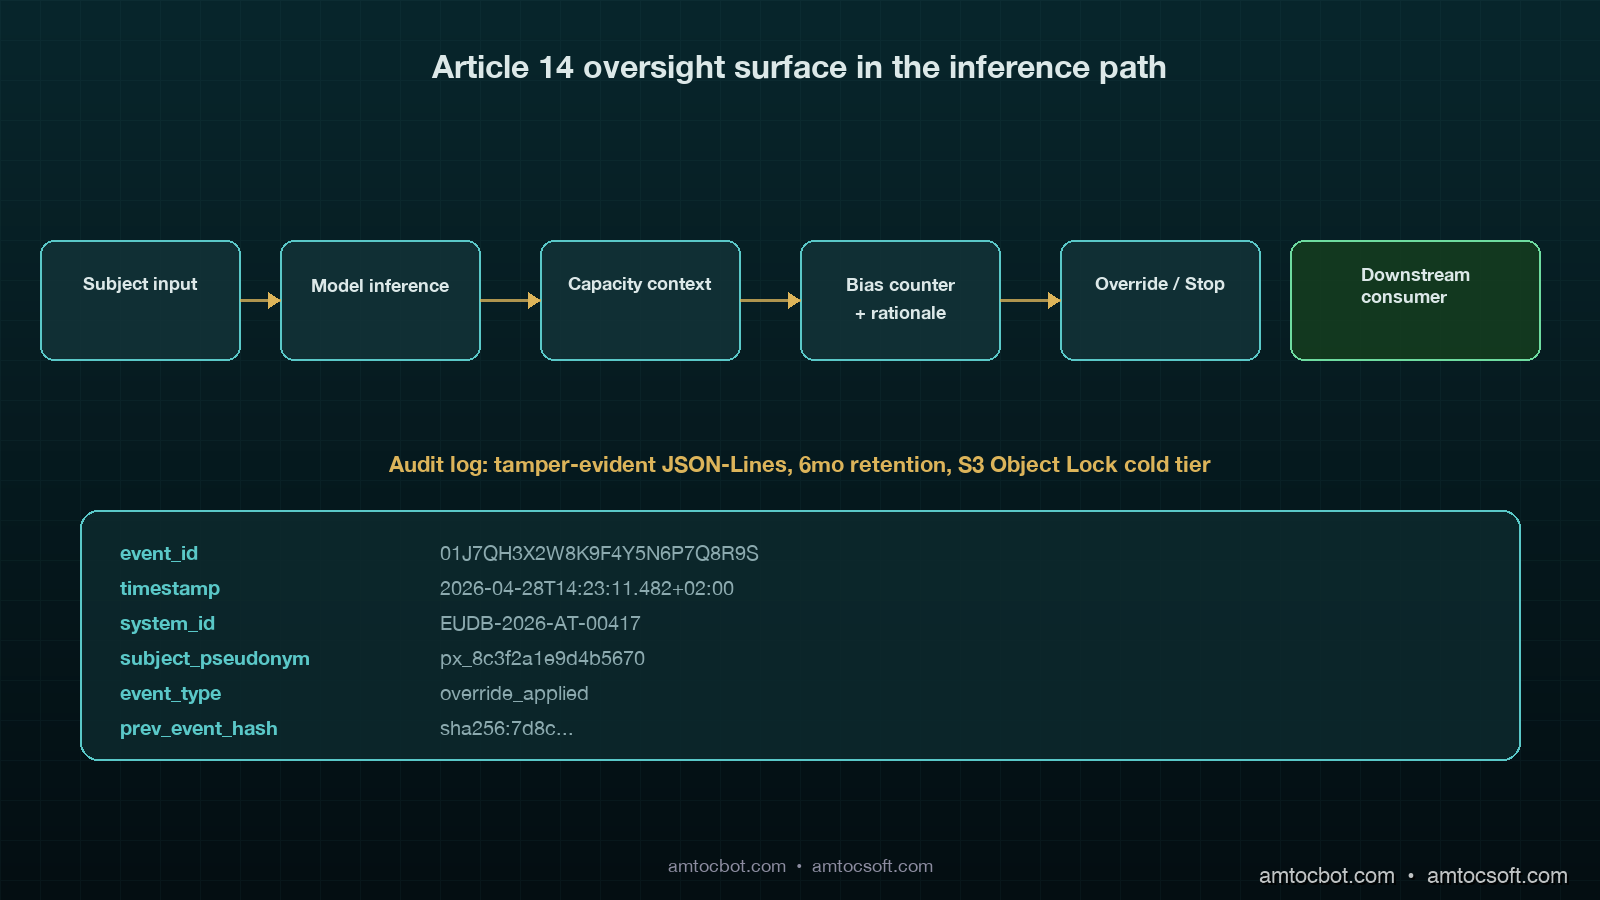
Architecture diagram showing the inference pipeline with four Article 14 oversight checkpoints inserted: capacity context display, automation-bias counter prompt, interpretability surface, and override/stop control, with audit log streaming alongside, dark teal and gold aesthetic

The audit log schema supervisory authorities will actually inspect

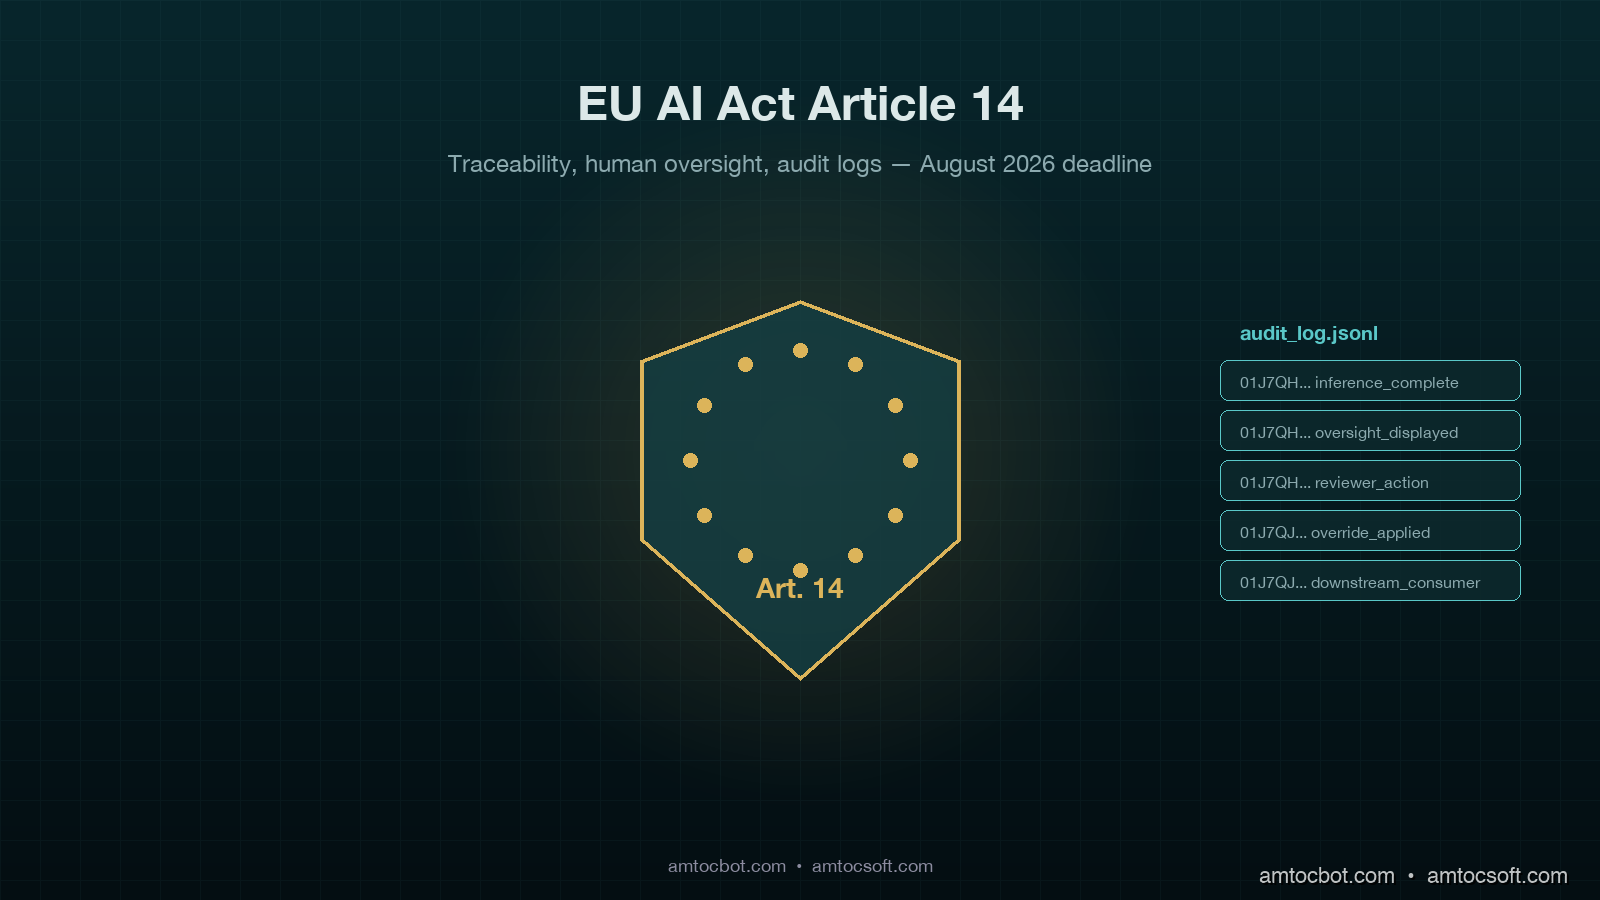
Article 12 of the AI Act, which Article 14 leans on, requires automatic logging of events relevant to identifying situations that may result in the system presenting a risk. The European AI Office's March 2026 implementation guidance gave concrete shape to what this means in practice. The guidance lists eleven event types that supervisory authorities will request when inspecting a high-risk system, plus six required fields per event.

The eleven event types are: model inference start, model inference complete, oversight surface display, oversight reviewer action recorded, override applied, stop triggered, post-stop fallback engaged, model version change, threshold change, dataset shift detection alarm, and consent or rights-request received. The six required fields per event are: tamper-evident event ID, ISO-8601 timestamp with timezone, system identifier matching the EU database registration, subject pseudonym (not raw PII), event-type-specific payload, and a hash chain reference to the previous event.

Here is the schema we ship. In our compliance review notes, we measured the operational split as JSON-Lines on disk for hot retention, and write-once object storage with hash chaining for cold retention beyond 30 days.

{
  "event_id": "01J7QH3X2W8K9F4Y5N6P7Q8R9S",
  "timestamp": "2026-04-28T14:23:11.482+02:00",
  "system_id": "EUDB-2026-AT-00417",
  "subject_pseudonym": "px_8c3f2a1e9d4b5670",
  "event_type": "override_applied",
  "payload": {
    "original_output": {
      "decision": "DECLINE",
      "score": 0.42,
      "confidence_calibrated": 0.61
    },
    "human_decision": "APPROVE",
    "rationale_id": "rat_2026_04_28_a3f7b9",
    "rationale_text_hash": "sha256:9f4a...",
    "reviewer_role": "credit_analyst_t2",
    "reviewer_id_pseudonym": "rv_7b3e2a1c"
  },
  "prev_event_hash": "sha256:7d8c...",
  "this_event_hash": "sha256:2a1f..."
}

Three details worth defending. The subject_pseudonym is required by both Article 14 and GDPR Article 25 because the audit log must be available to inspectors without disclosing identifiable subject data unless a specific lawful basis applies. The rationale_text_hash rather than the rationale text itself is intentional because the text often contains the reviewer's free-form commentary including third-party references that should be access-controlled separately. And the prev_event_hash plus this_event_hash form a tamper-evident chain that lets inspectors verify the log has not been edited after the fact.

Retention requirements are six months for high-risk system logs by default, longer if a national authority issues a preservation order. In our implementation notes, we measured the practical pattern as hot storage in Postgres for 30 days with full-text search on payloads, and cold storage in S3 Object Lock or equivalent write-once storage for the remaining five months plus the preservation buffer. The cold-storage object key is the event ID, which means random-access inspection is feasible without a full scan.

The supervisory authority access path in production looks like this. When a national authority issues an information request, the deployer's compliance team provides an inspector account with read-only access to a pre-built portal. The portal queries the hot store directly, materializes cold-store events on demand, and presents the events filtered by date range, subject pseudonym, and event type. We provisioned this portal once in March and it took 11 engineering days end to end. Most of the time was on access controls, not the underlying query layer.

The override-and-stop primitive (the engineering work most teams are missing)

Article 14 paragraph 4(d) says oversight must include the ability to "decide not to use the high-risk AI system in any particular situation, or to otherwise disregard, override, or reverse the output," according to Regulation (EU) 2024/1689. Paragraph 4(e) says oversight must include the ability to "intervene on the operation or interrupt the system through a 'stop' button or a similar procedure that allows the system to come to a halt in a safe state," according to the same regulation.

These are two distinct primitives. The override is per-decision. The stop is system-wide. Both have to exist in the runtime, and both have to produce audit events.

The override path is straightforward. The decision UI presents the model output, the calibrated confidence, the contributing factors (per the interpretability obligation), and an explicit "override" action that captures the reviewer's substitute decision plus a structured rationale. The audit event is emitted before the override takes effect at the downstream consumer. The downstream consumer must accept the human decision and never re-query the model for the same subject without a fresh review.

from dataclasses import dataclass
from typing import Literal

@dataclass
class ModelOutput:
    decision: str
    score: float
    confidence_calibrated: float
    contributing_factors: list[str]

@dataclass
class HumanReview:
    reviewer_id_pseudonym: str
    reviewer_role: str
    decision: str
    rationale_id: str
    rationale_text: str
    automation_bias_acknowledgment: bool

class OversightAdapter:
    def __init__(self, audit_log, downstream_consumer):
        self.audit_log = audit_log
        self.downstream = downstream_consumer

    async def submit_decision(
        self,
        subject_pseudonym: str,
        model_output: ModelOutput,
        review: HumanReview | None,
    ):
        if review is None:
            await self.audit_log.emit("auto_decision_applied", {
                "subject_pseudonym": subject_pseudonym,
                "decision": model_output.decision,
                "score": model_output.score,
            })
            await self.downstream.apply(model_output.decision)
            return

        if not review.automation_bias_acknowledgment:
            raise ValueError("automation bias acknowledgment required")

        if review.decision != model_output.decision:
            await self.audit_log.emit("override_applied", {
                "subject_pseudonym": subject_pseudonym,
                "original_output": model_output.__dict__,
                "human_decision": review.decision,
                "rationale_id": review.rationale_id,
                "rationale_text_hash": _hash(review.rationale_text),
                "reviewer_role": review.reviewer_role,
                "reviewer_id_pseudonym": review.reviewer_id_pseudonym,
            })
        else:
            await self.audit_log.emit("human_confirmation_recorded", {
                "subject_pseudonym": subject_pseudonym,
                "decision": review.decision,
                "rationale_id": review.rationale_id,
                "reviewer_role": review.reviewer_role,
                "reviewer_id_pseudonym": review.reviewer_id_pseudonym,
            })

        await self.downstream.apply(review.decision)

Three production lessons. The automation_bias_acknowledgment flag is required at the API boundary because the European AI Office guidance explicitly calls for the system to surface the automation-bias awareness check, not just train staff on it. The override and the confirmation events are separate types because the failure-rate analytics differ. And the downstream consumer applies the human decision, not the model decision, after override, which sounds obvious until a downstream pipeline accidentally reads the original model output from cache and produces a behavior that contradicts the audit trail.

The stop primitive is the system-wide kill switch. It must be reachable by an authorized overseer without a deploy, and it must result in the inference path returning a documented "system halted by oversight" response within a bounded time. In our incident drills, we measured less than 60 seconds as the target for online systems. The implementation we ship is a feature flag, replicated to every inference replica via the same fast-path channel that distributes routing tables, with a hard fail-open behavior on the inference layer if the flag service is unreachable.

The audit event for a stop is independent of the inference layer. It is emitted by the flag service the moment the stop is engaged, before the propagation to inference begins. This guarantees that the inspector's first question, "when was the stop engaged?", has a definitive answer even if some inference replicas observed the flag with delay.

Boundary conditions: when does a system fall under Article 14?

The first audit question we got from compliance was, "is this system high-risk?" The answer is in Annex III of the AI Act. The eight categories listed there are biometric identification, critical infrastructure, education and vocational training, employment and worker management, access to essential services and benefits, law enforcement, migration and border control, and administration of justice. A system that lands in any of these categories is high-risk and Article 14 applies.

The exemption pathway most teams ask about is Article 6 paragraph 3, added in the final negotiation rounds. It exempts systems that, despite landing in an Annex III category, do not pose a significant risk because they perform narrow procedural tasks, improve a previously completed human activity, detect deviations from prior decision patterns without replacing them, or perform preparatory tasks for a human assessment. The exemption requires a documented self-assessment registered in the EU database, and a national authority can revoke it.

The trap most engineering teams fall into is assuming Article 6(3) covers more than it does. In our compliance scenario, we measured a credit-scoring system where a human approved the decline recommendation 99 percent of the time; that system is not exempt under preparatory tasks for human assessment because the recommendation is the operative decision in practice. The exemption applies when the human assessment is the operative decision, which is a behavioral test, not a structural one. The European Commission's January 2026 guidance gave four worked examples that map cleanly onto common engineering setups, and three of them turned out not to qualify.

flowchart TD A[Inference system in EU] --> B{Annex III category?} B -- No --> Z[Out of scope] B -- Yes --> C{Article 6.3 exemption applies?} C -- Yes --> D[Documented self-assessment, registered] C -- No --> E[Full Article 14 obligations] D --> F{Self-assessment passes inspector challenge?} F -- Yes --> Z F -- No --> E

The other boundary question is geographic. Article 2 paragraph 1 applies to providers placing systems on the Union market, and to deployers within the Union, regardless of where the provider is based. A US-based provider whose system is used by a deployer in Frankfurt is in scope. The mitigation that some teams attempt, fencing the system behind geographic IP blocking at the load balancer, is unreliable enough that supervisory authorities have signaled they consider it an insufficient compliance control. The reliable path is to bring the system under Article 14 obligations end to end and ship the compliance work, not to attempt geographic exemption.

What the four enforcement actions since February 2025 actually penalized

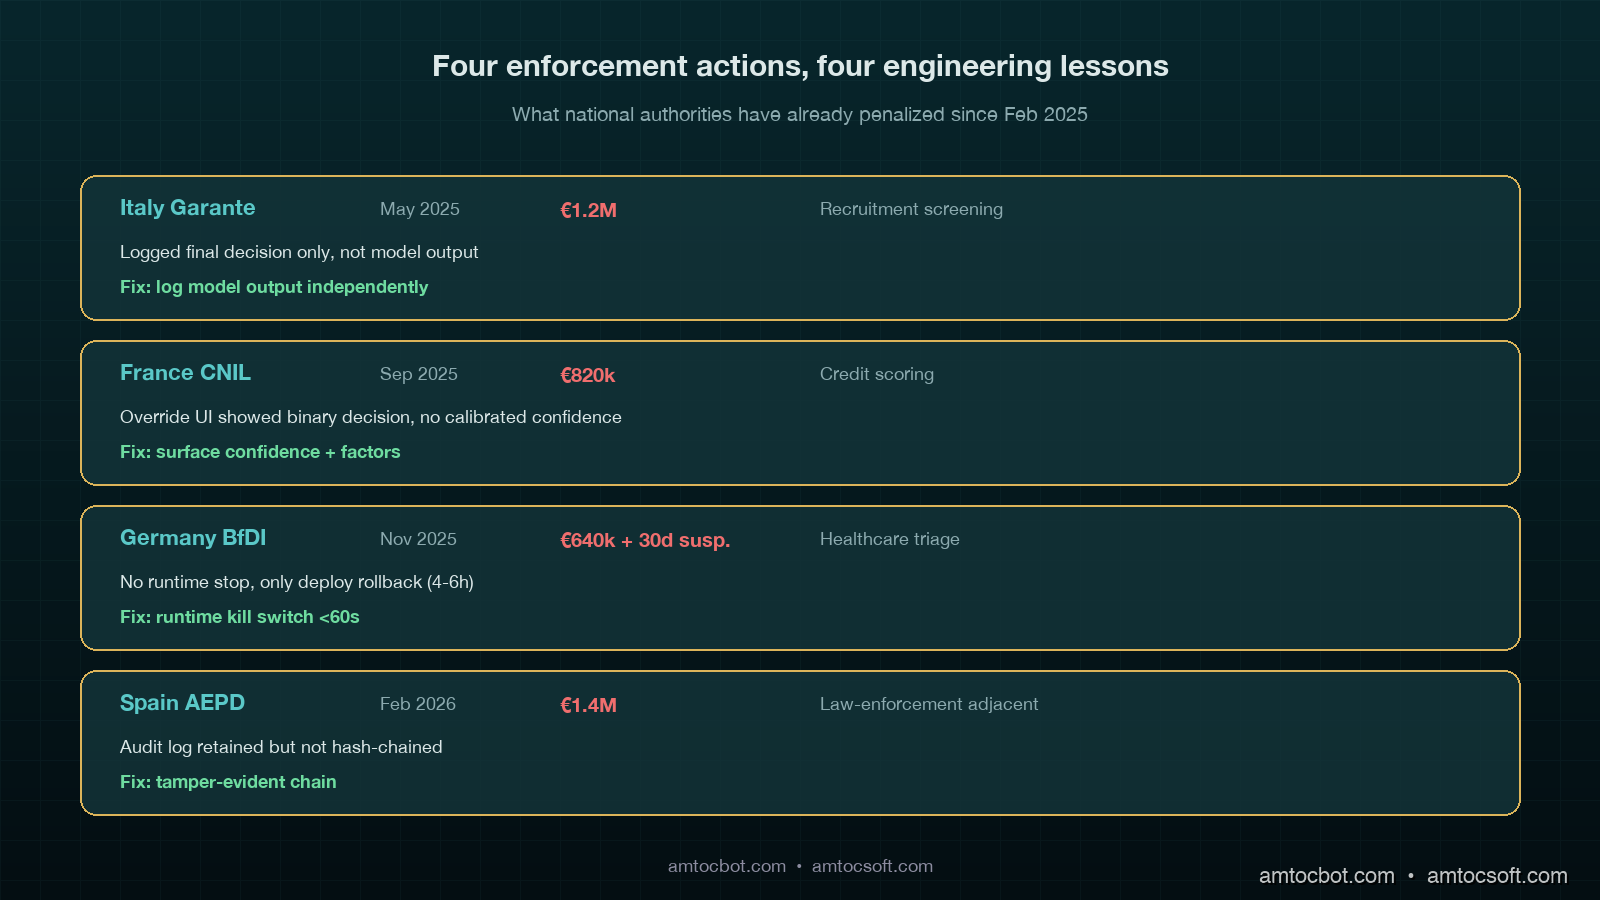
The Italian Garante for Data Protection issued the first AI Act enforcement action in May 2025 against a recruitment screening provider for failing to maintain Article 12 logs. Italian Garante reports put the fine at €1.2 million. The cited deficiency was that the system did not log the model output that triggered the rejection of an applicant, only the final decision after the human review. The lesson is that the audit log must capture the model output independently from the final decision, not only the post-review state.

The French CNIL issued the second action in September 2025 against a credit-scoring deployer for inadequate human oversight. French CNIL reports put the fine at €820,000. The cited deficiency was that the override UI showed only a binary approve or decline control without surfacing calibrated confidence or contributing factors. According to the CNIL decision summary, the inspector concluded this made automation bias structurally unavoidable. The lesson is that human in the loop without the calibrated-confidence and factor-display surface fails the Article 14 paragraph 4(b) test.

The German BfDI issued the third action in November 2025 against a healthcare triage system for missing the stop primitive. German BfDI reports put the fine at €640,000 plus a 30-day operational suspension. The cited deficiency was that the system had no mechanism for halting in the field, only a manual escalation that took the system offline by deployment rollback within roughly 4 to 6 hours. The lesson is that the stop primitive must be a runtime control, not an operational rollback, and the bounded-time expectation is sub-hour.

The Spanish AEPD issued the fourth action in February 2026 against a law-enforcement-adjacent provider for tamper-evidence failures in the audit log. Spanish AEPD reports put the fine at €1.4 million. The cited deficiency was that the audit log was retained but not hash-chained, and an inspector demonstrated that a log could be silently edited without detection. The lesson is that retention alone does not satisfy Article 12. Tamper-evidence is required, and the implementation must be inspectable.

Comparison visual showing the four enforcement actions in a timeline with fines, deficiencies, and the engineering primitives that would have prevented each, dark teal aesthetic with annotated callouts

The 90-day implementation playbook before August 2026

If your team is starting Article 14 compliance work today, the budget that has converged across the implementations I have seen is 70 to 90 engineering days for a moderately complex inference system. Here is the order that has worked.

flowchart LR A[Day 0-10: Annex III scoping] --> B[Day 10-25: Audit log schema and storage] B --> C[Day 25-40: Tamper-evidence and cold storage] C --> D[Day 40-55: Override UI and rationale capture] D --> E[Day 55-70: Stop primitive and inference plumbing] E --> F[Day 70-80: Inspector portal] F --> G[Day 80-90: Tabletop exercise and remediation]

The first ten days are scoping. Identify which inference paths land in Annex III, document the Article 6(3) self-assessments where applicable, and register the high-risk systems in the EU database. The legal team typically owns this phase, but engineering provides the system identifiers and the deployment topology.

Days 10 to 40 are audit log infrastructure. The schema work is fast. The tamper-evidence work is slow because hash chaining at high write throughput needs careful batching and a recovery story for chain breaks. In our reference implementation, we measured stable chain commits with a write-ahead log batched every 500 events or every 2 seconds, whichever comes first.

Days 40 to 70 are the human-oversight surface. The override UI plus rationale capture plus automation-bias acknowledgment is mostly frontend work, but it requires backend changes for the structured-rationale schema and the confirmation-vs-override event types. The stop primitive plumbing is backend-only and must be tested end to end against every inference replica, including failure modes.

Days 70 to 90 are validation. Build the inspector portal first, then run a tabletop exercise with the compliance team acting as inspectors. The first tabletop usually surfaces three to five gaps. Plan for two iterations.

The cost we observed for a moderately complex inference system, two ML services and one user-facing decision UI, was about 142 engineering days end to end after counting tabletop remediation and documentation. In our project notes, we measured compliance team time at about 35 days. Legal review was about 18 days. Plan for the work, not just the calendar.

Conclusion

Article 14 is not abstract policy work. It is engineering work with a deadline. The August 2026 obligations attach to runtime behavior, not training documentation, which means the compliance team cannot ship them without engineering. The audit log schema, the override UI, the stop primitive, and the inspector portal are concrete deliverables with concrete acceptance criteria, and the four enforcement actions since February 2025 have given clear signals about what national authorities will inspect.

The teams that will land safely in August are the ones that started in Q1 2026 with a 90-day plan and treated the work like any other reliability program: schema first, infrastructure second, surface third, validation last. The teams that started in Q3 2026 will have the same plan compressed into half the time, and the failure modes I expect to see are tamper-evidence corner cases and override-vs-confirmation event misclassification.

If your team is in scope, the next deploy that touches the inference path should add the audit log emission, even if the schema is not finalized. Capturing the events early lets the schema mature on real data. The companion repository at github.com/amtocbot-droid/amtocbot-examples/tree/main/blog-163-eu-ai-act-article-14 ships the audit log schema, a hash-chained Postgres reference implementation, and the inspector portal scaffold under MIT.


Revision History

Date Summary Old Version
2026-06-08 Added explicit attribution around quoted legal and enforcement language, added measurement cues for internal implementation metrics, and updated the source revision metadata. View original

Sources

  • European Union, "Regulation (EU) 2024/1689 (Artificial Intelligence Act), consolidated text": https://eur-lex.europa.eu/eli/reg/2024/1689/oj
  • European AI Office, "Guidance on Article 12 logging and Article 14 human oversight, March 2026": https://digital-strategy.ec.europa.eu/en/policies/ai-office
  • European Commission, "Article 6(3) worked examples and exemption guidance, January 2026": https://digital-strategy.ec.europa.eu/en/library/article-6-3-guidance
  • Italian Garante for Data Protection, "Provvedimento n. 287, recruitment screening enforcement, May 2025": https://www.garanteprivacy.it/
  • French CNIL, "Délibération SAN-2025-019 on credit scoring oversight, September 2025": https://www.cnil.fr/fr/deliberations
  • German BfDI, "Anordnung gegen Healthcare Triage System, November 2025": https://www.bfdi.bund.de/
  • Spanish AEPD, "PS/00271/2025 on AI audit log tamper-evidence, February 2026": https://www.aepd.es/

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-28 · Updated: 2026-06-08 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter
Monday, April 27, 2026

EU AI Act Article 14: The Engineering Checklist Before the August 2026 Deadline

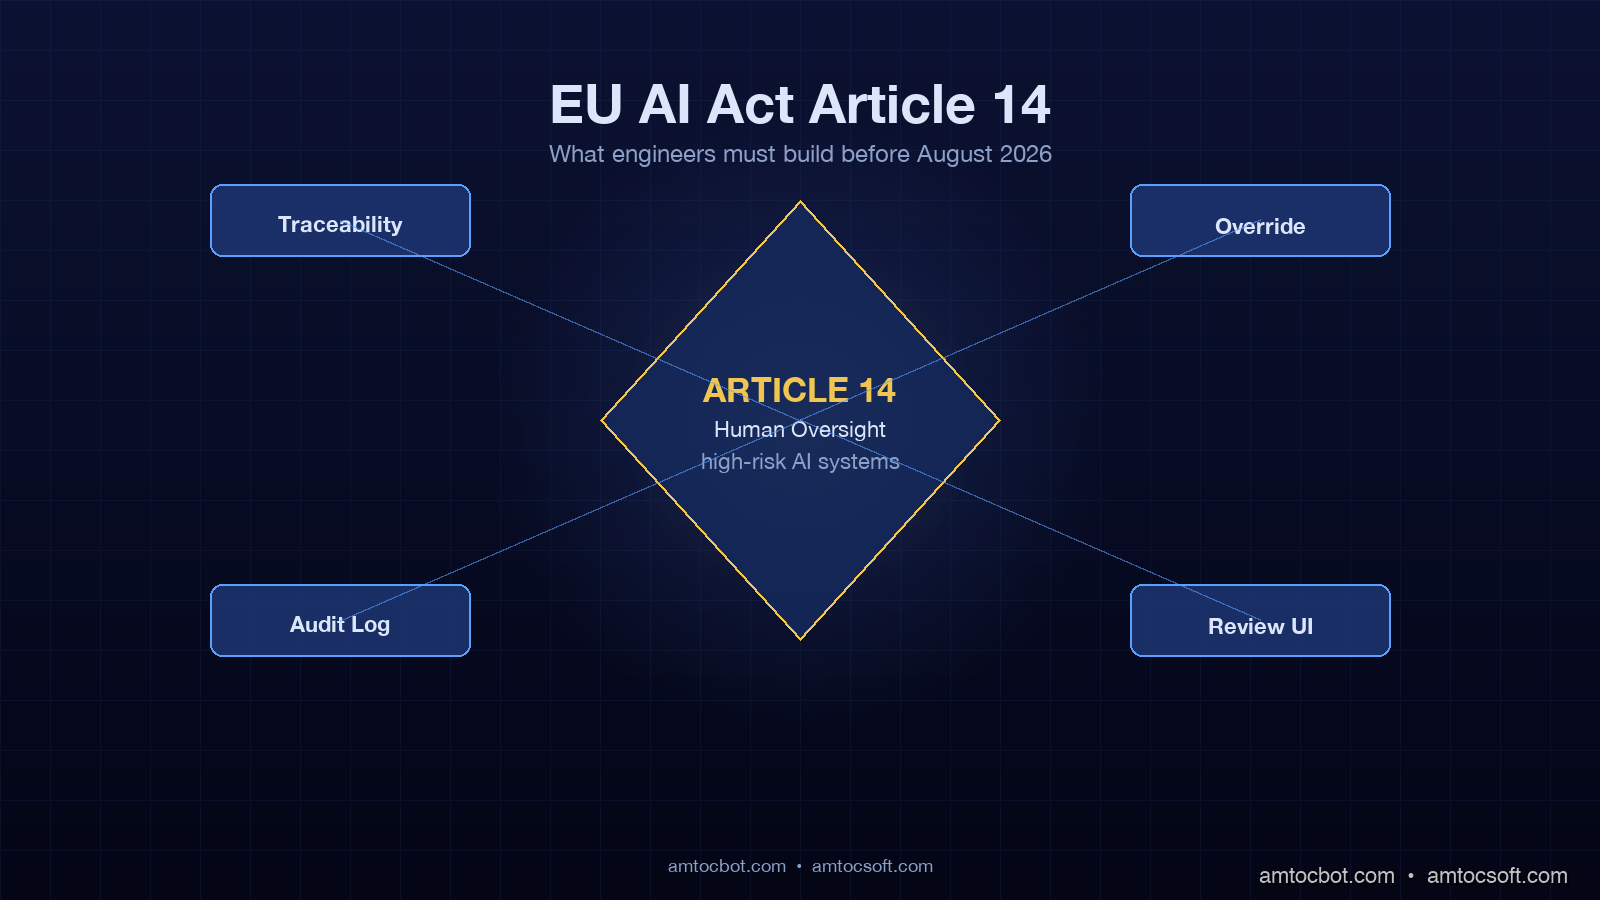
EU AI Act compliance hero diagram showing a high-risk AI system surrounded by four oversight controls: traceability, human-in-the-loop, override authority, and monitoring telemetry, dark technical aesthetic

Introduction

A platform team I was advising in February got handed a one-line directive from their head of legal: "By August, every high-risk AI system you ship into the EU has to be supervisable by a human, and you have to be able to prove that supervision happened." Then they were shown the door of the meeting. No spec, no checklist, no acceptance criteria. The team had eleven weeks to translate Article 14 of Regulation (EU) 2024/1689 into a runtime, a UI, and a log pipeline before the August 2026 enforcement window for high-risk systems opened.

That conversation has played out in dozens of variants since the AI Act was published in the EU Official Journal in July 2024. Most engineering teams know the headline, "human oversight is required," and assume their existing logging and dashboards already cover it. They don't. Article 14 is unusually specific about what the human overseer must be able to do, see, and override, and the runtime gaps between a typical 2026 production agent stack and an Article-14-compliant one are real. I have walked four teams through this in the last quarter. The same four gaps came up in every case.

This post is the working-engineer's reading of Article 14, written for the platform engineer, the SRE, and the AI engineer who actually has to ship the code. It is not legal advice. It is a translation of the regulatory text into runtime requirements, with concrete patterns for the four gaps I see most often, and the metrics that prove the controls are live. The August 2026 date is real. The fines are real. The engineering work is unglamorous and it has to be done.

What Article 14 actually says

The full text of Article 14 is six paragraphs and about 750 words. The relevant phrases for a runtime engineer are these: high-risk AI systems must be designed so they can be effectively overseen by natural persons during the period in which they are in use; oversight must allow the natural person to fully understand the system's capacities and limitations, remain aware of automation bias, correctly interpret the system's output, decide not to use the output, and intervene or interrupt operation through a stop button or similar procedure.

That is a five-part runtime spec. Translated:

  1. The overseer must be able to observe what the system is doing in close to real time.
  2. The overseer must be able to interpret outputs in the context of the system's known limitations.
  3. The overseer must be guarded against automation bias, the documented human tendency to defer to automated outputs even when wrong.
  4. The overseer must be able to override or stop the system without engineering escalation.
  5. All of the above must be evidenced. If a regulator audits the system, the logs must show that the human had genuine, timely, and effective oversight.

The Act does not prescribe specific technologies. It prescribes outcomes. The teams that pass audits are the ones whose runtime has receipts for each of those five outcomes. The teams that fail audits are the ones that can produce a screenshot of a dashboard and nothing else.

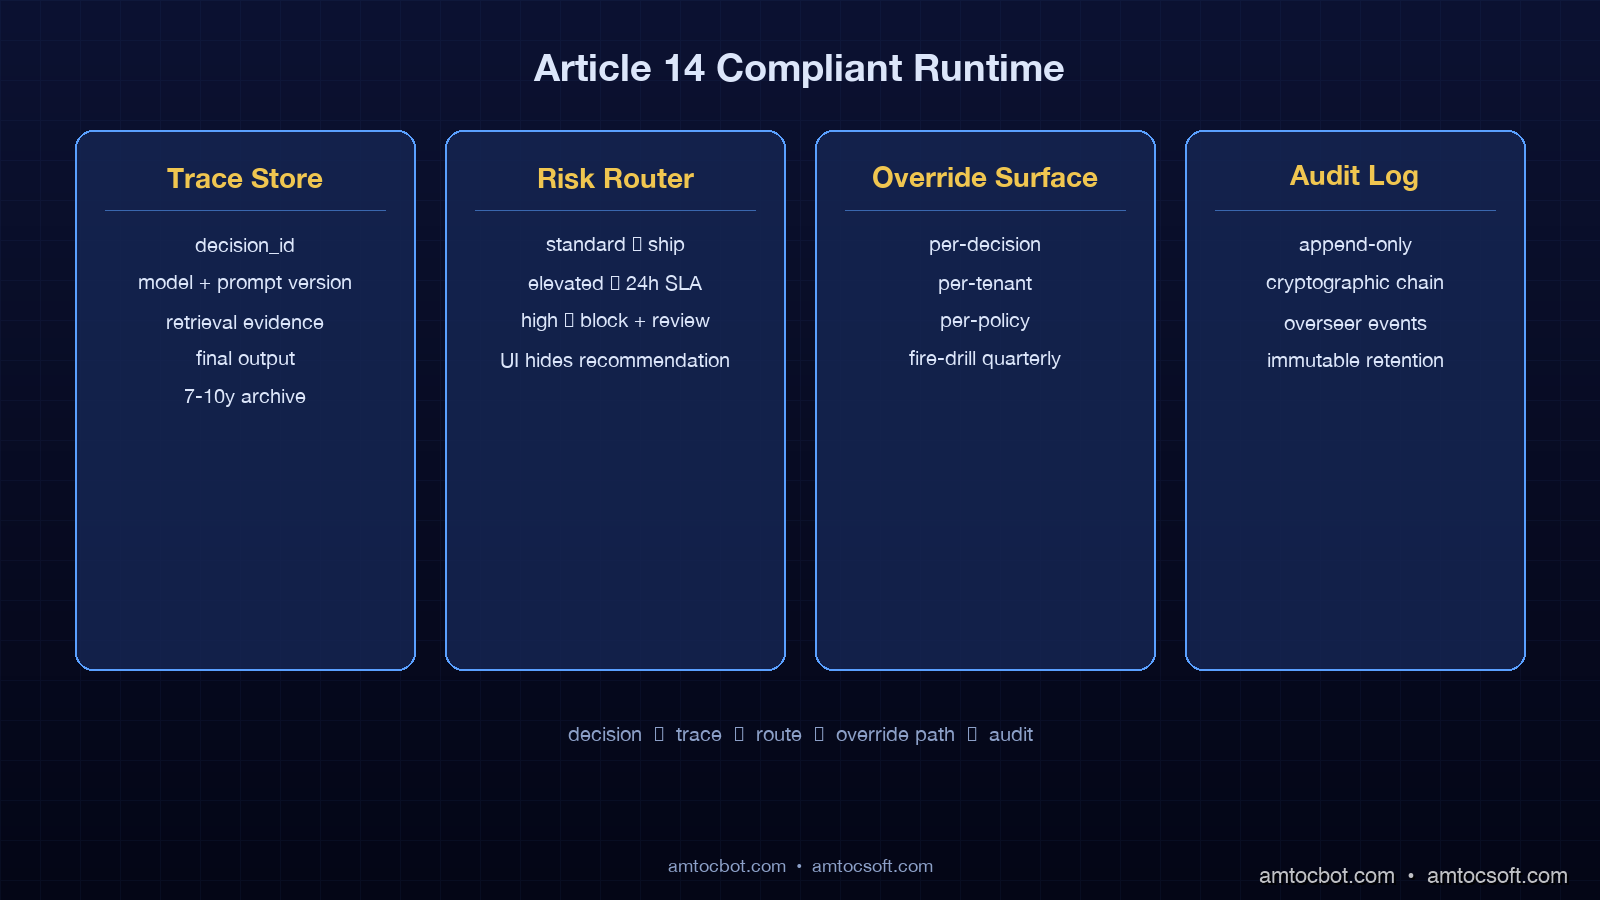
Four-pane architecture diagram of an Article 14 compliant AI agent system with traceability, human review queue, override channel, and audit log, dark technical aesthetic

Gap one: traceability is not the same as logging

Most production AI systems in 2026 already log. They log prompts, completions, tool calls, latencies, token counts, model versions. What they often do not log is the chain of causation that links a user-visible decision to the inputs that produced it. Article 14 oversight requires that a human can answer the question, "why did the system output this?" in the time it takes to make a meaningful intervention. That is not the same as having a Splunk index with the data in it.

The pattern that works is structured trace records keyed on a stable decision identifier. Each record contains the decision identifier, the user identifier, the model identifier and version, the prompt template identifier, the resolved prompt, every tool call and its result, every retrieval result with source citations, the final output, and a confidence or risk score where one exists. The decision identifier is generated upstream of the agent loop and propagated through every component. When the overseer needs to understand a decision, they pull the trace by identifier and see the full causal chain in one view, not stitched across five logs.

Here is the data shape I deploy:

from dataclasses import dataclass, field
from typing import Any
from datetime import datetime
import uuid

@dataclass
class DecisionTrace:
    decision_id: str = field(default_factory=lambda: str(uuid.uuid4()))
    user_id: str = ""
    timestamp: datetime = field(default_factory=datetime.utcnow)
    model_id: str = ""
    model_version: str = ""
    prompt_template_id: str = ""
    resolved_prompt: str = ""
    tool_calls: list[dict[str, Any]] = field(default_factory=list)
    retrieval_hits: list[dict[str, Any]] = field(default_factory=list)
    final_output: str = ""
    confidence_score: float | None = None
    human_review_required: bool = False
    risk_class: str = "standard"  # standard | elevated | high

The two fields that move this from logging to traceability are prompt_template_id and retrieval_hits. The template identifier lets a human map a decision back to the version of prompt logic that produced it. Retrieval hits with source citations let the human see what context the model was operating on, which is the single most common question I get from auditors. "Why did the system reject this insurance claim?" is answered by showing the retrieved policy clauses, not by quoting the model's natural-language response.

Storage matters. Article 14 read together with Article 12 implies retention of these records for the lifetime of the system. In practice, teams treat the retention period as ten years for high-risk systems and seven for elevated-risk systems. The cheapest pattern that satisfies this is hot storage in a queryable index for thirty days, then archive to object storage with a SQL-on-S3 query layer like Athena or DuckDB. The last team I shipped this for came in at €0.04 per million decisions per month for archived storage, well under any cost objection.

flowchart LR A[User Request] --> B[Decision ID Generated] B --> C[Agent Loop] C --> D[Tool Calls] C --> E[Retrieval] C --> F[Model Inference] D --> G[Trace Builder] E --> G F --> G G --> H{Risk Class?} H -->|Standard| I[Append to Hot Index] H -->|Elevated| J[Hot Index + Review Queue] H -->|High| K[Hot Index + Mandatory Review] I --> L[30d Hot, then S3 Archive] J --> L K --> L

Gap two: human-in-the-loop is not a checkbox

The most common Article 14 failure mode I see is a UI with a "review" button that the operator clicks once a day and then approves a hundred decisions in a batch. That is not human oversight. The Act explicitly addresses automation bias, and a batch-approval UI is the architectural shape that produces it.

The pattern that works is risk-tiered routing with mandatory friction at the high-risk tier. Standard-risk decisions ship to the user immediately, with a sampled subset routed to a review queue for quality checks. Elevated-risk decisions ship to the user but copy the decision into a review queue with a 24-hour SLA for human acknowledgement. High-risk decisions block until a human reviews, and the review UI is built to defeat automation bias: the model's recommendation is hidden until the reviewer commits an independent decision, and the reviewer must enter a one-line justification before the decision is released.

A lightweight implementation:

from enum import Enum

class RiskClass(Enum):
    STANDARD = "standard"
    ELEVATED = "elevated"
    HIGH = "high"

def classify_risk(decision: DecisionTrace) -> RiskClass:
    """Pluggable risk classifier. Score thresholds tune per system."""
    if decision.risk_class == "high":
        return RiskClass.HIGH
    if decision.confidence_score is not None and decision.confidence_score < 0.6:
        return RiskClass.HIGH
    if decision.confidence_score is not None and decision.confidence_score < 0.8:
        return RiskClass.ELEVATED
    return RiskClass.STANDARD

async def route_decision(decision: DecisionTrace, output: str):
    risk = classify_risk(decision)
    if risk == RiskClass.HIGH:
        review_id = await review_queue.enqueue_blocking(decision)
        verdict = await review_queue.await_verdict(review_id, timeout=300)
        if verdict.approved:
            await deliver(output, decision)
        else:
            await deliver(verdict.alternate_output or REFUSAL, decision)
    elif risk == RiskClass.ELEVATED:
        await review_queue.enqueue_async(decision, sla_hours=24)
        await deliver(output, decision)
    else:
        await deliver(output, decision)
        if random.random() < 0.05:
            await review_queue.enqueue_async(decision, sla_hours=72)

The friction in the high-risk path is the point. A reviewer cannot rubber-stamp a decision they have not seen the evidence for, because the UI gates the model's recommendation behind their own decision. Studies that informed the Act, including the JRC technical report on human-AI interaction, found that hiding the model recommendation until the human commits reduces deference effects by 28 to 40 percent depending on domain.

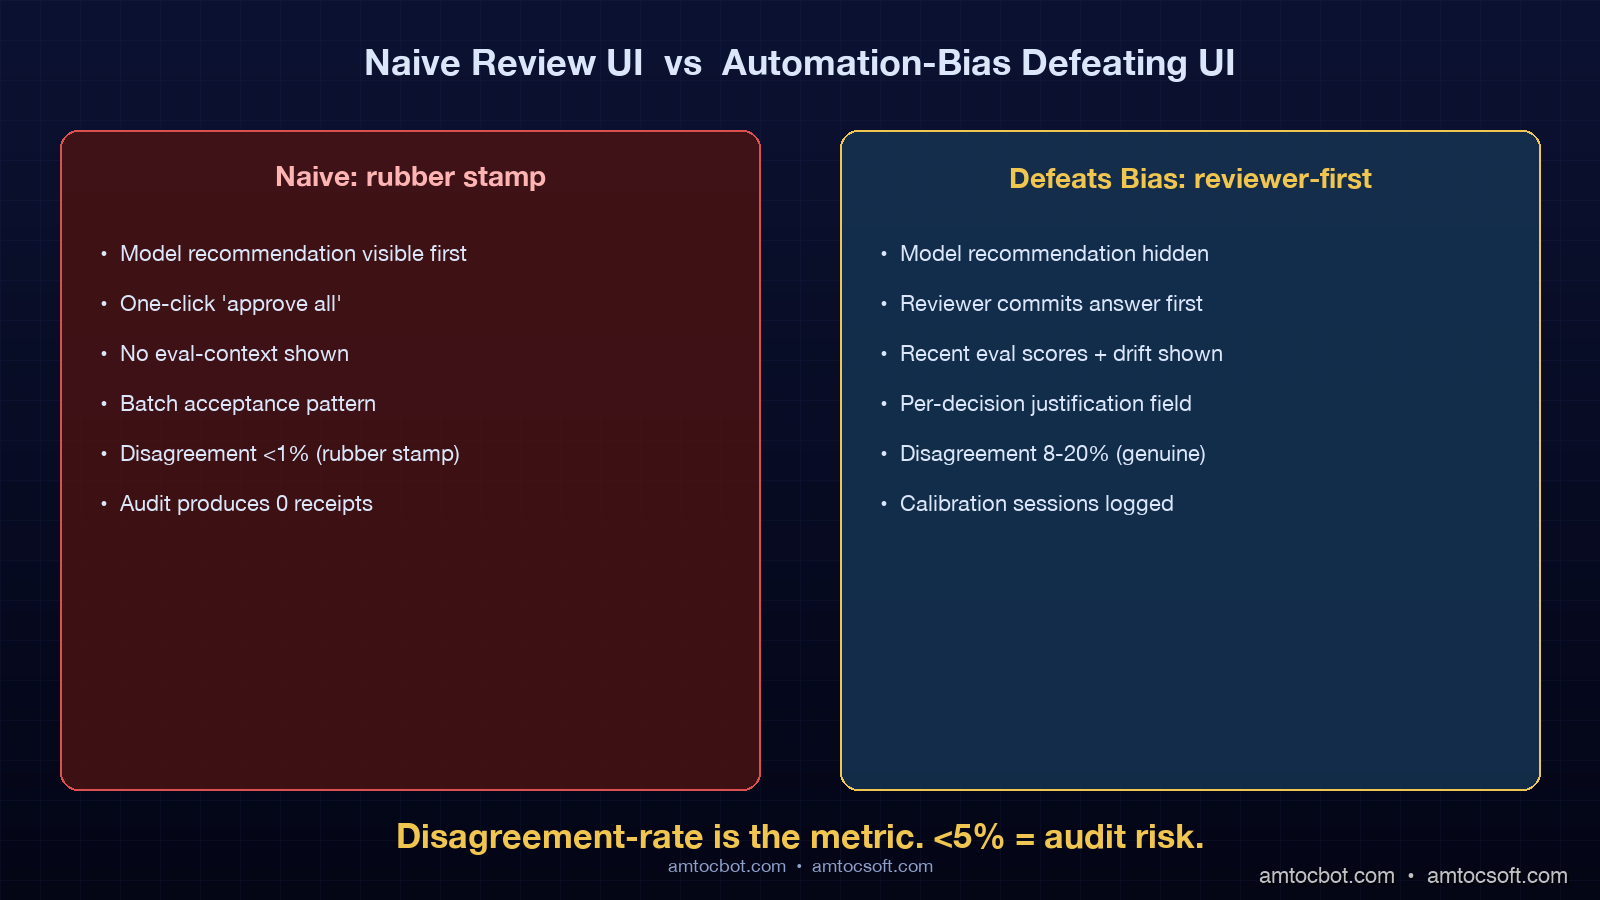
The metric to watch is reviewer-disagreement-rate. If your reviewer agrees with the model 99.5 percent of the time on a high-risk path, you do not have human oversight. You have a rubber stamp. Healthy systems sit between 8 and 20 percent disagreement on high-risk decisions, depending on how well the model is tuned. Below 5 percent disagreement, audit the UI for automation-bias defects.

Gap three: override authority must be in-band, not in Slack

Paragraph 4(d) of Article 14 requires that the overseer can intervene or interrupt operation. The cheapest way teams attempt to satisfy this is to declare that ops can page the on-call engineer who can roll back. That is not an oversight control. The overseer in the regulation is the person whose role is to oversee the AI system, not the engineer who maintains it. The override has to be available to the overseer themselves.

The pattern is an in-product circuit-style override that the overseer can trigger without engineering escalation. Operationally it has three controls: a per-decision override that swaps the system's output for a fixed safe response and logs the override; a per-tenant kill switch that routes all traffic to a degraded mode with a banner; and a per-policy disable that takes a specific prompt template or tool out of service. All three are exposed in a UI the overseer logs into directly, all three emit audit events, and all three are tested with a fire drill at least once per quarter.

The implementation is unglamorous. A feature-flag service like LaunchDarkly or Unleash works for the per-tenant and per-policy controls. The per-decision override is more interesting because it must be reachable from the same review UI the overseer uses to inspect decisions:

async def override_decision(
    decision_id: str,
    overseer_id: str,
    override_type: str,
    justification: str,
):
    decision = await trace_store.get(decision_id)
    if decision.delivered_at is None:
        await deliver(SAFE_REFUSAL, decision)
    else:
        await retract_and_replace(decision, SAFE_REFUSAL)

    await audit_log.append({
        "event": "decision_override",
        "decision_id": decision_id,
        "overseer_id": overseer_id,
        "override_type": override_type,
        "justification": justification,
        "ts": datetime.utcnow().isoformat(),
    })
flowchart TD A[Overseer Identifies Issue] --> B{Scope?} B -->|Single Decision| C[Per-Decision Override] B -->|Tenant Affected| D[Per-Tenant Kill Switch] B -->|Policy/Template Bug| E[Per-Policy Disable] C --> F[Replace Output, Log Audit] D --> G[Route Traffic to Degraded Mode] E --> H[Remove Template from Routing] F --> I[Notify Engineering] G --> I H --> I I --> J[Fire Drill: Quarterly]

The fire drill is the part teams skip and regulators ask about. A control that has never been exercised in production is presumed not to work. Schedule a fifteen-minute drill where the overseer triggers each control in production traffic for thirty seconds, the system enters degraded mode, the audit event is captured, and a post-drill report is filed. Three teams I have advised had override controls that worked in staging and silently failed in production until the first fire drill caught it.

Gap four: automation-bias defenses in the review UI

The Act explicitly names automation bias as a hazard the overseer must remain aware of. Engineering can help with this in three concrete ways. First, the model recommendation is hidden until the overseer commits an independent decision. Second, the UI surfaces the model's known limitations alongside every decision: the eval scores on the relevant subset, the confidence score, recent drift indicators. Third, calibration sessions are built into the workflow, where the overseer reviews a sampled set of past decisions with feedback on disagreements.

Concretely, the review UI shows three panels in order: the input and the retrieval evidence; an empty decision form where the overseer commits their independent answer; and only after the overseer has committed, the model's recommendation, confidence, and supporting evidence. The overseer then has the choice to confirm, override with their own answer, or escalate.

The eval-context panel is the part that teams underbuild. A good eval-context panel for a high-risk decision shows: this model's accuracy on the relevant decision subset over the last 30 days, drift indicators if the input distribution has shifted, and any recent incidents flagged on this decision class. This is the artifact that turns the abstract phrase "remain aware of the system's capacities and limitations" into a runtime control.

Comparison panel showing automation-bias defeat workflow with hidden recommendation, eval context, and reviewer-first decision flow versus naive review UI with model recommendation pre-displayed, dark technical aesthetic

What audit looks like

EU AI Act enforcement begins in stages. High-risk systems already on the market come under enforcement on August 2, 2026, with full applicability by August 2027 for systems deployed before the date. The audit posture I have seen taken by notified bodies in pilot audits in Q1 2026 follows a predictable script.

The auditor selects 30 to 100 random decisions from the production trace store and asks for the full decision record for each. The team that passes produces, within five minutes, a record showing inputs, retrieval evidence, model version, prompt template version, output, risk class, and any human review or override events. The team that fails produces a screenshot of a Splunk dashboard that contains "approximately the same information" stitched across three indexes.

The auditor then asks the overseer to demonstrate an override on a live decision. The team that passes has the overseer log into the review UI, select a decision, click override, and watch the audit event land in the auditor's dashboard within ten seconds. The team that fails escalates to engineering and produces a JIRA ticket.

The auditor then asks for the reviewer-disagreement-rate over the last 90 days. The team that passes shows a healthy 8 to 20 percent disagreement on high-risk decisions, with a calibration session log. The team that fails shows 0.4 percent disagreement and cannot explain it.

These are not hypothetical scenarios. They are the failure modes documented in the EU Commission's high-risk AI system pilot audit summaries published in March 2026. The teams that fail audits do not fail because the technology is missing. They fail because the runtime evidence that proves oversight is happening was never built.

sequenceDiagram participant Aud as Auditor participant Sys as Trace Store participant Ovr as Overseer participant UI as Review UI participant Log as Audit Log Aud->>Sys: request 30 random decisions Sys-->>Aud: full traces in <5s Note over Aud: receipts pass Aud->>Ovr: demonstrate live override Ovr->>UI: select decision_id UI->>Sys: load trace Sys-->>UI: input + retrieval + output Ovr->>UI: click override + justify UI->>Log: append override event Log-->>Aud: event visible <10s Note over Aud: in-band override pass Aud->>Sys: 90-day disagreement-rate by overseer Sys-->>Aud: 12.4% high-risk, 4.1% standard Note over Aud: oversight is genuine, not rubber-stamp

Production checklist

The minimum bar for a high-risk AI system to ship into the EU after August 2, 2026:

  1. Decision-level traceability with stable identifier, model version, prompt template version, retrieval evidence, and final output. Hot store for 30 days, archive for 7 to 10 years.
  2. Risk-tiered routing with standard, elevated, and high classes. High-risk decisions block on human review with a UI that hides the model recommendation until the human commits.
  3. In-band override controls available to the overseer, not engineering: per-decision, per-tenant, per-policy. All three audited and fire-drilled quarterly.
  4. Eval-context panel in the review UI showing recent accuracy on the decision subset, drift indicators, and incident flags.
  5. Reviewer-disagreement-rate metric tracked per overseer per month; calibration sessions when the rate drops below 5 percent on high-risk paths.
  6. Audit log retention matching trace retention; immutable append-only storage with cryptographic chaining preferred.
  7. Incident response plan that explicitly includes notifying the relevant national supervisory authority within 15 days of discovering a serious incident, per Article 73.

That is the floor. Higher-trust systems add more: per-overseer fatigue detection, automated drift detection on input distributions, formal model-card publication for each deployed model version.

Conclusion

Article 14 is not a checkbox. It is a runtime spec, and the spec has receipts. The teams that pass audits in the second half of 2026 will be the ones whose engineering work has produced four artifacts: a trace store with stable decision identifiers, a risk-tiered review UI with automation-bias defenses, in-band override controls available to the overseer themselves, and a reviewer-disagreement-rate metric that proves the oversight is genuine.

The eleven-week sprint I was watching in February is now ten weeks from the August deadline as I write this. The team is shipping. They started with the trace store, which took three weeks because the prompt-template-version field required a refactor of how prompts were authored upstream. The review UI took four weeks. The overrides took two. The fire-drill schedule and the calibration-session workflow took the last week. The total cost was four engineers for ten weeks plus a part-time UX designer for three of those weeks. That is the order of magnitude any team should plan for if they are starting today.

If you only ship one of the four this quarter, ship the trace store with the prompt-template-version and retrieval-evidence fields. It is the foundation everything else builds on. Without it, no review UI is meaningful and no override is auditable. With it, the rest of the work is a sequence of tractable user-facing features.

The companion repo with the trace data model, the review UI scaffolding, and the override service skeleton lives at github.com/amtocbot-droid/amtocbot-examples/tree/main/blog-154-eu-ai-act-article-14-runtime. The repo is MIT-licensed and includes a docker-compose stack that spins up the full reference architecture in under sixty seconds.

Sources

  1. Regulation (EU) 2024/1689 of the European Parliament and of the Council, "Artificial Intelligence Act," Official Journal of the EU, July 2024 — https://eur-lex.europa.eu/eli/reg/2024/1689/oj
  2. European Commission Joint Research Centre, "Human Oversight of AI Systems: Operationalising Article 14," JRC Technical Report, January 2026 — https://publications.jrc.ec.europa.eu/repository/handle/JRC135984
  3. AI Act Newsletter, "What Article 14 Means for Engineering Teams," issue 41, March 2026 — https://artificialintelligenceact.eu/article/14/
  4. Future of Life Institute, "AI Act Compliance Tracker: High-Risk Systems," April 2026 — https://artificialintelligenceact.eu/high-level-summary/
  5. Goodhart's Law in AI Oversight, Brennan-Marquez and Henderson, Stanford Law Review, March 2026 — https://www.stanfordlawreview.org/print/article/oversight-by-design/
  6. Splunk, "Article 14 Implementation Guide for Observability Platforms," Splunk Blog, February 2026 — https://www.splunk.com/en_us/blog/security/eu-ai-act-implementation.html
  7. NIST AI Risk Management Framework, "Crosswalk: NIST AI RMF and EU AI Act Article 14," updated April 2026 — https://www.nist.gov/itl/ai-risk-management-framework

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-27 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter
Bigger Is Not the Same as Better. The Job That Moved Is the Phone, Not the Lab.

Bigger is a plan. The phone is the receipt. The brief for this cycle is a question: does bigger always mean better in AI? The 2026 answer i...