Showing posts with label grpc. Show all posts

Wednesday, April 15, 2026

gRPC in Production: Protocol Buffers, Streaming, and Why REST Isn't Always the Answer

Hero: gRPC vs REST performance comparison with latency and throughput charts

REST with JSON is the default for web APIs. It's readable, flexible, and works everywhere. It's also 3-10× slower than gRPC for service-to-service communication, requires manual schema documentation, and has no built-in streaming semantics.

gRPC is the alternative for internal microservices and high-throughput APIs: binary serialization with Protocol Buffers, HTTP/2 multiplexing, bi-directional streaming, and code generation in 12 languages from a single .proto schema. In 2026, gRPC is standard for service meshes, ML inference pipelines, and any internal API where latency and throughput matter.

The Problem: REST at the Wrong Layer

REST over JSON was designed for client-server communication across the public internet — where human readability matters and client diversity is unpredictable. Applied to internal microservice communication, its characteristics become costs:

JSON parsing overhead: Serializing a complex object to JSON and back is 5-10× slower than Protocol Buffer serialization. At 10,000 RPC calls/second, this overhead compounds.

No schema enforcement: REST with JSON has no built-in contract. A service changes a field name; clients break silently. API versioning is manual and inconsistent.

HTTP/1.1 head-of-line blocking: A slow request blocks subsequent requests on the same connection. HTTP/2 multiplexes multiple requests over a single connection — a slow stream doesn't block others.

No streaming: REST request-response is fundamentally single-shot. Real-time streaming (model inference tokens, log tailing, live data feeds) requires workarounds: SSE, WebSockets, or polling.

gRPC solves all four using HTTP/2 as transport, Protocol Buffers as serialization, and code generation to enforce the contract at compile time.

graph LR subgraph "REST / JSON" A[Client] -->|HTTP/1.1 + JSON text| B[Server] B -->|JSON response| A A -.->|"Each request: parse JSON\nNo streaming\nNo schema"| A end subgraph "gRPC" C[Client] -->|HTTP/2 + Protobuf binary| D[Server] D -->|Binary response| C C -.->|"Binary: 5-10× faster\nStreaming built-in\nSchema enforced"| C end style A fill:#f59e0b style C fill:#22c55e,color:#fff

How It Works: Protocol Buffers and Code Generation

The center of gRPC is the .proto file — a language-agnostic schema that defines your service and message types. This single file generates client and server code in Python, Go, Java, TypeScript, Rust, and more.

// payments.proto
syntax = "proto3";

package payments.v1;

option go_package = "github.com/myorg/payments/gen/go/payments/v1;paymentsv1";

// Service definition — the RPC contract
service PaymentService {
  // Unary RPC: single request, single response
  rpc ChargeCard(ChargeRequest) returns (ChargeResponse);

  // Server streaming: single request, stream of responses
  rpc StreamTransactions(TransactionStreamRequest) returns (stream Transaction);

  // Client streaming: stream of requests, single response
  rpc BatchCharge(stream ChargeRequest) returns (BatchChargeResponse);

  // Bidirectional streaming: stream in both directions
  rpc PaymentChat(stream PaymentMessage) returns (stream PaymentMessage);
}

message ChargeRequest {
  string customer_id = 1;
  int64 amount_cents = 2;
  string currency = 3;         // "USD", "EUR", etc.
  string idempotency_key = 4;  // Prevents double-charges
  optional string description = 5;
}

message ChargeResponse {
  string transaction_id = 1;
  ChargeStatus status = 2;
  string processor_reference = 3;
  int64 processed_at_unix = 4;
}

enum ChargeStatus {
  CHARGE_STATUS_UNSPECIFIED = 0;  // proto3: always have a zero value
  CHARGE_STATUS_SUCCESS = 1;
  CHARGE_STATUS_DECLINED = 2;
  CHARGE_STATUS_ERROR = 3;
}

message Transaction {
  string id = 1;
  string customer_id = 2;
  int64 amount_cents = 3;
  string currency = 4;
  int64 created_at_unix = 5;
}

message TransactionStreamRequest {
  string customer_id = 1;
  int64 since_unix = 2;  // Stream transactions after this timestamp
}

message BatchChargeResponse {
  int32 total = 1;
  int32 succeeded = 2;
  int32 failed = 3;
  repeated string failed_idempotency_keys = 4;
}

Generate code:

# Install protoc + gRPC plugins
pip install grpcio grpcio-tools

# Generate Python client and server code from .proto
python -m grpc_tools.protoc \
  -I. \
  --python_out=./gen/python \
  --grpc_python_out=./gen/python \
  payments.proto

This generates payments_pb2.py (message types) and payments_pb2_grpc.py (service stubs). When the .proto changes, regenerate — mismatches are caught at import time, not at runtime.

Implementation: Server and Client

Python gRPC Server

import grpc
from concurrent import futures
import payments_pb2
import payments_pb2_grpc
import logging
import time

class PaymentServicer(payments_pb2_grpc.PaymentServiceServicer):
    """Implements the PaymentService defined in payments.proto"""

    def ChargeCard(self, request, context):
        """Unary RPC: charge a card and return the result."""
        # Validate request
        if request.amount_cents <= 0:
            context.set_code(grpc.StatusCode.INVALID_ARGUMENT)
            context.set_details("amount_cents must be positive")
            return payments_pb2.ChargeResponse()

        if not request.idempotency_key:
            context.set_code(grpc.StatusCode.INVALID_ARGUMENT)
            context.set_details("idempotency_key is required")
            return payments_pb2.ChargeResponse()

        # Check idempotency (deduplication)
        existing = idempotency_store.get(request.idempotency_key)
        if existing:
            return existing  # Return cached result — safe to retry

        # Process charge
        try:
            result = stripe_client.charge(
                customer=request.customer_id,
                amount=request.amount_cents,
                currency=request.currency,
            )

            response = payments_pb2.ChargeResponse(
                transaction_id=result.id,
                status=payments_pb2.CHARGE_STATUS_SUCCESS,
                processor_reference=result.balance_transaction,
                processed_at_unix=int(time.time()),
            )
            idempotency_store.set(request.idempotency_key, response, ttl=86400)
            return response

        except stripe.CardError as e:
            return payments_pb2.ChargeResponse(
                status=payments_pb2.CHARGE_STATUS_DECLINED,
            )

    def StreamTransactions(self, request, context):
        """Server streaming: yield transactions as they occur."""
        # Initial backfill of historical transactions
        for tx in db.get_transactions(
            customer_id=request.customer_id,
            since=request.since_unix,
        ):
            if context.is_active():  # Check if client is still connected
                yield payments_pb2.Transaction(
                    id=tx.id,
                    customer_id=tx.customer_id,
                    amount_cents=tx.amount_cents,
                    currency=tx.currency,
                    created_at_unix=int(tx.created_at.timestamp()),
                )

        # Subscribe to real-time events
        with event_bus.subscribe(f"transactions:{request.customer_id}") as sub:
            for event in sub:
                if not context.is_active():
                    return  # Client disconnected — stop streaming
                yield payments_pb2.Transaction(**event)


def serve():
    server = grpc.server(
        futures.ThreadPoolExecutor(max_workers=10),
        options=[
            ('grpc.max_receive_message_length', 4 * 1024 * 1024),  # 4MB
            ('grpc.max_send_message_length', 4 * 1024 * 1024),
            ('grpc.keepalive_time_ms', 30000),      # Send keepalive every 30s
            ('grpc.keepalive_timeout_ms', 5000),    # Wait 5s for keepalive ack
        ]
    )
    payments_pb2_grpc.add_PaymentServiceServicer_to_server(PaymentServicer(), server)
    server.add_insecure_port('[::]:50051')
    server.start()
    logging.info("gRPC server started on port 50051")
    server.wait_for_termination()

Python gRPC Client with Interceptors

import grpc
from grpc import UnaryUnaryClientInterceptor

class AuthInterceptor(UnaryUnaryClientInterceptor):
    """Adds authorization header to every outbound RPC."""

    def __init__(self, token_provider):
        self.token_provider = token_provider

    def intercept_unary_unary(self, continuation, client_call_details, request):
        metadata = list(client_call_details.metadata or [])
        metadata.append(('authorization', f'Bearer {self.token_provider()}'))
        metadata.append(('x-request-id', generate_request_id()))

        new_details = client_call_details._replace(metadata=metadata)
        return continuation(new_details, request)


class RetryInterceptor(UnaryUnaryClientInterceptor):
    """Retries failed RPCs with exponential backoff for retriable status codes."""

    RETRIABLE_CODES = {grpc.StatusCode.UNAVAILABLE, grpc.StatusCode.DEADLINE_EXCEEDED}

    def intercept_unary_unary(self, continuation, client_call_details, request):
        for attempt in range(3):
            response = continuation(client_call_details, request)
            try:
                return response.result()
            except grpc.RpcError as e:
                if e.code() in self.RETRIABLE_CODES and attempt < 2:
                    time.sleep(0.1 * (2 ** attempt))  # 100ms, 200ms backoff
                    continue
                raise


# Build client with interceptors
channel = grpc.intercept_channel(
    grpc.secure_channel('payments.internal:50051', grpc.ssl_channel_credentials()),
    AuthInterceptor(token_provider=get_service_token),
    RetryInterceptor(),
)

stub = payments_pb2_grpc.PaymentServiceStub(channel)

# Unary call with deadline
try:
    response = stub.ChargeCard(
        payments_pb2.ChargeRequest(
            customer_id="cust_123",
            amount_cents=4999,
            currency="USD",
            idempotency_key="order_789_charge_1",
        ),
        timeout=5.0,  # 5-second deadline
    )
    print(f"Charged: {response.transaction_id}")
except grpc.RpcError as e:
    print(f"RPC failed: {e.code()}: {e.details()}")

The Four Streaming Modes

gRPC's most distinctive feature over REST is native streaming. The four modes cover all communication patterns:

# Mode 1: Unary — request/response (same as REST)
response = stub.ChargeCard(request, timeout=5.0)

# Mode 2: Server streaming — one request, many responses
# Use case: tail a log, stream ML inference tokens, real-time feeds
def stream_inference_tokens(prompt: str):
    request = InferenceRequest(prompt=prompt, max_tokens=512)
    for chunk in stub.StreamInference(request):
        yield chunk.token  # Streams as LLM generates

# Mode 3: Client streaming — many requests, one response
# Use case: batch operations, file upload in chunks
def batch_charge(charges: list[ChargeRequest]) -> BatchChargeResponse:
    def generate_charges():
        for charge in charges:
            yield charge
    return stub.BatchCharge(generate_charges())

# Mode 4: Bidirectional streaming — both sides stream simultaneously
# Use case: real-time bidirectional chat, agent/tool call loops
async def payment_chat(messages):
    async def request_iterator():
        for msg in messages:
            yield PaymentMessage(text=msg)

    async for response in stub.PaymentChat(request_iterator()):
        print(f"Server: {response.text}")

For LLM inference APIs, server streaming is the critical mode: instead of waiting for the entire response before returning (4-30 seconds for long responses), the client receives tokens as they're generated. This is how ChatGPT, Claude, and every production LLM API works at the protocol level.

gRPC in Service Meshes: Istio and Envoy

Service meshes like Istio and Linkerd use Envoy as a sidecar proxy. Envoy has first-class gRPC support: health checking, load balancing, observability, and circuit breaking all work at the gRPC protocol level.

# Istio VirtualService: route 10% of gRPC traffic to new version
apiVersion: networking.istio.io/v1alpha3
kind: VirtualService
metadata:
  name: payments-service
spec:
  hosts:
    - payments.internal
  http:
    - match:
        - headers:
            grpc-method:   # Route specific gRPC methods differently
              exact: "/payments.v1.PaymentService/ChargeCard"
      route:
        - destination:
            host: payments-service
            subset: v2
          weight: 10     # 10% to new version
        - destination:
            host: payments-service
            subset: v1
          weight: 90

Envoy also handles retries for gRPC. The key difference from HTTP retries: gRPC has built-in status codes that indicate whether a request is safe to retry. UNAVAILABLE and DEADLINE_EXCEEDED are typically safe; ALREADY_EXISTS and FAILED_PRECONDITION are not.

# Istio DestinationRule: retry policy for gRPC services
apiVersion: networking.istio.io/v1alpha3
kind: DestinationRule
metadata:
  name: payments-retry
spec:
  host: payments.internal
  trafficPolicy:
    connectionPool:
      http:
        h2UpgradePolicy: UPGRADE  # Force HTTP/2 for gRPC
    outlierDetection:
      consecutive5xxErrors: 5
      interval: 10s
      baseEjectionTime: 30s
    retryPolicy:
      attempts: 3
      perTryTimeout: 2s
      retryOn: "5xx,gateway-error,reset,connect-failure,retriable-4xx"

gRPC vs REST: When to Use Which

flowchart TD Q1{Public API or\ninternal service?} Q1 -- Public, browser clients --> R[REST + JSON\nOpenAPI spec] Q1 -- Internal microservices --> Q2{Streaming needed?} Q2 -- Yes --> G[gRPC with streaming] Q2 -- No --> Q3{High throughput\n> 1k req/s?} Q3 -- Yes --> G Q3 -- No --> Q4{Multiple language\nclients?} Q4 -- Yes, need type safety --> G Q4 -- No or simple --> R2[REST + JSON\nsimpler tooling] style G fill:#22c55e,color:#fff style R fill:#3b82f6,color:#fff style R2 fill:#3b82f6,color:#fff
Dimension gRPC REST/JSON
Serialization speed Binary (~10× faster) Text (flexible)
Schema enforcement Compile-time (Protobuf) Optional (OpenAPI)
Streaming Native (4 modes) Workaround (SSE/WS)
Browser support Limited (grpc-web proxy) Native
Human readability Low (binary) High
Tooling maturity Good, growing Excellent
Use case fit Internal services, ML inference Public APIs, browser clients

gRPC is the right choice for:
- Internal microservice communication (service mesh)
- ML model inference (streaming token output, batch inference)
- High-throughput data pipelines
- Polyglot teams needing type-safe cross-language contracts

REST is the right choice for:
- Public APIs consumed by browsers and third parties
- APIs where human readability and curl-debuggability matter
- Simple CRUD services with low traffic

Reflection and Debugging

REST APIs are debuggable with curl. Binary gRPC is not. Two tools bridge this gap:

grpcurl — curl for gRPC:

# List available services (requires reflection enabled on server)
grpcurl -plaintext localhost:50051 list

# Describe a service
grpcurl -plaintext localhost:50051 describe payments.v1.PaymentService

# Call an RPC
grpcurl -plaintext -d '{
  "customer_id": "cust_123",
  "amount_cents": 4999,
  "currency": "USD",
  "idempotency_key": "test-001"
}' localhost:50051 payments.v1.PaymentService/ChargeCard

Evans — interactive gRPC REPL:

evans --host localhost --port 50051 --reflection repl
# > call ChargeCard
# customer_id (TYPE_STRING) => cust_123
# amount_cents (TYPE_INT64) => 4999
# ...

To enable server reflection (needed by grpcurl/Evans):

from grpc_reflection.v1alpha import reflection

# Add to your server setup
SERVICE_NAMES = (
    payments_pb2.DESCRIPTOR.services_by_name['PaymentService'].full_name,
    reflection.SERVICE_NAME,
)
reflection.enable_server_reflection(SERVICE_NAMES, server)

Enable reflection only in non-production environments. Reflection exposes your entire API schema — useful for dev/staging, a security concern in production.

Production Considerations

Health Checking and Load Balancing

gRPC has a standard health checking protocol. All production gRPC servers should implement it — load balancers and service meshes (Istio, Linkerd) rely on it:

from grpc_health.v1 import health_pb2_grpc, health_pb2
from grpc_health.v1.health import HealthServicer

# Add health service to your server
health_servicer = HealthServicer()
health_pb2_grpc.add_HealthServicer_to_server(health_servicer, server)

# Mark service as serving (or NOT_SERVING during graceful shutdown)
health_servicer.set(
    "payments.v1.PaymentService",
    health_pb2.HealthCheckResponse.SERVING
)

gRPC-Gateway for REST Compatibility

Sometimes you need both: gRPC for internal services and REST for external clients. grpc-gateway generates a REST proxy from your proto annotations:

import "google/api/annotations.proto";

service PaymentService {
  rpc ChargeCard(ChargeRequest) returns (ChargeResponse) {
    option (google.api.http) = {
      post: "/v1/charges"
      body: "*"
    };
  }
}

The gateway translates JSON REST requests into gRPC calls transparently — one server implementation, two transports.

Metadata and Custom Headers

gRPC metadata is the equivalent of HTTP headers — key-value pairs sent with each RPC call. Use metadata for authentication, request tracing, and custom context:

# Server: extract metadata from incoming context
class PaymentServicer(payments_pb2_grpc.PaymentServiceServicer):
    def ChargeCard(self, request, context):
        # Extract metadata (like HTTP headers)
        metadata = dict(context.invocation_metadata())

        request_id = metadata.get('x-request-id', 'unknown')
        auth_token = metadata.get('authorization', '')

        # Verify token
        if not verify_token(auth_token):
            context.set_code(grpc.StatusCode.UNAUTHENTICATED)
            context.set_details("Invalid or missing authorization token")
            return payments_pb2.ChargeResponse()

        # Add response metadata (like response headers)
        context.send_initial_metadata([
            ('x-request-id', request_id),       # Echo back for correlation
            ('x-processing-region', 'us-east-1'),
        ])

        return process_charge(request)

Interceptors (shown earlier) are the idiomatic way to add metadata globally, rather than in every service method.

Deadlines Are Mandatory

Every gRPC call should have a deadline. Without one, a slow upstream can hold connections indefinitely:

# Always set a timeout — never make an unbounded RPC call
try:
    response = stub.ChargeCard(request, timeout=3.0)  # 3 seconds max
except grpc.RpcError as e:
    if e.code() == grpc.StatusCode.DEADLINE_EXCEEDED:
        # Timeout — circuit break or return cached result
        ...

Set deadlines based on your SLO, not generously. A 30-second deadline on a 200ms call means slow cascading failures propagate for 30 seconds instead of failing fast.

Performance: Why gRPC Is Faster Than REST

The performance advantage comes from three compounding factors:

Binary serialization vs JSON: JSON is human-readable text. "amount_cents": 4999 encodes as 21 bytes. The same int64 in protobuf encodes as 3 bytes (field tag + varint). For complex nested messages with repeated fields, protobuf is typically 5-10× smaller than JSON.

import json
import time
from google.protobuf import json_format

# Benchmark: serialize 1000 ChargeRequest messages
charge = {"customer_id": "cust_abc123", "amount_cents": 4999, "currency": "USD", "idempotency_key": "idem_xyz789"}

# JSON serialization: ~1,200 nanoseconds per message
json_bytes = json.dumps(charge).encode()  # 83 bytes

# Protobuf serialization: ~120 nanoseconds per message
proto_msg = ChargeRequest(**charge)
proto_bytes = proto_msg.SerializeToString()  # 34 bytes

# 2.4× smaller, 10× faster serialization

HTTP/2 multiplexing: HTTP/1.1 connections handle one request at a time. Multiple requests require multiple connections (or pipelining with head-of-line blocking). HTTP/2 multiplexes many streams over one TCP connection. At 10,000 RPC/s, the connection overhead difference is significant.

Connection reuse: gRPC clients maintain a pool of long-lived HTTP/2 connections. REST clients often open a new connection per request (or maintain a pool with HTTP keep-alive). Long-lived HTTP/2 connections eliminate TCP and TLS handshake overhead per request.

Combined: in benchmarks of internal service-to-service communication, gRPC typically shows 2-7× lower latency and 2-5× higher throughput than REST/JSON for equivalent payloads. The gap widens with larger payloads and higher concurrency.

Protocol Buffers: Field Numbers and Backward Compatibility

One of protobuf's most important properties: backward-compatible schema evolution. Field numbers — not names — identify fields in the serialized binary. This means you can rename fields without breaking existing clients, and you can add new fields without breaking old clients.

// Version 1 of ChargeRequest
message ChargeRequest {
  string customer_id = 1;
  int64 amount_cents = 2;
  string currency = 3;
  string idempotency_key = 4;
}

// Version 2: BACKWARD COMPATIBLE additions
message ChargeRequest {
  string customer_id = 1;
  int64 amount_cents = 2;
  string currency = 3;
  string idempotency_key = 4;
  optional string description = 5;   // New field — old clients ignore it
  optional string merchant_id = 6;   // Another new field
  // NEVER reuse field numbers 1-4 — would break existing serialized data
}

Rules for safe proto evolution:
1. Never delete a field — mark it reserved and add to the reserved list instead
2. Never reuse a field number — the binary format uses numbers, not names
3. New fields should be optional — required fields in proto3 don't exist; in proto2, adding a required field is a breaking change
4. Never change a field type — int32 to int64 might work, but int64 to string will break
5. Never rename an enum value — enum values have both a number and a name; changing the name changes the default serialized value

// SAFE: reserve removed fields to prevent accidental reuse
message OldChargeRequest {
  reserved 5, 6;  // These field numbers can never be reused
  reserved "coupon_code", "promo_id";  // These names can never be reused

  string customer_id = 1;
  int64 amount_cents = 2;
}

This makes gRPC schema evolution safer than REST JSON APIs. A JSON API change that renames a field silently breaks all clients. A protobuf rename is invisible to the wire format — old and new clients interoperate without modification.

Conclusion

gRPC's advantages are clearest in internal service-to-service communication: binary serialization that's 5-10× faster than JSON, schema enforcement that catches breaking changes at compile time, native streaming for ML inference and real-time data, and code generation that eliminates hand-written client boilerplate.

The ecosystem has matured to the point where gRPC is no longer an exotic choice. Kubernetes, Envoy, Istio, and most cloud-native infrastructure speak gRPC natively. ML frameworks (TensorFlow Serving, Triton Inference Server) use gRPC for inference APIs. The service mesh ecosystem depends on gRPC for control plane communication.

For teams building new internal services in 2026, the decision framework is simple: if it's a browser-facing public API, use REST. If it's a service talking to another service, start with gRPC. The tooling (grpcurl, Evans, reflection), the generated clients, and the schema-first development workflow are all production-ready.

The migration path from existing REST services isn't all-or-nothing. grpc-gateway lets you expose both REST and gRPC from the same server implementation — add gRPC for new service-to-service consumers while maintaining the REST API for existing browser clients. Over time, internal consumers migrate to gRPC; the REST endpoint remains for compatibility. This hybrid approach is how most organizations transition their internal API surface to gRPC without a big-bang rewrite.

The learning curve — proto files, code generation, lack of curl debuggability — is real but small. The payoff at scale is significant. Use REST for public-facing APIs where browser clients and human readability matter. Use gRPC everywhere internal, especially in service meshes where the efficiency gains multiply across thousands of calls per second.

The proto-first workflow also improves cross-team collaboration. Service contracts live in a shared proto repository. Teams consume the generated clients without needing to understand server internals. API reviews become proto reviews — structured, diff-able, and enforceable in CI. This is the developer experience improvement that, more than raw performance numbers, drives gRPC adoption in mature engineering organizations.


Sources

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-05-19 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter

Sunday, April 12, 2026

GraphQL vs REST vs gRPC in 2026: Which API Style Should You Choose?

API Styles Comparison

Introduction

Every engineering team building distributed systems eventually hits the same wall: the API design conversation. REST has been the industry default for over two decades. GraphQL emerged in 2015 from Facebook's internal frustrations with REST's rigidity. gRPC, born inside Google, became the backbone of most large-scale microservice meshes. By 2026, all three are mature, battle-tested, and still actively competing for the same mindshare.

The problem is that the debate never really ended — it just got noisier. You'll find passionate engineers on all sides, each armed with benchmarks and horror stories. REST veterans warn you about GraphQL's N+1 query problem. GraphQL advocates complain about REST's over-fetching on mobile. gRPC proponents will tell you protobuf is the only sane serialization format worth considering at scale.

This post cuts through the tribal loyalty and gives you a practical, technical comparison you can use to make the right call for your specific system. We'll look at real implementation patterns, performance characteristics, versioning strategies, and a use-case decision matrix so you can stop debating and start building.

Whether you're designing a public API consumed by third-party developers, building an internal service mesh, or shipping a mobile app that needs to squeeze every millisecond of latency out of its backend — this guide has a concrete answer for you.


The Problem: Why One Size Doesn't Fit All

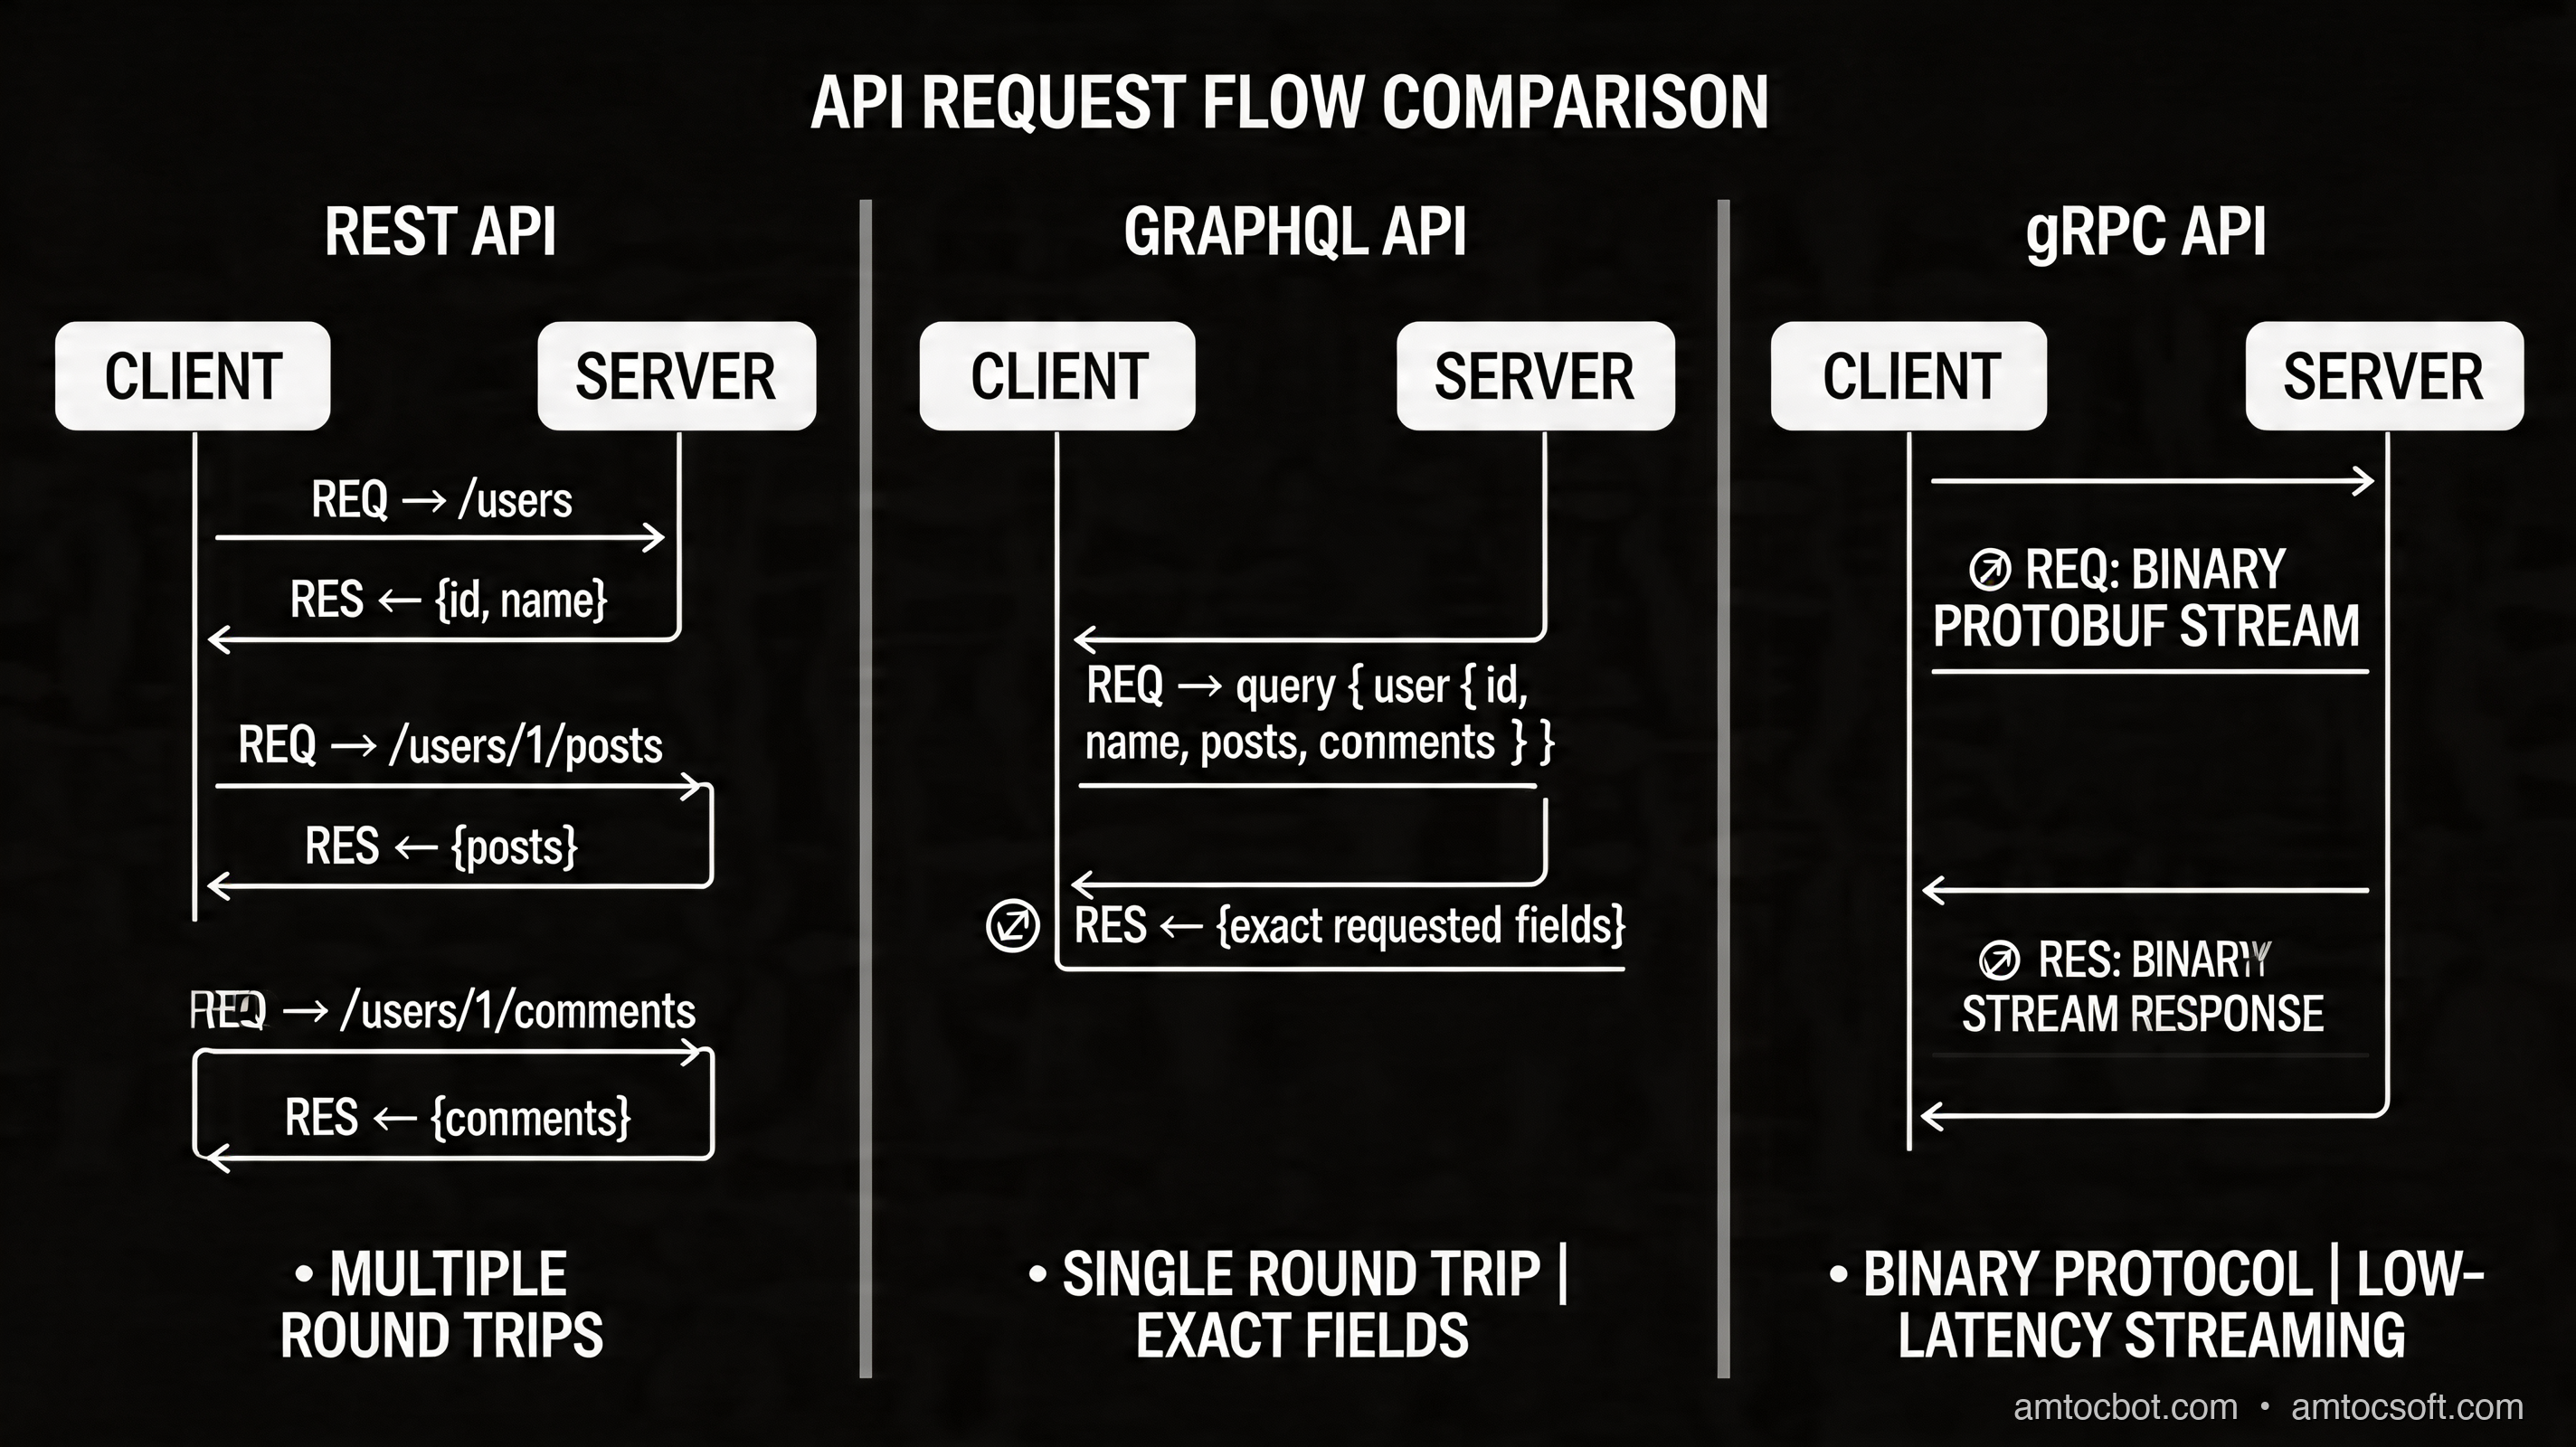
REST was designed around the concept of resources and uniform interfaces. It maps beautifully to CRUD operations and HTTP semantics. But real applications don't always model cleanly onto resources. A dashboard that needs user data, recent orders, notification counts, and product recommendations in a single render cycle is asking REST to do something it was never designed for elegantly — and the result is either massive over-fetching (returning too much data) or multiple round trips (under-fetching).

GraphQL solved those problems but introduced new ones. A flexible query language means clients can request arbitrary shapes of data, which is powerful — until a malicious or poorly written client sends a deeply nested query that hammers your database for minutes. The N+1 query problem, where each item in a list triggers a separate database lookup, has burned teams who didn't build DataLoader patterns from day one.

gRPC sidesteps much of this by using strongly typed contracts (Protocol Buffers) and HTTP/2's multiplexing. It's extremely fast for internal service-to-service calls. But it's nearly useless for browser-native consumption without additional tooling (grpc-web or Connect), and protobuf schemas have a learning curve that slows down exploratory API development.

The real problem engineers face in 2026 is not choosing the "best" API style — it's choosing the right one for the right context, and potentially using all three in the same system.

Request Flow Comparison

How It Works: Technical Deep Dive

REST: Resources, Verbs, and Stateless Contracts

REST (Representational State Transfer) operates on six architectural constraints: statelessness, client-server separation, cacheability, layered system, uniform interface, and optionally code on demand. In practice, REST APIs are defined by their resource URLs and HTTP verbs.

GET    /users/42           → Fetch user 42
POST   /users              → Create a new user
PUT    /users/42           → Replace user 42
PATCH  /users/42           → Partially update user 42
DELETE /users/42           → Delete user 42

The power of REST is that HTTP infrastructure already understands it. CDNs can cache GET responses. Load balancers route by path. API gateways apply rate limits per route. Every HTTP client in every language can speak it without special libraries.

A well-designed REST response for a user resource might look like this:

GET /users/42
{
  "id": 42,
  "name": "Alice Chen",
  "email": "alice@example.com",
  "role": "admin",
  "created_at": "2024-01-15T09:00:00Z",
  "organization_id": 7,
  "avatar_url": "https://cdn.example.com/avatars/42.png",
  "preferences": {
    "theme": "dark",
    "notifications": true
  }
}

The catch: if your mobile client only needs name and avatar_url, you've transmitted six unnecessary fields on every request. Multiply that across millions of calls and it's wasted bandwidth and parsing cost.

REST versioning is another pain point. The common approaches are URL versioning (/v1/users, /v2/users), header versioning (Accept: application/vnd.api+json;version=2), or query parameter versioning (/users?version=2). Each has tradeoffs. URL versioning duplicates routing logic. Header versioning is less visible. None of them prevent the proliferation of parallel API versions that all need to be maintained.

GraphQL: Schema-First, Client-Driven Queries

GraphQL flips the model. Instead of the server defining what data is available at which endpoint, the server defines a typed schema and the client asks for exactly what it needs.

# Schema definition (server-side)
type User {
  id: ID!
  name: String!
  email: String!
  orders(limit: Int, status: OrderStatus): [Order!]!
  organization: Organization!
}

type Order {
  id: ID!
  total: Float!
  status: OrderStatus!
  items: [OrderItem!]!
  createdAt: DateTime!
}

type Query {
  user(id: ID!): User
  users(role: String, limit: Int): [User!]!
}

type Mutation {
  updateUser(id: ID!, input: UpdateUserInput!): User!
  createOrder(input: CreateOrderInput!): Order!
}

The client now sends a single query that specifies exactly the shape it wants:

query GetDashboardData {
  user(id: "42") {
    name
    avatarUrl
    orders(limit: 5, status: PENDING) {
      id
      total
      status
      createdAt
    }
    organization {
      name
      plan
    }
  }
}

One HTTP request. One response. No over-fetching, no multiple round trips. The client gets a dashboard's worth of data in a single call.

The N+1 Problem and DataLoader

The dangerous failure mode in GraphQL is the N+1 query. If you resolve a list of 100 orders and each Order.user field triggers a separate database query, you've issued 101 queries where one would do. The solution is DataLoader — a batching and caching utility that collects all the individual lookup requests within a single execution tick and issues one batched query.

// Without DataLoader — N+1 problem
const resolvers = {
  Order: {
    user: async (order) => {
      // Called once per order — 100 queries for 100 orders!
      return db.users.findById(order.userId);
    }
  }
};

// With DataLoader — batched, one query
import DataLoader from 'dataloader';

const userLoader = new DataLoader(async (userIds) => {
  // Called ONCE with all userIds collected this tick
  const users = await db.users.findByIds(userIds);
  return userIds.map(id => users.find(u => u.id === id));
});

const resolvers = {
  Order: {
    user: async (order) => {
      return userLoader.load(order.userId); // batched automatically
    }
  }
};

GraphQL versioning is simpler than REST because you evolve the schema rather than creating new endpoints. Fields are deprecated with @deprecated(reason: "Use newField instead") and remain available until all clients migrate. This allows gradual evolution without breaking consumers.

graph TD Client["🖥️ GraphQL Client"] GW["API Gateway / GraphQL Server"] QP["Query Parser & Validator"] RE["Resolver Engine"] DL["DataLoader Batch Collector"] DB_Users["Users DB"] DB_Orders["Orders DB"] DB_Orgs["Organizations DB"] Cache["Response Cache"] Client -->|"POST /graphql\n{ query, variables }"| GW GW --> QP QP -->|"Validated AST"| RE RE -->|"user(id: 42)"| DL RE -->|"orders(userId: 42)"| DL RE -->|"organization(id: 7)"| DL DL -->|"Batch: SELECT * FROM users WHERE id IN (...)"| DB_Users DL -->|"Batch: SELECT * FROM orders WHERE user_id IN (...)"| DB_Orders DL -->|"Batch: SELECT * FROM orgs WHERE id IN (...)"| DB_Orgs DB_Users -->|"User rows"| DL DB_Orders -->|"Order rows"| DL DB_Orgs -->|"Org rows"| DL DL -->|"Resolved fields"| RE RE -->|"Assembled JSON"| Cache Cache -->|"{ data: {...} }"| Client

gRPC: Contracts, Protobuf, and HTTP/2 Streaming

gRPC uses Protocol Buffers (protobuf) as its interface definition language and serialization format, and runs over HTTP/2. The schema is defined in .proto files, and client/server code is generated from those definitions.

// user.proto
syntax = "proto3";

package users.v1;

service UserService {
  rpc GetUser (GetUserRequest) returns (User);
  rpc ListUsers (ListUsersRequest) returns (stream User);
  rpc UpdateUser (UpdateUserRequest) returns (User);
  rpc StreamUserActivity (GetUserRequest) returns (stream ActivityEvent);
}

message GetUserRequest {
  string user_id = 1;
}

message User {
  string id = 1;
  string name = 2;
  string email = 3;
  string role = 4;
  int64 created_at = 5;
  string organization_id = 6;
}

message ListUsersRequest {
  string role = 1;
  int32 limit = 2;
  string cursor = 3;
}

message ActivityEvent {
  string event_type = 1;
  int64 timestamp = 2;
  map<string, string> metadata = 3;
}

From this .proto file, protoc generates strongly typed client and server code in Go, Python, TypeScript, Java, Rust, and a dozen other languages. The generated client looks like a regular function call:

// Generated Go client usage
conn, err := grpc.Dial("user-service:50051", grpc.WithTransportCredentials(creds))
client := usersv1.NewUserServiceClient(conn)

// Unary call — just like a function
user, err := client.GetUser(ctx, &usersv1.GetUserRequest{
    UserId: "42",
})
fmt.Printf("Name: %s\n", user.Name)

// Server-side streaming — get users as they arrive
stream, err := client.ListUsers(ctx, &usersv1.ListUsersRequest{
    Role:  "admin",
    Limit: 100,
})
for {
    user, err := stream.Recv()
    if err == io.EOF {
        break
    }
    process(user)
}

// Bidirectional streaming — real-time activity feed
actStream, err := client.StreamUserActivity(ctx, &usersv1.GetUserRequest{UserId: "42"})
for {
    event, err := actStream.Recv()
    if err != nil { break }
    handleEvent(event)
}

Protobuf's binary encoding is roughly 3-10x smaller than equivalent JSON, and serialization/deserialization is significantly faster. For high-throughput internal services exchanging millions of messages per second, this is a meaningful advantage.

HTTP/2 multiplexing means multiple streams can share a single TCP connection without head-of-line blocking, and gRPC supports four call patterns: unary (one request, one response), server streaming, client streaming, and bidirectional streaming. This makes gRPC the natural choice for real-time event feeds, large file uploads, and long-lived connections.


Implementation Guide

REST: A Production-Ready Node.js Endpoint

// routes/users.js — Express + Zod validation
import express from 'express';
import { z } from 'zod';
import { db } from '../db/index.js';
import { cache } from '../cache/redis.js';
import { requireAuth, requireRole } from '../middleware/auth.js';

const router = express.Router();

const UpdateUserSchema = z.object({
  name: z.string().min(1).max(100).optional(),
  email: z.string().email().optional(),
  role: z.enum(['admin', 'member', 'viewer']).optional(),
});

// GET /v1/users/:id
// Cache-Control: max-age=60, stale-while-revalidate=300
router.get('/:id', requireAuth, async (req, res) => {
  const { id } = req.params;
  const cacheKey = `user:${id}`;

  const cached = await cache.get(cacheKey);
  if (cached) {
    res.set('X-Cache', 'HIT');
    return res.json(JSON.parse(cached));
  }

  const user = await db.users.findById(id);
  if (!user) {
    return res.status(404).json({
      error: 'NOT_FOUND',
      message: `User ${id} not found`,
    });
  }

  const response = {
    id: user.id,
    name: user.name,
    email: user.email,
    role: user.role,
    created_at: user.createdAt.toISOString(),
    organization_id: user.organizationId,
    _links: {
      self: { href: `/v1/users/${user.id}` },
      organization: { href: `/v1/organizations/${user.organizationId}` },
      orders: { href: `/v1/users/${user.id}/orders` },
    },
  };

  await cache.setex(cacheKey, 60, JSON.stringify(response));
  res.set('Cache-Control', 'max-age=60, stale-while-revalidate=300');
  res.set('X-Cache', 'MISS');
  res.json(response);
});

// PATCH /v1/users/:id
router.patch('/:id', requireAuth, requireRole('admin'), async (req, res) => {
  const { id } = req.params;
  const parsed = UpdateUserSchema.safeParse(req.body);

  if (!parsed.success) {
    return res.status(400).json({
      error: 'VALIDATION_ERROR',
      details: parsed.error.flatten(),
    });
  }

  const updated = await db.users.update(id, parsed.data);
  await cache.del(`user:${id}`); // Invalidate cache

  res.json(updated);
});

export default router;

GraphQL: Apollo Server with DataLoader and Auth

// graphql/resolvers/user.js
import DataLoader from 'dataloader';
import { AuthenticationError, ForbiddenError } from 'apollo-server-errors';
import { db } from '../../db/index.js';

// Create loaders per-request (not global — prevents cross-request cache pollution)
export function createLoaders() {
  return {
    userById: new DataLoader(async (ids) => {
      const users = await db.users.findByIds(ids);
      const map = new Map(users.map(u => [u.id, u]));
      return ids.map(id => map.get(id) ?? new Error(`User ${id} not found`));
    }),
    ordersByUserId: new DataLoader(async (userIds) => {
      const orders = await db.orders.findByUserIds(userIds);
      const grouped = new Map();
      for (const order of orders) {
        if (!grouped.has(order.userId)) grouped.set(order.userId, []);
        grouped.get(order.userId).push(order);
      }
      return userIds.map(id => grouped.get(id) ?? []);
    }),
  };
}

// typeDefs (schema)
export const typeDefs = `#graphql
  type User {
    id: ID!
    name: String!
    email: String!
    role: UserRole!
    createdAt: DateTime!
    organization: Organization!
    orders(limit: Int = 10, status: OrderStatus): [Order!]!
  }

  enum UserRole { ADMIN MEMBER VIEWER }
  enum OrderStatus { PENDING PROCESSING SHIPPED DELIVERED CANCELLED }

  type Query {
    user(id: ID!): User
    me: User!
  }

  type Mutation {
    updateUser(id: ID!, input: UpdateUserInput!): User!
  }

  input UpdateUserInput {
    name: String
    email: String
    role: UserRole
  }
`;

export const resolvers = {
  Query: {
    user: async (_, { id }, { user, loaders }) => {
      if (!user) throw new AuthenticationError('Not authenticated');
      return loaders.userById.load(id);
    },
    me: async (_, __, { user }) => {
      if (!user) throw new AuthenticationError('Not authenticated');
      return user;
    },
  },
  Mutation: {
    updateUser: async (_, { id, input }, { user, loaders }) => {
      if (!user) throw new AuthenticationError('Not authenticated');
      if (user.role !== 'ADMIN' && user.id !== id) {
        throw new ForbiddenError('Cannot update other users');
      }
      const updated = await db.users.update(id, input);
      loaders.userById.clear(id); // Clear specific loader cache
      return updated;
    },
  },
  User: {
    organization: (user, _, { loaders }) => {
      return loaders.organizationById.load(user.organizationId);
    },
    orders: async (user, { limit, status }, { loaders }) => {
      const orders = await loaders.ordersByUserId.load(user.id);
      const filtered = status ? orders.filter(o => o.status === status) : orders;
      return filtered.slice(0, limit);
    },
  },
};

gRPC: Go Server Implementation

// server/user_service.go
package server

import (
    "context"
    "database/sql"
    "time"

    "google.golang.org/grpc/codes"
    "google.golang.org/grpc/status"

    usersv1 "github.com/example/api/gen/users/v1"
)

type UserServiceServer struct {
    usersv1.UnimplementedUserServiceServer
    db    *sql.DB
    cache Cache
}

func NewUserServiceServer(db *sql.DB, cache Cache) *UserServiceServer {
    return &UserServiceServer{db: db, cache: cache}
}

// Unary RPC — GetUser
func (s *UserServiceServer) GetUser(
    ctx context.Context,
    req *usersv1.GetUserRequest,
) (*usersv1.User, error) {
    if req.UserId == "" {
        return nil, status.Error(codes.InvalidArgument, "user_id is required")
    }

    // Check cache
    if cached, ok := s.cache.Get(ctx, "user:"+req.UserId); ok {
        return cached.(*usersv1.User), nil
    }

    var user usersv1.User
    var createdAt time.Time

    err := s.db.QueryRowContext(ctx,
        `SELECT id, name, email, role, created_at, organization_id
         FROM users WHERE id = $1 AND deleted_at IS NULL`,
        req.UserId,
    ).Scan(&user.Id, &user.Name, &user.Email, &user.Role, &createdAt, &user.OrganizationId)

    if err == sql.ErrNoRows {
        return nil, status.Errorf(codes.NotFound, "user %s not found", req.UserId)
    }
    if err != nil {
        return nil, status.Errorf(codes.Internal, "database error: %v", err)
    }

    user.CreatedAt = createdAt.Unix()
    s.cache.Set(ctx, "user:"+req.UserId, &user, 60*time.Second)
    return &user, nil
}

// Server streaming RPC — ListUsers
func (s *UserServiceServer) ListUsers(
    req *usersv1.ListUsersRequest,
    stream usersv1.UserService_ListUsersServer,
) error {
    query := `SELECT id, name, email, role, created_at, organization_id
              FROM users WHERE deleted_at IS NULL`
    args := []any{}

    if req.Role != "" {
        query += " AND role = $1"
        args = append(args, req.Role)
    }
    if req.Limit > 0 {
        query += " LIMIT $2"
        args = append(args, req.Limit)
    }

    rows, err := s.db.QueryContext(stream.Context(), query, args...)
    if err != nil {
        return status.Errorf(codes.Internal, "query error: %v", err)
    }
    defer rows.Close()

    for rows.Next() {
        var user usersv1.User
        var createdAt time.Time

        if err := rows.Scan(
            &user.Id, &user.Name, &user.Email,
            &user.Role, &createdAt, &user.OrganizationId,
        ); err != nil {
            return status.Errorf(codes.Internal, "scan error: %v", err)
        }
        user.CreatedAt = createdAt.Unix()

        // Send each user as it's scanned — true streaming
        if err := stream.Send(&user); err != nil {
            return err // Client disconnected
        }
    }

    return rows.Err()
}
flowchart TD Start(["Start: API Design Decision"]) Q1{"Public API?\n(Third-party devs)"} Q2{"Mobile-heavy\nclient?"} Q3{"Real-time or\nstreaming needed?"} Q4{"Internal service\nto service?"} Q5{"Strict schema\ncontract needed?"} REST["✅ Use REST\n\n• Familiar to all HTTP clients\n• CDN caching works natively\n• Easy to document with OpenAPI\n• Wide tooling ecosystem"] GraphQL["✅ Use GraphQL\n\n• Client-driven queries\n• One endpoint, flexible shape\n• Solves over/under-fetching\n• Schema introspection built in"] gRPC_Stream["✅ Use gRPC\n(with streaming)\n\n• Bidirectional streaming\n• Low latency, binary protocol\n• HTTP/2 multiplexing\n• Ideal for real-time feeds"] gRPC_Internal["✅ Use gRPC\n(internal services)\n\n• Generated typed clients\n• ~3-10x faster than JSON/REST\n• Enforced contract via protobuf\n• Service mesh friendly"] Hybrid["⚡ Consider Hybrid\n\nREST for public\ngRPC internally\nGraphQL for BFF layer"] Start --> Q1 Q1 -->|Yes| REST Q1 -->|No| Q2 Q2 -->|Yes, complex data needs| GraphQL Q2 -->|No| Q3 Q3 -->|Yes, bidirectional| gRPC_Stream Q3 -->|No| Q4 Q4 -->|Yes| Q5 Q5 -->|Yes, high performance| gRPC_Internal Q5 -->|No, flexible iteration| GraphQL Q4 -->|No, mixed concerns| Hybrid

Comparison and Tradeoffs

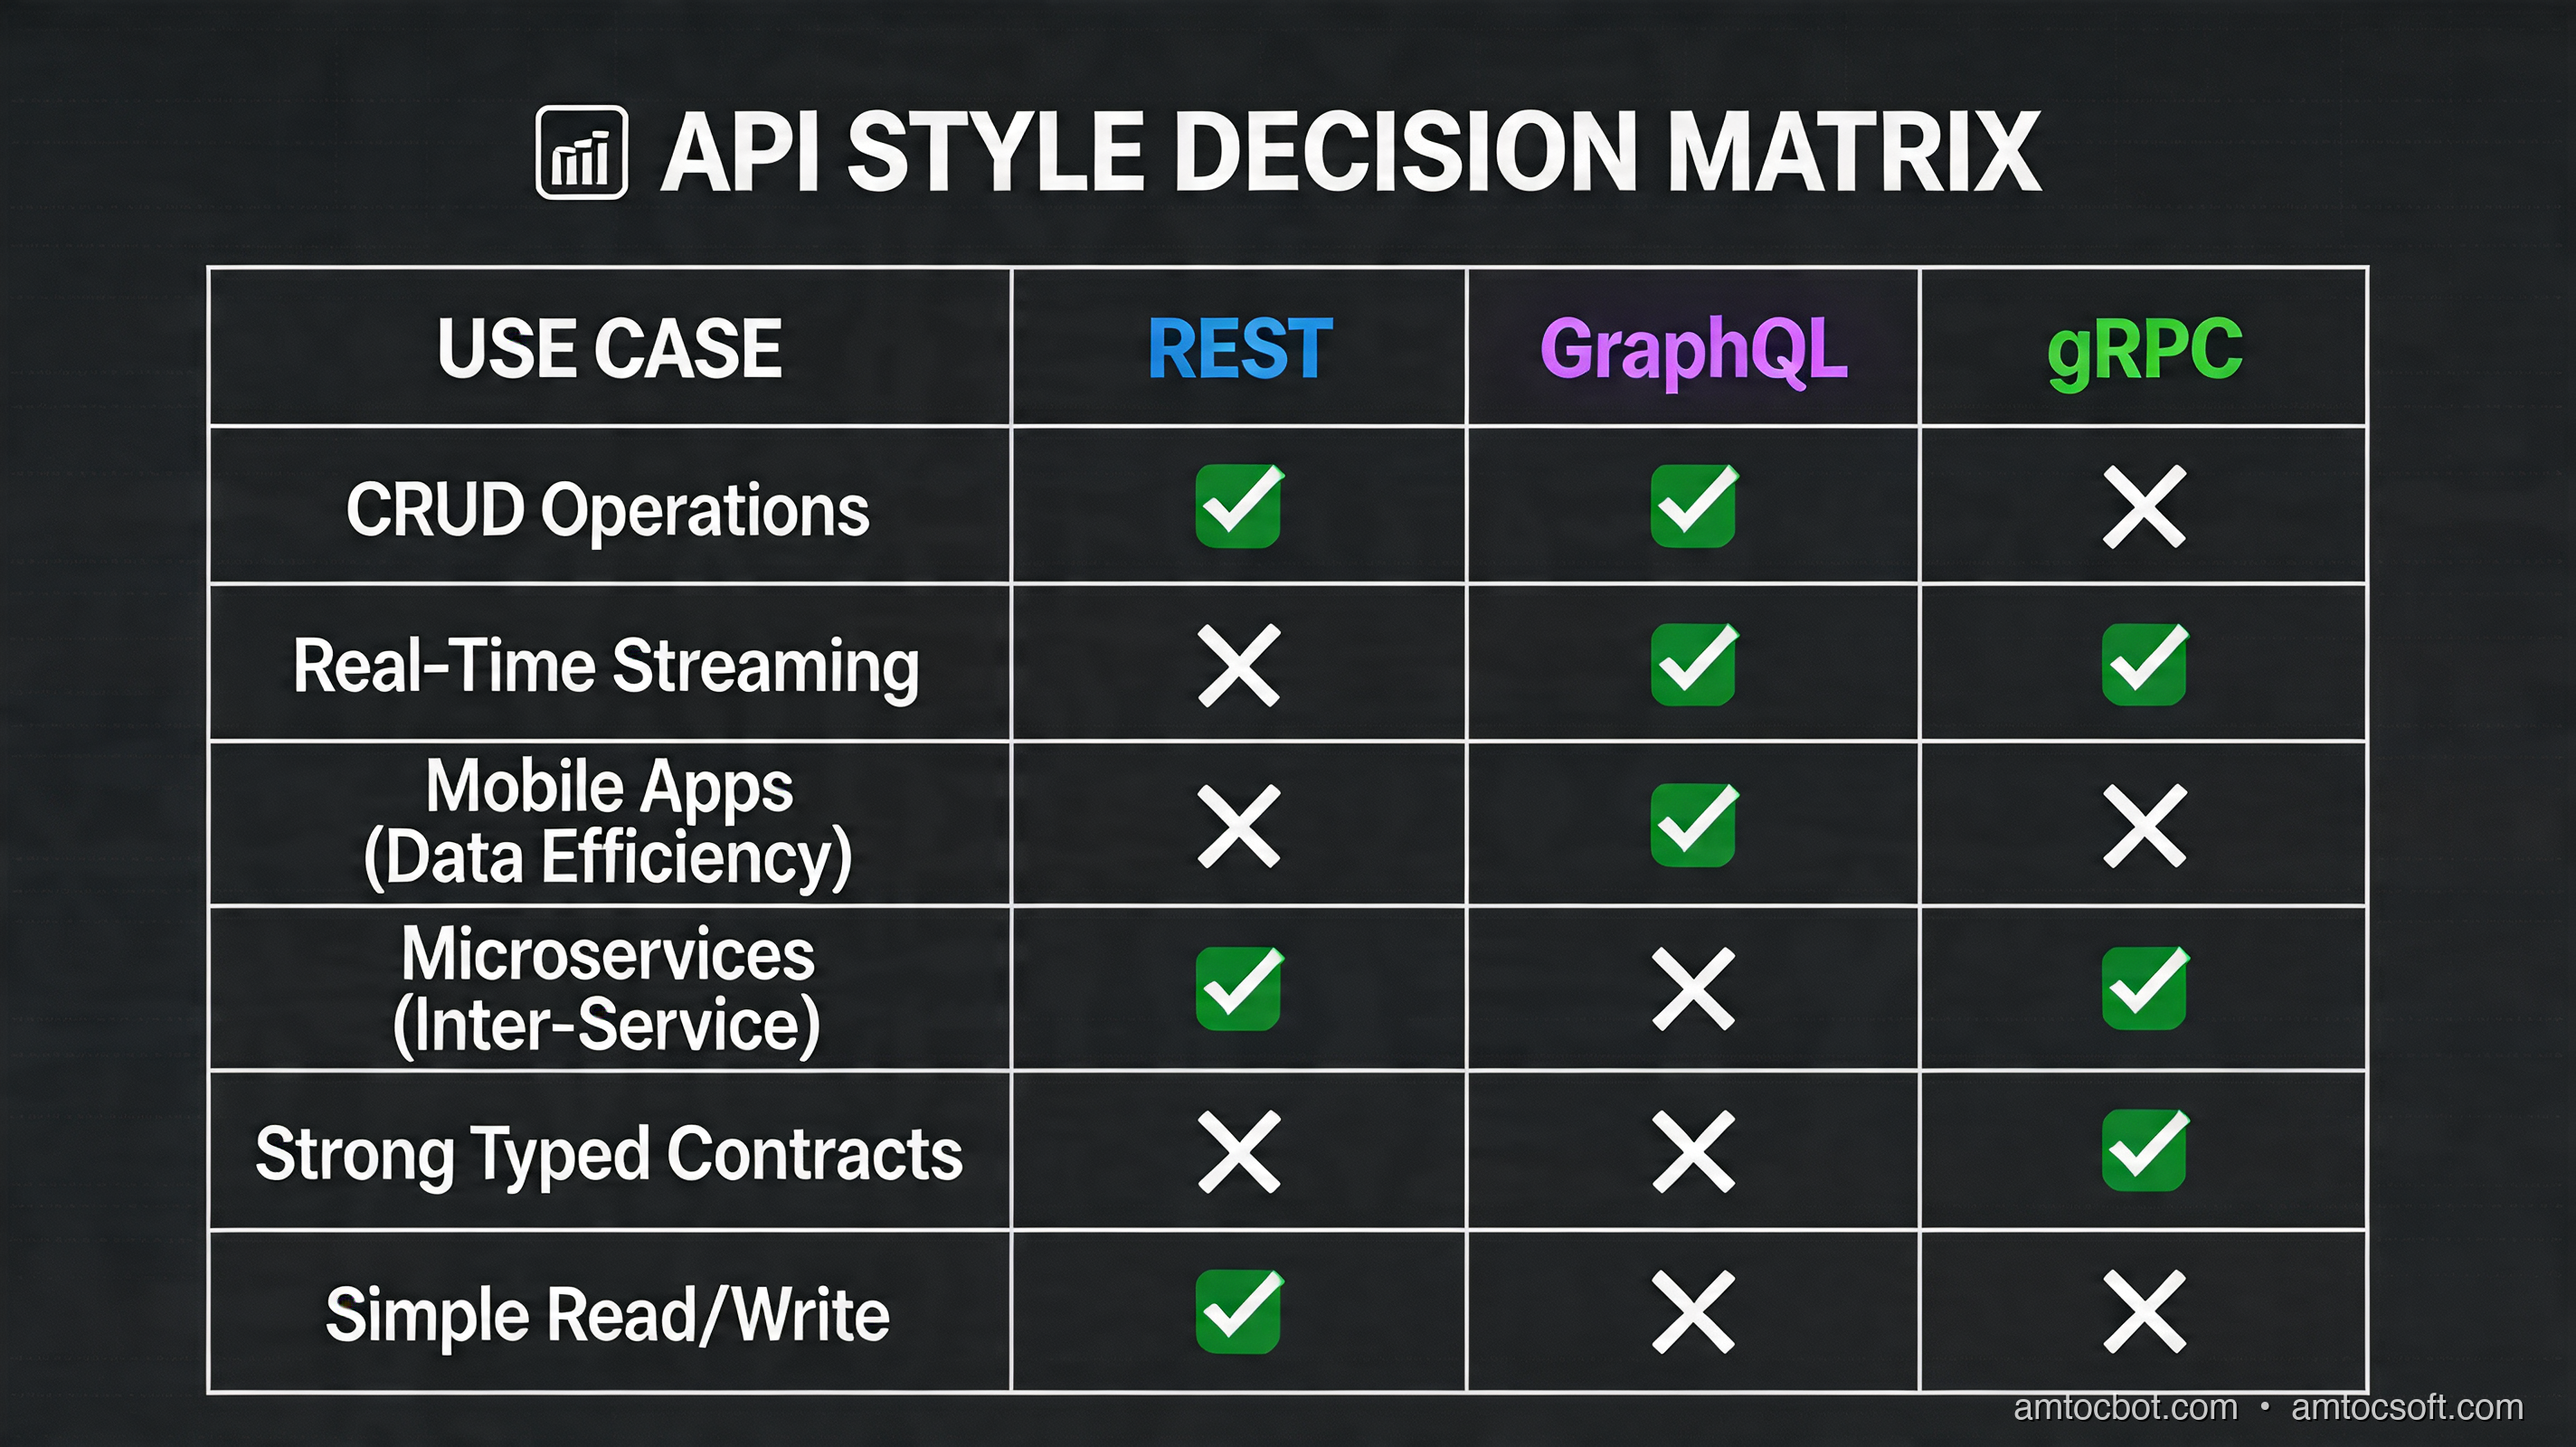
GraphQL vs REST vs gRPC Decision Matrix

The following table consolidates the major engineering tradeoffs across all three styles.

Dimension REST GraphQL gRPC
Protocol HTTP/1.1 + 2 HTTP/1.1 + 2 HTTP/2 only
Payload format JSON (typically) JSON Protobuf (binary)
Schema OpenAPI (optional) Mandatory SDL Mandatory .proto
Browser support Native Native Needs grpc-web/Connect
Streaming SSE / WebSocket (workaround) Subscriptions Native (4 modes)
Caching HTTP cache (CDN-friendly) Complex (POST by default) Not HTTP-cache-friendly
Versioning URL/Header-based Schema evolution + deprecation Package versioning in proto
Code generation Optional (OpenAPI gen) Optional (codegen tools) Required (protoc)
Learning curve Low Medium High
Over-fetching Common problem Eliminated Not applicable
N+1 problem Not applicable Real risk (DataLoader required) Not applicable
Tooling maturity Excellent Very good Good
Type safety Optional Schema-enforced Enforced via protobuf
Throughput Baseline ~5-15% overhead vs REST 2-10x faster than REST
Best for Public APIs, CRUD Mobile, BFF, complex graphs Internal services, streaming

Performance in Numbers (2026 Benchmarks)

In synthetic benchmarks on equivalent hardware (4-core, 16GB, 10Gbps network):

  • Simple GET (single resource, small payload):
  • REST/JSON: ~12,000 req/s
  • GraphQL: ~10,500 req/s (schema parsing overhead)
  • gRPC/protobuf: ~45,000 req/s

  • Complex query (5 related entities, large payload):

  • REST (5 round trips): ~1,800 req/s effective throughput
  • GraphQL (1 request): ~9,800 req/s
  • gRPC (streaming): ~38,000 msg/s

GraphQL's overhead on simple queries is real but small. Its advantage on complex, multi-entity queries is dramatic. gRPC wins on raw throughput in every scenario where it applies.

sequenceDiagram participant C as Client participant REST as REST API participant GQL as GraphQL API participant GRPC as gRPC Service participant DB as Database Note over C,DB: Same operation: fetch user + last 5 orders + organization rect rgb(255, 240, 240) Note over C,REST: REST — 3 round trips C->>REST: GET /v1/users/42 REST->>DB: SELECT * FROM users WHERE id=42 DB-->>REST: user row REST-->>C: { user object } C->>REST: GET /v1/users/42/orders?limit=5 REST->>DB: SELECT * FROM orders WHERE user_id=42 LIMIT 5 DB-->>REST: 5 order rows REST-->>C: [order array] C->>REST: GET /v1/organizations/7 REST->>DB: SELECT * FROM organizations WHERE id=7 DB-->>REST: org row REST-->>C: { org object } Note over C: 3 requests, 3 round trips, 3x latency end rect rgb(240, 255, 240) Note over C,GQL: GraphQL — 1 request, batched queries C->>GQL: POST /graphql { user(id:42) { name orders { ... } organization { ... } } } GQL->>DB: SELECT FROM users WHERE id=42 GQL->>DB: SELECT FROM orders WHERE user_id=42 LIMIT 5 (DataLoader batch) GQL->>DB: SELECT FROM organizations WHERE id=7 (DataLoader batch) DB-->>GQL: all results GQL-->>C: { data: { user: { name, orders, organization } } } Note over C: 1 request, parallel DB queries, minimal latency end rect rgb(240, 240, 255) Note over C,GRPC: gRPC — binary, multiplexed C->>GRPC: GetUserWithRelations(user_id: "42") [protobuf, HTTP/2 stream 1] GRPC->>DB: Batched JOIN query DB-->>GRPC: Binary result set GRPC-->>C: UserWithRelations message [protobuf, ~3x smaller than JSON] Note over C: 1 request, binary protocol, HTTP/2 multiplexing end

Versioning Strategy Deep Dive

REST versioning creates parallel codebases. /v1/ and /v2/ must both be maintained until all clients migrate. This is operationally expensive — every bug fix or security patch must be applied to every active version.

GraphQL versioning is fundamentally different. You never create /v2/graphql. Instead, you add fields, deprecate old ones, and remove them only after usage drops to zero (visible via field-level usage metrics). This allows continuous evolution without breaking existing clients.

type User {
  id: ID!
  name: String!
  # Deprecated — use `avatarUrl` instead
  avatar: String @deprecated(reason: "Use avatarUrl for CDN-optimized images")
  avatarUrl: String!
  # New field — clients opt in
  profileCompleteness: Int!
}

gRPC uses protobuf's field numbering rules for backward compatibility. You never remove or renumber fields; you only add new ones. Clients compiled against old .proto files ignore unknown fields. This allows independent deployment of services and clients, which is critical in a microservice mesh where you can't coordinate releases.

message User {
  string id = 1;
  string name = 2;
  string email = 3;
  // Field 4 was deprecated and removed — number 4 is reserved forever
  reserved 4;
  reserved "old_avatar_url";
  // New fields added safely — old clients ignore these
  string avatar_url = 5;
  int32 profile_completeness = 6;
}

Production Considerations

gRPC in Production

gRPC's main production challenge is observability. Protobuf binary payloads can't be read in standard network tools. Invest in proper tracing (OpenTelemetry, Jaeger) from day one. Envoy proxy with gRPC-JSON transcoding lets you expose gRPC services as REST endpoints for debugging and for clients that can't speak gRPC natively.

Health checking requires gRPC's own health protocol (grpc.health.v1.Health) — Kubernetes readiness probes need to be configured with grpc probe type (available since Kubernetes 1.24) or a sidecar.

# Kubernetes liveness probe for gRPC service
livenessProbe:
  grpc:
    port: 50051
  initialDelaySeconds: 10
  periodSeconds: 15

GraphQL in Production

Depth limiting and complexity analysis are non-negotiable in any GraphQL API exposed to the public or to third-party clients. A query like { users { orders { user { orders { user { ... } } } } } } can recurse infinitely.

import depthLimit from 'graphql-depth-limit';
import { createComplexityRule } from 'graphql-query-complexity';

const server = new ApolloServer({
  typeDefs,
  resolvers,
  validationRules: [
    depthLimit(7),  // Max query depth
    createComplexityRule({
      maximumComplexity: 1000,
      estimators: [
        fieldExtensionsEstimator(),
        simpleEstimator({ defaultComplexity: 1 }),
      ],
    }),
  ],
  plugins: [
    ApolloServerPluginLandingPageDisabledPlugin(), // Disable in prod
  ],
});

Persisted queries (storing query hashes server-side and having clients send only the hash) eliminate the attack surface of arbitrary query execution entirely and dramatically improve caching.

REST in Production

REST's production story is the most mature of the three. API gateways (Kong, AWS API Gateway, Cloudflare API Shield) understand HTTP semantics natively. Rate limiting by IP, user, or API key is built-in. CDN caching for GET endpoints is trivially enabled.

The main REST production pitfall is inconsistent error shapes. Define a standard error envelope and enforce it across all services:

{
  "error": {
    "code": "VALIDATION_ERROR",
    "message": "Request validation failed",
    "details": [
      { "field": "email", "message": "Must be a valid email address" }
    ],
    "request_id": "req_01HX7M3K2NQVP9WFZYX4B6R8C",
    "timestamp": "2026-04-15T10:30:00Z"
  }
}

Use OpenAPI 3.1 specifications as the source of truth for all REST APIs. Generate server stubs, client SDKs, and documentation from the spec rather than writing them separately. Tools like Speakeasy, OpenAPI Generator, and Redocly make this straightforward in 2026.

Choosing a Hybrid Architecture

The pragmatic answer for most production systems in 2026 is a hybrid. A common pattern:

  • Public API: REST (OpenAPI 3.1, versioned, CDN-cached)
  • BFF (Backend for Frontend): GraphQL (per-client schemas for web, iOS, Android)
  • Internal service mesh: gRPC (typed contracts, binary protocol, service discovery via Consul or Kubernetes)

This pattern lets each communication style do what it's best at. REST gives you a stable, well-understood public surface. GraphQL lets your frontend teams move fast without waiting for backend endpoint changes. gRPC keeps your internal services fast and contract-safe.


Conclusion

There is no universally correct answer to the GraphQL vs REST vs gRPC question in 2026 — but there are clearly correct answers for each context.

Choose REST when you're building a public API that needs to be usable by any HTTP client, when CDN caching is important, or when your team is small and tooling simplicity matters. It's not exciting, but it's proven, well-understood, and has the widest ecosystem support.

Choose GraphQL when your client teams (especially mobile) have complex, variable data needs. When over-fetching is hurting performance or developer productivity. When you have a graph-shaped data model. Budget time to implement DataLoader patterns correctly and add query complexity limits before going to production.

Choose gRPC for internal service-to-service communication where performance, streaming, and strict contracts matter more than browser compatibility. It's the right call for high-throughput pipelines, real-time event streams, and service meshes where the 3-10x performance advantage over JSON/REST pays for the protobuf learning curve many times over.

The most sophisticated systems — the ones at Google, Netflix, Shopify, and other high-scale organizations — use all three. REST faces the world. gRPC moves data internally. GraphQL sits at the boundary, composing internal data into exactly what each client needs.

Start with the one that fits your current constraints. Design your boundaries so switching or adding another style later is possible. The API layer is one of the few architectural decisions that's genuinely hard to reverse — get the fundamentals right from the start.


Tags: graphql, rest, grpc, api-design, microservices, software-engineering


Sources

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-15 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter
Bigger Is Not the Same as Better. The Job That Moved Is the Phone, Not the Lab.

Bigger is a plan. The phone is the receipt. The brief for this cycle is a question: does bigger always mean better in AI? The 2026 answer i...