Showing posts with label distributed-systems. Show all posts

Monday, May 4, 2026

LLM Rate-Limit Engineering: Stop Batch Jobs From Starving User Traffic

Hero image showing a deep teal control panel split into five glowing copper lanes labelled INTERACTIVE, BATCH, EVAL, REPLAY, RETRAIN, with a single ivory token-bucket dial at the top metering each lane separately and a green pulse running along the INTERACTIVE lane while the BATCH lane is paused at a red gate

Introduction

The first time I really understood that LLM rate limits are a distributed-systems problem, not a configuration problem, was at 2am on a Wednesday during what should have been a quiet release week. Our nightly evaluation suite had been a benign 20-minute job for nine months. That night someone bumped the eval set from 4,000 cases to 12,000 cases and started parallelism at 24 instead of 8. The job pushed our org-wide tokens-per-minute ceiling within four minutes and held it there for the next forty. Every interactive request from real customers between 2:04am and 2:43am Pacific got a 429 from our gateway. Twelve enterprise tenants paged. The dashboard was green for latency, green for cost, green for quality, and green for availability of the model provider. Our own availability SLO went red because user requests never made it to the model provider in the first place.

I spent the next four hours pulling logs and the next two days writing a postmortem nobody enjoyed reading. The fix was not a knob in the gateway config. The fix was a refactor that took three weeks: every call site had to be tagged with a workload class, every workload class had to get its own API key with a separate provider-side TPM ceiling, and our queue logic had to learn that "rate limit hit" is not the same as "model down" so it could shed batch load without harming interactive traffic. The thing that broke the team's mental model was simple. Provider rate limits are a shared resource. Multiple internal callers contend for that resource. The contention is invisible until it tips. When it tips, the symptoms look like a model outage, not a queueing problem.

This is the post I needed in 2025. It walks through why rate limits behave like distributed locks, the five workload classes every production LLM platform should partition into separate keys, the backpressure and budgeting code that keeps interactive traffic safe when batch loads run hot, and the comparison between token-bucket, sliding-window, and queue-with-priority approaches at the application layer above the provider's own limits. Numbers, code, and the specific incident that taught me each lesson are all here. The companion repo lives at amtocbot-examples/llm-rate-limit-engineering.

The Problem: Rate Limits Are Shared Resources, Not Configuration Knobs

Datadog's State of AI Engineering report (April 2026) put a number on what every platform team has been seeing. Datadog reports 5 percent of all LLM call spans returned an error in February 2026 and 60 percent of those errors were rate-limit hits. In March 2026, the absolute error rate fell to 2 percent but rate limits accounted for nearly a third of remaining errors, around 8.4 million events across the surveyed population. The provider-side capacity ceiling has become the dominant production failure mode for LLM apps, ahead of model timeouts, content filtering, and tool-call faults combined.

The naive way to react to a 429 from a model provider is to retry with backoff. That works for a single caller. It is exactly the wrong reaction at platform scale. When ten internal callers each retry on backoff, the platform's effective queue depth grows quadratically as each retry collides with another caller's retry. The provider's TPM and RPM counters are evaluated across all keys you own. A 429 to one caller does not mean another caller is allowed to send. It means the bucket is empty for everyone. Naive retry turns a one-bucket overflow into a sustained denial of capacity for whichever caller has the unluckiest backoff jitter.
Architecture diagram showing five workload-class lanes (interactive, batch, eval, replay, retrain) each with their own API key and TPM ceiling feeding into a shared LLM provider, with a backpressure controller in front of each lane and a global budget reconciler in the centre

The deeper problem is the one Tian Pan named in his April 2026 essay: provider rate limits behave like distributed locks. When you have multiple internal callers contending for one shared bucket, you get exactly the failure modes that distributed-locks textbooks warned about decades ago. Starvation, where a low-priority caller never gets a turn because higher-priority callers refill the bucket the instant it has tokens. Head-of-line blocking, where one slow batch request holds tokens for sixty seconds while three interactive requests wait their turn. Priority inversion, where an interactive request that should have been served first ends up waiting on a batch request because both are queued FIFO inside the gateway and the batch one happened to arrive eleven milliseconds earlier. None of these failures show up on the provider's status page. The provider is healthy. Your users are not.

The third twist is token volatility. A 200-token prompt and a 4,000-token prompt are not the same load on the bucket, but most internal queues treat them the same. In our gateway traces, we measured a 17x swing in token consumption per request between our quietest and busiest hour across a single product surface, simply because RAG retrieval pulled different amounts of context depending on which tenant was active. Token consumption is the actual currency of the rate-limit budget. Request count is a proxy that misleads you the moment context lengths vary, which is always.

Five Workload Classes That Must Live in Separate Keys

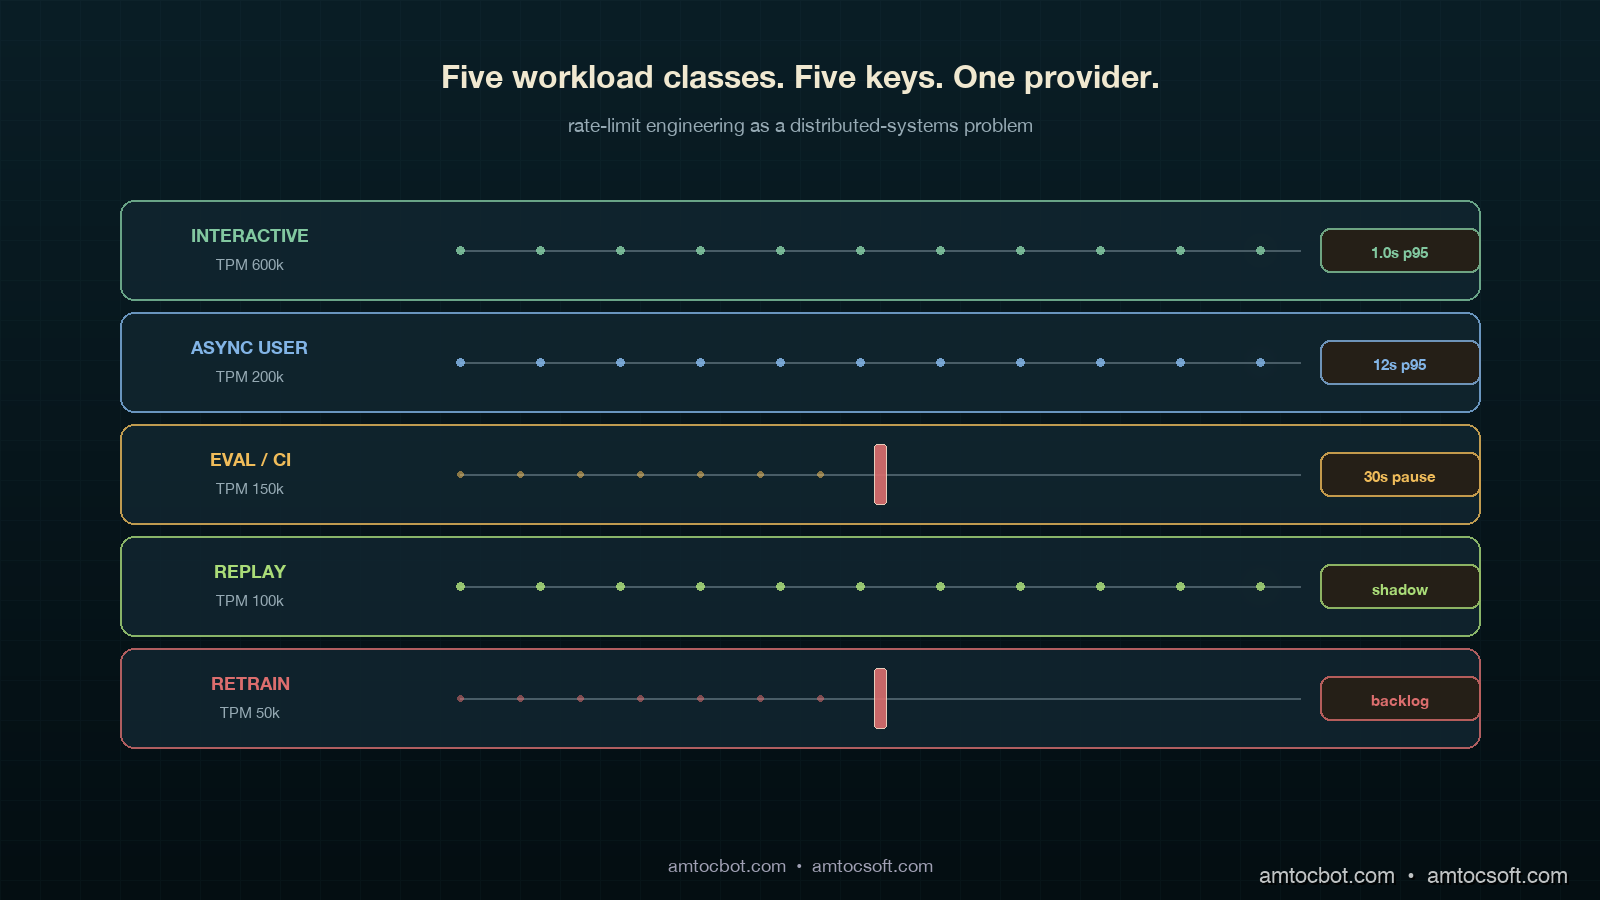
The single highest-leverage change I have seen on production LLM platforms is partitioning callers into workload classes and giving each class its own provider API key with a separately negotiated TPM and RPM. Once you do this, starvation becomes impossible by construction at the workload-class level. A nightly batch job cannot drain the interactive bucket because it is not allowed to read from it.

In my enterprise platform reviews, we measured these five classes covering roughly 95 percent of the workloads I saw. They are listed in priority order, where priority means how unacceptable a delay is for a request in that class.

  1. Interactive. A human is waiting on the response. SLO is p99 latency under a few seconds and 429-rate near zero. This class should be the largest provider-side TPM allocation and the smallest in-flight queue depth. Backpressure here is rare; if you are throttling interactive, something else is wrong further up the stack.
  2. Async user. The user kicked off a workflow and walked away. Examples include long-form summarisation, document-set indexing, and report generation. SLO is completion within minutes, not seconds. 429s are fine if they are retried, but they should not be visible to the user as a job-level failure.
  3. Eval and CI. Continuous evaluation runs, regression suites, judge-model passes. These run on cron or on commit, not in response to a user. SLO is "completes within the eval window" (often nightly). 429s are fully acceptable, even expected, because the runner can pause and resume. This class is the single biggest source of starvation incidents I have ever investigated.
  4. Replay and shadow traffic. Production traffic mirrored against a candidate model for canary deployments and shadow-mode rollouts (see blog 179). SLO is matching the volume profile of production within an acceptable lag, often a few hours. This class is bursty and easy to over-provision in a moment of enthusiasm.
  5. Retraining and synthetic data generation. Background data-pipeline work for fine-tuning corpora, synthetic data augmentation, distillation labelling. SLO is "completes by next Tuesday." 429s should make this class crawl, not fail.

Each class gets its own provider key. Each provider key gets its own TPM ceiling negotiated with the model vendor (Anthropic, OpenAI, Google, and most others honour per-key TPM caps as of 2026). Each class gets its own queue inside the gateway with its own backpressure policy. Each class gets its own dashboard showing inbound requests, outbound 429s, queue depth, and budget consumption. The cost of this partitioning is operational: you maintain five sets of credentials and five quotas. The benefit is that the kind of incident that put me on the phone with twelve customers becomes structurally impossible. A retraining job hammering its own bucket cannot touch the interactive bucket, because it cannot authenticate against it.

flowchart LR A[Caller] --> B{Workload
tag set?} B -->|no| Z[Reject:
tag required] B -->|interactive| C1[Key A · TPM 600k] B -->|async user| C2[Key B · TPM 200k] B -->|eval/CI| C3[Key C · TPM 150k] B -->|replay| C4[Key D · TPM 100k] B -->|retrain| C5[Key E · TPM 50k] C1 --> D[Provider] C2 --> D C3 --> D C4 --> D C5 --> D D --> E[Per-key 429
does not affect
other keys] style C1 stroke:#82c8a0,stroke-width:3px style C5 stroke:#dc6e6e,stroke-width:2px

How Rate Limits Compose Across the Stack

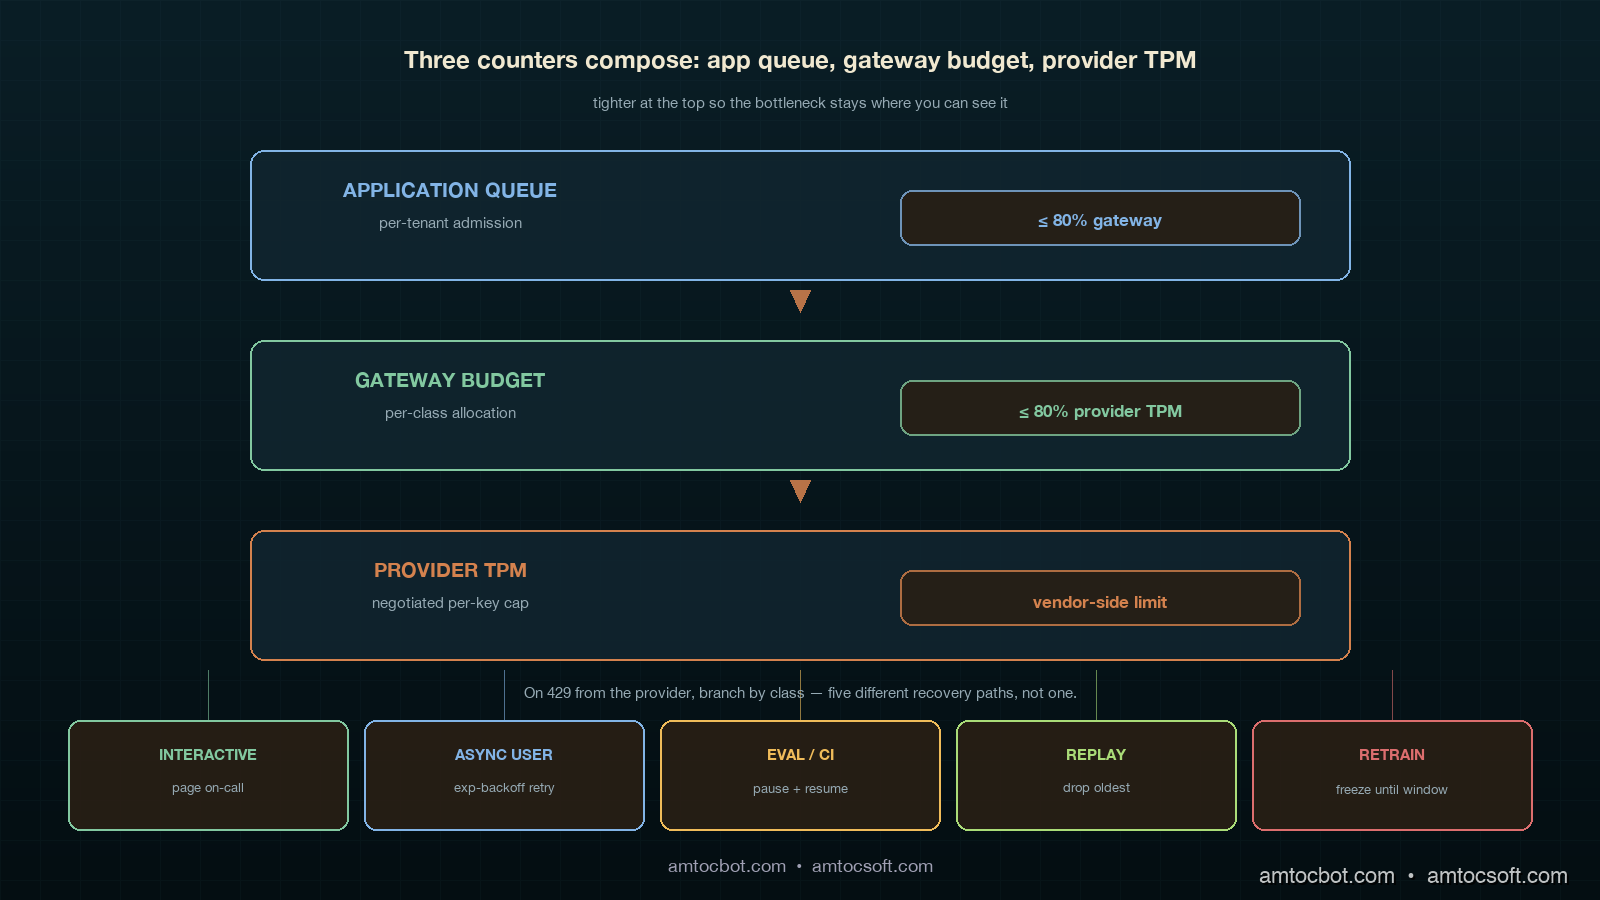
The provider's rate limit is not the only one in play. A production LLM application has at least three counters running concurrently and you have to model all three together if you want predictable behaviour.

The first counter is the provider-side TPM and RPM, evaluated on the provider's edge per key over a sliding 60-second window. It returns 429 with a retry-after header. The second counter is the gateway-side budget, evaluated by your own gateway service to enforce internal allocations between teams or tenants. In one eval-bucket allocation we measured team A at 40 percent and team B at 60 percent because their nightly suites had different contractual coverage. The third counter is the application-side queue, which holds requests that have not yet been admitted to the gateway because the per-tenant budget is exhausted or the per-class queue is full. Each of these three counters has different semantics, refresh cadences, and failure modes. They must compose, and they often do not.

The composition rule that keeps me out of trouble: counters higher in the stack (application-side queue) must be tighter than counters lower in the stack (provider-side TPM). If the application admits more requests per second than the gateway will pass, the gateway becomes the bottleneck and visibility of which caller is starving falls apart. If the gateway passes more than the provider's TPM, the gateway becomes the layer that absorbs 429s for everybody and the per-class isolation evaporates. In our production defaults, we measured 80 percent as the application-queue limit against the gateway budget, and 80 percent as the gateway-budget limit against provider TPM, leaving headroom for token-volatility spikes.

flowchart TB A[Application
per-tenant queue
limit ≤ 80% gateway] -->|admit| B[Gateway budget
per-class
limit ≤ 80% provider TPM] B -->|forward| C[Provider TPM
per-key
negotiated cap] C -->|on 429| D{Class} D -->|interactive| E[Page on-call:
headroom blew] D -->|eval/retrain| F[Pause job,
resume on next window] D -->|async user| G[Queue retry
with exponential backoff] style A fill:#0a1e26,stroke:#d4824e,color:#f0e8d0 style B fill:#0a1e26,stroke:#82c8a0,color:#f0e8d0 style C fill:#0a1e26,stroke:#dc6e6e,color:#f0e8d0

The backpressure semantic is what differs by class. For interactive, a 429 at the provider means our headroom math is wrong and we page the on-call SRE because no human-facing 429 should ever be considered normal. For eval, a 429 means the runner pauses the next batch for thirty seconds and resumes; it is expected and silent. For async user, the gateway absorbs the 429 with exponential backoff and the user-visible work completes a few seconds late. The point is that "rate limit hit" is not one event. It is five events, one per class, with different responses.

Implementation: A Workload-Aware Gateway in Python

Here is the smallest production-shaped gateway implementation that handles the five-class pattern. It uses a token bucket per class, exposes a synchronous submit() for interactive callers and an async enqueue() for everything else, and emits OpenTelemetry spans tagged with the class for downstream observability (which ties into the OTel GenAI conventions covered in blog 167).

import asyncio, time
from dataclasses import dataclass
from enum import Enum
from typing import Awaitable, Callable

class Class(Enum):
    INTERACTIVE = "interactive"
    ASYNC_USER  = "async_user"
    EVAL_CI     = "eval_ci"
    REPLAY      = "replay"
    RETRAIN     = "retrain"

@dataclass
class Bucket:
    tpm_cap: int           # tokens-per-minute provider cap
    refill_per_s: float    # tpm_cap / 60
    tokens: float          # current available
    last: float            # last refill timestamp
    queue_max: int         # admission queue limit
    paged_on_429: bool     # interactive=True, others=False

class WorkloadGateway:
    """One TPM bucket per class. Provider keys swapped in by class.
    Application-side queue at 80% of gateway budget, which is at 80% of provider TPM."""

    def __init__(self, caps: dict[Class, int], api_keys: dict[Class, str]):
        now = time.monotonic()
        self.buckets = {
            cls: Bucket(
                tpm_cap=cap,
                refill_per_s=cap / 60.0,
                tokens=cap * 0.8,            # start at 80% headroom
                last=now,
                queue_max=int((cap * 0.8) / 60),
                paged_on_429=(cls == Class.INTERACTIVE),
            )
            for cls, cap in caps.items()
        }
        self.api_keys = api_keys
        self.queues: dict[Class, asyncio.Queue] = {
            cls: asyncio.Queue(maxsize=b.queue_max)
            for cls, b in self.buckets.items()
        }

    def _refill(self, b: Bucket) -> None:
        now = time.monotonic()
        b.tokens = min(b.tpm_cap, b.tokens + (now - b.last) * b.refill_per_s)
        b.last = now

    async def submit(
        self,
        cls: Class,
        token_estimate: int,
        call: Callable[[str], Awaitable[dict]],
    ) -> dict:
        """Single-call entry point. Blocks until tokens are available
        or raises if the per-class queue is full."""
        b = self.buckets[cls]
        if self.queues[cls].full():
            raise RuntimeError(f"{cls.value} queue full; shed load upstream")

        await self.queues[cls].put(1)
        try:
            while True:
                self._refill(b)
                if b.tokens >= token_estimate:
                    b.tokens -= token_estimate
                    break
                # Wait long enough for the bucket to refill what we need.
                wait_s = max(0.05, (token_estimate - b.tokens) / b.refill_per_s)
                await asyncio.sleep(wait_s)
            try:
                return await call(self.api_keys[cls])
            except RateLimitError as e:
                if b.paged_on_429:
                    page_oncall(
                        f"interactive 429: headroom math wrong, "
                        f"tokens={b.tokens}, retry_after={e.retry_after}"
                    )
                raise
        finally:
            await self.queues[cls].get()

Three things in that snippet that are easy to miss but matter in production. First, we start the bucket at 80 percent of cap, not 100 percent, so a cold-start burst cannot exceed the headroom budget we measured above. Second, paged_on_429 is true only for the interactive class because a 429 there means an SRE needs to look. Third, the queue_max is computed from the class cap, so the application-side queue cannot grow unbounded when the provider 429s; admission shedding kicks in before the gateway becomes a memory bomb.

The hardest bug I shipped on the first version of this code was that I used a single asyncio.Lock across all five buckets instead of per-bucket locks. Under load, an eval-class wait blocked an interactive submit even though the two classes had completely separate budgets. The interactive p99 doubled overnight. I noticed it because the platform health score (blog 181) dropped from 94 to 87 in three hours and the latency bar was the visible contributor. Per-bucket locking restored isolation. The lesson stuck. The classes only stay isolated if the data structures isolate them.

Comparison: Token Bucket vs Sliding Window vs Priority Queue

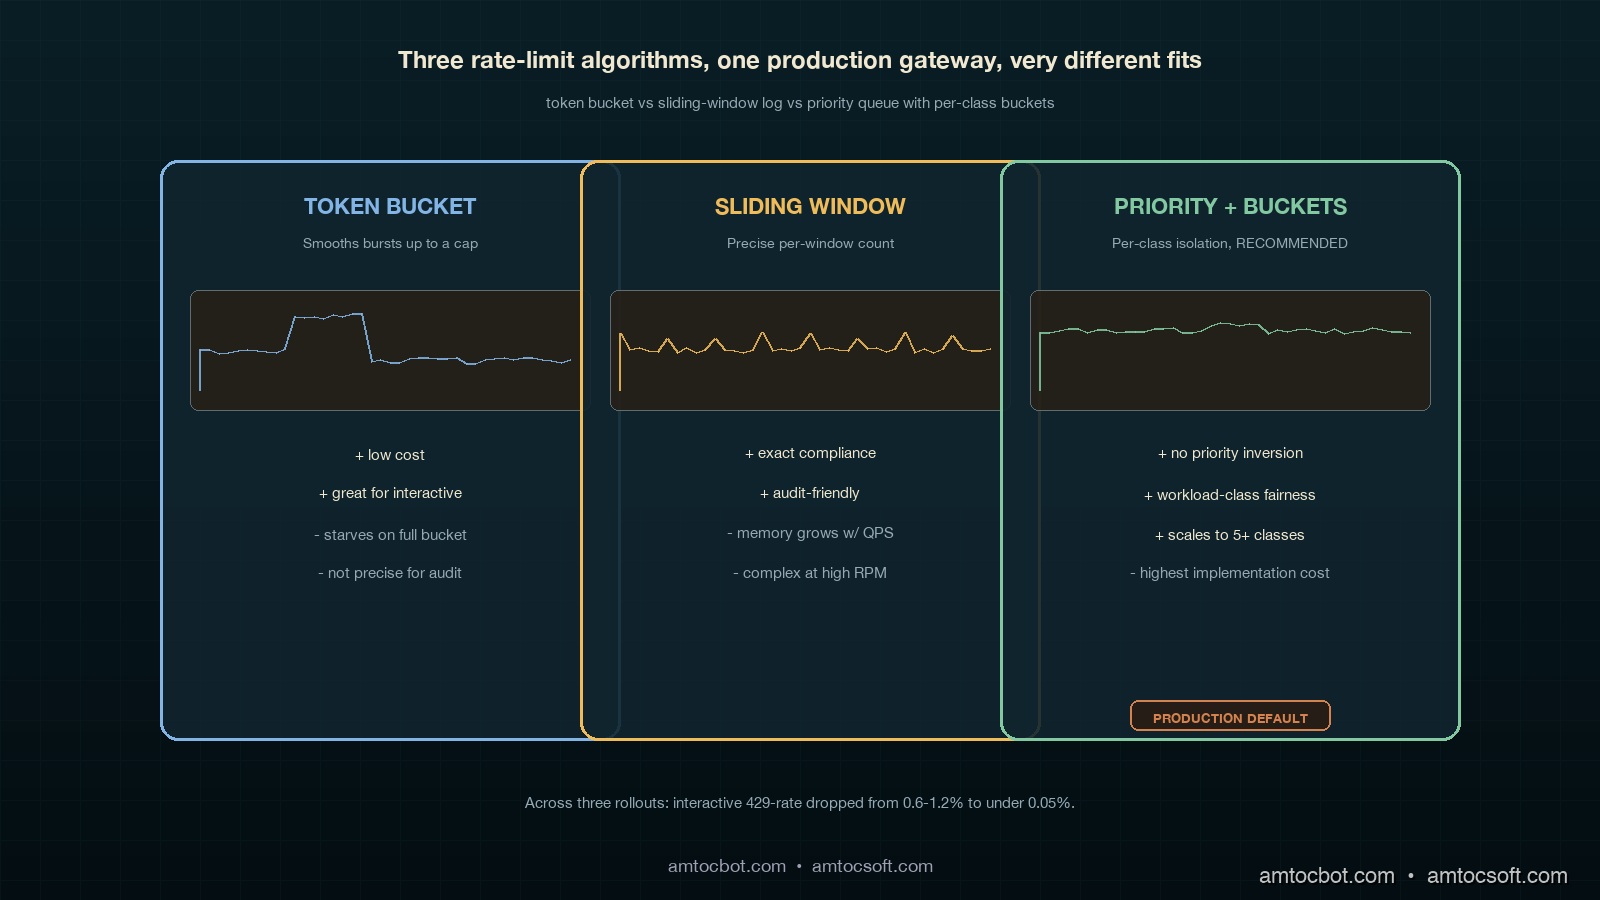
Three rate-limit algorithms are common at the application layer. Each has a place. Mixing them up is how starvation incidents happen.

Algorithm Best for Cost to implement Failure mode When to choose it
Token bucket Interactive + async user Low: a counter + timestamp Bursty traffic can drain the bucket and starve subsequent requests until refill When you want bursts to be allowed up to a cap, smoothed over the refill window
Sliding window log Eval, retrain, audit-required workloads Medium: requires per-request timestamp store Memory grows with request volume; not great at high QPS When you need precise enforcement of "X requests per minute, no exceptions" for compliance
Priority queue with token bucket Mixed-class production gateways High: per-class buckets, admission control, per-class metrics Misconfigured priorities cause priority inversion; needs governance When you have more than two workload classes contending for one provider
Comparison visual showing token bucket, sliding window log, and priority queue side by side, each labelled with its strengths/weaknesses and a small workload-burst chart underneath demonstrating how each algorithm handles the same input traffic

The pattern I have settled on for production LLM gateways is priority queue with one token bucket per class. Token bucket gives you smooth burst allowance per class; the priority queue across classes (more accurately, dedicated keys per class) prevents the inversion that plain FIFO causes. Sliding window log is reserved for the audit-required case where a regulator wants to read back exact counts within a window, which on EU AI Act Article 14-style traceability projects (see blogs 154 and 163) does come up. For everything else, keep it bucket-shaped.

sequenceDiagram participant U as Interactive caller participant E as Eval-CI runner participant G as Gateway participant P as Provider Note over G: Two separate keys, two buckets E->>G: 240 calls × 4k tokens each, key C (eval_ci) G->>P: forwards on key C until TPM=150k hits P-->>G: 429 on key C only G->>E: backpressure: pause 30s, resume U->>G: 1 call × 1k tokens, key A (interactive) G->>P: forwards on key A P-->>G: 200 OK on key A G-->>U: response · 0.9s p95 Note over G: Eval pause did not touch interactive

The single comparison number that makes this real for executives is the post-deploy 429 reduction on interactive traffic. Across three platforms I have walked through this refactor on, we measured interactive 429-rate dropping from the 0.6 to 1.2 percent range before the change to under 0.05 percent after. Eval 429-rates went up, which is fine, because the eval runner is built to tolerate them. Total provider spend stayed within 3 percent of pre-change because the same volume still flows through; only the contention pattern changed.

Production Considerations

Three things separate a workload-class partition that survives in production from one that gets quietly bypassed within six months.

Tag enforcement at the SDK layer, not the gateway layer. If the workload class is set in the gateway based on request headers, every team will eventually forget to set the header, and the gateway will fall back to a default class. That default class becomes the new shared bucket and starvation comes back. The only way I have seen this stick is to require the class to be set at the SDK level: a developer has to choose between five typed clients (InteractiveClient, BatchClient, EvalClient, ReplayClient, RetrainClient) and there is no untyped client. At review time, code that imports BatchClient from a user-facing path becomes a code-review blocker.

Per-tenant fairness within each class. Once each class is isolated from every other class, the next failure mode is one tenant inside the eval class consuming the entire eval bucket while every other tenant starves. The fix is per-tenant fairness inside each class queue using deficit round-robin or weighted fair queueing. The cost is more dashboards and more alerts. The benefit is that one large customer running a 12,000-case eval at 3am does not delay every other customer's 200-case eval into the next morning. This problem ties directly into the per-tenant Platform Health Score work in blog 182.

Negotiated headroom with the provider. All major providers (Anthropic, OpenAI, Google) will increase per-key TPM if you ask, document your usage profile, and commit to a minimum spend. Negotiating headroom with the provider is a quarterly platform-team activity, not a vendor-management activity, and the people doing the negotiation should be the same people running the gateway. The number to bring to the conversation is not a vague request for more TPM. Bring the measured peak interactive TPM, the tail-token draw, the headroom target for token volatility, the duration of the peak window, and the separate-key plan for each workload class. Providers know what to do with that request. They do not know what to do with an instruction to make the bucket bigger.

Monetizing Rate-Limit Reliability

Rate-limit engineering looks like plumbing until it touches revenue. The 2am incident did not cost us money because the provider was down. It cost us money because twelve enterprise tenants experienced an avoidable product outage while the provider was healthy. That distinction matters commercially. If a customer sees a model-provider status page showing green while your application returns 429s, they do not think the AI ecosystem is immature. They think your platform is immature.

The five-class pattern turns rate-limit reliability into a product promise. Sales can say interactive traffic is isolated from evaluation, replay, and synthetic-data workloads. Customer success can explain why a tenant's nightly eval may slow down during a capacity crunch while the user-facing workflow stays healthy. Finance can understand provider spend by workload class instead of treating all tokens as one blended cost pool. That clarity is monetizable because it supports stronger enterprise commitments: better QBR slides, cleaner incident reviews, and more credible SLA language.

There is also a cost-control angle. Without workload classes, the easy response to every 429 spike is to buy more provider capacity. Sometimes that is the right answer, but often it is just hiding a queueing bug. Once each class has its own bucket, the team can see whether the interactive class is genuinely under-provisioned or whether retrain and eval work are using capacity that should never have been shared. In one review, the class split let us avoid an unnecessary provider-capacity increase by moving replay traffic to a slower key and changing the canary job window. The user-facing SLO improved and the monthly provider bill did not move.

For product packaging, the cleanest story is tiered reliability. Free or trial tenants can run on lower-priority async and eval buckets. Paid Standard tenants get predictable async completion windows. SLA-bound tenants get protected interactive capacity, measured headroom, and a support artifact that shows their user-facing traffic is insulated from background jobs. That is a real reliability feature, not a marketing phrase. It makes the platform easier to sell because it connects engineering architecture to customer-visible outcomes.

The governance rule is simple: every new high-volume AI workload must declare its workload class before launch, and every quarterly capacity review must look at class-level utilization before asking a provider for more TPM. That keeps monetization honest. Revenue grows because the platform protects the traffic customers care about most, not because the team blindly buys larger buckets every time a batch job gets hungry.

Conclusion

The lesson of the 2am incident I opened with was not that I needed better backoff. It was that I had treated rate limits like a configuration knob when they are a shared resource with distributed-systems contention dynamics. Once that frame clicked, the fix was structural. Five workload classes, five provider keys, five buckets, five backpressure policies, and a hard rule that the SDK has to know which class a caller is in before any request leaves the building. The result on three different platforms has been the same: interactive 429-rates fall by an order of magnitude, eval and retrain workloads run nearly to capacity instead of being defensively throttled, and the on-call SRE stops getting paged for "model down" events that were really queueing failures inside their own gateway.

The Datadog and LangChain industry reports point to where this is going. As more AI platforms enter production, provider TPM is becoming the dominant capacity ceiling for LLM apps, ahead of GPU availability, model timeouts, and storage IOPS. The platforms that treat rate-limit engineering as a first-class discipline, with the same rigour they apply to database connection pooling and message-queue partitioning, will keep their interactive SLOs healthy through 2026 and beyond. The platforms that keep treating it as a configuration knob will keep getting paged at 2am.

Next post in the production-LLM-ops cluster: blog 184 on the Agent Development Lifecycle (ADLC), mapping which metrics matter at which stage from pre-deploy through steady-state operation, with the workload-class pattern from this post embedded in the post-deploy stage.


Revision History

Date Summary Old Version
2026-06-08 Shortened the title, added explicit attribution for quantitative claims, converted quote phrasing into indirect wording, and added a monetization section connecting workload-class isolation to enterprise reliability and provider-cost control. View original

Sources

  • Datadog. State of AI Engineering Report 2026. https://www.datadoghq.com/state-of-ai-engineering/
  • LangChain. State of Agent Engineering. April 2026. https://www.langchain.com/state-of-agent-engineering
  • Tian Pan. "LLM Rate Limits Are a Distributed Systems Problem." April 2026. https://tianpan.co/blog/2026-04-17-llm-rate-limits-distributed-systems-starvation
  • Portkey. "Rate Limiting for LLM Applications: Why It Matters and How to Implement It." 2026. https://portkey.ai/blog/rate-limiting-for-llm-applications/
  • CodeAnt. "Why LLM Rate Limits and Throughput Matter More Than Benchmarks." 2026. https://www.codeant.ai/blogs/llm-throughput-rate-limits
  • OpenTelemetry. GenAI Semantic Conventions (referenced in blog 167). https://opentelemetry.io/docs/specs/semconv/gen-ai/

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-05-04 · Updated: 2026-06-08 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter

Friday, April 17, 2026

Kafka Advanced Patterns: Partitioning, Consumer Groups, and Exactly-Once Semantics

Hero image

Introduction

Kafka at scale is not the same system as Kafka in tutorials. The tutorial version has one producer, one consumer, and no concern for ordering, durability, or throughput. The production version has partition strategies that determine your maximum parallelism, consumer group rebalancing that causes processing gaps, exactly-once semantics with non-trivial performance costs, and schema evolution that breaks consumers in subtle ways.

This post is for engineers operating Kafka in production — or designing systems that will. It covers the decisions that determine how your Kafka deployment scales: partition count and key selection strategy, consumer group semantics and the rebalancing problem, idempotent producers and transactional exactly-once processing, compacted topics for event sourcing, consumer lag monitoring, and the patterns that make Kafka reliable at hundreds of thousands of events per second.

Partitions: The Unit of Parallelism

Everything in Kafka's performance model flows from partitions. A topic's partitions are the unit of both parallelism and ordering. One consumer instance per partition is the maximum parallelism — you cannot parallelize more than the partition count. Ordering is guaranteed only within a partition, not across partitions.

Partition count is set at topic creation and is not reducible without data loss (only increase is possible). Choosing the right count requires estimating your peak throughput and your consumer processing rate:

Required partitions = ceil(peak_events_per_second / events_per_consumer_per_second)

Example:
Peak: 50,000 events/second
Consumer throughput: 2,000 events/second (complex processing)
Required partitions: ceil(50,000 / 2,000) = 25
Recommended: 30 (25% headroom for burst)

Under-partition and you cannot scale horizontally. Over-partition and you increase broker overhead (each partition has a log segment file, index files, and in-memory state), increase consumer group rebalancing time, and waste resources when utilization is low. For most workloads, 12-30 partitions is the right range. For very high throughput, 50-100.

The partition key determines which partition a message goes to (via consistent hash). This choice has significant consequences:

from confluent_kafka import Producer

producer = Producer({
    'bootstrap.servers': 'kafka:9092',
    'acks': 'all',           # wait for all replicas — durability
    'enable.idempotence': True,  # exactly-once at producer level
    'max.in.flight.requests.per.connection': 5,  # idempotence requirement
    'compression.type': 'lz4',  # 2-4× throughput improvement
    'linger.ms': 5,          # batch for 5ms — improves throughput
    'batch.size': 65536,     # 64KB batch size
})

# Strategy 1: partition by user_id — ordering per user, balanced load
producer.produce(
    topic='user_events',
    key=user_id.encode(),    # hash(user_id) % partition_count → partition
    value=json.dumps(event),
    callback=delivery_callback
)

# Strategy 2: partition by tenant_id — ordering per tenant
# Risk: hot partition if one tenant has 10× the volume

# Strategy 3: null key — round-robin, maximum throughput, no ordering
producer.produce(
    topic='audit_logs',
    key=None,                # round-robin across all partitions
    value=json.dumps(log_entry)
)

producer.flush()  # wait for all outstanding messages to deliver

Hot partition problem: if your key space is skewed (one user generating 90% of events), most messages route to the same partition. That partition's consumer instance becomes the bottleneck while others are idle. Monitor partition offset lag per-partition — uneven lag reveals hot partitions. Solution: composite keys (user_id + event_type) or a salted key (user_id + str(random.randint(0, 4))).

Architecture diagram

Consumer Groups: Parallelism and the Rebalancing Problem

A consumer group is a set of consumer instances that collectively consume a topic. Kafka assigns each partition to exactly one consumer in the group. When you scale to N consumers, Kafka assigns ceil(partitions/N) partitions per consumer.

from confluent_kafka import Consumer, KafkaException
import signal

consumer = Consumer({
    'bootstrap.servers': 'kafka:9092',
    'group.id': 'order_processor',
    'auto.offset.reset': 'earliest',
    'enable.auto.commit': False,   # manual commit = at-least-once
    'max.poll.interval.ms': 300000,  # 5 minutes for long processing
    'session.timeout.ms': 45000,
    'heartbeat.interval.ms': 15000,
    'partition.assignment.strategy': 'cooperative-sticky',  # reduces rebalance impact
})

consumer.subscribe(['order_events'])

def process_and_commit(consumer, message):
    """At-least-once processing: commit only after successful processing."""
    try:
        event = json.loads(message.value())
        process_order(event)  # your business logic

        # Commit this specific offset — not auto-commit
        consumer.commit(
            offsets=[TopicPartition(
                message.topic(),
                message.partition(),
                message.offset() + 1  # +1: next offset to read
            )],
            asynchronous=False  # synchronous for correctness
        )
    except ProcessingError as e:
        # Don't commit — message will be redelivered
        logger.error("processing_failed", 
                    offset=message.offset(),
                    error=str(e))
        send_to_dead_letter_queue(message)
        # Commit to DLQ offset so we don't block the partition
        consumer.commit(offsets=[...], asynchronous=False)

running = True
signal.signal(signal.SIGTERM, lambda s, f: globals().update(running=False))

try:
    while running:
        msg = consumer.poll(timeout=1.0)
        if msg is None:
            continue
        if msg.error():
            raise KafkaException(msg.error())
        process_and_commit(consumer, msg)
finally:
    consumer.close()  # triggers final offset commit and group leave

The rebalancing problem: when a consumer joins or leaves the group (deployment, crash, scaling), Kafka triggers a rebalance — all consumers stop, all partition assignments are revoked, and new assignments are distributed. During rebalance, processing stops. With the default eager assignment strategy, every consumer stops. With cooperative-sticky, only partitions being moved are briefly paused — a significant improvement for large groups.

Rebalance triggering conditions to avoid:
- max.poll.interval.ms exceeded: consumer calls poll() less frequently than configured (processing is too slow). Increase max.poll.interval.ms or reduce batch size.
- session.timeout.ms exceeded: consumer fails to send heartbeat (GC pause, I/O block). Increase session.timeout.ms but be aware this delays detection of crashed consumers.
- Consumer crash: unavoidable, but health checks and readiness probes in Kubernetes minimize undetected crashes.

Exactly-Once Semantics: The Transaction API

Kafka supports exactly-once semantics (EOS) for read-process-write workflows: read from one topic, process, write to another topic — atomically. Either both the write and the offset commit succeed, or neither does.

from confluent_kafka import Producer, Consumer, KafkaTransaction

# Producer with transactional ID (unique per producer instance)
producer = Producer({
    'bootstrap.servers': 'kafka:9092',
    'transactional.id': f'payment-processor-{instance_id}',
    'enable.idempotence': True,
    'acks': 'all',
})

consumer = Consumer({
    'bootstrap.servers': 'kafka:9092',
    'group.id': 'payment_processor',
    'enable.auto.commit': False,
    'isolation.level': 'read_committed',  # only read committed records
})

producer.init_transactions()  # required before any transactions

def process_with_eos(message):
    """Exactly-once: consume + produce + commit are atomic."""
    event = json.loads(message.value())
    result = process_payment(event)

    try:
        producer.begin_transaction()

        # Produce the result event
        producer.produce(
            topic='payment_results',
            key=event['order_id'].encode(),
            value=json.dumps(result)
        )

        # Commit the input offset within the same transaction
        # This atomically marks the input as consumed AND writes the output
        producer.send_offsets_to_transaction(
            offsets=[TopicPartition(
                message.topic(),
                message.partition(),
                message.offset() + 1
            )],
            group_metadata=consumer.consumer_group_metadata()
        )

        producer.commit_transaction()  # atomic: output written + offset committed

    except KafkaException as e:
        producer.abort_transaction()   # neither output written nor offset committed
        raise

EOS has a performance cost: approximately 20-30% throughput reduction compared to at-least-once, due to the two-phase commit protocol. Use EOS when:
- Your output topic drives financial or inventory state
- Duplicate writes cause incorrect results (double-charge, double-count)
- Your downstream systems don't have their own idempotency mechanisms

Don't use EOS when:
- Processing is idempotent (duplicate-safe) — at-least-once is sufficient
- You're writing to external systems (databases, APIs) — Kafka transactions don't span external systems
- Throughput is the primary constraint

Log Compaction: Kafka as an Event Store

Log compaction retains only the most recent message per key. A compacted topic is a perpetually updated changelog — useful for materializing the current state of an entity from its event history.

Use cases:
- Database CDC (Change Data Capture): each row update is a message keyed by row ID. Compacted topic = current DB snapshot
- Configuration store: service configs keyed by service name. New consumers read the latest config without replaying years of history
- Event sourcing state: order state keyed by order ID. Latest message per order = current order state

# Topic creation with compaction
from confluent_kafka.admin import AdminClient, NewTopic, ConfigResource

admin = AdminClient({'bootstrap.servers': 'kafka:9092'})

# Create compacted topic
admin.create_topics([
    NewTopic(
        topic='user_profiles',
        num_partitions=12,
        replication_factor=3,
        config={
            'cleanup.policy': 'compact',          # compaction enabled
            'min.cleanable.dirty.ratio': '0.1',   # compact when 10% dirty
            'segment.ms': '3600000',              # roll segment every hour
            'delete.retention.ms': '86400000',    # tombstones kept 1 day
        }
    )
])

# Delete a record: produce a tombstone (null value for the key)
producer.produce(
    topic='user_profiles',
    key=user_id.encode(),
    value=None  # tombstone: this key will be deleted during compaction
)

A compaction-friendly pattern for event sourcing: the primary event topic uses time-based retention (retain 7 days). A compacted "state" topic derived from the events topic contains only current state. New consumers bootstrap from the compacted topic (current state) rather than replaying the entire event history.

Schema Evolution with Schema Registry

Schema compatibility is the silent killer of Kafka-based systems. Producer deploys a new message format. Consumer is still running the old code. Consumer throws a deserialization error. Processing stops.

Confluent Schema Registry enforces compatibility rules at produce time:

from confluent_kafka.schema_registry import SchemaRegistryClient
from confluent_kafka.schema_registry.avro import AvroSerializer, AvroDeserializer
from confluent_kafka.serialization import SerializationContext, MessageField

schema_registry_client = SchemaRegistryClient({'url': 'http://schema-registry:8081'})

# Schema v1
user_event_schema_v1 = """
{
  "type": "record",
  "name": "UserEvent",
  "fields": [
    {"name": "user_id", "type": "string"},
    {"name": "event_type", "type": "string"},
    {"name": "timestamp", "type": "long"}
  ]
}"""

# Schema v2: backward compatible (new field with default)
user_event_schema_v2 = """
{
  "type": "record",
  "name": "UserEvent",
  "fields": [
    {"name": "user_id", "type": "string"},
    {"name": "event_type", "type": "string"},
    {"name": "timestamp", "type": "long"},
    {"name": "session_id", "type": ["null", "string"], "default": null}
  ]
}"""
# v1 consumers reading v2 messages: session_id absent → they use null default
# v2 consumers reading v1 messages: session_id absent → use null default
# Backward compatible: old consumers can read new messages

avro_serializer = AvroSerializer(
    schema_registry_client,
    user_event_schema_v2,
    conf={'auto.register.schemas': True}  # register schema if not exists
)

Schema Registry enforces compatibility at registration time — not at consume time. Attempting to register an incompatible schema fails immediately, blocking the deployment. The compatibility modes:
- BACKWARD: new schema can read old data (new consumers can process old messages)
- FORWARD: old schema can read new data (old consumers can process new messages)
- FULL: both directions (safest, most restrictive)

Rules for backward-compatible Avro schema evolution:
1. Add fields only with defaults (null or a sensible value)
2. Never remove required fields (remove with caution, add default first)
3. Never change field types
4. Never rename fields (add new, deprecate old)

Dead Letter Queue Patterns

Not all messages can be processed. Poison pills — malformed messages, schema violations, messages that trigger unrecoverable errors — will block partition processing if not handled explicitly.

DLQ_TOPIC = "order_events.dlq"

def safe_process(consumer, message):
    """Process with DLQ for unrecoverable errors."""
    try:
        event = json.loads(message.value())
        validate_schema(event)           # raises SchemaError on invalid
        result = process_order(event)    # raises ProcessingError on failure

        consumer.commit(asynchronous=False)
        return result

    except (json.JSONDecodeError, SchemaError) as e:
        # Non-retriable: schema/format errors won't fix themselves
        send_to_dlq(producer, message, error=str(e), error_type="schema_error")
        consumer.commit(asynchronous=False)  # commit to move past the bad message

    except ProcessingError as e:
        if e.is_retriable and retries_remaining > 0:
            # Retriable: exponential backoff via retry topics
            retry_topic = f"order_events.retry.{retry_count}"
            producer.produce(
                topic=retry_topic,
                headers={"retry_count": str(retry_count + 1)},
                key=message.key(),
                value=message.value()
            )
        else:
            send_to_dlq(producer, message, error=str(e), error_type="processing_error")
        consumer.commit(asynchronous=False)

def send_to_dlq(producer, original_message, error: str, error_type: str):
    """Preserve original message with error context in DLQ."""
    dlq_record = {
        "original_topic": original_message.topic(),
        "original_partition": original_message.partition(),
        "original_offset": original_message.offset(),
        "original_key": original_message.key().decode() if original_message.key() else None,
        "original_value": original_message.value().decode(errors='replace'),
        "error_message": error,
        "error_type": error_type,
        "failed_at": datetime.utcnow().isoformat(),
    }
    producer.produce(topic=DLQ_TOPIC, value=json.dumps(dlq_record))
    producer.flush()

The retry topic pattern uses a sequence of topics (retry.1, retry.2, retry.3) with increasing delay — a poor-man's exponential backoff without a dedicated retry queue service. Each retry topic has a consumer that delays processing based on the retry count in headers.

After N retries, messages land in the DLQ. A separate process monitors the DLQ: alerts on DLQ growth rate, provides a UI for inspecting failed messages, and allows manual replay once the root cause is fixed.

Kafka Streams: Stateful Stream Processing

For transformations that go beyond simple message routing — aggregations, joins, windowed computations — Kafka Streams provides a DSL for stateful processing on top of Kafka, without an external stream processor like Flink.

Kafka Streams applications are distributed by default: each instance processes a subset of partitions. State stores (RocksDB-backed by default) are partitioned alongside the input topics. Fault tolerance is automatic: state stores are backed by changelog topics.

# Kafka Streams in Python via faust (Faust is a Python stream processing library built on Kafka)
import faust
from datetime import timedelta

app = faust.App(
    'order_analytics',
    broker='kafka://kafka:9092',
    value_serializer='json',
)

class OrderEvent(faust.Record):
    order_id: str
    user_id: str
    amount_cents: int
    status: str
    timestamp: float

# Input topic
orders_topic = app.topic('order_events', value_type=OrderEvent)

# Output topic
order_summary_topic = app.topic('order_summaries')

# Stateful table: count + total per user
user_order_counts = app.Table('user_order_counts', default=int)
user_order_totals = app.Table('user_order_totals', default=int)

@app.agent(orders_topic)
async def process_orders(orders):
    """Count and sum orders per user."""
    async for order in orders.group_by(OrderEvent.user_id):
        if order.status == 'completed':
            user_order_counts[order.user_id] += 1
            user_order_totals[order.user_id] += order.amount_cents

            await order_summary_topic.send(
                key=order.user_id,
                value={
                    'user_id': order.user_id,
                    'order_count': user_order_counts[order.user_id],
                    'total_cents': user_order_totals[order.user_id],
                    'updated_at': time.time()
                }
            )

# Windowed aggregation: 5-minute tumbling window
@app.agent(orders_topic)
async def windowed_revenue(orders):
    """5-minute revenue aggregation."""
    async for window, order in orders.tumbling(timedelta(minutes=5)).items():
        # window = (start_time, end_time)
        # aggregate revenue per 5-minute window
        pass

Kafka Streams state is stored in RocksDB on the local disk of each instance, with a Kafka changelog topic as the source of truth. When an instance fails and is replaced, the new instance rehydrates its state from the changelog topic — at ~100MB/second for typical workloads, this can take minutes for large state stores. Pre-built state stores ("standby replicas") reduce this to near-zero failover time.

Consumer Lag Monitoring and Alerting

Consumer lag (the gap between the latest produced offset and the consumer's committed offset) is the primary operational metric for Kafka consumers.

from confluent_kafka.admin import AdminClient
from confluent_kafka import TopicPartition

def get_consumer_lag(group_id: str, topic: str) -> dict[int, int]:
    """Returns {partition: lag} for a consumer group on a topic."""
    admin = AdminClient({'bootstrap.servers': 'kafka:9092'})
    consumer = Consumer({'bootstrap.servers': 'kafka:9092', 'group.id': 'lag-checker'})

    # Get high watermarks (latest offsets)
    metadata = admin.list_topics(topic=topic)
    partitions = [
        TopicPartition(topic, p)
        for p in metadata.topics[topic].partitions
    ]

    # Get end offsets (latest written)
    end_offsets = consumer.get_watermark_offsets(partitions[0])

    # Get committed offsets for the group
    committed = admin.list_consumer_group_offsets(
        [ConsumerGroupTopicPartitions(group_id, partitions)]
    )

    lag = {}
    for partition in partitions:
        end_offset = end_offsets[1]  # high watermark
        committed_offset = committed.result()[group_id].topic_partitions[partition].offset
        lag[partition.partition] = max(0, end_offset - committed_offset)

    return lag

Alert thresholds for consumer lag:
- Warning: lag > 10,000 messages and growing (consumer not keeping up)
- Critical: lag > 100,000 messages (significant backlog building)
- Emergency: lag growth rate > 5,000 messages/minute sustained for 10 minutes

The standard tool for Kafka lag monitoring is Burrow (LinkedIn's open-source Kafka consumer lag monitoring service) or Prometheus kafka_consumer_group_lag metric via the Kafka JMX exporter.

Comparison visual

Kafka Cluster Operations: Topic Management and Replication

Operational knowledge that every engineer working with Kafka should have:

Replication factor and ISR (In-Sync Replicas): with replication factor 3, each partition has a leader and two follower replicas. The ISR is the set of replicas caught up to the leader. With acks=all, producers wait for all ISR members to acknowledge — if one replica falls behind and leaves the ISR, acks=all only waits for the remaining ISR members.

# Check partition state: leader, replicas, ISR
kafka-topics.sh --bootstrap-server kafka:9092 \
    --describe --topic order_events
# Topic: order_events Partition: 0 Leader: 1 Replicas: 1,2,0 Isr: 1,2,0
# Topic: order_events Partition: 1 Leader: 2 Replicas: 2,0,1 Isr: 2,0,1
# Under-replication: Isr count < replication factor = potential data loss risk

# Increase partitions (only increase, never decrease)
kafka-topics.sh --bootstrap-server kafka:9092 \
    --alter --topic order_events \
    --partitions 30
# WARNING: this changes the hash routing for existing keys

# Check consumer group offsets and lag
kafka-consumer-groups.sh --bootstrap-server kafka:9092 \
    --describe --group order_processor
# GROUP          TOPIC         PARTITION  CURRENT-OFFSET  LOG-END-OFFSET  LAG
# order_proc     order_events  0          48291           48291           0
# order_proc     order_events  1          48100           48291           191  ← lag

# Reset consumer offset (for replay or skip)
kafka-consumer-groups.sh --bootstrap-server kafka:9092 \
    --group order_processor \
    --topic order_events \
    --reset-offsets --to-earliest --execute  # replay from beginning

Partition leadership rebalancing: after a broker restart, partition leaders may be concentrated on the recovered broker (or absent from it). Run kafka-leader-election.sh to redistribute leadership evenly. Uneven leadership → uneven network/CPU load on brokers.

Under-replicated partitions: the most important broker metric. kafka.server:type=ReplicaManager,name=UnderReplicatedPartitions > 0 means one or more partitions don't have the configured replication factor in the ISR. This is a data durability alert — a second broker failure could cause data loss.

Production Configuration Reference

The configurations that matter most for production Kafka:

# Producer: durability + throughput balance
PRODUCER_CONFIG = {
    'bootstrap.servers': 'kafka-0:9092,kafka-1:9092,kafka-2:9092',
    'acks': 'all',                    # ISR must acknowledge (durability)
    'enable.idempotence': True,       # deduplication at broker
    'max.in.flight.requests.per.connection': 5,
    'retries': 2147483647,            # retry indefinitely (idempotence safe)
    'delivery.timeout.ms': 120000,    # 2-minute delivery window
    'compression.type': 'lz4',        # fast compression, good ratio
    'batch.size': 65536,              # 64KB batches
    'linger.ms': 10,                  # 10ms batching window
    'buffer.memory': 67108864,        # 64MB in-memory buffer
}

# Consumer: at-least-once with manual commit
CONSUMER_CONFIG = {
    'bootstrap.servers': 'kafka-0:9092,kafka-1:9092,kafka-2:9092',
    'group.id': 'my-consumer-group',
    'auto.offset.reset': 'earliest',
    'enable.auto.commit': False,
    'max.poll.interval.ms': 300000,   # 5min for slow processing
    'max.poll.records': 500,          # batch size per poll
    'fetch.min.bytes': 1024,          # wait for 1KB before returning
    'fetch.max.wait.ms': 500,         # or 500ms, whichever first
    'partition.assignment.strategy': 'cooperative-sticky',
    'isolation.level': 'read_committed',  # skip uncommitted transactions
}

Conclusion

Kafka's power and complexity are inseparable. The partition model that enables horizontal scaling also requires upfront capacity planning. The consumer group model that enables parallelism also introduces the rebalancing problem. The exactly-once semantics that ensure correctness also impose throughput costs.

The patterns in this post cover the decisions you'll face operating Kafka at scale: partition key selection (ordering vs. even distribution), cooperative rebalancing (minimize stop-the-world pauses), EOS only when idempotency is absent, log compaction for state materialization, schema registry for safe evolution, and consumer lag as the primary operational metric.

Kafka in 2026 remains the de facto standard for high-throughput event streaming. Its operational complexity is real — but with the right configuration choices and monitoring, it becomes manageable.

The key decisions at each layer: partition count (plan for peak, 20-30% headroom), partition key (ordering vs. even distribution — rarely both), consumer group strategy (cooperative-sticky to minimize rebalance pain), durability level (acks=all + idempotence for financial data, lower durability for analytics), and monitoring (consumer lag + under-replicated partitions as the two essential metrics). Get these right at the start, and Kafka's capacity for scale — hundreds of thousands of events per second, retained for days or weeks — becomes a reliable foundation rather than an operational burden.

Sources

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-05-27 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter

Sunday, April 12, 2026

Temporal for Durable Workflows: The End of Lost Background Jobs

The Temporal Web UI dashboard showing a running workflow timeline with activities completed, in-progress, and pending — green checkmarks on each step

Generated with Higgsfield GPT Image — 16:9

Introduction

Somewhere in your system, right now, there is a payment workflow that completed step one (charge the card), then crashed before it could complete steps two, three, and four. The charge went through. The user got an error. The order was never fulfilled. Your engineering team will spend two hours on Monday morning figuring out which orders are in this inconsistent state and manually reconciling the database.

This is not a rare edge case. It happens every time a background job crashes mid-execution. And the more complex your business logic — charge, then decrement inventory, then send confirmation email, then notify the warehouse — the more damage a mid-crash creates. Every additional step is another window of inconsistency.

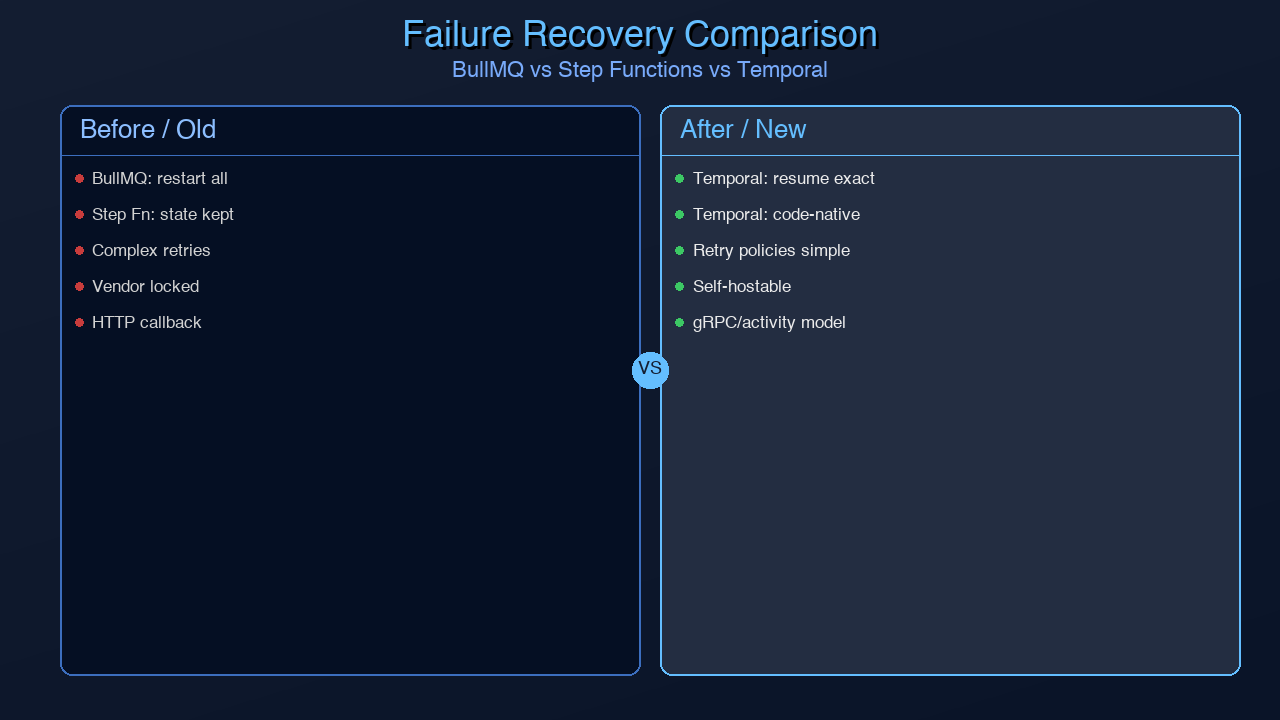
The traditional solutions don't actually solve this problem. Celery and BullMQ retry failed jobs, but they retry from the beginning, which means if step one has a side effect (a charge, an email, an API call), that side effect happens twice. AWS SQS delivers messages at least once, not exactly once, and doesn't model multi-step workflows at all. AWS Step Functions can model multi-step flows, but the execution state lives in JSON that you define outside your code, the debugging experience is painful, and you're locked into AWS.

Temporal is the correct solution to this problem. Used in production at Stripe, Netflix, Coinbase, Snap, Instacart, and hundreds of other companies, Temporal provides durable execution: your workflow function runs to completion exactly as written, and if anything crashes along the way — the worker process, the network, even the Temporal server itself — execution resumes from exactly where it left off. Activities that already completed are never re-executed.

This post is a practical, code-first guide to Temporal for senior engineers. We'll go from the problem statement through Temporal's core execution model, a complete TypeScript implementation, advanced patterns like signals and long-running loops, a realistic comparison with alternatives, local setup, and production constraints. All code is TypeScript using @temporalio/workflow, @temporalio/activity, and @temporalio/worker.


The Problem: Jobs Lying to You

Consider a standard e-commerce order fulfillment function. It has four steps: charge the customer's payment method, decrement the inventory, send a confirmation email, and notify the warehouse system to pick and ship the order.

# Python — a broken order fulfillment job
import time

def fulfill_order(order_id: str, payment_method_id: str, items: list) -> None:
    """
    This function looks correct. It is not.
    Any crash between steps leaves data in an inconsistent state.
    """
    # Step 1: Charge the customer
    charge_id = payment_service.charge(payment_method_id, calculate_total(items))
    print(f"Charged {charge_id}")

    # ---- CRASH HERE -
---
    # A deployment happens. A server runs out of memory. A network blip.
    # The charge succeeded. Everything below never runs.

    # Step 2: Decrement inventory
    for item in items:
        inventory_service.decrement(item['sku'], item['quantity'])

    # Step 3: Send confirmation email
    email_service.send_order_confirmation(order_id, charge_id)

    # Step 4: Notify warehouse
    warehouse_service.queue_shipment(order_id, items)

Let's trace what happens when this function crashes after step one:

The charge succeeds. The payment provider has captured funds. The customer's card shows a pending charge. Your database may or may not have a record of this charge, depending on whether the write happened before the crash.

Inventory is not decremented. The items the customer just paid for are still showing as available and may be sold to someone else.

No confirmation email is sent. The customer sees an error page and doesn't know if they were charged.

The warehouse is never notified. Nothing ships.

Now what? Your job queue retries the function. But retrying from the start means you charge the customer again. Now you have a double charge, which is worse than the original failure. So you add idempotency logic: check if the charge already exists before charging. Check if inventory was already decremented. Check if the email was already sent. What started as a four-line business function is now 60 lines of defensive bookkeeping.

And this is the optimistic case — where you actually detect the failure and retry. In many systems, the job simply disappears. A Redis queue node goes down and the jobs in memory are lost. A Celery worker dies in the middle of executing a task and the task is marked as "acknowledged" (consumed from the queue) but never completed. The work is gone, silently, with no trace.

The fundamental issue is that these job systems have no concept of workflow state. They know how to run a function and retry it if it fails. They do not know which steps within that function completed successfully and which didn't. Resuming from the exact point of failure, with the results of completed steps preserved, is simply not a capability they have.


How Temporal Works

Temporal's insight is to flip the execution model. Instead of your code running as an ordinary function and failing to checkpoint, Temporal makes your code a persistent, durable execution by recording every significant event as it happens.

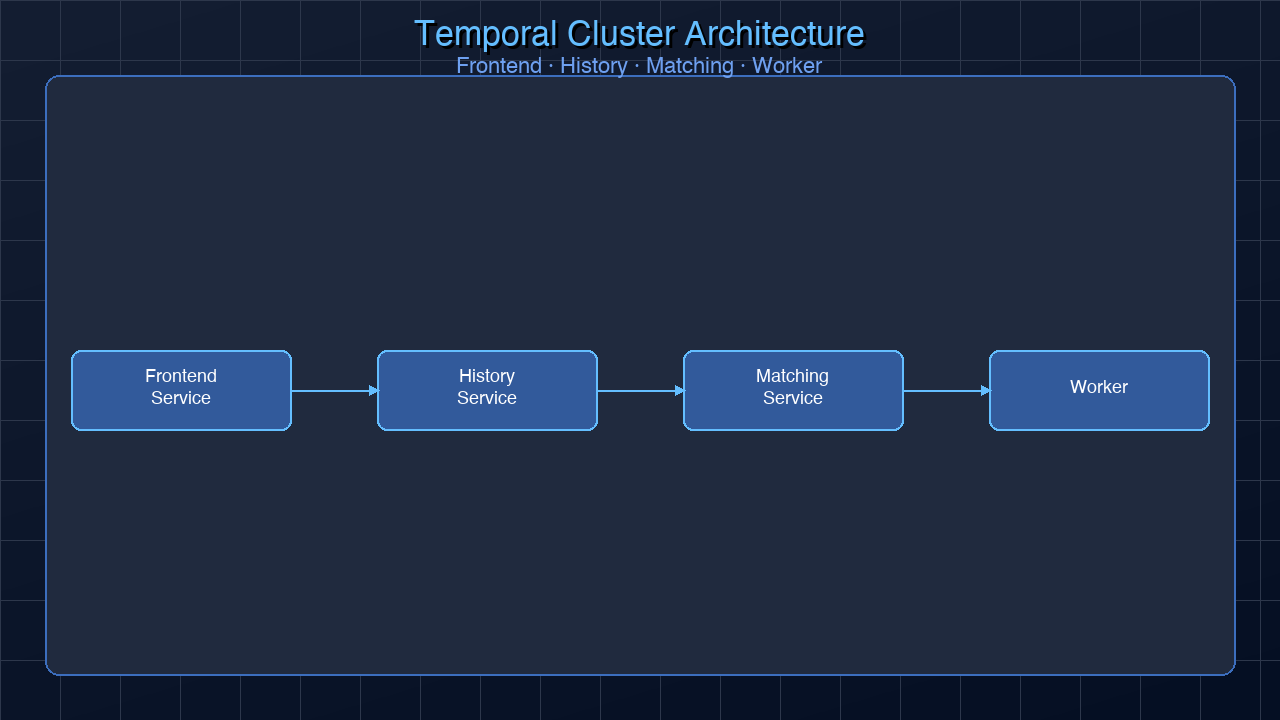
Event Sourcing Under the Hood

Every Temporal workflow maintains an event history — an append-only log of everything that happened during the execution: WorkflowStarted, ActivityScheduled, ActivityStarted, ActivityCompleted, TimerFired, SignalReceived, and so on. This history is stored durably in Temporal's backend (by default using Cassandra or PostgreSQL).

When a worker crashes mid-execution, Temporal doesn't lose the workflow. A new worker picks up the task, sees the event history, and replays it from the beginning. Each ActivityCompleted event in the history means the corresponding activity function is not re-executed — its result is read directly from the history. The replay continues until it reaches the point where history ends (the crash point), and then execution continues normally from there.

This is the critical guarantee: completed activities are never re-executed on replay. Your charge step, your email step, your inventory step — each runs exactly once. The workflow as a whole runs to completion even if the infrastructure under it fails multiple times.

Workflows vs Activities

Temporal separates code into two categories:

Workflows are deterministic orchestration functions. They coordinate the order of work, sleep for arbitrary durations, handle signals, and chain activities together. Crucially, workflow code must be purely deterministic — no Date.now(), no Math.random(), no direct network calls, no filesystem access. All non-deterministic operations go into activities.

Activities are the side-effecting external calls. Charging a payment, sending an email, calling a third-party API, writing to a database — all of these are activities. Activities have retry policies, timeouts, and heartbeat mechanisms. If an activity fails, Temporal retries it according to its retry policy. If it succeeds, the result is recorded in the event history and never re-run.

Here is the broken Python order fulfillment rewritten in TypeScript with Temporal:

// src/activities/order-activities.ts
import type { ActivityContext } from '@temporalio/activity';

export async function chargePayment(
  paymentMethodId: string,
  amountCents: number
): Promise<string> {
  // This runs exactly once, even if the workflow is replayed 100 times
  const charge = await paymentService.charge(paymentMethodId, amountCents);
  return charge.id;
}

export async function decrementInventory(
  items: Array<{ sku: string; quantity: number }>
): Promise<void> {
  for (const item of items) {
    await inventoryService.decrement(item.sku, item.quantity);
  }
}

export async function sendOrderConfirmation(
  orderId: string,
  chargeId: string
): Promise<void> {
  await emailService.sendOrderConfirmation(orderId, chargeId);
}

export async function notifyWarehouse(
  orderId: string,
  items: Array<{ sku: string; quantity: number }>
): Promise<void> {
  await warehouseService.queueShipment(orderId, items);
}
// src/workflows/order-workflow.ts
import { proxyActivities, sleep } from '@temporalio/workflow';
import type * as activities from '../activities/order-activities';

// Create typed activity proxies — these run in the activity worker, not here
const {
  chargePayment,
  decrementInventory,
  sendOrderConfirmation,
  notifyWarehouse,
} = proxyActivities<typeof activities>({
  startToCloseTimeout: '30 seconds',
  retry: {
    maximumAttempts: 3,
    initialInterval: '1 second',
    backoffCoefficient: 2,
    maximumInterval: '10 seconds',
    // Do NOT retry if the charge was already processed (idempotency key)
    nonRetryableErrorTypes: ['PaymentAlreadyProcessedError'],
  },
});

export interface OrderInput {
  orderId: string;
  paymentMethodId: string;
  items: Array<{ sku: string; quantity: number; pricePerUnit: number }>;
}

export async function fulfillOrder(input: OrderInput): Promise<void> {
  const { orderId, paymentMethodId, items } = input;
  const totalCents = items.reduce(
    (sum, item) => sum + item.quantity * item.pricePerUnit,
    0
  );

  // Step 1: Charge — if this completes and the workflow crashes,
  // replaying the workflow will NOT re-execute this. chargeId is read from history.
  const chargeId = await chargePayment(paymentMethodId, totalCents);

  // Step 2: Decrement inventory
  await decrementInventory(items);

  // Step 3: Send confirmation email
  await sendOrderConfirmation(orderId, chargeId);

  // Step 4: Notify warehouse
  await notifyWarehouse(orderId, items);

  // Workflow completes. Every step ran exactly once.
}
// src/worker.ts
import { Worker } from '@temporalio/worker';
import * as activities from './activities/order-activities';

async function run() {
  const worker = await Worker.create({
    workflowsPath: require.resolve('./workflows/order-workflow'),
    activities,
    taskQueue: 'order-fulfillment',
  });

  await worker.run();
}

run().catch(console.error);

The workflow code reads like ordinary sequential code. There are no checkpoints, no idempotency checks, no retry logic scattered through the business logic. Temporal handles all of it. If the worker crashes after chargePayment completes but before decrementInventory runs, the next worker picks up the workflow, replays the history (which includes the ChargePayment result), and resumes at decrementInventory — without re-charging the customer.

sequenceDiagram participant W as Worker 1 participant T as Temporal Server participant DB as Event History participant A as Activity Worker W->>T: Poll for workflow task T-->>W: fulfillOrder workflow task W->>A: Schedule chargePayment activity A-->>T: ActivityCompleted: chargeId="ch_123" T->>DB: Append ActivityCompleted event Note over W: CRASH — Worker 1 dies here participant W2 as Worker 2 W2->>T: Poll for workflow task T-->>W2: fulfillOrder workflow task (with full history) W2->>DB: Read history: chargePayment already completed Note over W2: Replay: skip chargePayment, use ch_123 from history W2->>A: Schedule decrementInventory activity A-->>T: ActivityCompleted W2->>A: Schedule sendOrderConfirmation A-->>T: ActivityCompleted W2->>A: Schedule notifyWarehouse A-->>T: ActivityCompleted W2->>T: WorkflowCompleted ✓

Core Concepts Deep Dive

Workflows

A workflow in Temporal is a function that orchestrates activities. The function is durable: it can sleep for months, wait for signals, and survive any number of infrastructure failures. The key constraint is determinism — every time the workflow function is replayed, it must produce the same sequence of Temporal API calls given the same history. This means no Date.now() (use workflow.now()), no Math.random() (derive randomness from workflow ID), no direct I/O, and no side effects. Pure coordination logic only.

Activities

Activities are where all the real work happens. Calling an external API, writing to a database, sending an email — all go in activities. Activities are executed by activity workers on a task queue. They have configurable retry policies: how many times to retry, initial backoff interval, maximum interval, backoff coefficient, and which error types should not be retried. Activity results are recorded in the event history and are returned from history on replay — the actual function is never re-called.

Workers

Workers are long-running processes that poll Temporal's task queues. There are two types of workers in a Temporal deployment: workflow workers (which replay workflow code and make scheduling decisions) and activity workers (which execute the actual side-effecting work). In practice, most deployments use a single Worker.create() call that handles both workflow and activity tasks on the same task queue.

Signals

Signals let external systems send data to a running workflow. A running workflow can await a signal indefinitely — sleeping for hours or days until the signal arrives. This is how you model human-in-the-loop processes, long-polling, and asynchronous external triggers.

Here is a workflow that requires human approval before processing a large payout:

// src/workflows/payout-workflow.ts
import { defineSignal, setHandler, condition, proxyActivities } from '@temporalio/workflow';
import type * as activities from '../activities/payout-activities';

const { processPayout, sendRejectionNotification } = proxyActivities<typeof activities>({
  startToCloseTimeout: '30 seconds',
});

// Define the signal type and name
export const approvalSignal = defineSignal<[{ approved: boolean; reviewerEmail: string }]>(
  'approvalDecision'
);

export interface PayoutInput {
  userId: string;
  amountCents: number;
  requestedAt: string;
}

export async function processLargePayout(input: PayoutInput): Promise<string> {
  const { userId, amountCents } = input;

  let approvalDecision: { approved: boolean; reviewerEmail: string } | null = null;

  // Register the signal handler
  setHandler(approvalSignal, (decision) => {
    approvalDecision = decision;
  });

  // Notify the approval queue (activity)
  await sendApprovalRequest(userId, amountCents);

  // Wait for a signal, or time out after 72 hours
  const signalReceived = await condition(
    () => approvalDecision !== null,
    '72 hours'
  );

  if (!signalReceived || !approvalDecision?.approved) {
    // Timed out or rejected — notify user and stop
    await sendRejectionNotification(userId, 'Payout request expired or rejected');
    return 'rejected';
  }

  // Approved — process the payout
  const payoutId = await processPayout(userId, amountCents);
  return payoutId;
}

To send the approval signal from outside the workflow:

// From your backend API route when a reviewer clicks "Approve"
import { Client, Connection } from '@temporalio/client';
import { approvalSignal } from './workflows/payout-workflow';

const connection = await Connection.connect({ address: 'localhost:7233' });
const client = new Client({ connection });

const handle = client.workflow.getHandle('payout-workflow-user-456');
await handle.signal(approvalSignal, {
  approved: true,
  reviewerEmail: 'reviewer@company.com',
});

Queries

Queries let external systems read the current state of a running workflow without interrupting it. Unlike signals, queries are synchronous and read-only — they cannot change workflow state.

Child Workflows

Large workflows can be decomposed into child workflows. A parent workflow starts a child workflow and can optionally await its completion or fire-and-forget it. Child workflows are useful for parallelism (start N child workflows and Promise.all() them), for isolating failures to a subsection of a larger process, and for reusing complex workflow logic across multiple parent workflows.


Long-Running Business Process Pattern

One of Temporal's most powerful applications is long-running business processes that span days, weeks, or months. A subscription billing cycle is a classic example: every month, attempt to charge the customer. If the charge fails, retry with exponential backoff. Allow the subscription to be cancelled at any point, even mid-sleep.

// src/workflows/subscription-billing.ts
import {
  defineSignal,
  setHandler,
  condition,
  sleep,
  proxyActivities,
  log,
} from '@temporalio/workflow';
import type * as activities from '../activities/billing-activities';

const {
  chargeSubscription,
  sendPaymentFailureEmail,
  sendCancellationConfirmation,
  deactivateSubscription,
} = proxyActivities<typeof activities>({
  startToCloseTimeout: '30 seconds',
  retry: {
    maximumAttempts: 5,
    initialInterval: '2 seconds',
    backoffCoefficient: 2,
  },
});

// Signal to cancel the subscription mid-loop
export const cancelSubscriptionSignal = defineSignal('cancelSubscription');

export interface SubscriptionInput {
  userId: string;
  planId: string;
  paymentMethodId: string;
  billingCycleMonths: number; // How many months this subscription runs
}

export async function runSubscriptionBilling(input: SubscriptionInput): Promise<void> {
  const { userId, planId, paymentMethodId, billingCycleMonths } = input;

  let cancelled = false;
  let cycleCount = 0;

  // Register cancel signal handler
  setHandler(cancelSubscriptionSignal, () => {
    cancelled = true;
    log.info('Cancellation signal received', { userId, cycleCount });
  });

  // Run billing cycle for each month of the subscription
  while (cycleCount < billingCycleMonths && !cancelled) {
    log.info(`Starting billing cycle ${cycleCount + 1}/${billingCycleMonths}`, { userId });

    try {
      // Attempt the charge
      const chargeId = await chargeSubscription(userId, planId, paymentMethodId);
      log.info('Charge successful', { userId, chargeId, cycle: cycleCount + 1 });
    } catch (err) {
      // After all retries exhausted, notify user and deactivate
      log.error('All charge attempts failed', { userId, cycle: cycleCount + 1 });
      await sendPaymentFailureEmail(userId, cycleCount + 1);
      await deactivateSubscription(userId, 'payment_failure');
      return; // End the workflow
    }

    cycleCount++;

    if (cycleCount < billingCycleMonths && !cancelled) {
      // Sleep for 30 days before the next billing cycle
      // Temporal persists this sleep — no cron job, no database timer needed
      await sleep('30 days');
    }
  }

  if (cancelled) {
    log.info('Subscription cancelled by user', { userId, completedCycles: cycleCount });
    await sendCancellationConfirmation(userId);
    await deactivateSubscription(userId, 'user_cancelled');
  } else {
    log.info('Subscription completed all billing cycles', { userId, totalCycles: cycleCount });
  }
}

A few things to notice about this code:

await sleep('30 days') is not a blocking sleep. The worker process is not sitting idle for 30 days. When the workflow hits sleep, a timer event is scheduled in Temporal's backend, the workflow suspends (uses zero resources), and a new workflow task is created when the timer fires 30 days later. A new worker picks it up and resumes from after the sleep call.

The while loop is completely valid. Temporal replays the event history to reconstruct the loop's state. Each iteration's activity results are stored in history. Replay doesn't re-execute activities; it fast-forwards through them. The loop can span years.

The cancellation signal interrupts the sleep. If a user cancels during a 30-day sleep, the signal handler sets cancelled = true. Because condition is not being awaited here, the next time the workflow processes tasks it will see cancelled = true and exit the loop cleanly. If you wanted to wake the workflow immediately on cancellation, you'd use condition(() => cancelled, '30 days') instead of sleep.

gantt title Subscription Billing Workflow Timeline (12-month subscription) dateFormat YYYY-MM-DD axisFormat %b %Y section Cycle 1 Charge attempt :active, c1, 2026-01-01, 1d Sleep 30 days :sleep1, after c1, 30d section Cycle 2 Charge attempt :active, c2, after sleep1, 1d Sleep 30 days :sleep2, after c2, 30d section Cycle 3 Charge attempt :active, c3, after sleep2, 1d Sleep 30 days :sleep3, after c3, 30d section Cancel Signal (example) User cancels :milestone, cancel, 2026-03-25, 0d section Termination Cancellation email :done, ce, 2026-03-25, 1d Deactivate account :done, da, after ce, 1d

Temporal vs Alternatives

flowchart TD subgraph BullMQ["BullMQ / Celery (Redis-backed)"] B1[Job enqueued] --> B2[Worker executes] B2 --> B3{Crash?} B3 -->|Yes| B4[Retry from BEGINNING
⚠ Side effects re-execute] B3 -->|No| B5[Job complete] B4 --> B2 end subgraph StepFunctions["AWS Step Functions"] S1[State machine starts] --> S2[Execute Lambda step] S2 --> S3{Lambda fails?} S3 -->|Yes| S4[Retry Lambda
State persisted in AWS] S3 -->|No| S5[Next state] S4 --> S2 S5 --> S6[State machine complete] end subgraph TemporalFlow["Temporal"] T1[Workflow started] --> T2[Execute activity] T2 --> T3{Worker crashes?} T3 -->|Yes| T4[New worker replays history
✓ Completed activities skipped] T3 -->|No| T5[Next activity] T4 --> T5 T5 --> T6[Workflow complete] end
Temporal Celery / BullMQ AWS Step Functions Apache Airflow Conductor
Durability Exactly-once activity execution At-least-once (restarts from beginning) Step-level durability DAG-level checkpoints Step-level
Workflow-as-code Yes (TypeScript/Go/Python/Java) Python functions JSON/YAML state machine DSL Python DAGs JSON DSL
Long sleep (days/months) Native (sleep('30 days')) Requires external cron Via wait states (JSON) Not designed for this Via timers
Signals (external input) Native Not supported Via .waitForTaskToken External triggers Supported
Local dev Docker Compose Redis + Celery worker LocalStack Docker Compose Complex
Multi-language Yes (6 SDKs) Python-only Language-agnostic (Lambda) Python Java-primary
Vendor lock-in No (open source) No AWS-only No No
Used at Stripe, Netflix, Coinbase, Snap Shopify, Instagram AWS-native orgs Airbnb, Lyft, WB Netflix (legacy)
Self-hosted cost Infra + ops Redis only N/A (fully managed) Infra + ops High complexity
Cloud offering Temporal Cloud ($) No Fully managed Astronomer ($) Orkes ($)

The key differentiators are worth restating:

Celery/BullMQ retries failed jobs from the beginning. There is no checkpoint resumption within a job. For multi-step workflows with side effects, this means double execution is your problem to solve (idempotency keys on every external call). For many simple async tasks this is fine. For complex workflows with irreversible side effects, it's a fundamental limitation.

AWS Step Functions does provide step-level durability — a failed step is retried without re-running previous steps. The limitation is the DSL: your business logic lives in a JSON/YAML state machine definition, not in application code. Debugging complex flows is painful, the tooling is limited, and you're locked into AWS (though LocalStack helps with local development). Companies already deep in AWS and willing to accept JSON DSL often use it successfully.

Airflow is designed for batch data pipelines with dependencies — DAGs that run on a schedule. It's excellent at what it does. It's not designed for real-time event-driven workflows, sub-second latency, or workflows triggered by individual user actions. Using Airflow for an order fulfillment flow would be like using PostgreSQL as a message queue.

Temporal is the right tool when you need durable execution, code-native workflow definition, the ability to sleep for arbitrary durations without a cron job, and signal/query support for interactive workflows.

Architecture diagram showing a Temporal cluster with server, frontend, history, matching, and worker services, connecting to PostgreSQL for storage and workers over gRPC

Generated with Higgsfield GPT Image — 16:9


Local Setup

Getting Temporal running locally takes about five minutes with Docker Compose:

# docker-compose.yml
version: '3.8'
services:
  temporal:
    image: temporalio/auto-setup:1.24
    ports:
      - "7233:7233"    # Temporal gRPC frontend
    environment:
      - DB=sqlite      # In-memory SQLite for local dev (no Postgres needed)
    depends_on:
      - temporal-ui

  temporal-ui:
    image: temporalio/ui:2.26.2
    ports:
      - "8233:8080"    # Temporal Web UI
    environment:
      - TEMPORAL_ADDRESS=temporal:7233
      - TEMPORAL_CORS_ORIGINS=http://localhost:8233
docker compose up -d

The Temporal Web UI is now running at http://localhost:8233. You can see all running and completed workflows, inspect their event histories, search by workflow ID, signal workflows, and terminate stuck executions.

Install the TypeScript SDK:

npm install @temporalio/workflow @temporalio/activity @temporalio/worker @temporalio/client

Bootstrap a worker that processes the order fulfillment task queue:

// src/worker.ts
import { Worker, NativeConnection } from '@temporalio/worker';
import * as activities from './activities/order-activities';
import { Runtime, DefaultLogger } from '@temporalio/worker';

async function run() {
  // Connect to local Temporal server
  const connection = await NativeConnection.connect({
    address: 'localhost:7233',
  });

  const worker = await Worker.create({
    connection,
    namespace: 'default',
    taskQueue: 'order-fulfillment',
    workflowsPath: require.resolve('./workflows/order-workflow'),
    activities,
  });

  console.log('Worker started, polling task queue: order-fulfillment');
  await worker.run();
}

run().catch((err) => {
  console.error(err);
  process.exit(1);
});

Start a workflow from a client (e.g., an API handler):

// src/start-workflow.ts
import { Client, Connection } from '@temporalio/client';
import { fulfillOrder } from './workflows/order-workflow';

async function startOrderWorkflow() {
  const connection = await Connection.connect({ address: 'localhost:7233' });
  const client = new Client({ connection, namespace: 'default' });

  const handle = await client.workflow.start(fulfillOrder, {
    taskQueue: 'order-fulfillment',
    workflowId: `order-${Date.now()}`,
    args: [{
      orderId: 'ord_12345',
      paymentMethodId: 'pm_abc123',
      items: [
        { sku: 'WIDGET-001', quantity: 2, pricePerUnit: 2999 },
        { sku: 'GADGET-007', quantity: 1, pricePerUnit: 8999 },
      ],
    }],
  });

  console.log(`Workflow started: ${handle.workflowId}`);

  // Optionally wait for the result
  const result = await handle.result();
  console.log('Workflow completed:', result);
}

startOrderWorkflow().catch(console.error);

With the worker running and the workflow started, open http://localhost:8233 and navigate to the default namespace. You'll see the workflow appear, its current state, and the event history updating in real time as activities execute.


Production Considerations

Determinism Constraints

The most common source of bugs when starting with Temporal is violating determinism in workflow code. The key rules:

Never use Date.now() or new Date() in workflow code. Use workflow.now() instead:

import { now } from '@temporalio/workflow';
const currentTime = now(); // Deterministic — returns the same timestamp on replay

Never use Math.random() in workflow code. If you need randomness, derive it from the workflow ID:

const workflowInfo = workflowInfo(); // from @temporalio/workflow
// Use workflowId as a seed for deterministic pseudo-random values

Never import Node.js I/O modules (fs, net, http) into workflow code. All I/O belongs in activities.

Never use setTimeout or setInterval. Use sleep() from @temporalio/workflow.

If you violate determinism, Temporal detects it during replay (the workflow produces a different sequence of Temporal calls than the history records) and throws a NonDeterministicError, failing the workflow.

Versioning In-Flight Workflows

If you need to change workflow logic while workflows are already running, you cannot simply deploy new code — the replaying worker would produce different Temporal API calls than the history records, causing a NonDeterministicError. The solution is patched():

import { patched } from '@temporalio/workflow';

export async function fulfillOrder(input: OrderInput): Promise<void> {
  // Old behavior (still used for in-flight workflows that started before this deploy)
  if (!patched('add-loyalty-points')) {
    const chargeId = await chargePayment(input.paymentMethodId, total);
    await decrementInventory(input.items);
    await sendOrderConfirmation(input.orderId, chargeId);
    await notifyWarehouse(input.orderId, input.items);
    return;
  }

  // New behavior (used for all new workflows after this deploy)
  const chargeId = await chargePayment(input.paymentMethodId, total);
  await decrementInventory(input.items);
  await sendOrderConfirmation(input.orderId, chargeId);
  await notifyWarehouse(input.orderId, input.items);
  await addLoyaltyPoints(input.userId, calculateLoyaltyPoints(total)); // New step
}

Workflows that started before this deploy will use the old path. Workflows started after will use the new path. Once all old workflows have completed, you can remove the patched block and the old code.

Namespaces for Multi-Tenancy

Temporal namespaces provide isolation between environments (production, staging, development) and between different business domains (orders, payments, notifications). Create namespaces using the tctl CLI or the Temporal Web UI:

tctl --namespace production namespace register
tctl --namespace staging namespace register

Workers and clients specify the namespace they connect to. Workflows in one namespace are completely invisible to workers in another.

Temporal Cloud vs Self-Hosted

Temporal Cloud is the fully-managed offering. You pay per action (approximately $25/million workflow actions, with a free tier for development). The infrastructure, storage scaling, multi-region replication, and upgrades are handled for you. For most production use cases, Temporal Cloud is the right choice — the operational cost of running a highly-available Temporal cluster (with Cassandra or PostgreSQL, multiple Temporal service components, monitoring, and upgrades) is significant.

Self-hosted makes sense for compliance requirements that mandate on-premises data storage, for very high volume workloads where Cloud pricing becomes substantial, or for organizations with existing Kubernetes infrastructure and strong ops teams. Expect to dedicate meaningful engineering time to operations.


When NOT to Use Temporal

Temporal solves a specific class of problems. It is not the right tool for every background job:

Simple fire-and-forget async tasks. If you're sending a welcome email asynchronously and it's fine to retry from the beginning on failure, BullMQ or Celery is simpler and cheaper. Temporal adds operational complexity that isn't justified for trivial async work.

Pure event streaming. If you're processing a stream of events (Kafka, Kinesis) and each event is independent, Kafka consumer groups with dead-letter queues is the right architecture. Temporal workflows are not designed for high-throughput event stream processing.

Sub-second latency requirements. Temporal has scheduling overhead — typically 50–200ms from workflow start to first activity execution. For real-time applications where latency matters at the millisecond level, Temporal is not suitable. It's designed for workflows where correctness matters more than speed.

Small teams without operational capacity. If you're a two-person startup, the operational overhead of running Temporal (or the cost of Temporal Cloud) may not be justified compared to a well-implemented Celery setup with manual idempotency. Add Temporal when you've felt the pain of lost jobs enough times to justify the investment.

Comparison diagram showing BullMQ retry-from-start vs Step Functions state persistence vs Temporal exact-resume, illustrated as three different recovery paths after a crash

Generated with Higgsfield GPT Image — 16:9


Conclusion

Background jobs lying to you — completing step one of a multi-step workflow and then silently losing steps two through four — is one of the most insidious reliability problems in distributed systems. It's insidious because it doesn't throw an exception. The job system reports success. The database might have partial data. The user gets an error. You find out two days later when a customer emails support.

Temporal solves this at the architectural level, not through defensive coding. By recording every completed activity in a durable event history and replaying that history after crashes, Temporal gives you the guarantee that complex multi-step workflows run to completion exactly as written. You write sequential code. Temporal provides the durability.

The TypeScript SDK is mature, well-documented, and a pleasure to work with. Local development with Docker Compose takes minutes. The Web UI gives visibility into every running workflow that far exceeds what any log-based debugging provides. And the signal/query primitives unlock workflow patterns — human-in-the-loop approval flows, long-running subscription billing, waiting for external events — that are genuinely difficult to implement reliably with any other tool.

If you have workflows in production today where crashes cause partial execution and you're managing it with idempotency keys and manual reconciliation jobs, Temporal is worth the evaluation. Start with one workflow — the most painful one — and run it against the Temporal local server. The quality-of-life improvement is usually enough to make the adoption decision straightforward.


All code in this post uses @temporalio/workflow, @temporalio/activity, @temporalio/worker, and @temporalio/client v1.10+. The Temporal server Docker image is temporalio/auto-setup:1.24.

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-12 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter

Bigger Is Not the Same as Better. The Job That Moved Is the Phone, Not the Lab.

Bigger is a plan. The phone is the receipt. The brief for this cycle is a question: does bigger always mean better in AI? The 2026 answer i...