Generated with Higgsfield GPT Image — 16:9
Introduction
On March 14, 2024, a single malicious actor compromised a critical open-source dependency used by millions of Linux systems worldwide. The XZ Utils backdoor — embedded over two years of patient, methodical social engineering — was only discovered by accident when a Microsoft engineer noticed an unexpected performance regression in SSH logins. The backdoor had likely been in production SSH deployments for weeks before detection.
This is the threat landscape in 2026. Attacks are slower, more patient, more sophisticated, and more automated than ever before. The old mental model — attackers move fast, defenders need to move faster — no longer holds. The new model is: attackers move slowly and systematically, defenders need to watch everything, all the time, at scale.
AI is the only force multiplier that makes that equation work for defenders. A human SOC analyst can meaningfully process roughly 100-200 security alerts per shift. Modern enterprise environments generate tens of thousands. The math does not work without automation.
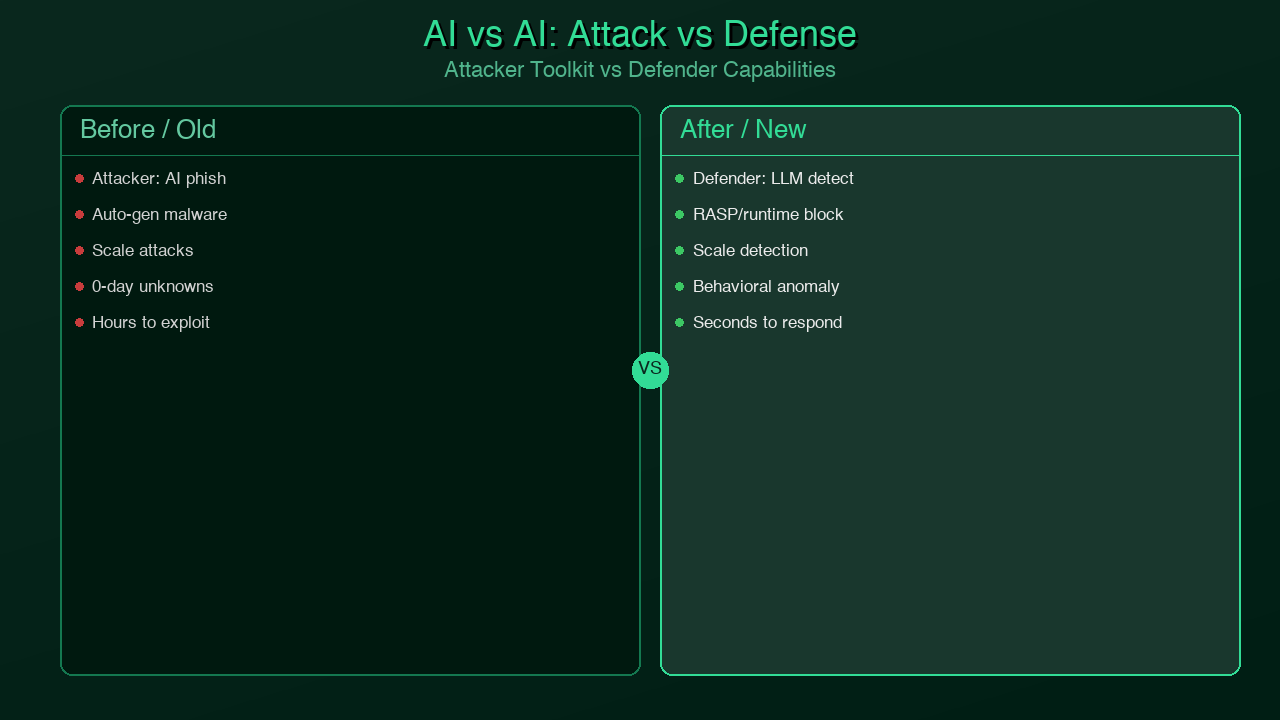
But the arms race cuts both ways. The same AI capabilities that enable defenders to detect threats faster enable attackers to discover vulnerabilities, craft phishing campaigns, and probe defenses at machine speed. In 2026, the cybersecurity contest is no longer human versus human — it is AI versus AI, with human judgment as the final arbiter.
This post covers how AI is reshaping every layer of cybersecurity: threat detection, vulnerability management, attack surface reduction, and incident response. It also covers how organizations can integrate AI security capabilities into their development pipelines today — and what to watch out for when the AI in your pipeline is also a potential attack vector.
Traditional Security is Losing
The numbers are brutal. Despite record investment in cybersecurity tools and talent, the defender side of the ledger shows consistent underperformance against a threat environment that keeps accelerating.
Alert fatigue has reached crisis levels. The average SOC analyst handles over 1,000 security alerts per day. Studies consistently find that 90% or more of these alerts are false positives — benign activity that pattern-matched a rule written years ago. Analysts develop alert blindness: they start processing alerts mechanically, approving dismissals at high speed to keep the queue manageable. The result is that genuine threats hide in the noise. When IBM's 2024 Cost of a Data Breach report found the average mean time to detect a breach had fallen to 194 days, it was tracking progress — but 194 days is still six months of an attacker living inside your environment.
Signature-based detection misses modern attacks. Traditional antivirus and intrusion detection systems work by matching against known-bad signatures: file hashes, domain names, IP addresses, known malware patterns. This approach is fundamentally reactive. It only catches attacks that have already been catalogued. Zero-day exploits, novel malware, and living-off-the-land attacks (where attackers use legitimate system tools like PowerShell or WMI) routinely evade signature-based defenses entirely.
The analyst shortage compounds everything. The global shortfall of cybersecurity professionals stood at 3.5 million unfilled roles in 2024. This number has barely moved in three years. Organizations cannot hire their way out of the detection problem. The tools must become smarter, not the teams bigger.
Compliance theater versus actual security. Many organizations have optimized their security programs for passing audits rather than resisting attacks. Ticking boxes on SOC 2 Type II does not protect against a sophisticated threat actor who has been patiently mapping your environment for six months. The compliance-first mindset creates a false sense of security precisely when the threat is most novel.
AI for Threat Detection
The most mature and impactful application of AI in cybersecurity today is behavioral threat detection — using machine learning to identify anomalous activity patterns that signature-based systems would miss entirely.
User and Entity Behavior Analytics (UEBA)
UEBA platforms establish baseline behavioral profiles for every user and system entity in an environment. What time does this user normally log in? From which IP ranges? How many files do they access per hour? Which systems do they authenticate to? When activity deviates significantly from baseline, the system flags it for investigation — not because it matched a known-bad signature, but because it is unusual for that specific entity.
This approach catches insider threats (where the attacker IS a legitimate user), compromised credential abuse (where an attacker authenticates with stolen credentials but behaves differently from the legitimate owner), and lateral movement (where an attacker who has compromised one system begins exploring others).
LLM-Assisted Log Analysis
The more recent development is using large language models to correlate and reason about security events across systems. Traditional SIEM correlation rules are brittle: they require human analysts to anticipate attack patterns in advance and encode them as queries. LLM-assisted analysis can read raw log data across multiple systems and identify narrative patterns — this user authenticated to the VPN from an unusual location, then immediately accessed the HR database, then exported a large CSV — that no single correlation rule would catch.
Microsoft Sentinel Copilot, CrowdStrike Charlotte AI, and SentinelOne Purple AI are the leading implementations of this approach in 2026. Each takes a slightly different form — some prioritize natural language querying of security data, others focus on automated investigation and playbook execution — but all share the core capability of helping analysts process more data, faster.
The Impact: MTTD Before and After AI
One of the most concrete measures of AI's impact in security is mean time to detect (MTTD). Traditional signature-based and manual approaches face an inherent bottleneck: alert volume grows faster than analyst capacity. AI-augmented detection inverts this relationship.
timeline
title Mean Time to Detect (MTTD) — Evolution of Security Detection
2018 : Signature-based SIEM only
: MTTD ~280 days
: High false positive rate (~95%)
2020 : UEBA added to SIEM stack
: MTTD ~220 days
: Behavioral baselines established
2022 : First-gen ML anomaly detection
: MTTD ~194 days (IBM Cost of Breach average)
: Automated triage for low-complexity alerts
2024 : LLM-assisted correlation + CrowdStrike Charlotte AI
: MTTD ~48 hours for well-instrumented orgs
: 70% reduction in analyst alert queue
2026 : AI-native SIEM + preemptive threat intel
: MTTD < 4 hours (elite orgs)
: Predictive attack path identification
A Practical Anomaly Detection Example
Here is a working Python implementation of login anomaly detection using Isolation Forest — the same general approach used in production UEBA systems, simplified for illustration:
from sklearn.ensemble import IsolationForest
from sklearn.preprocessing import StandardScaler
import pandas as pd
import numpy as np
from datetime import datetime
from typing import Tuple

def engineer_login_features(df: pd.DataFrame) -> pd.DataFrame:
    """
    Transform raw login event data into ML-ready features.

    Expected columns in df:
        - timestamp: datetime of login attempt
        - user_id: identifier of the user
        - source_ip: IP address used
        - success: bool, whether login succeeded
        - failed_attempts_before: int, consecutive failures before this event
        - is_new_ip: bool, IP not seen for this user in last 30 days
        - geo_distance_km: float, km from user's most common login location
        - device_fingerprint: string, hashed browser/device fingerprint
    """
    df = df.copy()

    # Extract time-based features
    df['hour'] = pd.to_datetime(df['timestamp']).dt.hour
    df['day_of_week'] = pd.to_datetime(df['timestamp']).dt.dayofweek
    df['is_weekend'] = (df['day_of_week'] >= 5).astype(int)
    df['is_off_hours'] = ((df['hour'] < 7) | (df['hour'] > 20)).astype(int)

    # Binary flags to numeric
    df['new_ip'] = df['is_new_ip'].astype(int)
    df['new_device'] = (df['device_fingerprint'] == 'unknown').astype(int)

    return df


def detect_anomalous_logins(
    login_events: pd.DataFrame,
    contamination: float = 0.05,
    threshold_score: float = -0.3
) -> Tuple[pd.DataFrame, pd.DataFrame]:
    """
    Flag anomalous login patterns using Isolation Forest.

    Isolation Forest works by randomly partitioning the feature space.
    Anomalous points — those that are isolated quickly by random splits —
    receive lower (more negative) anomaly scores.

    Args:
        login_events: DataFrame of login events with engineered features
        contamination: Expected proportion of anomalies (0.05 = 5%)
        threshold_score: Score cutoff for flagging (lower = more anomalous)

    Returns:
        Tuple of (all_events_with_scores, flagged_anomalies)
    """
    df = engineer_login_features(login_events)

    feature_cols = [
        'hour', 'is_off_hours', 'is_weekend',
        'failed_attempts_before', 'new_ip', 'new_device',
        'geo_distance_km'
    ]

    # Normalize features to equal scale
    scaler = StandardScaler()
    X = scaler.fit_transform(df[feature_cols].fillna(0))

    # Train Isolation Forest
    model = IsolationForest(
        n_estimators=200,
        contamination=contamination,
        max_samples='auto',
        random_state=42,
        n_jobs=-1
    )

    # score_samples returns negative scores: closer to 0 = more normal
    df['raw_anomaly_score'] = model.fit_predict(X)
    df['anomaly_score'] = model.score_samples(X)
    df['is_anomaly'] = (df['raw_anomaly_score'] == -1)

    # Calculate risk level for flagged events
    flagged = df[df['is_anomaly']].copy()
    flagged['risk_level'] = pd.cut(
        flagged['anomaly_score'],
        bins=[-np.inf, -0.6, -0.45, -0.3, 0],
        labels=['critical', 'high', 'medium', 'low']
    )

    # Sort by anomaly score (most anomalous first)
    flagged = flagged.sort_values('anomaly_score')

    return df, flagged


def summarize_anomalies(flagged: pd.DataFrame) -> dict:
    """Generate a summary report of detected anomalies for SOC analyst review."""
    if flagged.empty:
        return {"total_flagged": 0, "risk_breakdown": {}, "top_users": []}

    return {
        "total_flagged": len(flagged),
        "risk_breakdown": flagged['risk_level'].value_counts().to_dict(),
        "top_affected_users": (
            flagged.groupby('user_id')
            .size()
            .sort_values(ascending=False)
            .head(10)
            .to_dict()
        ),
        "off_hours_percentage": (
            flagged['is_off_hours'].sum() / len(flagged) * 100
        ),
        "new_ip_percentage": (
            flagged['new_ip'].sum() / len(flagged) * 100
        ),
    }
Production UEBA systems apply this same principle across billions of events per day, with continuous model retraining to adapt to legitimate behavioral drift (a developer who moves to a new city, a sales rep who starts traveling internationally). The key advantage over rule-based detection: the model finds anomalies the analyst never anticipated.
AI for Vulnerability Management
The second major frontier for AI in security is vulnerability discovery and remediation. The traditional vulnerability management lifecycle — scan, triage, prioritize, patch, verify — is slow, manual-intensive, and inherently reactive. AI is accelerating every stage.
AI-Powered Static Analysis
AI-enhanced SAST tools go far beyond pattern matching on known vulnerability signatures. Tools like Snyk DeepCode AI, GitHub Copilot Autofix, and Semgrep Assistant use large language models to understand code semantics — what a function actually does, how data flows through a codebase, whether user input can reach a dangerous sink — rather than matching surface-level patterns.
The practical result: significantly lower false positive rates and the ability to detect vulnerability classes that require multi-step reasoning to identify. A SQL injection via a chain of three function calls, where none of the individual calls looks suspicious, is difficult for pattern-based tools but tractable for semantic analysis.
GitHub Copilot Autofix goes one step further: when it identifies a vulnerability, it generates a fix and opens a pull request. The developer reviews and approves; the machine does the mechanical repair work. For high-volume, well-understood vulnerabilities (dependency version bumps, known SQL injection patterns, XSS in template rendering), autofix is ready for production use. For novel or business-logic vulnerabilities, it still requires human review — and that is appropriate.
AI-Assisted CVE Understanding
The National Vulnerability Database logs thousands of CVEs per year. Security teams cannot read and manually triage all of them. AI tools that translate CVE descriptions from technical jargon into plain-English impact assessments — "this vulnerability lets an unauthenticated attacker execute arbitrary code on your Redis instance if it is exposed to the internet" — dramatically accelerate triage.
Automatic Patch Generation
Research teams at Google (Project Zero), Microsoft, and several universities have demonstrated LLMs generating patches for known CVEs with high accuracy for narrow vulnerability classes. This capability is not yet production-standard for arbitrary vulnerabilities, but for well-understood classes (buffer overflows in C, prototype pollution in JavaScript, SSRF via unvalidated URLs), patch-generation AI is becoming a practical tool.
The key risk to understand: over-relying on AI for security code review creates a false sense of coverage. AI tools miss vulnerabilities — especially novel ones, business-logic flaws, and subtle authentication bypass issues. They should augment human review, never replace it.
The Attacker's AI Toolkit
Understanding AI-powered defense requires understanding AI-powered offense. The same capabilities that accelerate threat detection also accelerate threat creation.
FraudGPT and WormGPT — jailbroken or fine-tuned LLMs sold on dark web forums — lower the skill floor for social engineering attacks. A beginner phisher can now generate grammatically perfect, psychologically tailored spear-phishing emails at scale. The era of "just look for bad grammar in phishing emails" is definitively over.
AI-accelerated vulnerability scanning means that the window between a CVE being published and active exploitation has collapsed from weeks to hours or days. Automated systems continuously scrape vulnerability databases, map CVEs to production systems via internet scanning (using tools like Shodan and Censys as inputs), and generate working exploits. Organizations that patch on a monthly cycle are now perpetually behind.
Deepfake audio and video have matured to the point where voice cloning from a 15-second sample is commercially available. Business email compromise attacks, already the highest-dollar-value category of cybercrime, are evolving into business voice compromise — attackers calling employees and impersonating executives or vendors with cloned voices.
AI-assisted zero-day discovery is perhaps the most concerning long-term development. LLMs combined with fuzzing frameworks can automate the process of exploring codebases for novel vulnerability classes. The economics of zero-day discovery, historically a domain of well-funded nation-states, are becoming more accessible.
Defenders cannot prevent attackers from having these tools. What they can do is ensure their defenses are equally AI-augmented — responding at machine speed, with AI-assisted analysis, rather than human speed with manual triage.
The current AI capability gap between attackers and defenders varies significantly by capability area:
quadrantChart
title AI Capability Maturity — Attackers vs Defenders (2026)
x-axis Attacker Maturity --> Defender Maturity
y-axis Low Impact --> High Impact
Spear Phishing Generation: [0.85, 0.75]
Vulnerability Scanning: [0.90, 0.70]
Zero-Day Discovery: [0.65, 0.30]
Deepfake Social Engineering: [0.80, 0.25]
Malware Obfuscation: [0.75, 0.60]
Behavioral Anomaly Detection: [0.40, 0.85]
Automated Patch Generation: [0.55, 0.70]
Incident Correlation: [0.50, 0.80]
Threat Intelligence: [0.60, 0.75]
Code Vulnerability Analysis: [0.70, 0.78]
Generated with Higgsfield GPT Image — 16:9
Building AI-Augmented Security Pipelines
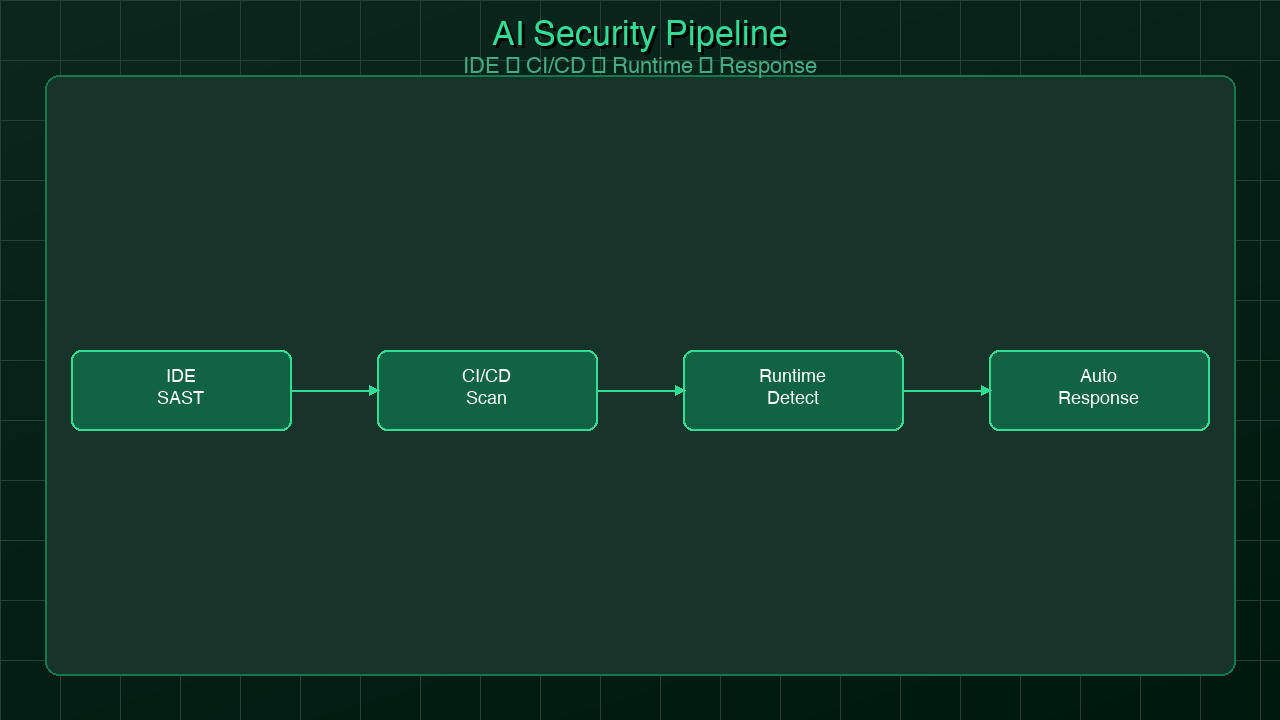
The most actionable thing a software organization can do right now is integrate AI security scanning throughout the development lifecycle, not just at the perimeter. This is the shift-left security model, accelerated by AI.
Generated with Higgsfield GPT Image — 16:9
flowchart LR
subgraph DEV["Developer Environment"]
IDE[IDE\nReal-time AI SAST\nCopilot Autofix\nSnyk IDE plugin]
end
subgraph PR["Pull Request / CI Gate"]
SAST[AI SAST Scan\nSemgrep / CodeQL\nDeepCode AI]
SCA[SCA Scan\nDependency vulns\nSnyk / Dependabot]
SECRETS[Secrets Detection\nGitGuardian / TruffleHog]
CONTAINER[Container Scan\nTrivy / Grype]
GATE{Severity Gate\nBlock on Critical/High?}
SAST --> GATE
SCA --> GATE
SECRETS --> GATE
CONTAINER --> GATE
end
subgraph DEPLOY["Deployment"]
DAST[AI DAST\nBurp Suite / OWASP ZAP\nagainst staging env]
IAC[IaC Scan\nCheckov / Terrascan\nTerraform misconfigs]
end
subgraph RUNTIME["Production Runtime"]
RASP[RASP / WAF\nRuntime protection\nCloudflare / AWS WAF]
UEBA[AI Anomaly Detection\nUser behavior analysis\nNetwork flow anomalies]
SIEM[AI-Augmented SIEM\nMicrosoft Sentinel\nCrowdStrike / Splunk AI]
end
subgraph RESPONSE["Incident Response"]
AUTO[Automated Playbooks\nAI-assisted triage\nAuto-quarantine]
ANALYST[Human Analyst\nAI-summarized context\nDecision support]
end
DEV -->|Code pushed| PR
GATE -->|Pass| DEPLOY
GATE -->|Fail - block PR| DEV
DEPLOY -->|Deployed| RUNTIME
RUNTIME -->|Alerts| RESPONSE
RESPONSE -->|Lessons learned| DEV
style DEV fill:#e8f5e9,stroke:#2e7d32
style PR fill:#fff3e0,stroke:#f57c00
style DEPLOY fill:#e3f2fd,stroke:#1565c0
style RUNTIME fill:#fce4ec,stroke:#c62828
style RESPONSE fill:#f3e5f5,stroke:#6a1b9a
Stage 1: IDE (Shift Left)
AI security scanning starts in the developer's editor. Snyk's IDE plugin, GitHub Advanced Security, and SonarLint with AI explanation all provide real-time feedback as code is written. When a developer introduces a SQL query that concatenates user input, they see the warning immediately — not after a CI scan 20 minutes later.
This stage catches the highest-value issues: vulnerabilities introduced by the developer in the current working session, before they are even committed.
Stage 2: Pull Request Gate
Every pull request should run a battery of automated security checks before merge. The AI-augmented stack includes:
- SAST (Static Analysis): CodeQL, Semgrep, or Snyk Code scan the diff for vulnerability patterns, with AI-generated explanations of findings
- SCA (Software Composition Analysis): Snyk, Dependabot, or OWASP Dependency Check scan for known vulnerable dependencies
- Secret Detection: GitGuardian or TruffleHog scan for accidentally committed API keys, passwords, or certificates
- Container Scanning: Trivy or Grype scan the container image produced by the PR build
The gate decision — block the PR or warn — should be calibrated to your organization's risk tolerance. Critical severity findings should typically block; medium and low can be warnings with required acknowledgment.
Stage 3: Dynamic Testing in Staging
DAST tools test running applications for vulnerabilities that static analysis cannot find: authentication bypasses, business logic flaws, API access control issues, and XSS in rendered HTML. Modern DAST tools like Burp Suite Enterprise and OWASP ZAP with ML extensions are beginning to use AI to intelligently guide test cases rather than brute-forcing all inputs.
Stage 4: Runtime Protection and Monitoring
The production runtime layer combines several capabilities:
- WAF/RASP: Block known attack patterns at the edge (Cloudflare WAF, AWS WAF) and within the application runtime
- UEBA: AI behavioral analysis of user and system activity (as described in the threat detection section above)
- AI-augmented SIEM: Microsoft Sentinel Copilot, CrowdStrike Charlotte AI, or Splunk AI for correlated analysis of security events across all systems
Stage 5: AI-Assisted Incident Response
When an alert fires, the AI's job is to give the analyst everything they need to make a decision — fast. AI-assisted response tools automatically gather context (what other events correlate with this alert? what is the blast radius if this is real?), generate natural language incident summaries, and execute pre-approved playbooks (isolate the affected endpoint, revoke the compromised credential, notify the owner team) without requiring manual steps for low-risk, high-confidence responses.
LLM-Specific Security Risks
As AI systems become part of production software infrastructure, they introduce a new category of security risks that traditional security frameworks were not designed to handle.
Prompt Injection is the LLM equivalent of SQL injection. An attacker embeds malicious instructions in data that the LLM processes — a document, an email, a web page, a user-supplied field — and the LLM executes those instructions rather than its legitimate task. A customer service LLM that summarizes incoming emails can be hijacked to exfiltrate customer data, send unauthorized messages, or escalate its own permissions if the system does not properly separate trusted instructions from untrusted content.
Training Data Poisoning targets LLMs during training. By injecting malicious examples into training data — a possibility whenever models are fine-tuned on web-scraped or user-generated content — attackers can create backdoors that activate on specific trigger phrases or cause systematic biases in model behavior.
Model Exfiltration involves reconstructing training data or model weights through carefully crafted queries. Proprietary models trained on internal data can leak sensitive information through their outputs.
OWASP Top 10 for LLMs (2025 edition) provides the most comprehensive framework for these risks. The top categories are: prompt injection, insecure output handling, training data poisoning, model denial of service, supply chain vulnerabilities, sensitive information disclosure, insecure plugin design, excessive agency, overreliance, and model theft.
Defense patterns for LLM systems include:
- Input sanitization: Validate and sanitize all user inputs before passing to the LLM. Define what the model is allowed to do and enforce it structurally
- Output validation: Treat LLM output as untrusted data. Validate, sanitize, and constrain it before acting on it
- Sandboxing: Give LLM agents the minimum permissions needed. Do not give an LLM that summarizes documents the ability to send emails
- Human-in-the-loop: For high-stakes decisions, require human approval even when the LLM is confident
- Audit logging: Log all LLM inputs and outputs for forensic analysis
What Security Teams Should Do Now
The AI security landscape is moving fast. Organizations that wait for the technology to stabilize before acting will be meaningfully behind in both tooling and defensive capability. These are the concrete steps security teams should take in the next 90 days.
Evaluate one AI-powered security tool. Pick the layer where your team feels the most pain — SIEM alert overload, vulnerability triage, code review burden — and evaluate one AI-augmented product in that space. CrowdStrike Falcon with Charlotte AI, Wiz for cloud security posture, Snyk Code for developer security, and Microsoft Sentinel Copilot are all production-ready. Most offer a trial period. Run a 30-day evaluation with real data and measure impact.
Train your analysts on prompt engineering for security queries. The ability to query your SIEM or EDR using natural language — "show me all events where a user authenticated from a new country and then accessed a sensitive database within 30 minutes" — is powerful. But it requires knowing how to ask. Prompt engineering is a skill, and security analysts who develop it will be 2-3x more effective with AI-augmented tools.
Run a purple team exercise with AI tools on both sides. Use AI-assisted attack simulation (tools like AttackIQ, Vectra, or a GPT-assisted red team) to probe your defenses while your defenders use AI-augmented detection to find the activity. The exercise will reveal detection gaps and help your team understand how AI changes the attack-defense calculus in your specific environment.
Build AI security scanning into your CI/CD pipeline. If you only do one thing, do this: add Snyk, Semgrep, or CodeQL to every pull request. Configure it to block on critical-severity findings. The investment is a few hours of setup; the payoff is catching high-severity vulnerabilities before they reach production.
Do not replace humans — augment them. The consistent finding from organizations that have deployed AI security tools is that the technology raises the floor of defensive capability and frees human analysts for the work that actually requires judgment. The human security analyst is not being replaced; they are being equipped with tools that make them dramatically more effective. The organizations that treat AI as a replacement for human security expertise will discover that AI tools, like all tools, have failure modes that only humans can catch.
Conclusion
The cybersecurity contest of 2026 is an AI arms race. Attackers have AI tools that automate vulnerability discovery, craft targeted phishing at scale, and probe defenses continuously. Defenders have AI tools that correlate security events across millions of data points, detect behavioral anomalies that humans would miss, and explain complex security situations in plain language.
The key insight is that AI does not resolve the fundamental asymmetry between attackers and defenders — attackers only need to succeed once, defenders need to succeed every time. What AI does is change the economics of defense. A well-instrumented, AI-augmented security program can achieve coverage that previously required teams ten times larger. For organizations that cannot hire enough security engineers, that is transformative.
The pipeline model described in this post — AI security scanning from IDE to production runtime — is achievable for any software organization with existing DevOps practices. Start with CI integration. Add runtime behavioral monitoring. Build towards AI-assisted incident response. Each layer compounds the defensive capability of the previous one.
The organizations that will be best positioned in three years are not those who wait for a single AI security product to solve everything. They are the ones building security deeply into their development culture — treating security as an engineering problem, using AI to scale their defenses, and keeping humans in the loop where judgment matters.
The attack surface will keep growing. The AI capabilities on both sides will keep improving. The only sustainable advantage is building security into everything, from the first line of code to the last production event.
Related reading: Platform Engineering and Developer Security — how platform teams build security into the golden path by default.