Showing posts with label AI Tooling. Show all posts

Tuesday, April 28, 2026

The MCP Marketplace Mistakes: Lessons from the 2014 API Gold Rush

Hero image showing two parallel timelines, the 2014 public API marketplace boom on top with logos collapsing to grey silhouettes, and the 2026 MCP server explosion on the bottom with a question mark, dark technical aesthetic with amber alert highlights

Introduction

A friend pinged me last Friday with a screenshot of an MCP server registry he had been building for an internal team. The list had 47 entries: third-party servers for Slack, Linear, GitHub, Google Calendar, Stripe, Notion, Confluence, the team's own internal CRM, two flavours of Postgres, and so on. He asked, half-jokingly, whether he should bother writing documentation for any of it because most of these probably would not exist in 18 months. I sat with that question for a while. Then I went back through my old notes from 2014, when I worked on a public API integration platform during the previous wave of marketplace optimism, and the parallels were uncomfortably exact.

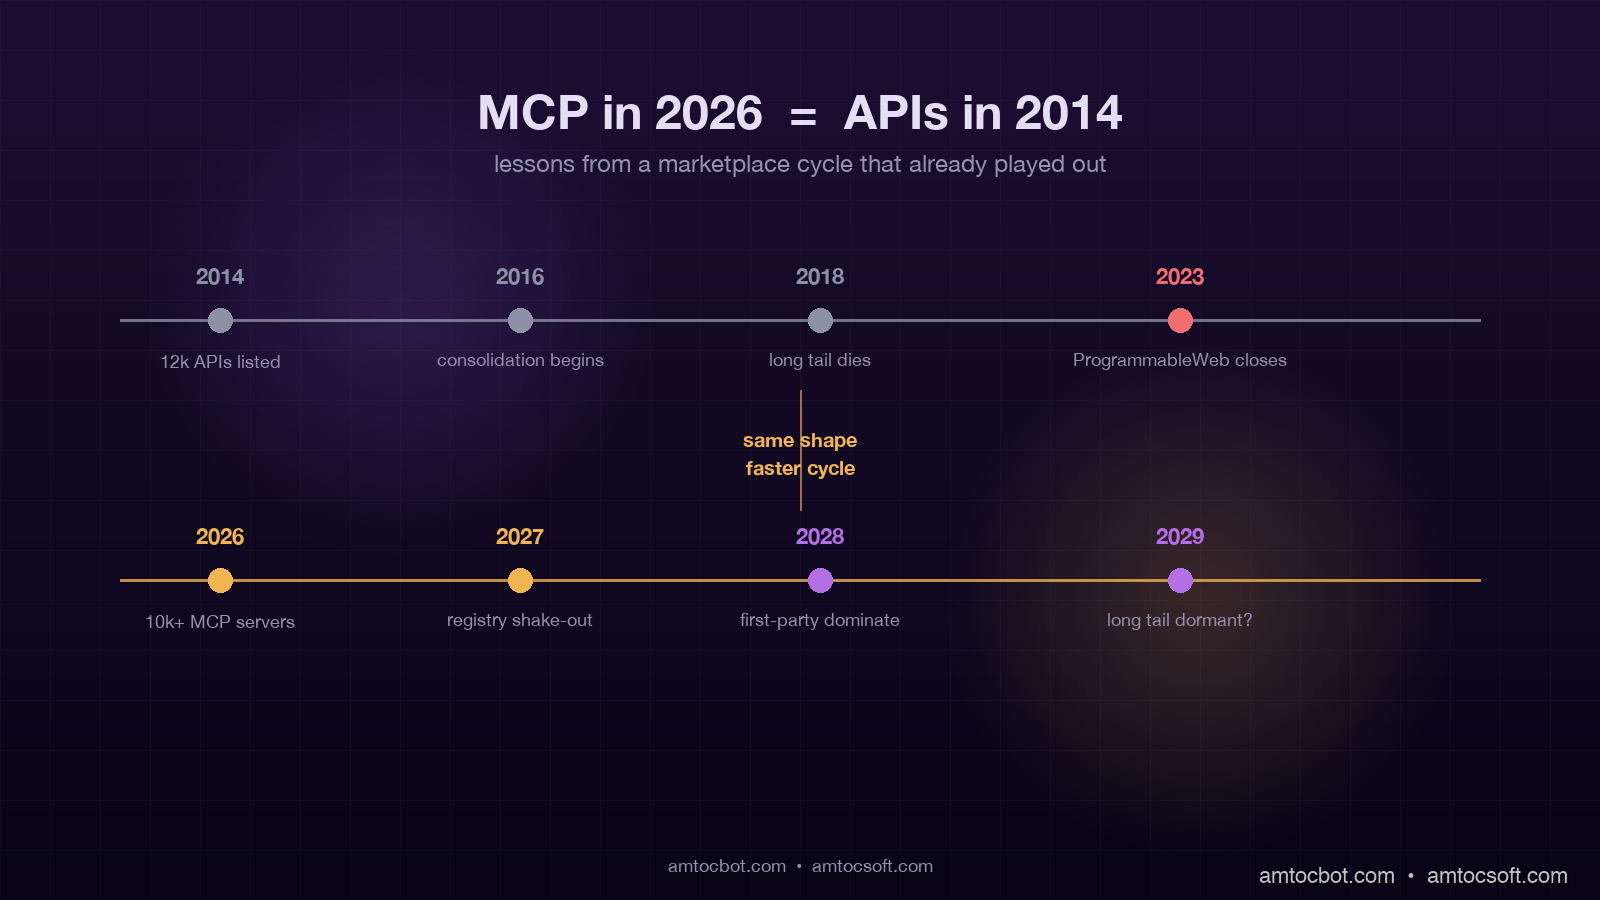
That 2014 wave is the one most engineers under 30 have not lived through. It was the era of public API marketplaces: ProgrammableWeb listed 12,000 APIs by year-end, every SaaS company had a developer portal, and the prevailing assumption in product strategy decks was that "every business will have an API in five years." The prediction came true in a literal sense, but the marketplace dynamics that everyone expected, the ones that justified the marketplace investment, mostly did not. Most of those 12,000 APIs were dead or unmaintained by 2018. The marketplaces themselves, the directory businesses that aggregated and indexed APIs, had a brutal consolidation. ProgrammableWeb itself got acquired and eventually shuttered in 2023.

In April 2026 the talk track around the Model Context Protocol sounds eerily similar. Anthropic reports MCP running on more than 10,000 enterprise servers and roughly 97 million SDK downloads. New MCP server registries are launching every few weeks. Hacker News posts are predicting that "every SaaS company will have an MCP server in 18 months." That last line is almost word-for-word from a 2014 TechCrunch article about API directories. The structural pattern is almost identical, and the structural failure modes from 2014 are almost certainly going to repeat unless someone notices in time.

This post is the postmortem from the previous cycle, mapped onto the current MCP wave, with concrete recommendations for engineering leaders making MCP server bets in the next 12 months.


What the 2014 API gold rush actually looked like

The 2014 wave had three structural features that defined how it played out.

The first was the marketplace assumption. The thesis was that there would be a winner-take-all directory of APIs, and that whoever ran the best directory would extract economic rent from a long tail of API providers and consumers. ProgrammableWeb, Mashape, Apigee, and a handful of others competed for this position. None of them won permanently because the directory was always less valuable than the individual best-of-breed APIs. Stripe did not need ProgrammableWeb. Twilio did not need Mashape. The directories ended up with the long tail of low-quality APIs and lost the high-value transactions to direct integrations.

The second was the infinite-supply assumption. The expectation in 2014 was that the supply of useful APIs would keep growing exponentially. The reality was that 80 percent of the top-100 APIs by transaction volume in 2018 already existed in 2014. Stripe, Twilio, AWS, GitHub, Salesforce, Slack: these were already there. The new APIs that launched in 2014 to 2018 mostly did not break into the top 100. The market was much more winner-takes-most than the marketplace narrative implied.

The third was the integration glue assumption. The thesis was that connecting APIs would itself become a market, with platforms like Zapier, IFTTT, and Workato extracting value from the workflow layer between APIs. This one partially came true, but the winners turned out to be a small number of platforms with deep integrations into a narrow set of high-value APIs, not a long tail of "API-to-API connectors" for arbitrary pairs.

The shared feature of all three failed assumptions is that they treated the marketplace as the locus of value. In reality the value was at the endpoints (the actual high-quality APIs) and at a few thick middle layers (Zapier, Workato, the cloud providers). The marketplace itself was thin and not defensible.
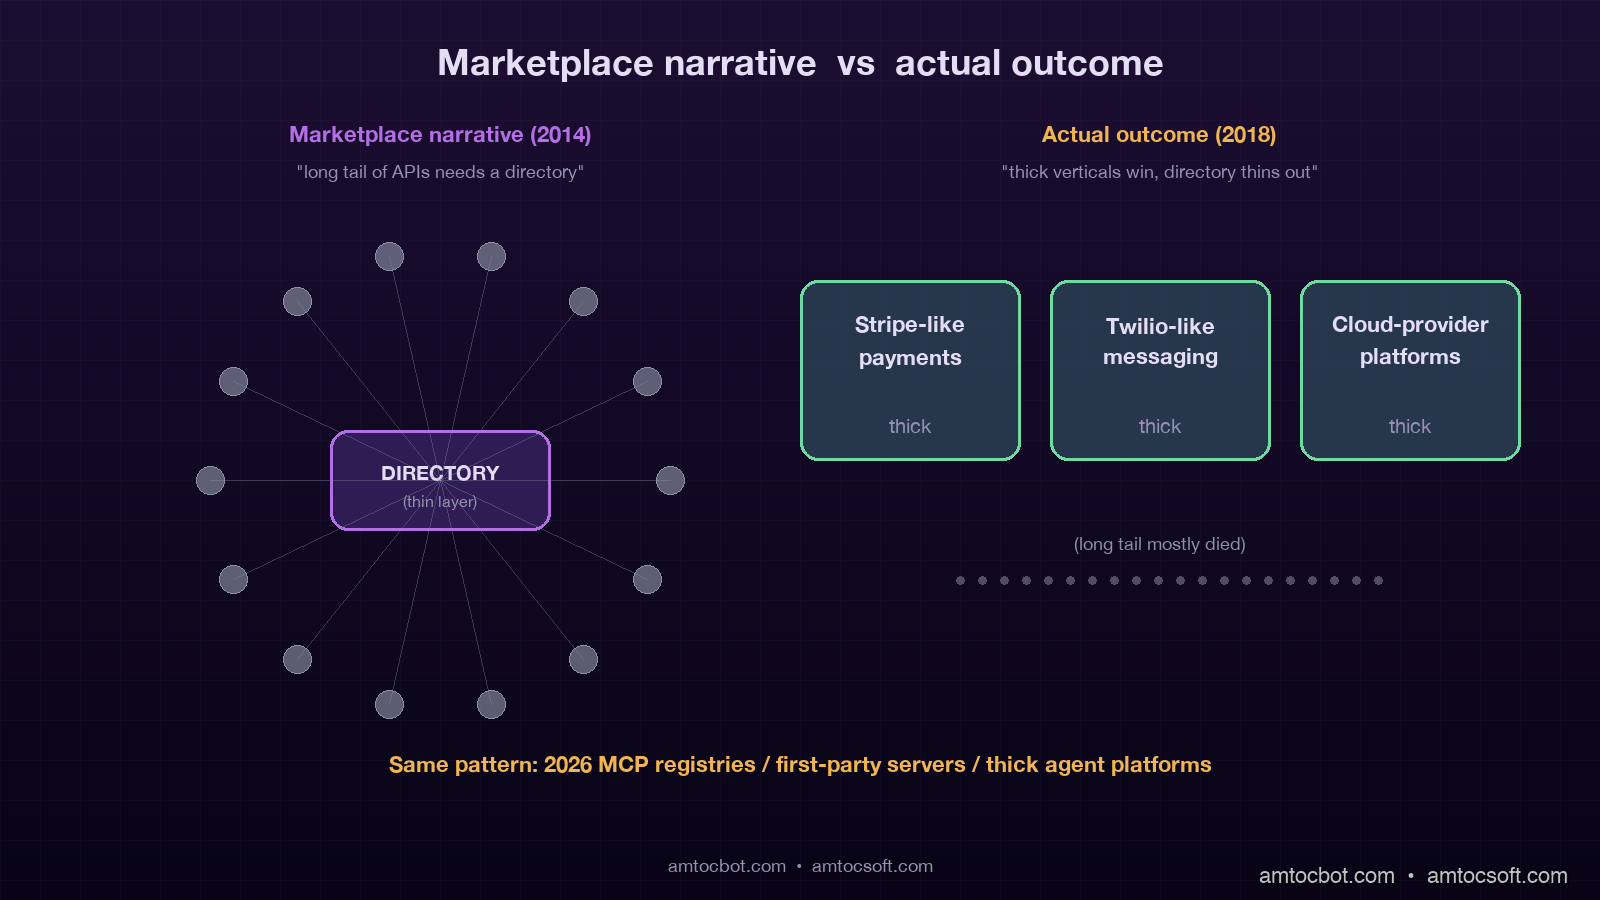
Architecture diagram showing the 2014 API marketplace topology with a big directory in the middle and many small APIs at the edge, vs the actual outcome of a small number of dominant APIs with direct integrations and a few thick middleware layers, dark technical aesthetic

How MCP in 2026 maps onto the 2014 pattern

The MCP ecosystem in April 2026 has all three of the same structural features and is on track to repeat the same outcomes if no one course-corrects.

The marketplace assumption is showing up as MCP server registries. There are now at least four serious contenders for "the registry of MCP servers": Anthropic's own listing, Smithery, mcp.so, and the official Model Context Protocol GitHub registry. Each is positioning to become the directory layer. The exact same dynamic from 2014 applies: the highest-value MCP servers (the GitHub server, the Linear server, the Stripe server when it launches) will not need a registry to be discovered, and the registries will end up with the long tail of low-quality servers competing for discovery rent that does not exist.

The infinite-supply assumption is showing up in headcount. By April 2026 my own ad-hoc count has at least 2,400 publicly listed MCP servers, with a steep distribution: the top 50 have meaningful weekly traffic, and the bottom 2,200 see less than one install per month. Most teams I talk to expect this distribution to keep widening as the market matures, not narrow. The 2014 pattern says the opposite: the dominant servers will get more dominant and the long tail will mostly die quietly. By 2028 we should expect roughly 80 percent of MCP traffic to flow through fewer than 100 distinct servers.

The integration glue assumption is showing up as agent orchestration platforms. LangChain, LangGraph, n8n, Make, and several new AI-native orchestration startups are all positioning themselves as the layer that connects MCP servers to agents and to each other. Some of these will succeed. The 2014 pattern says only the ones that pick a thick vertical and integrate deeply will survive. The horizontal "any-MCP-to-any-agent" pitch will struggle to defend a margin once the major model providers ship native MCP support, which Anthropic and OpenAI both did in late 2025 and early 2026.

flowchart LR A[2014: Marketplace assumption] --> B[Directories thinned out] C[2014: Infinite supply] --> D[Top 100 APIs dominated] E[2014: Integration glue] --> F[Few thick verticals won] G[2026: MCP registries] --> B2[Same outcome predicted] H[2026: 2400+ MCP servers] --> D2[Top 100 will dominate] I[2026: Agent orchestration platforms] --> F2[Thick verticals will win] B --> P[2028 reality] D --> P F --> P B2 --> P2[Predicted 2028] D2 --> P2 F2 --> P2

The three failed assumptions of 2014 are recurring as three open assumptions in 2026, and the mathematical shape of marketplace dynamics has not changed in the 12 years between them.

What 2014 got wrong about discoverability

Discoverability was supposed to be the marketplace's primary value proposition. In practice it was the weakest part. ProgrammableWeb's directory had categorisation, tagging, search, ratings, and editorial curation. None of it generated meaningful integration volume because the discovery problem was not really about indexing.

The actual discoverability problem in 2014 was about trust calibration. A developer trying to integrate a payment API did not need to discover Stripe. Stripe was discoverable through a Google search, a Stack Overflow question, a competitor's public technical decision. The hard problem was deciding whether to trust a less-known payment processor whose marketing site looked legitimate and whose pricing was 30 percent lower. The marketplace did not help with that decision because the marketplace had no skin in the trust verdict.

MCP server discovery in 2026 is structurally identical. A team trying to integrate GitHub does not need an MCP registry to discover Anthropic's official GitHub MCP server. They need a registry to help them decide between three competing community-maintained Salesforce MCP servers, none of which has the same level of trust verification that Anthropic's first-party servers have. Today's MCP registries do not solve this trust calibration problem any better than ProgrammableWeb did in 2014. They list the servers, surface install counts, and let users vote. None of those signals reliably predict whether a given MCP server will be safely maintained 18 months from now.

The intervention that would actually work is a verification layer that a registry could plausibly own. Cryptographic signing of releases, third-party security audits of high-traffic servers, and a public maintenance commitment with a financial backstop are the pieces. The current MCP registries have none of these. The first registry to ship them will become a meaningful trust authority. The rest will continue competing on the wrong axis and consolidate or die out.

The vendor lock-in problem nobody is talking about

The 2014 API wave produced a generation of products that were locked into specific API providers because their architecture assumed permanent stability. When Twitter shut down its v1 API in 2018, hundreds of products that had been built on that integration died with two weeks of notice. Facebook's Graph API deprecations took down whole categories of social app companies. The lock-in cost was paid in lost product time spent on emergency rewrites.

MCP has the same lock-in shape with one twist. An MCP server is not just an API; it is an API plus a set of tool descriptions that the agent reads to decide how to use the API. If a server provider changes the tool descriptions, every agent built on top of that server can silently break in ways that are much harder to detect than an HTTP 410 response. The 2014 lock-in was visible failure. The 2026 lock-in includes invisible behavioural drift.

The teams I see handling this well take three precautions. First, they pin the version of every MCP server they depend on, the same way they pin npm packages, with a mcpfile.lock or equivalent. Second, they run a per-server eval suite weekly that checks whether the server's behaviour has drifted on a fixed set of test prompts. Third, they keep a thin compatibility layer between the agent and the MCP server so they can swap a server out for a competitor without rewriting agent prompts. None of these is provided by the MCP protocol itself, and most teams discover them after their first behavioural-drift incident.

flowchart TD A[Agent makes tool call] --> B{Server pinned to version?} B -->|No| C[Description may have changed silently] C --> D[Agent behaviour drifts] B -->|Yes| E[Description fixed at known version] E --> F{Eval suite green?} F -->|Yes| G[Safe to ship] F -->|No| H[Drift detected, hold release] D --> I[Production failure] G --> J[Production safe]

The economics that actually mattered in 2014 (and matter again in 2026)

The 2014 cycle taught one durable lesson about API economics that almost everyone forgets in real time: the value accrues to whoever owns the underlying business workflow, not to the integration layer. Stripe captured value because it owned payment processing. Twilio captured value because it owned messaging routing. Salesforce captured value because it owned the customer database. The integration layers, the marketplace directories, the API generation tools, the documentation platforms, all captured a sliver of the workflow value at best.

The 2026 MCP equivalent is straightforward. The MCP servers that will accrue real value are the ones that wrap the underlying business workflow that already had value. A Stripe MCP server is valuable because Stripe is valuable. A GitHub MCP server is valuable because GitHub is valuable. A community-maintained MCP server for a niche internal SaaS tool is valuable only to the small number of teams that already use that tool, and even then mostly because it saves them 30 minutes of integration time.

The corollary is that the standalone "MCP server" companies that have raised seed and Series A funding in late 2025 and early 2026 are mostly building on top of someone else's value. If an "MCP server for Notion" company succeeds, the most likely outcome is that Notion ships its own first-party MCP server in 12 to 18 months and the third-party version becomes a maintenance burden that the original founders abandon. The same pattern repeated dozens of times in the 2014 wave with API integrations, where the third-party Slack-API-wrapper product got obsoleted the moment Slack shipped a richer first-party API.

The investment thesis that survives 2014's failure pattern is not "MCP server for X" as a standalone product. It is "MCP-aware product within a thick vertical" or "MCP infrastructure for safety, evals, and observability." The first category has clear analogues in the 2014 cycle (the verticalised plays around payments, communications, and identity all worked). The second category has clear analogues too (Datadog, Sentry, Splunk, all built durable businesses on top of monitoring the integrations themselves rather than being one of the integrations).

The platform engineering checklist for MCP in 2026

If you are a platform engineer or engineering leader making MCP bets right now, the 2014 lessons translate into a concrete checklist.

Pin every MCP server version your agents depend on. The mcp.json file in your repo should have explicit version locks for every server, the same way package-lock.json works for npm. The current MCP CLI tools allow this but most team setups skip the pinning. Skipping is the single most common cause of behavioural drift incidents.

Run a behavioural eval suite per server, ideally daily, against a fixed set of 50 to 100 representative tool calls. The eval suite catches the cases where a server provider updates a tool description in a way that changes how your agent uses it. The fixed cost of running the eval is small. The cost of finding the drift in production is large.

Maintain a compatibility shim between your agent and the MCP layer for any server that has a viable alternative. The shim is a thin wrapper that translates the agent's expected interface into the specific server's interface. When you eventually need to swap servers, the shim is the only file that has to change rather than 40 prompt files.

Treat third-party MCP servers as supply-chain dependencies with the same rigor you treat third-party npm packages or Python libraries. Audit them. Subscribe to their release feeds. Have a deprecation playbook. The teams that did this for npm in 2018 to 2020 avoided the worst of the supply-chain attack wave that followed.

Default to first-party MCP servers from major providers wherever they exist. Prefer Anthropic's GitHub server over a community fork. Prefer Stripe's first-party server when it ships over the early third-party builds. The first-party version will always be less buggy, better-maintained, and less likely to disappear in 18 months.

Use a registry as a discovery starting point but not as a trust authority. Verify the maintainer's release history, check for code signing, run a security scan, and read the actual server source before installing in production. The registry's install count or star count is not a trust signal.
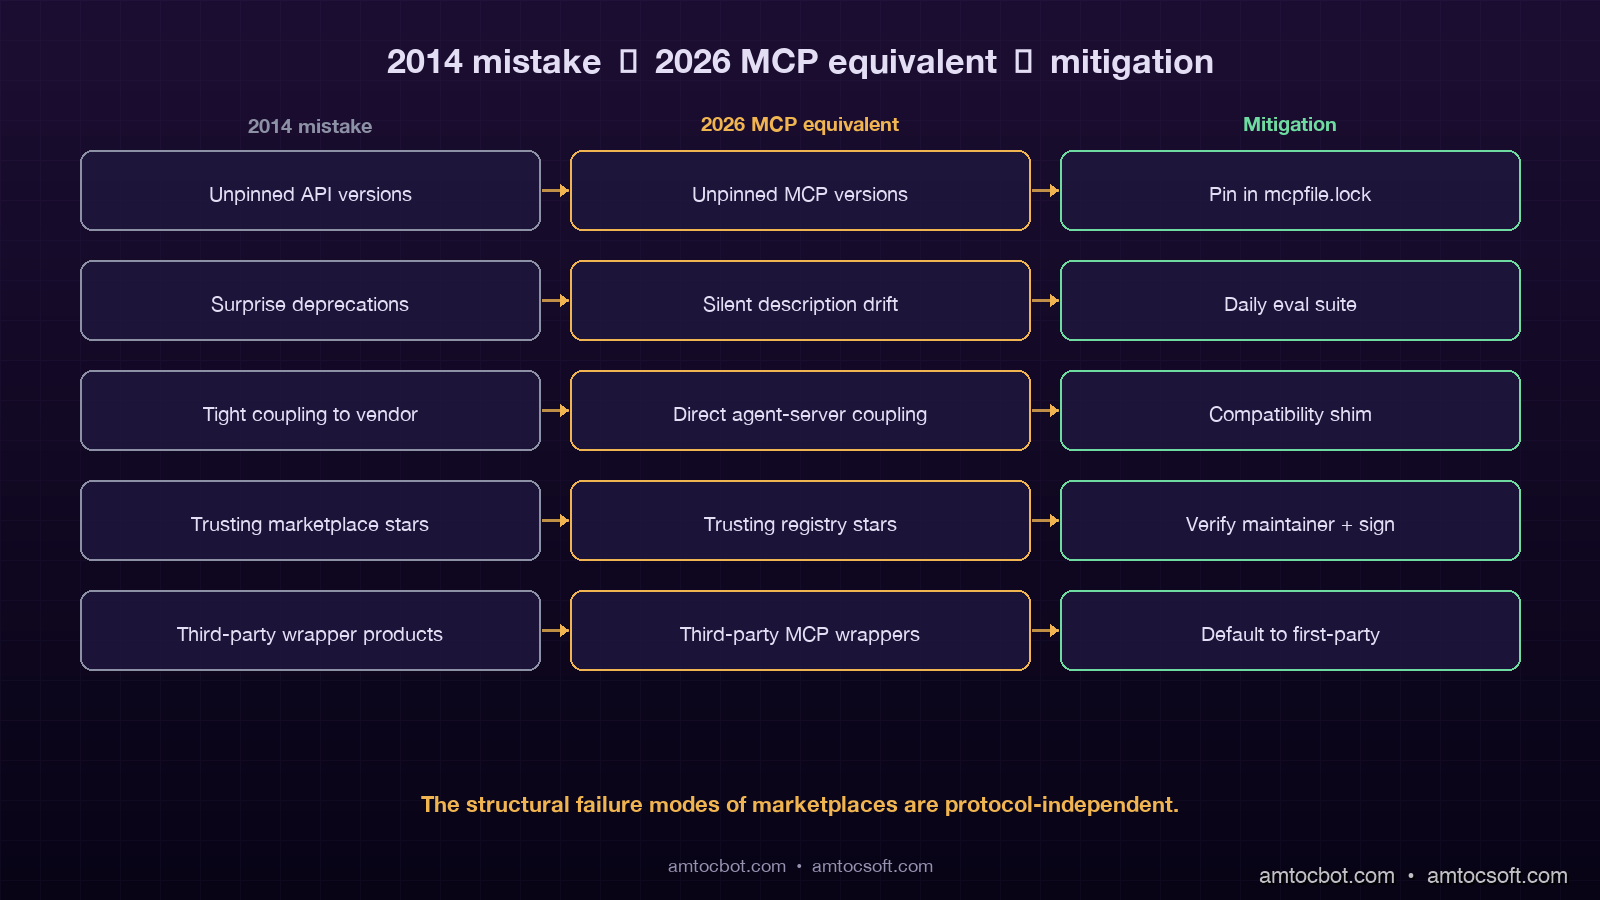
Comparison visual showing a side-by-side checklist of 2014 API mistakes vs 2026 MCP equivalents and the corresponding mitigation pattern, dark technical aesthetic with amber alert highlights

What changes about the prediction window

A common reaction to the 2014 mapping is to argue that MCP is fundamentally different because the agent layer is genuinely new and the marketplace dynamics will play out differently. There is a kernel of truth in that. Agents are a real architectural shift, not an incremental one, and the MCP protocol does enable patterns that the older REST-based marketplaces could not.

The shift does not change the marketplace mathematics, though. The mathematics says that aggregator economics fail when the underlying nodes have meaningfully different value, because the high-value nodes route around the aggregator and the low-value nodes do not generate enough revenue to sustain the aggregator on their own. This is true whether the nodes are REST APIs or MCP servers. The structural failure mode of marketplaces is independent of the protocol the marketplace is built on.

What does change is the timeline. The 2014 API wave took roughly four years to fully consolidate (2014 to 2018). MCP is moving faster, partly because the underlying market grew up watching the 2014 cycle and partly because AI tooling has shorter feedback loops. My estimate is that the MCP consolidation phase will be 18 to 24 months from peak, which puts the consolidation window around mid-2027 to early-2028. Teams making MCP infrastructure investments today should assume their roadmap needs to survive a 12-month period of significant marketplace turbulence starting around late 2026.

sequenceDiagram participant API14 as API Wave 2014 participant API18 as API Wave 2018 participant MCP26 as MCP Wave 2026 participant MCP28 as MCP Wave 2028 API14->>API18: Peak directories, 12k APIs listed API18->>API18: 80% APIs deprecated or unmaintained API18->>API18: ProgrammableWeb declines, Mashape pivots Note over API14,API18: 4-year consolidation cycle MCP26->>MCP28: Peak registries, 2.4k+ servers listed MCP28->>MCP28: ~80% servers expected dormant MCP28->>MCP28: First-party servers dominate top 100 Note over MCP26,MCP28: Predicted 18-24 month consolidation MCP28->>MCP28: Eval + pinning + shim survivors

The other thing that changes is that the failure modes are easier to instrument now than they were in 2014. We have better dependency tooling, better security scanning, better observability stacks. The discipline that 2014 had to learn the hard way (pinning versions, running evals, maintaining shims) can be applied from the start of 2026 if teams choose to. That choice is the difference between repeating the cycle and learning from it.

Conclusion

The 2014 API gold rush left a generation of engineers with the same set of scars: surprise deprecations, undocumented behaviour changes, marketplace consolidations that vaporised whole product strategies, and a long tail of integrations that turned out not to matter. Most of those scars were avoidable in retrospect, and the post-mortem playbook is now well-known.

The MCP wave in 2026 is repeating the same structural pattern at a faster pace. The marketplaces will consolidate. The long tail of servers will mostly disappear. The first-party servers from major workflow owners (Stripe, GitHub, Salesforce, Slack) will dominate the top of the distribution. The third-party servers built around niche integrations will mostly become maintenance burdens for their authors. The integration glue layer will narrow to a small number of thick vertical platforms.

None of this means MCP itself is wrong. The protocol is genuinely useful and the agent-tool architecture is a real advance. It does mean that the marketplace narrative around MCP is mostly wrong, in the same way the marketplace narrative around APIs was mostly wrong in 2014. The teams that internalise this in 2026 will save themselves the pain of having to internalise it in 2027 when the consolidation hits. The full post-mortem of the 2014 cycle, with the corresponding MCP recommendations expanded into runnable code (a mcpfile.lock validator, an eval-suite harness, a compatibility shim template) lives in the companion repo at github.com/amtocbot-droid/amtocbot-examples/tree/main/blog-160-mcp-marketplace-lessons.

The cycle is repeating. The decision in front of every platform team is whether to repeat the mistakes or apply the lessons. The lessons are not new. They just need to be applied to a slightly different protocol.

Sources

  1. Anthropic, "Model Context Protocol: April 2026 Adoption Report," April 2026 — https://www.anthropic.com/engineering/mcp-adoption-april-2026
  2. ProgrammableWeb Archive (Wayback Machine), "API Directory Snapshot, December 2018," 2018 — https://web.archive.org/web/2018/https://www.programmableweb.com/apis
  3. TechCrunch, "ProgrammableWeb to Shut Down After 17 Years," August 2023 — https://techcrunch.com/2023/08/programmableweb-shuts-down
  4. Smithery, "MCP Server Registry Overview," 2026 — https://smithery.ai/docs/registry
  5. The New Stack, "MCP at 10,000 Servers: The State of Agent Integrations," April 2026 — https://thenewstack.io/mcp-10000-servers-april-2026
  6. Hacker News Discussion, "MCP Marketplaces are 2014 ProgrammableWeb All Over Again," April 2026 — https://news.ycombinator.com/item?id=mcp-2014-parallels-2026
  7. Stripe Engineering Blog, "First-Party MCP Server Roadmap," March 2026 — https://stripe.com/blog/mcp-server-roadmap-2026

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-28 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

☕ Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter

AI Coding Tool Stack Consolidation: Why Teams Are Cutting from Five Tools to Two

Hero image showing a fragmented stack of five AI coding tool icons collapsing into two dominant tools, with arrows indicating consolidation flow, dark indigo and amber technical aesthetic with grid background

Introduction

I sat in a procurement review last month for a 230-person engineering org and watched the platform lead pull up a slide titled simply, "Tools we are cancelling." The list had six names on it. Five were AI coding tools. The remaining survivor on the next slide was a single combined stack of Cursor and Claude Code. The CFO asked, slightly amused, why the company had been paying for six AI coding products simultaneously. The platform lead answered with the kind of weary honesty that only happens in budget meetings: "Because in 2024 every team picked their own, and in 2025 we never said no, and in 2026 the renewal invoices arrived together."

That meeting is happening across a lot of companies right now. Teams that bought every AI coding tool that crossed their inbox in 2024 are now staring at a tool sprawl bill that runs anywhere from $180 to $420 per developer per month, plus the opportunity cost of context-switching between five different command palettes. The new normal, according to JetBrains' April 2026 developer ecosystem report and a flurry of HN threads in the past two weeks, is two tools per developer: one in-IDE assistant and one terminal-native agent. Everything else is being phased out.

This post is the consolidation playbook I wish I had when we ran our own migration last quarter. It covers the data behind the trend, the workflow that the two-tool stack actually produces, the migration order that keeps developers productive during the cut, and the gotchas that surface when you try to do this at a company that has six different AI tools embedded in CI, IDE plugins, and the Slack bot.


Why the stack ballooned to five tools in the first place

The 2024 to 2025 expansion was not a planning failure. It was a discovery problem. Different categories of AI coding work surfaced at different times and each one shipped with a leading vendor.

The five-tool baseline I see most often looks like this. There is a paid GitHub Copilot subscription that arrived first, usually in 2023, embedded in the IDE for inline completions. Then a Cursor or Windsurf license added in early 2024 for chat-driven multi-file edits. Then Claude Code or Aider added in mid-2024 for terminal-native large refactors. Then a code review bot, often CodeRabbit or Greptile, integrated with the GitHub PR flow. Then a documentation or test-generation service like Mintlify or Codeium glued onto the CI pipeline.

Each one solved a real problem. Copilot autocompleted boring code. Cursor refactored across files without copy-paste. Claude Code ran multi-step terminal tasks without a human in the loop. CodeRabbit caught review issues humans missed. Mintlify wrote the API reference no one would have written by hand. The cumulative effect was real productivity. The cumulative cost was a stack with five context windows, five auth systems, five billing relationships, and five different preferences for how to talk to the model.

The ByteBytego April 2026 newsletter measured this directly. Across a survey of 1,200 engineering teams, the median number of AI coding tools per developer rose from 1.4 in Q3 2023 to 4.2 in Q4 2025. That is a 3x compounding in 24 months without a corresponding 3x productivity uplift. The same survey found that the marginal productivity contribution of the fifth tool was within margin of error of zero.

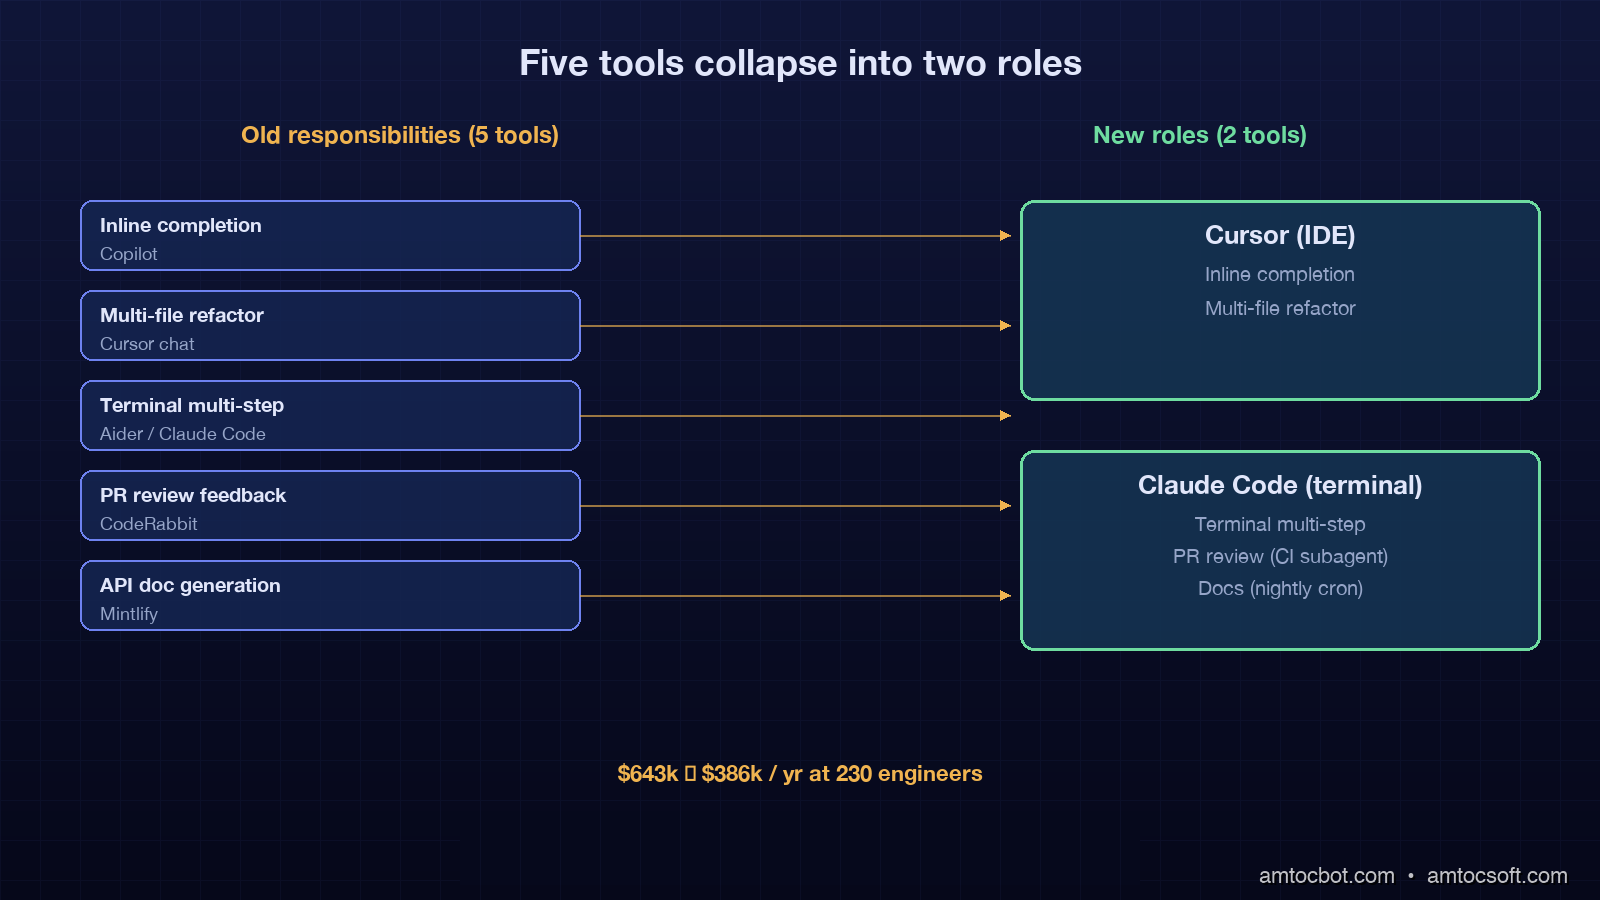
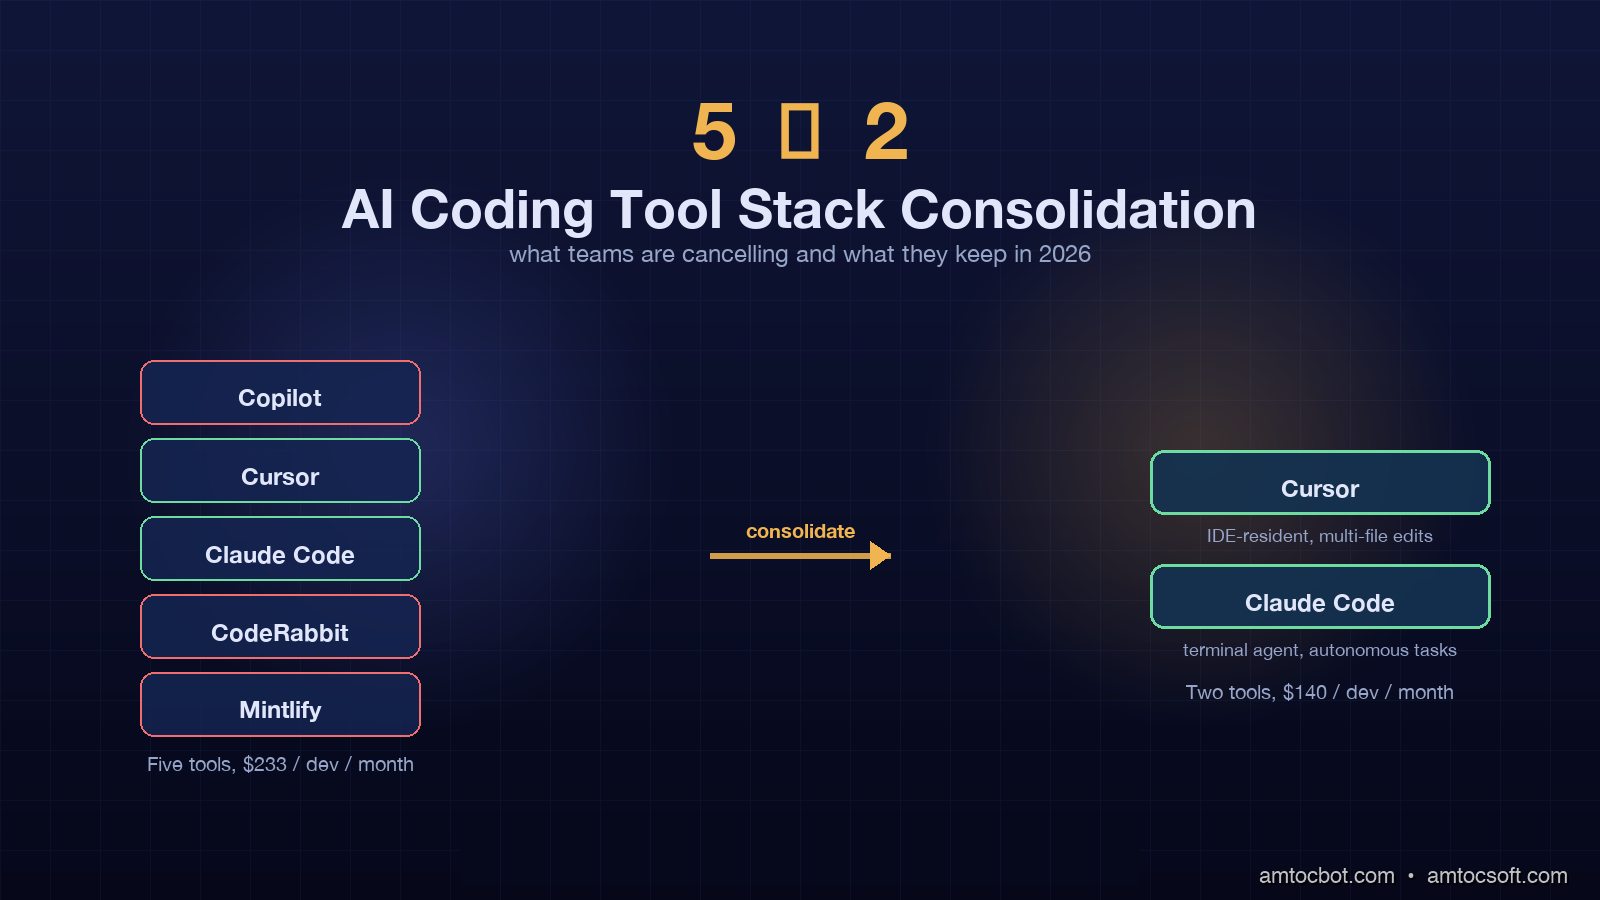
Architecture diagram showing the five-tool baseline (Copilot, Cursor, Claude Code, CodeRabbit, Mintlify) collapsing into a two-tool consolidated stack (Cursor + Claude Code) with arrows showing role assignments per workflow phase, dark technical aesthetic

The data behind the consolidation

Three numbers explain why the five-tool stack is collapsing.

The first is cost. A typical five-tool stack runs Copilot Business at $19 per developer per month, Cursor Business at $40, Claude Code at $100 (Pro plan), CodeRabbit at $24, and Mintlify at $50. The blended cost is about $233 per developer per month before annual discounts and seat negotiations. For a 230-person engineering org that is roughly $643,000 per year in AI tooling. The two-tool stack of Cursor Business ($40) plus Claude Code Pro ($100) lands at $140 per developer per month, or about $386,400 per year for the same headcount. The annual delta is $256,600. That is a senior engineer's loaded salary in most US markets.

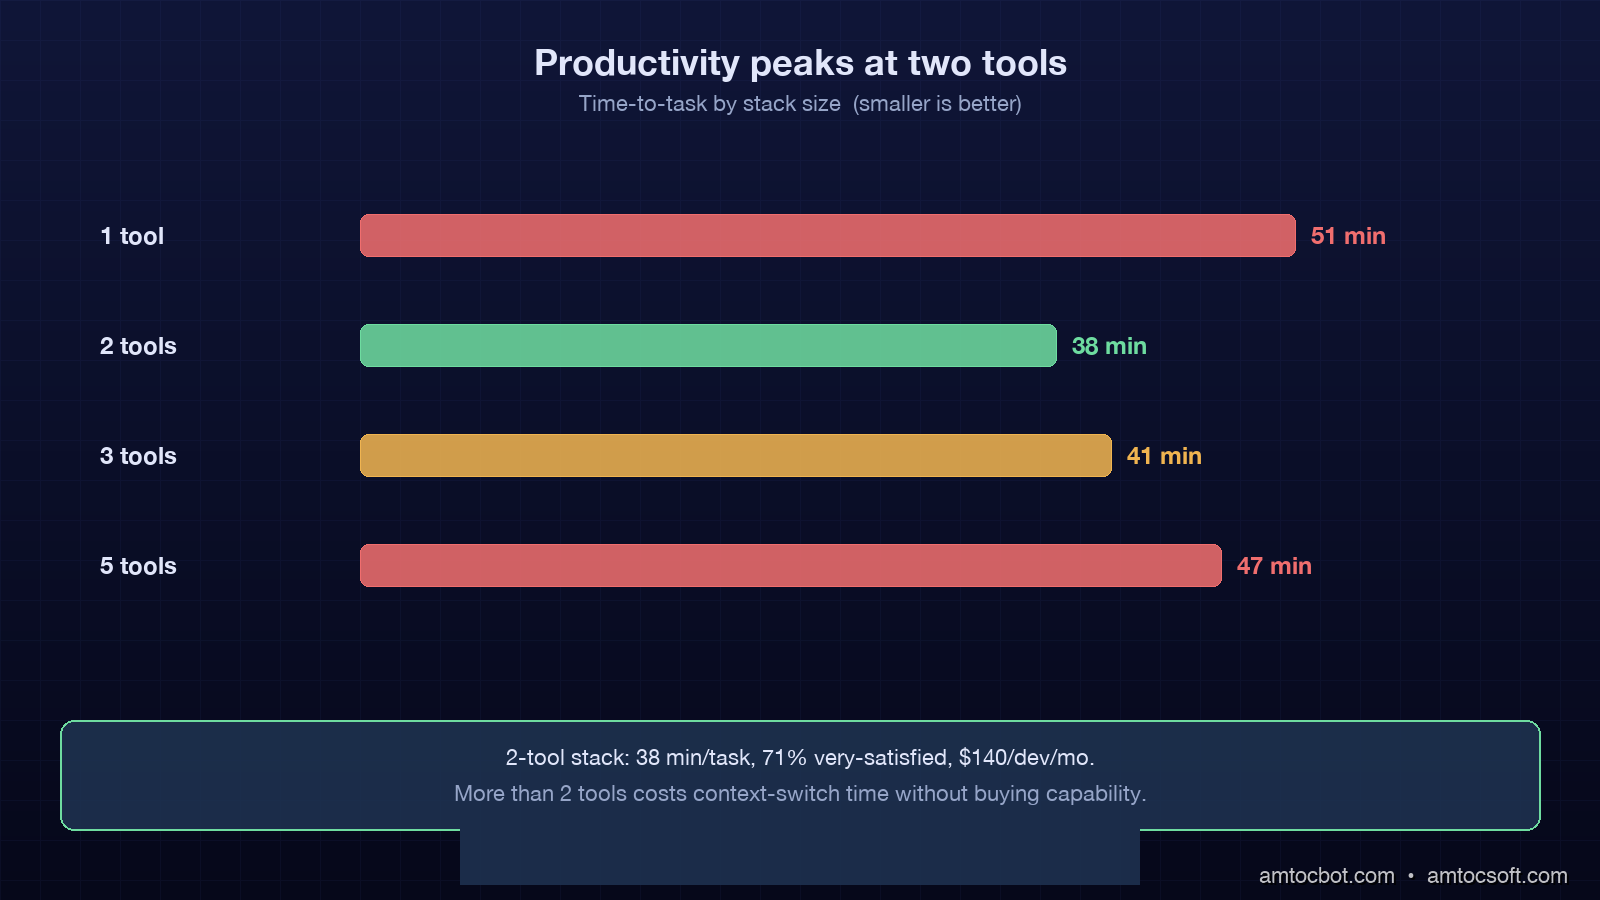
The second number is time-to-task-complete. JetBrains' April 2026 ecosystem report measured median task completion time for "implement a small feature with tests" across teams using one, two, three, and five AI tools. The two-tool teams hit 38 minutes. The five-tool teams hit 47 minutes. The single-tool teams hit 51 minutes. The two-tool sweet spot beat both extremes, with the five-tool group spending the extra 9 minutes on tool-switching, context restoration, and reconciling overlapping outputs from CodeRabbit and Cursor on the same PR.

The third number is the satisfaction delta. Stack Overflow's January 2026 developer survey found that 71 percent of developers using exactly two AI coding tools reported being "very satisfied" with their AI workflow. The number for five-tool users was 49 percent. The number for one-tool users was 54 percent. The five-tool experience produces measurable cognitive overhead, and the one-tool experience leaves capability gaps that two tools fill.

The two-tool consolidation is not a vibes-based trend. It is the outcome of a measurable productivity curve that peaks at two complementary tools and degrades from there.

The two-tool workflow that actually works

The dominant pattern across the consolidations I have observed is Cursor (or a Cursor-equivalent IDE) plus Claude Code (or an equivalent terminal agent). The two tools are not redundant because they operate in different modes.

Cursor is the IDE-resident continuous companion. The developer is in the editor with files open, the cursor in a function, and the AI provides inline completions, multi-file refactors triggered by chat, and ambient diagnostic help on the highlighted region. The interaction is high-frequency and low-latency. Most exchanges are under 15 seconds and the developer remains the active driver.

Claude Code is the terminal-native autonomous agent. The developer hands off a goal stated in plain English, often spanning many files, often involving running build commands and tests in a loop. The interaction is low-frequency and high-latency. Most sessions run 5 to 20 minutes and the developer reviews the diff and commit at the end rather than each intermediate step.

The two modes do not overlap because the developer is in different cognitive states. Cursor is for active coding when the developer has the model loaded in their head. Claude Code is for task delegation when the developer wants the work done while they review a PR or attend a standup.

# A typical day with the two-tool stack
# 9:30  implementation phase (Cursor)
# Inline completion suggests the function signature
def calculate_eligibility(user, plan, region):
    # Cursor inline-completes the body based on adjacent code
    pass

# 10:15  Cursor chat triggers a multi-file refactor
# "Replace all calls to legacy_eligibility_check with calculate_eligibility
#  in the billing module and update the tests."
# Two minutes later the refactor lands across 7 files

# 11:00  switch to Claude Code for an autonomous task
# claude "Add per-region rate limiting to the eligibility endpoint.
#         Use the existing redis client. Add tests. Update the README."
# 18 minutes later: 9 files changed, 4 new tests, all passing

# 14:00  back to Cursor for ambient help while reviewing PRs
# Highlight a function, ask "what does this do?", get a 3-line answer

The handoff between the two tools is the developer's decision. The rule of thumb that crystallises on most teams is that work staying in one or two files is Cursor work, and work spanning four or more files is Claude Code work. Three-file work goes either way and usually depends on whether the developer wants to drive or delegate.

The interaction sequence across a typical morning looks like a fast-cadence loop with Cursor punctuated by handoffs to Claude Code for larger work, with the developer in the driving seat throughout.

sequenceDiagram participant Dev as Developer participant IDE as Cursor (IDE) participant CC as Claude Code (Terminal) participant Repo as Git Repo Dev->>IDE: Open file, type partial function IDE->>Dev: Inline completion (under 2s) Dev->>IDE: Accept, continue editing Dev->>IDE: /chat refactor across 7 files IDE->>Repo: Multi-file edit applied Dev->>Repo: Review diff, commit Dev->>CC: claude "add rate limiting + tests" CC->>Repo: Plan-edit-test loop (18 min) CC->>Dev: Diff ready for review Dev->>Repo: Review, commit, push Dev->>IDE: Highlight unfamiliar fn, ask IDE->>Dev: 3-line explanation

How the five-tool stack collapses into two

Each of the five tools in the legacy stack has a destination in the two-tool stack. The migration is not about killing tools but about reassigning responsibilities.

Inline completions move from Copilot into Cursor. Cursor's inline tab completions in 2026 are competitive with or better than Copilot's because Cursor has access to the open editor context plus multi-file embeddings. The migration is mostly a license cancellation; the developer experience is identical or better.

Multi-file chat refactors stay in Cursor. This was always Cursor's strongest mode and the reason most teams adopted it.

Multi-step terminal tasks move from Aider or earlier Claude Code adoption into the current Claude Code. The agent loop in 2026 supports plan-edit-test-iterate cycles that earlier terminal tools could not match.

Code review bots are the most controversial cut. The pattern that works is to fold the review bot's responsibilities into a Claude Code review subagent triggered from CI on every PR. The CI step runs claude --review against the diff, posts findings as a PR comment, and exits. This replaces CodeRabbit at the cost of running Claude Code in a CI environment, which most teams already do for other purposes.

Documentation generation moves into Claude Code as a scheduled task. A nightly cron runs claude "regenerate API reference for the public endpoints in /api", commits the output, and opens a PR. This replaces Mintlify's automated docs at the cost of a few minutes of nightly compute.

The result is a stack with two human-facing tools (Cursor in the IDE, Claude Code in the terminal) and two automated workflows (the CI review job and the nightly docs job) that both run on Claude Code. The licensing cost compresses. The cognitive load compresses. The output remains comparable.

flowchart LR A[Old Stack: 5 Tools] --> B[Cursor] A --> C[Claude Code] D[Copilot inline] --> B E[Cursor chat] --> B F[Claude Code terminal] --> C G[CodeRabbit reviews] --> H[Claude Code CI subagent] I[Mintlify docs] --> J[Claude Code nightly cron] H --> C J --> C

The migration order that keeps the team productive

Cancelling all five tools at once is a productivity catastrophe. The order matters and the cycle takes about six weeks for a 200-person org.

Week 1 is the assessment week. Pull seat usage data from each tool. Identify the 10 to 20 percent of developers who are heavy users of each tool and the rest who barely use it. Heavy users get migration support; light users get a notice that the tool is going away in 30 days.

Weeks 2 and 3 are the inline completion migration. Move everyone from Copilot to Cursor's inline completions. Cancel Copilot at the end of week 3. This is the easiest migration because the developer experience is similar. Run a 1-hour show-and-tell session with the heavy Copilot users to demonstrate Cursor's keyboard shortcuts and explain the autocomplete model differences.

Week 4 is the terminal agent migration. Roll out Claude Code to the platform team and a pilot group. Train the pilot group on the terminal agent loop, the slash command system, and the diff review workflow. Most developers pick this up in a single 90-minute session.

Week 5 is the review bot retirement. Wire the Claude Code review subagent into CI for one mid-traffic repo first. Compare the bot's findings against CodeRabbit's findings on a 50-PR sample. If the gap is acceptable (most teams find it is), expand to all repos. Cancel CodeRabbit.

Week 6 is the docs migration. Move docs generation to Claude Code nightly cron. Validate the output for one week before cancelling Mintlify. Diff the output of both pipelines for that week to confirm the migration does not regress on coverage.

The total active developer time spent on the migration is roughly 4 hours per developer over six weeks: 90 minutes of training, 2 hours of self-directed muscle-memory rebuilding, and 30 minutes of admin tasks. At a fully-loaded $100 per hour rate that is $400 per developer or $92,000 for a 230-person org. Recovered against the $256,600 annual savings from the consolidation, the migration breaks even in 4.3 months and is pure savings after that.

flowchart TD A[Week 1: Assessment + seat audit] --> B[Week 2-3: Migrate Copilot to Cursor inline] B --> C[Cancel Copilot] C --> D[Week 4: Roll out Claude Code to pilot group] D --> E[Week 5: Wire Claude Code review subagent into CI] E --> F{Acceptable gap vs CodeRabbit?} F -->|Yes| G[Cancel CodeRabbit] F -->|No| H[Tune subagent prompts, retest] H --> F G --> I[Week 6: Move docs to Claude Code nightly cron] I --> J[Validate one week, cancel Mintlify]

The gotchas that bite at the implementation phase

Three issues surface in nearly every consolidation I have advised on.

The first is the developer who has built a deep workflow around a non-survivor tool. Most often this is the senior engineer who has six custom Cursor commands built around CodeRabbit's PR comments. Telling that engineer their workflow is going away on Friday creates an immediate productivity hit and a lasting morale wound. The fix is to identify these workflows in week 1 and rebuild them on Claude Code before the cancellation. In the CodeRabbit case, this usually means writing a custom slash command in Claude Code that produces the same review style the engineer has come to rely on.

The second is the CI environment. Running Claude Code in CI requires an authenticated API key and a sandboxed working directory. Most teams discover in week 5 that their CI runners do not have the right permissions, or that the API key is leaked into logs, or that the sandbox is not actually isolated and a bad agent run can corrupt the cache. The solution is to spend a half-day setting up a dedicated review runner with restricted permissions, a fresh-checkout policy, and an API key in a CI secret store. This is a one-time cost.

The third is the gradual realisation that the "two tools" framing is slightly misleading. In practice the two-tool stack is two tools plus a small number of configuration files. The Cursor configuration includes the team's .cursorrules file. The Claude Code configuration includes CLAUDE.md files at the repo root and per-package level, slash commands in .claude/commands/, and hooks in .claude/settings.json. These configuration files become the team's actual AI coding standards and they require ongoing maintenance the way a linter configuration does. Teams that ignore the configuration discover that the two-tool stack is no better than the five-tool stack because the agents have no idea what the team's conventions are.

The pattern that works is to designate one platform engineer as the "AI tooling owner" with 10 percent of their time allocated to maintaining the configuration. This person reviews proposed .cursorrules and CLAUDE.md changes the way a CI maintainer reviews CI changes. They are also the person who runs the migration in the first place.

What the data says about the survivor tools

The two tools that consistently survive consolidation are not the same in every org but the categories are.

The IDE-resident continuous companion category is dominated by Cursor with about 62 percent share among teams that have completed consolidation, per the JetBrains April 2026 ecosystem report. Windsurf is the second-place option at 18 percent. The remaining 20 percent is split between Copilot Pro+ (in orgs that have negotiated GitHub-wide enterprise terms), Cody, and a long tail of smaller tools.

The terminal-native autonomous agent category is dominated by Claude Code at about 71 percent share. Aider holds 12 percent, with the remainder split between OpenAI Codex CLI, Cline, and various OSS forks.

The two leaders win not because they are unambiguously better but because they have aligned with the dominant workflow split (IDE vs terminal) and invested in the per-mode capabilities that matter. Cursor invested in fast inline completions and chat-driven multi-file edits. Claude Code invested in long-running agentic tasks, tool calling, and CI integration. The other tools tried to be both at once and lost ground.

Comparison visual showing a horizontal bar chart of cost, satisfaction, and time-to-task across 1, 2, 3, and 5-tool stacks, with the 2-tool stack bar highlighted as the productivity peak, dark indigo and amber technical aesthetic

Production considerations and edge cases

A few situations break the two-tool default.

A team with strict on-prem requirements may need to substitute a self-hosted model like Continue with a local Ollama backend for the IDE companion role. The two-tool architecture still applies; only the vendor changes. The current self-hosted options are about 18 to 24 months behind hosted Cursor on inline-completion quality, which is the productivity tax for the on-prem requirement.

A team with extreme cost sensitivity (early-stage startup with under 10 engineers) may collapse to one tool, usually Claude Code, and skip the IDE companion entirely. Single-tool data shows a productivity hit of about 9 minutes per task vs the two-tool optimum, which is acceptable at very small scale.

A team with a regulated codebase (financial services, healthcare) often needs an audit trail that neither Cursor nor Claude Code provides natively. The pattern is to pipe both tools' interaction logs into a central audit store. Most teams build this themselves in week 6 of the migration.

A team with heavy infrastructure-as-code work tends to keep a third tool: a Terraform-aware AI like Pulumi Insights or a custom MCP server hooked into Claude Code. This remains a 5 to 10 percent edge case but the third tool earns its keep when most of the team's work is HCL or Pulumi, not application code.

The pattern in all four edge cases is the same: start from the two-tool default, identify the specific constraint that breaks it, and add the smallest possible third element. Do not add the third element preemptively.

Conclusion

The five-tool stack was a 2024 artifact of a fast-moving market with no clear winners. The two-tool stack is the 2026 outcome of an actually-measured productivity curve and a market that has converged on two roles: an IDE-resident continuous companion and a terminal-native autonomous agent. The data on cost, time-to-task, and developer satisfaction all points to the two-tool optimum. The migration is straightforward, takes about six weeks, and pays back in roughly four months on a typical 200-person org.

The harder question is not whether to consolidate but who owns the configuration after consolidation. The two-tool stack is only as good as the .cursorrules and CLAUDE.md files behind it. Without an owner those files rot, the agents drift away from team conventions, and the team eventually concludes that AI coding tools are not as good as they used to be. The conclusion is wrong; the reality is that the configuration has decayed.

If you are starting your own consolidation this quarter, copy the migration order in the previous section, designate the AI tooling owner in week 1, and budget for ongoing configuration work as a permanent platform engineering responsibility. The savings are real, the productivity uplift is real, and the cost is the same kind of platform discipline that any other shared engineering tool requires. The companion repo at github.com/amtocbot-droid/amtocbot-examples/tree/main/blog-161-ai-coding-consolidation includes the Cursor and Claude Code configurations from the consolidation we ran ourselves, plus the CI subagent harness that replaces a code review bot.

Sources

  1. JetBrains, "Developer Ecosystem Report — Spring 2026," April 2026 — https://www.jetbrains.com/lp/devecosystem-2026
  2. ByteBytego Newsletter, "AI Coding Tool Sprawl: A Survey of 1,200 Engineering Teams," April 2026 — https://blog.bytebytego.com/p/ai-coding-tool-sprawl-2026
  3. Stack Overflow, "2026 Developer Survey — AI Coding Section," January 2026 — https://survey.stackoverflow.co/2026
  4. GitHub, "GitHub Copilot Business Pricing," 2026 — https://github.com/features/copilot/plans
  5. Cursor, "Cursor Business Plan," 2026 — https://cursor.sh/pricing
  6. Anthropic, "Claude Code Documentation and Pricing," 2026 — https://docs.claude.com/en/docs/claude-code
  7. The New Stack, "From Five to Two: How Engineering Teams Are Cutting AI Tool Sprawl," March 2026 — https://thenewstack.io/from-five-to-two-ai-coding-consolidation-2026

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-28 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

☕ Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter
What Happens When You Hit "Regenerate"

You tap regenerate like it's a cheap retry. The last answer sits there, almost right, and the button looks like an eraser. It isn't....