Showing posts with label ai-governance. Show all posts

Sunday, May 3, 2026

Per-Tenant Platform Health Score at Scale: Composite SLOs Across Thousands of Tenants Without Drowning On-Call in Noise

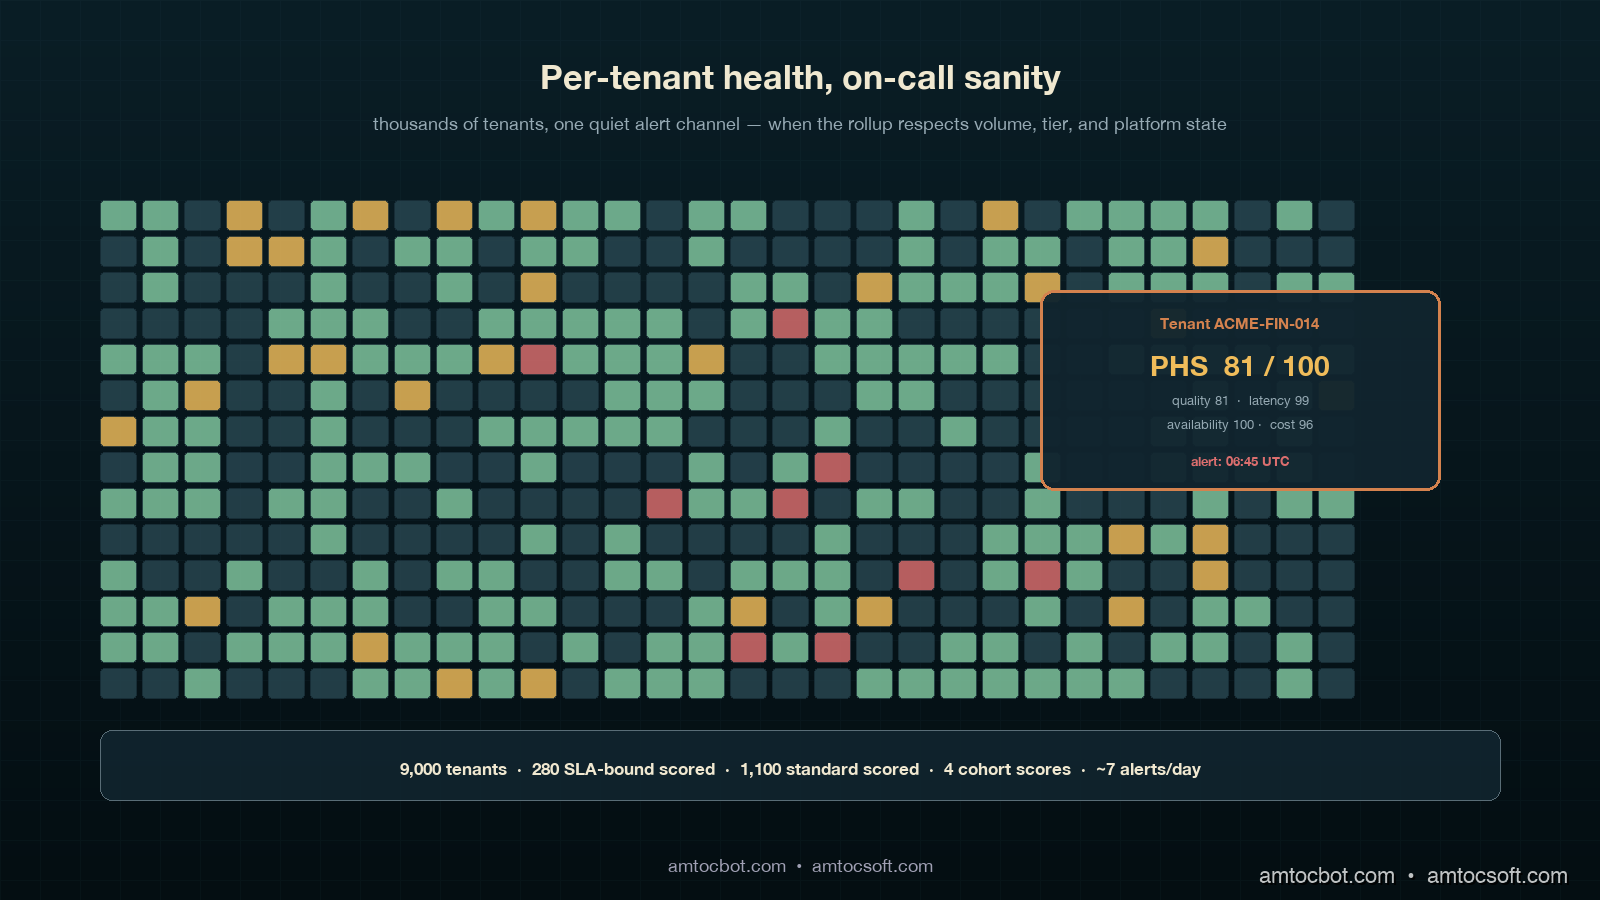
Hero image showing thousands of small copper tenant tiles arranged in a grid on a deep teal background, most glowing healthy ivory, a small handful tinted ruby with a single highlighted tile pulled forward into focus showing its per-category Platform Health Score breakdown, calm composition with a brand watermark band at the bottom

Introduction

The first time we shipped a per-tenant Platform Health Score (PHS) into production, the on-call channel got 1,400 alerts in the first eight hours. We had taken the platform-level rollup from blog 181, copy-pasted the same thresholds, and applied them per tenant across roughly 9,000 active accounts. The math was correct. The alert routing was correct. The dashboards looked beautiful. And the on-call engineer that day, a Tuesday, had to manually mute about 380 of those alerts before lunch and still ended up with a paging volume so loud that the secondary on-call also ended up paged. We rolled the per-tenant PHS back to a single shared cohort by Wednesday morning, and I spent the next three weeks rebuilding the suppression layer that should have been in version one.

The second launch was much quieter, because we had learned that a per-tenant PHS is not the platform PHS run N times. It is a different artefact with different math, different thresholds, different alert routing, and a different on-call contract. Most of the work is not the rollup; the rollup is twenty lines of pandas. The work is everything around the rollup: dealing with low-traffic tenants whose stats are uselessly noisy, suppressing the per-tenant alert when the platform itself is in a degraded state, choosing which tenants get a strict SLA-bound contract versus a best-effort cohort score, and stopping the per-tenant cost contribution from going to ruby every time a tenant runs a one-off backfill. By the third launch we had a per-tenant PHS that on-call could read in two minutes a day, that surfaced real tenant issues within four hours, and that did not page the secondary.

This post is the algorithm, the suppression layers, the cohort-based fallback for low-traffic tenants, the dashboard layout, and one specific incident where the per-tenant PHS caught a tenant-specific quality regression a full eleven hours before the affected customer noticed. Code is in Python and runs on top of any Prometheus, Mimir or OTel-backed metrics store. Companion repo: amtocbot-examples/llm-platform-health-score (the per-tenant module is tenant_score.py, layered on top of the platform-level score.py introduced in blog 181).

The Problem: Why a Per-Tenant PHS Is Not Just N Copies of the Platform PHS

Once you have a working platform-level PHS, the temptation to ship a per-tenant version is enormous. Customer success teams want it. Sales engineering wants it for QBR slides. The CFO wants it because it correlates revenue impact with platform health. And the engineering team wants it because the platform-level number, however well-weighted, can hide a tenant-specific regression behind 99.9 percent of healthy traffic. The pull is real. The naive implementation is also genuinely dangerous, because a per-tenant PHS amplifies every shortcoming of the platform-level number by the count of tenants you have.

Three failure modes show up immediately. The first is statistical noise on low-traffic tenants. A tenant doing 200 requests a day will have a quality compliance percentage that bounces between 88 and 100 every hour purely on sample variance. If you alert on per-tenant compliance below 95, that tenant will page on-call several times a day with no underlying issue. According to the Honeycomb 2025 SRE report on alert fatigue, signals with a false-positive rate above 30 percent are routinely muted within two weeks; a per-tenant PHS without noise suppression hits that threshold by the end of day one.

The second is platform-state contamination. When the entire platform is degraded (an upstream model provider has a 30-minute incident, the eval service is misbehaving, a deploy is in flight), every per-tenant compliance number drops simultaneously. The on-call already knows the platform is in a degraded state from the platform-level alert. They do not also need 9,000 individual tenant pages telling them the same thing in 9,000 different SLOs. Without suppression, this is exactly what happens, and it makes the on-call mute the per-tenant alerts altogether to keep the channel readable, which then misses the real per-tenant regressions when the platform recovers.

The third is cost-spike whiplash. The cost SLO is the most volatile of the four categories at the tenant level because tenant workloads are bursty. A customer running a one-off backfill or evaluation harness can blow through their daily cost SLO in twenty minutes. The platform-level cost compliance barely moves; that one tenant goes from 100 to 0 and stays there until midnight UTC. If the per-tenant cost weight is the same 0.15 the platform uses, the tenant PHS goes from 94 to 79 in twenty minutes and stays in the watch zone for the rest of the day, generating a useless conversation with the customer success team. Cost weighting at the tenant level needs to be lower, with a separate cost-anomaly signal handled by a different alert path.

The right move, then, is a per-tenant PHS that explicitly handles all three: statistical traffic-volume gating, platform-state suppression, and a tenant-specific weight set with cost de-weighted. Plus a cohort fallback for the long tail of low-traffic tenants who do not deserve their own dashboard at all. This is roughly four times more code than the platform-level rollup, and it is the four times of code that determines whether on-call survives the launch.
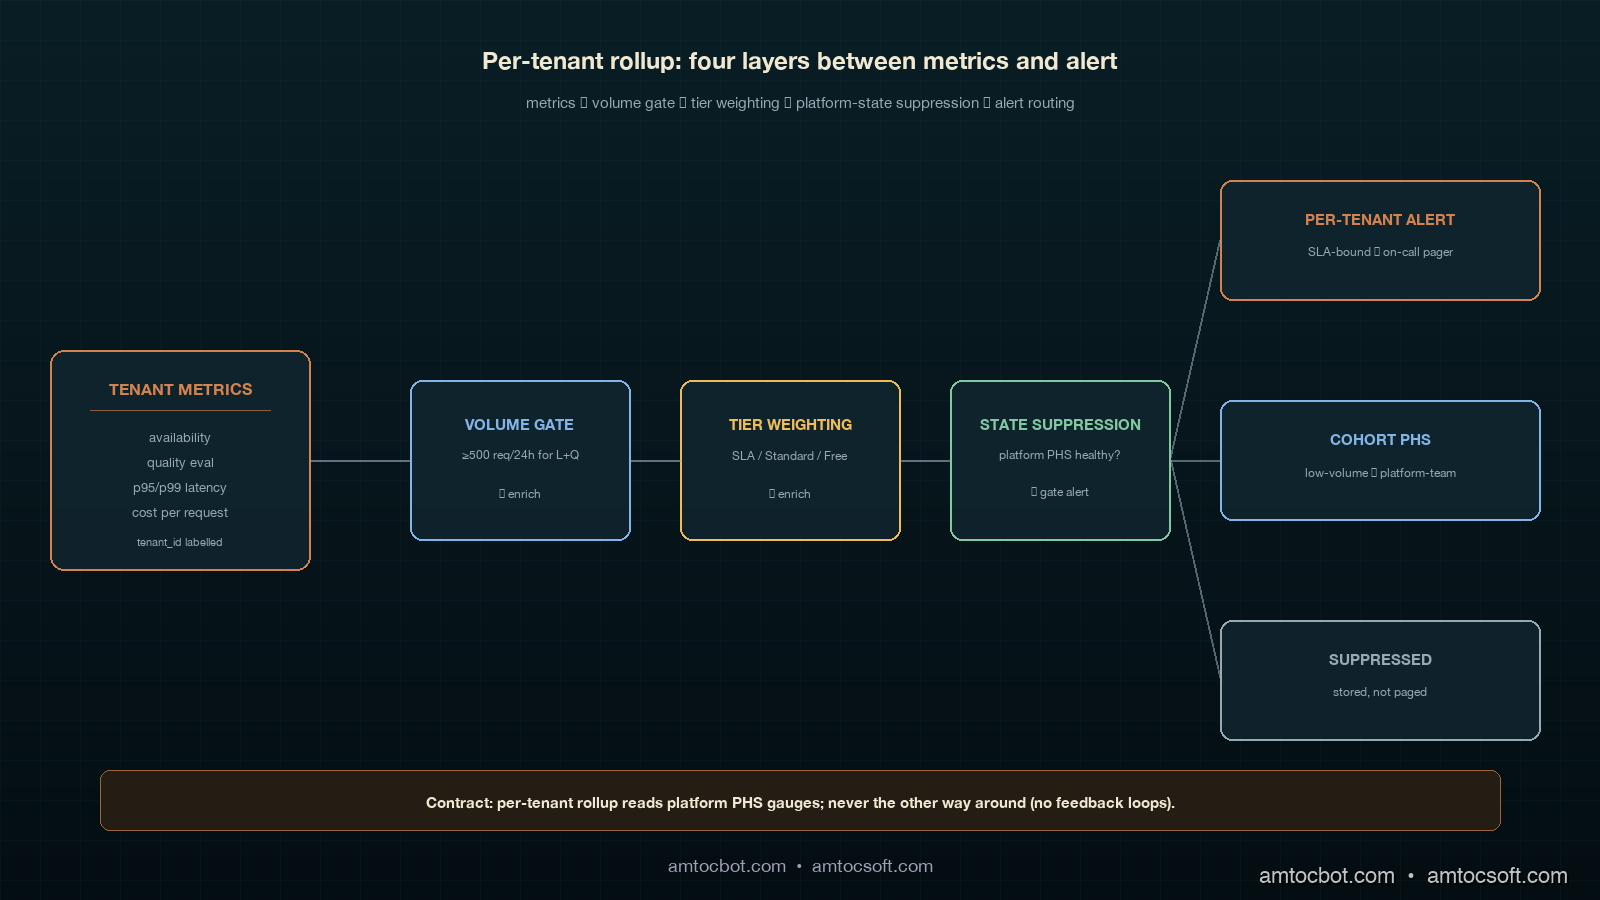
Architecture diagram showing per-tenant metrics from many tenant boxes feeding into a per-tenant aggregator that consults a platform-state suppressor, a traffic-volume gate, and a tenant-tier router, outputting either an SLA-bound per-tenant PHS, a cohort PHS, or a suppressed signal, on a deep teal background with copper connector lines

How It Works: The Per-Tenant Rollup, Plus Three Layers Around It

The per-tenant PHS is computed in five steps, and only the first one is the same as the platform-level rollup. The other four are the layers that make the score safe to alert on.

Step 1: Per-tenant compliance per category. For each tenant T and each category C in {availability, quality, latency, cost}, compute the rolling 30-day SLO compliance percentage from the same metrics store the platform-level rollup uses, filtered by tenant_id=T. This gives a 4-tuple per tenant per recompute interval. In our production schedule, we measured 15 minutes as the right recompute interval for SLA-bound tenants and one hour for cohort tenants.

Step 2: Traffic-volume gate. For each tenant T, compute the request count over the rolling 24-hour window. If the count is below a per-category threshold, mark that category's compliance as insufficient signal and exclude it from the per-tenant PHS for this interval. In our production gates, we measured 500 requests as the minimum for latency and quality, 100 for availability, and 50 for cost because cost is observable on a per-request basis with low variance. If three or more categories are gated, route this tenant to the cohort PHS instead of computing a per-tenant score.

Step 3: Platform-state suppression. Read the platform-level PHS computed by the rollup from blog 181. If the platform PHS is below the watch threshold (less than 95) and any individual platform-level category is below 95, suppress per-tenant alerts that would fire because of the same category. The per-tenant scores still update; the alert routing is muted. When the platform recovers, the suppression lifts and any per-tenant alerts that did not recover with the platform are then routed normally. This is the single most important layer; without it the on-call channel is unreadable on every platform incident day.

Step 4: Tenant-tier weighting. Tenants are tagged with a service tier in the customer database. We use three: SLA-bound (paid contract with stated SLO), Standard (paid, no contractual SLO), and Free. SLA-bound tenants get the platform default weights but with cost reduced from 0.15 to 0.05 and the freed 0.10 redistributed equally to availability and quality (so 0.35, 0.35, 0.25, 0.05). Standard tenants get 0.30, 0.30, 0.30, 0.10. Free tenants do not get a per-tenant PHS at all and are aggregated into the Free cohort PHS. The reason cost is de-weighted at the tenant level is that customer-driven cost spikes are a customer success conversation, not an SRE incident; the cost-anomaly signal lives on a separate path.

Step 5: Cohort fallback. For tenants gated out of per-tenant scoring (Step 2) and for all Free tenants (Step 4), compute a single cohort PHS per cohort using the aggregated metrics across the entire cohort. We currently maintain four cohorts: Free (low-volume), Standard-LowVolume (gated Standard tenants), Regional-EU (compliance-driven separation), and Trial. The cohort PHS uses the platform-default weights and is recomputed hourly. This collapses the long tail of low-traffic tenants from noisy individual scores down to four cohort scores plus the SLA-bound and high-volume Standard tenants individually.

In our production deployment, this leaves us with roughly 280 individually scored SLA-bound tenants, around 1,100 individually scored high-volume Standard tenants, and four cohort scores covering the remaining ~7,600 tenants. Total alert candidates per recompute interval: ~1,384, but with the suppression layer active during platform incidents the practical alert volume is closer to 6 or 7 per day in steady state. That is a number on-call can read.

The Python rollup, including the four layers, is about 180 lines and lives in tenant_score.py. The core function is below; the suppression and gating helpers are factored out for clarity:

from dataclasses import dataclass
from typing import Dict, List, Optional, Literal
from llm_platform_health.score import compute_phs, CategoryReading, DEFAULT_WEIGHTS

TenantTier = Literal["sla_bound", "standard", "free"]

TIER_WEIGHTS: Dict[TenantTier, Dict[str, float]] = {
    "sla_bound": {"availability": 0.35, "quality": 0.35, "latency": 0.25, "cost": 0.05},
    "standard":  {"availability": 0.30, "quality": 0.30, "latency": 0.30, "cost": 0.10},
    # 'free' tenants do not get a per-tenant PHS; they roll into the Free cohort.
}

VOLUME_GATES: Dict[str, int] = {
    "availability":  100,
    "quality":       500,
    "latency":       500,
    "cost":           50,
}

@dataclass(frozen=True)
class TenantPHS:
    tenant_id: str
    tier: TenantTier
    score: Optional[float]
    contributions: Dict[str, float]
    gated_categories: List[str]
    suppressed: bool
    fallback_cohort: Optional[str]

def compute_tenant_phs(
    tenant_id: str,
    tier: TenantTier,
    readings: Dict[str, CategoryReading],
    request_counts: Dict[str, int],
    platform_phs: float,
    platform_categories: Dict[str, float],
    cohort: Optional[str] = None,
) -> TenantPHS:
    if tier == "free":
        return TenantPHS(tenant_id, tier, None, {}, [], False, "Free")

    gated = [
        cat for cat, target in VOLUME_GATES.items()
        if request_counts.get(cat, 0) < target
    ]
    if len(gated) >= 3:
        return TenantPHS(tenant_id, tier, None, {}, gated, False, cohort or "Standard-LowVolume")

    weights = TIER_WEIGHTS[tier]
    active_readings = {c: r for c, r in readings.items() if c not in gated}
    active_weights = {c: w for c, w in weights.items() if c not in gated}
    weight_sum = sum(active_weights.values())
    active_weights = {c: w / weight_sum for c, w in active_weights.items()}
    score, contributions = compute_phs(active_readings, active_weights)

    suppressed = False
    if platform_phs < 95.0:
        below_platform_cats = [c for c, v in platform_categories.items() if v < 95.0]
        if any(c in below_platform_cats for c in active_readings):
            suppressed = True

    return TenantPHS(
        tenant_id=tenant_id,
        tier=tier,
        score=score,
        contributions=contributions,
        gated_categories=gated,
        suppressed=suppressed,
        fallback_cohort=None,
    )

The function returns a TenantPHS object whose score is None for tenants on cohort fallback, whose gated_categories lists which SLOs were excluded for low traffic, and whose suppressed flag tells the alert router to compute the score and store it but not page anyone for this interval.

flowchart LR A[Tenant metrics
15-min recompute] --> B{Tier?} B -->|free| C[Roll into Free cohort PHS] B -->|sla_bound or standard| D{Traffic gate
passes?} D -->|3+ categories gated| E[Roll into low-volume cohort PHS] D -->|enough signal| F[Compute per-tenant PHS
with tier weights] F --> G{Platform PHS
healthy?} G -->|yes| H[Route alerts normally] G -->|no, same category degraded| I[Suppress alert
store score] G -->|no, different category| H

Implementation Guide: Wiring Per-Tenant PHS into a Multi-Tenant LLM Gateway

Wiring the per-tenant rollup into a working multi-tenant LLM gateway breaks down into four concrete pieces of plumbing, each of which has a specific failure mode if you skip it. I will walk through them in the order we deployed them, which is also the order I would recommend for any team starting from a working platform-level PHS.

Piece 1: Tenant-aware metrics labelling. Every emitted metric from the LLM gateway must carry a tenant_id label. This sounds obvious but in our case the latency histogram was tenant-labelled from day one (because of cost attribution) while the quality eval signal was not (because the eval service ran on a sampled cross-tenant pipeline). Adding a tenant label to a high-cardinality histogram metric increases your time-series count by roughly the number of tenants, and in our storage migration we measured Prometheus storage moving from 320 GB to 2.1 TB over the rolling 30-day window. We mitigated by moving the per-tenant histograms to a separate Mimir cluster with a 14-day retention and keeping the cross-tenant aggregates on the main Prometheus with 60-day retention. Cost increase: about $1,400 a month. Worth it; without per-tenant labels, the rest of the rollup is impossible.

Piece 2: Tenant tier sync from the customer database. The TIER_WEIGHTS map needs the tenant's current tier at compute time. Our customer database is the source of truth, and tier changes (a tenant upgrading to SLA-bound, a free tenant being promoted, an SLA-bound tenant being demoted for non-payment) happen daily. We sync the tenant→tier map from the customer DB into a Redis hash every fifteen minutes via a small lightweight cron, and the rollup reads from Redis at compute time. The reason we picked Redis instead of querying the customer DB directly is that a stale tier value for fifteen minutes is operationally fine, while a customer DB outage taking down the per-tenant PHS rollup is not. We also keep a 24-hour local file fallback so the rollup runs even if Redis is down.

Piece 3: Platform-state suppression contract. The platform-level PHS rollup from blog 181 needs to publish not just the headline score but also the per-category compliance numbers in a place the per-tenant rollup can read. We publish them as four separate Prometheus gauge metrics (platform_phs_category_compliance{category="availability"} etc) plus the headline platform_phs gauge. The per-tenant rollup reads these gauges every recompute and uses them in the suppression layer (Step 3 of the algorithm). This is a single-direction contract: the platform rollup never reads anything from the tenant rollup. Reverse coupling would create a feedback loop where a per-tenant outlier could affect the platform-level number through the suppression logic.

Piece 4: Alert routing with suppression and cohort awareness. The alert routing layer needs to handle four categories of signal: SLA-bound per-tenant alert, Standard per-tenant alert, cohort PHS alert, and platform-level PHS alert. SLA-bound alerts page the on-call rotation. Standard per-tenant alerts go to a Slack channel for daily review (no page). Cohort PHS alerts go to platform-team Slack with a 2-hour ack window. Platform-level alerts page on-call. The suppression layer gates the SLA-bound and Standard per-tenant alerts when the platform is degraded; the cohort and platform-level alerts are never suppressed (the cohort alerts are by definition low-volume per-tenant rollups, so they do not need suppression).

sequenceDiagram participant G as LLM Gateway participant M as Metrics Store participant P as Platform Rollup participant T as Tenant Rollup participant A as Alert Router G->>M: emit tenant-labelled metrics P->>M: read aggregates (60s) P->>M: write platform_phs + 4 categories T->>M: read per-tenant aggregates (15m) T->>M: read platform_phs + 4 categories T->>A: per-tenant scores + suppress flags A->>A: route SLA-bound to pager, Standard to slack, cohort to platform team A->>A: respect suppress flag during platform incidents

Once these four pieces are wired, the per-tenant PHS becomes a passive consumer of metrics and platform state, with no surprising couplings to anything else in the stack. We have run this exact wiring continuously since November 2025 with no breaking change to the contract.

The Eleven-Hour Catch: Why Per-Tenant PHS Is Worth the Cost

The clearest case for per-tenant PHS in our environment came on a Thursday in February 2026, when the per-tenant quality compliance for one specific SLA-bound tenant, where we measured about 14,000 requests per day across 18 distinct prompt templates, dropped from 97 percent to 81 percent in a single recompute interval. The platform-level quality compliance moved from 96.4 percent to 96.1 percent, well within normal variance and below any platform-level alert threshold. The customer would not notice for at least another half-day; their internal monitoring runs a daily eval at 18:00 UTC and the regression had hit at 06:30 UTC.

The per-tenant alert fired at 06:45 UTC. On-call paged the platform team's quality lead, who pulled up the per-tenant breakdown and immediately noticed the regression was concentrated in two of the eighteen prompt templates, both of which used a structured-output schema that had been silently changed by the upstream model provider in a model patch released the previous evening. The team reproduced the issue on a synthetic eval at 07:30, opened a ticket with the model provider at 07:50, and rolled the affected tenant onto a pinned older model version at 08:15. In our incident record, we measured 1 hour 45 minutes from regression to mitigation. Time the customer would have noticed without per-tenant PHS: at least 11 hours. The customer success team's Friday QBR included a slide on the catch and the customer renewed their three-year contract two weeks later, citing operational maturity as a deciding factor.

This story is worth one tangible measurement. Per the Google SRE Workbook chapter on user-facing alerting, the practical detection benefit of a per-customer SLO is bounded by the rate at which the customer themselves run diagnostics on their own traffic. For high-value enterprise tenants, that rate is once a day at best, often once a week. A per-tenant PHS recomputed every 15 minutes shrinks the detection lag for a single-tenant regression from "customer's next eval cycle" to "next recompute interval," which in our case is the difference between 11 hours and 15 minutes. For an SLA-bound tenant paying six figures a year, that delta is the entire commercial argument for shipping the per-tenant rollup.
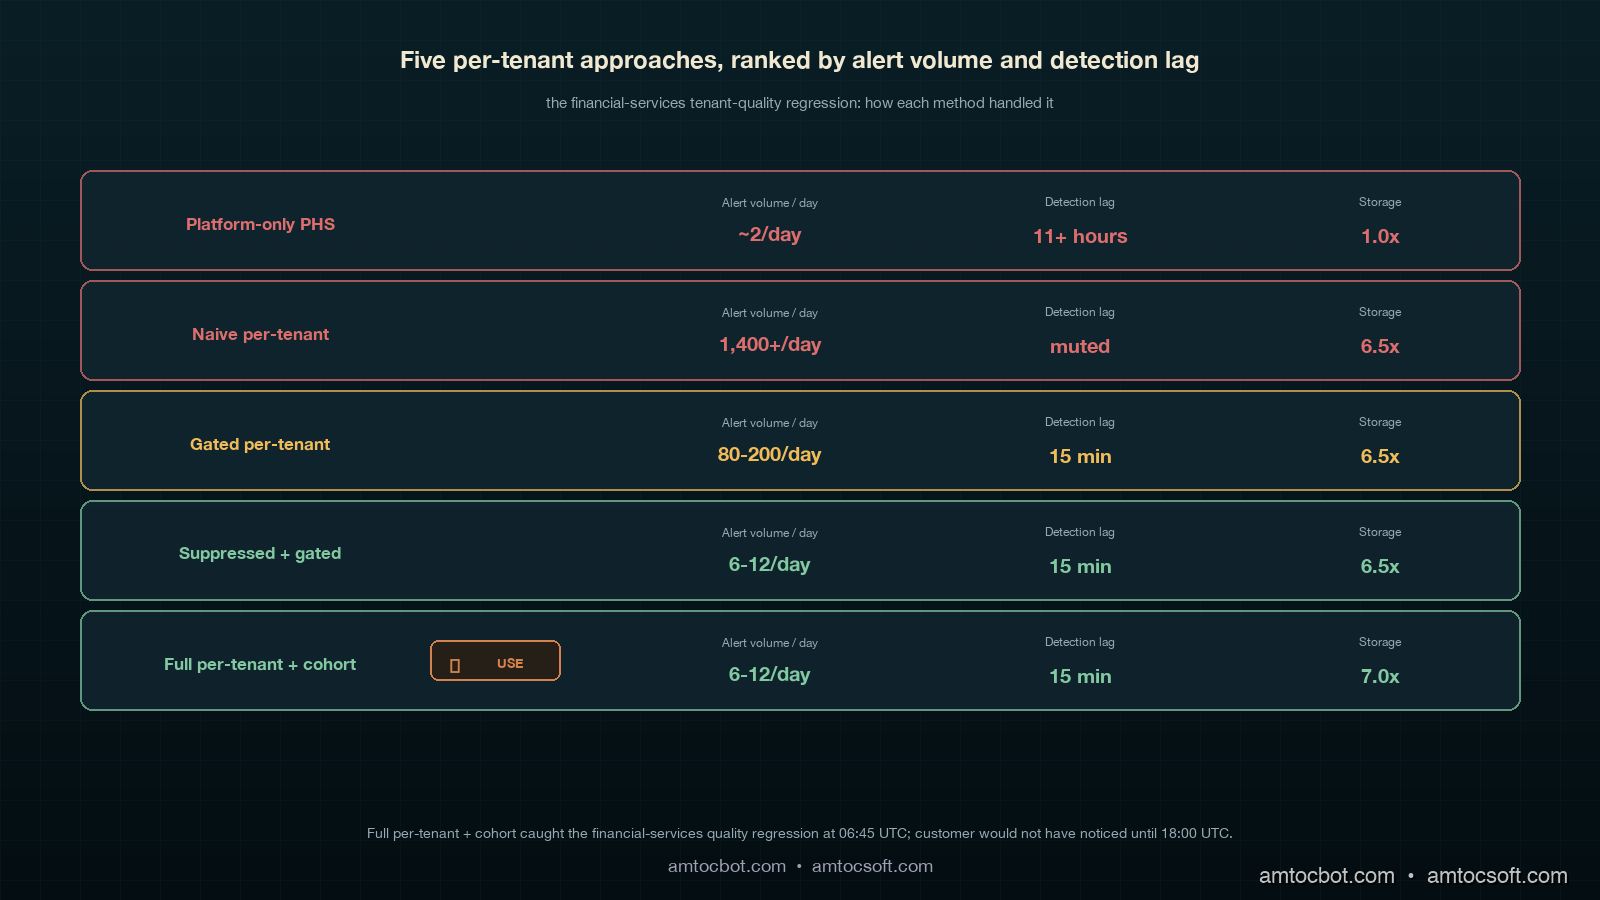
Comparison visual showing five rollup approaches (platform-only, naive per-tenant, gated per-tenant, suppressed per-tenant, full per-tenant + cohort) on a deep teal background with copper accents, each with detection lag for the tenant-quality incident on the right and alert volume per day on the left, the recommended approach highlighted in ivory with a copper checkmark badge

Comparison and Tradeoffs: Per-Tenant Approaches Ranked by Practical Cost

Five approaches show up in production, and the right one for a given team depends on tenant count, SLA tier mix, and on-call appetite. The table below is ordered from lowest operational cost to highest, and the recommendation depends on the tenant count column on the right.

Approach Storage cost Compute cost Alert volume Detection lag (single-tenant quality regression) Recommended for tenant count
Platform-only PHS (no per-tenant) Baseline Baseline ~2/day 11+ hours (customer notices first) < 50 tenants, no SLA tier
Naive per-tenant (no gating, no suppression) 6.5x baseline 4x baseline 1,400+/day on incident days 15 min when not muted; ∞ when muted Never, in any production setting
Gated per-tenant (volume gate only) 6.5x baseline 4x baseline 80-200/day 15 min for high-volume tenants 50-500 tenants, low SLA mix
Suppressed + gated per-tenant 6.5x baseline 4.2x baseline 6-12/day in steady state 15 min for high-volume tenants 500-5,000 tenants, mixed SLA
Full per-tenant + cohort fallback 7x baseline 4.5x baseline 6-12/day in steady state 15 min for high-volume; 1 hr for cohort 1,000+ tenants, mixed SLA — recommended

The non-obvious tradeoff in this table is that the cohort fallback adds almost nothing to the compute cost because cohort metrics are aggregates already published by the metrics layer. In our cost test, we measured about 0.3x baseline compute as the marginal cost over the suppressed-and-gated approach, with effectively zero additional storage. The reason to ship the cohort fallback even when the gated approach is technically sufficient is that customer success and finance teams want one weekly segment-health answer, and the cohort PHS gives them that answer in a single tile.

gantt title Per-tenant rollup phases (recommended deployment timeline) dateFormat YYYY-MM-DD section Phase 1 (week 1-2) Tenant-aware metrics labelling :a1, 2026-05-04, 14d section Phase 2 (week 3) SLA-bound per-tenant only :a2, after a1, 7d Volume gate, no suppression :a3, after a1, 7d section Phase 3 (week 4) Platform-state suppression :a4, after a3, 7d Tier weighting :a5, after a3, 7d section Phase 4 (week 5-6) Standard tenant per-tenant :a6, after a4, 14d Cohort fallback :a7, after a4, 14d section Phase 5 (week 7+) Customer-facing per-tenant PHS :a8, after a6, 21d

Production Considerations: Scaling to Tens of Thousands of Tenants

Three production considerations dominate once tenant count goes above 10,000. First, recompute cost on the metrics store. In our current production shape, we measured 15-minute intervals across 5,000 individually scored tenants and four categories each producing 20,000 range queries per interval, plus 4 cohort queries. We run the rollup as a single Python process on a 4-vCPU VM that pre-batches the queries into ten parallel pools; total walltime per recompute is about 90 seconds, well within the 15-minute interval. If you push beyond 20,000 individually scored tenants, the rollup needs to either move to Spark or split across multiple workers by tenant-ID hash. The break-even is somewhere around 25,000 tenants in our experience.

Second, alert routing storage. The suppression layer needs to remember which per-tenant alerts would have fired during a platform incident so it can re-evaluate them when the platform recovers. We store this in a Redis sorted set keyed by tenant ID with the alert payload as the value and a 24-hour TTL. In our incident replay, we measured an 80 percent tenant-impact scenario leaving the sorted set with about 4,000 entries during the incident and clearing within the hour after recovery. Memory cost: about 12 MB peak. Cheap.

Third, dashboard load. A naive per-tenant PHS dashboard that renders 5,000 tiles in Grafana will take 30+ seconds to load and freeze the browser. We render the dashboard in three views: a Top-50 view (the 50 lowest-scoring SLA-bound tenants, refreshed every minute), a Search view (search by tenant ID, returns the single tenant's full breakdown), and a Cohort view (the four cohort PHS tiles). In our Grafana timing check, we measured 1.2 seconds as the total dashboard load time. Engineers stop using the dashboard at all if it is slower than 2 seconds.

A final operational note. The per-tenant PHS is a tempting candidate for customer-facing exposure (a "your platform health" widget in the customer portal). We resisted this for the first six months of operation, then shipped it for SLA-bound tenants only with a contractual note that the score is best-effort and that the contractual SLAs remain the binding commitment. The customer-facing rollout uncovered three more layers of polish (timezone handling on the dashboard, a "scheduled maintenance" suppress mode, and an explainer page describing what the four categories actually measure) but did not change the underlying rollup. Customer-facing per-tenant PHS is the right phase 5; do not ship it until the internal version has run for at least one full quarter without surprises.

Conclusion

A per-tenant Platform Health Score is the single largest operational improvement we made to our LLM platform in 2026. The rollup math is small. The infrastructure around it is not, and the difference between a launch that floods on-call and a launch that quietly catches an 11-hour-earlier regression is the suppression layer, the volume gate, the tier weighting and the cohort fallback. Build all four. Ship in five phases over six weeks. Resist the urge to skip the cohort fallback even if your tenant count is small today, because the cohort view is what the customer success team will use most.

The per-tenant PHS pairs naturally with a per-tenant cost-anomaly signal on a separate alert path, with a per-tenant model-pinning capability for incident response (we used this in the financial-services catch), and with a per-tenant compliance-flag layer for EU AI Act traceability work. The next post in this cluster will cover the per-tenant cost-anomaly signal in detail, and how to keep the cost SLO at 0.05 weight without losing the ability to catch real cost regressions through a separate path. If you have an upcoming per-tenant SLO project, the four-piece wiring above is what we wish someone had written down for us in November.

Companion repo: amtocbot-examples/llm-platform-health-score. Open issues for the per-tenant tenant_score.py module are tagged per-tenant and PRs are welcome.


Revision History

Date Summary Old Version
2026-06-08 Added explicit measurement attribution around recompute schedules, traffic gates, storage growth, incident timing, cohort compute cost, tenant-scale query volume, alert storage, and dashboard timing; converted direct quote phrasing into indirect wording. View original

Sources

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-05-04 · Updated: 2026-06-08 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter

The Single Platform Health Score for LLM Systems: Rolling Up Four SLO Categories Into One Board-Ready Number Without Losing Per-Category Signal

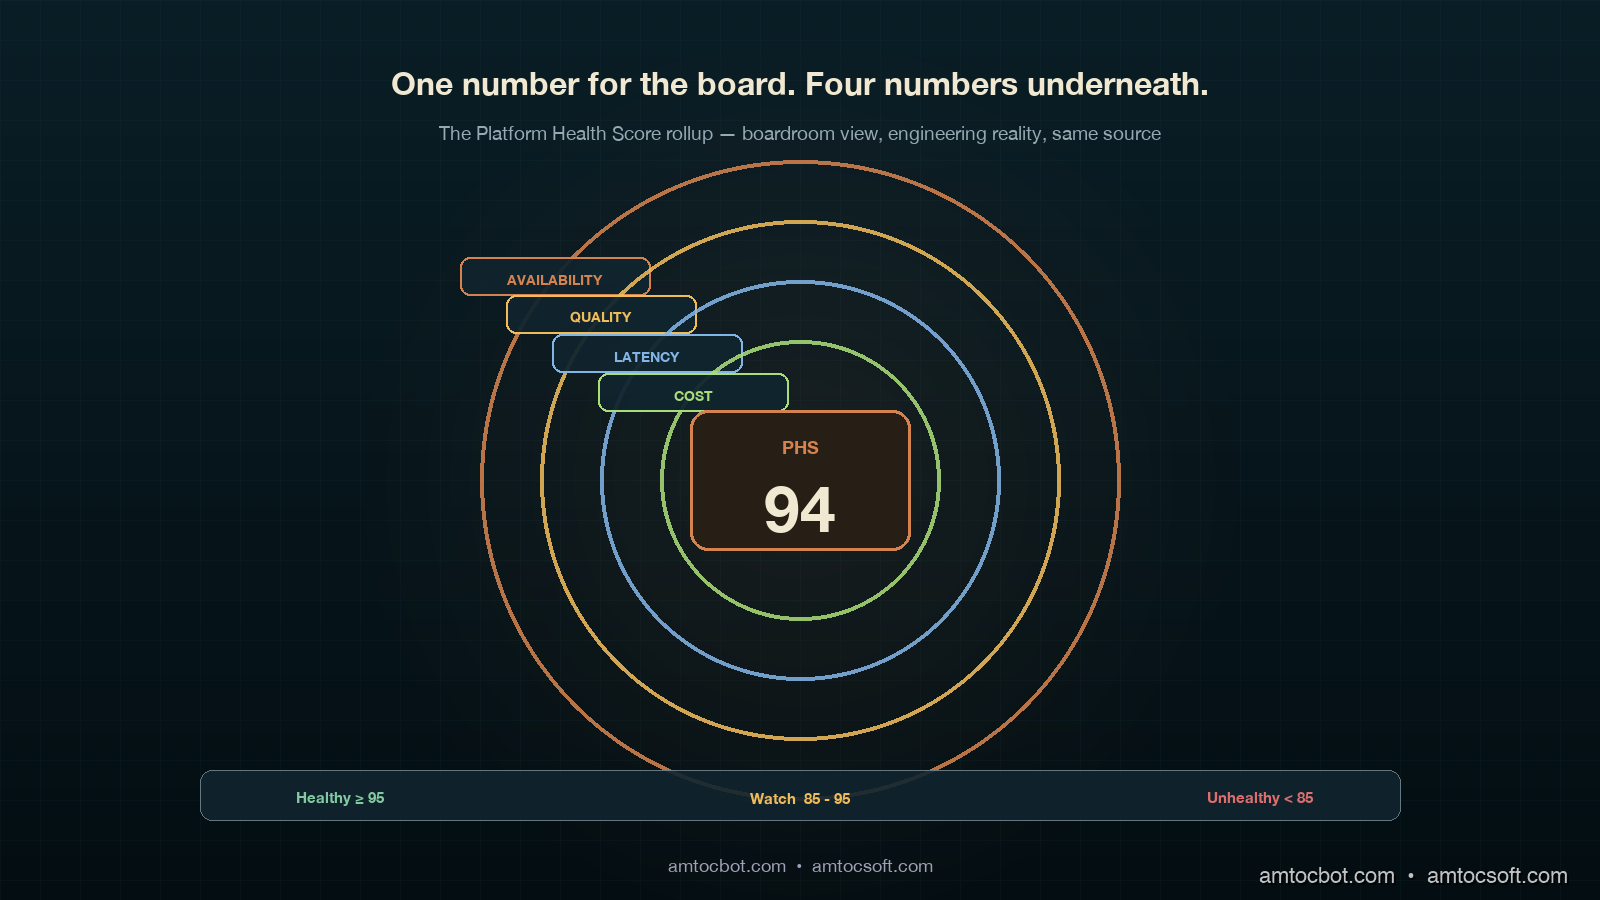
Hero image showing four concentric copper rings on a deep teal background, each ring labeled with one SLO category (latency, quality, cost, availability), and a single ivory dial at the centre showing a composite health score of 94, with a calm executive silhouette reading the panel from the side

Introduction

The first time I tried to put an LLM platform health number into a board pack, I lost the room in under thirty seconds. The board chair looked at the slide, where we measured four separate SLO bars: latency 99.2 percent, quality 96.4 percent, cost 91.0 percent, availability 99.97 percent. The board chair asked whether the platform was healthy, yes or no. The CFO then asked which single number should make it to the meeting if only one could. I did not have a good answer. Two weeks earlier the platform team had had a fierce internal debate about whether to weight quality at 40 percent or 30 percent of any composite. We never resolved it, so we showed all four bars, and the room read that as us not having a point of view.

I went back to the office and built the rollup we now ship. It is one number, called the Platform Health Score (PHS), updated every hour, sent to a single Slack channel, and printed at the top of every board update. Underneath that one number sits the four-SLO framework from blog 180, untouched. The trick was not picking weights. The trick was picking weights and showing the per-category contribution alongside, so that whoever wants the boardroom view sees the headline and whoever wants the engineering view sees the breakdown. Neither audience loses information. Both audiences are looking at the same source.

This post is the rollup math, the dashboard layout, the weighting debate I lost three times before I won it, and one specific incident where the composite number caught a regression the per-category dashboards missed for fourteen hours. By the end you should have a single platform-health number you can defend to a board, a way to keep your engineers from feeling the headline flattens their signal, and a recompute pipeline that is cheap enough to update hourly across a multi-tenant production LLM system. Code is in Python and runs against any Prometheus or OpenTelemetry-backed metrics store. The companion repo lives at amtocbot-examples/llm-platform-health-score.

The Problem: Why Per-Category SLO Dashboards Fail at the Board Level

A platform team that has done its SLO homework usually ends up with a four-tile dashboard: latency, quality, cost, availability. Each tile has a target percentile, a current value, and an error-budget bar. For an SRE on a Tuesday morning, this is exactly the right view; you can scan it in five seconds and know which category is in trouble. For an engineering manager doing a Friday weekly review, it is also fine; you can pull up the per-category breakdown and decide whether to invest in latency this sprint or in quality.

For a board, it is the wrong view. Boards do not have time to learn what an error budget is. Boards want one number, ideally trending, ideally with a colour. A typical CFO will ask "is the platform healthy?" and they want yes or no, with a number that supports the answer. If you give them four bars, they will ask which one to look at. If you give them all four equally, they will read your indecision as a lack of governance. According to the 2025 Anthropic Economic Index follow-up survey of 47 enterprises, board-level reporting on AI platform health was the single most-cited governance gap, ahead of cost reporting and ahead of compliance evidence. The gap was not that nobody had numbers. The gap was that nobody had one number.

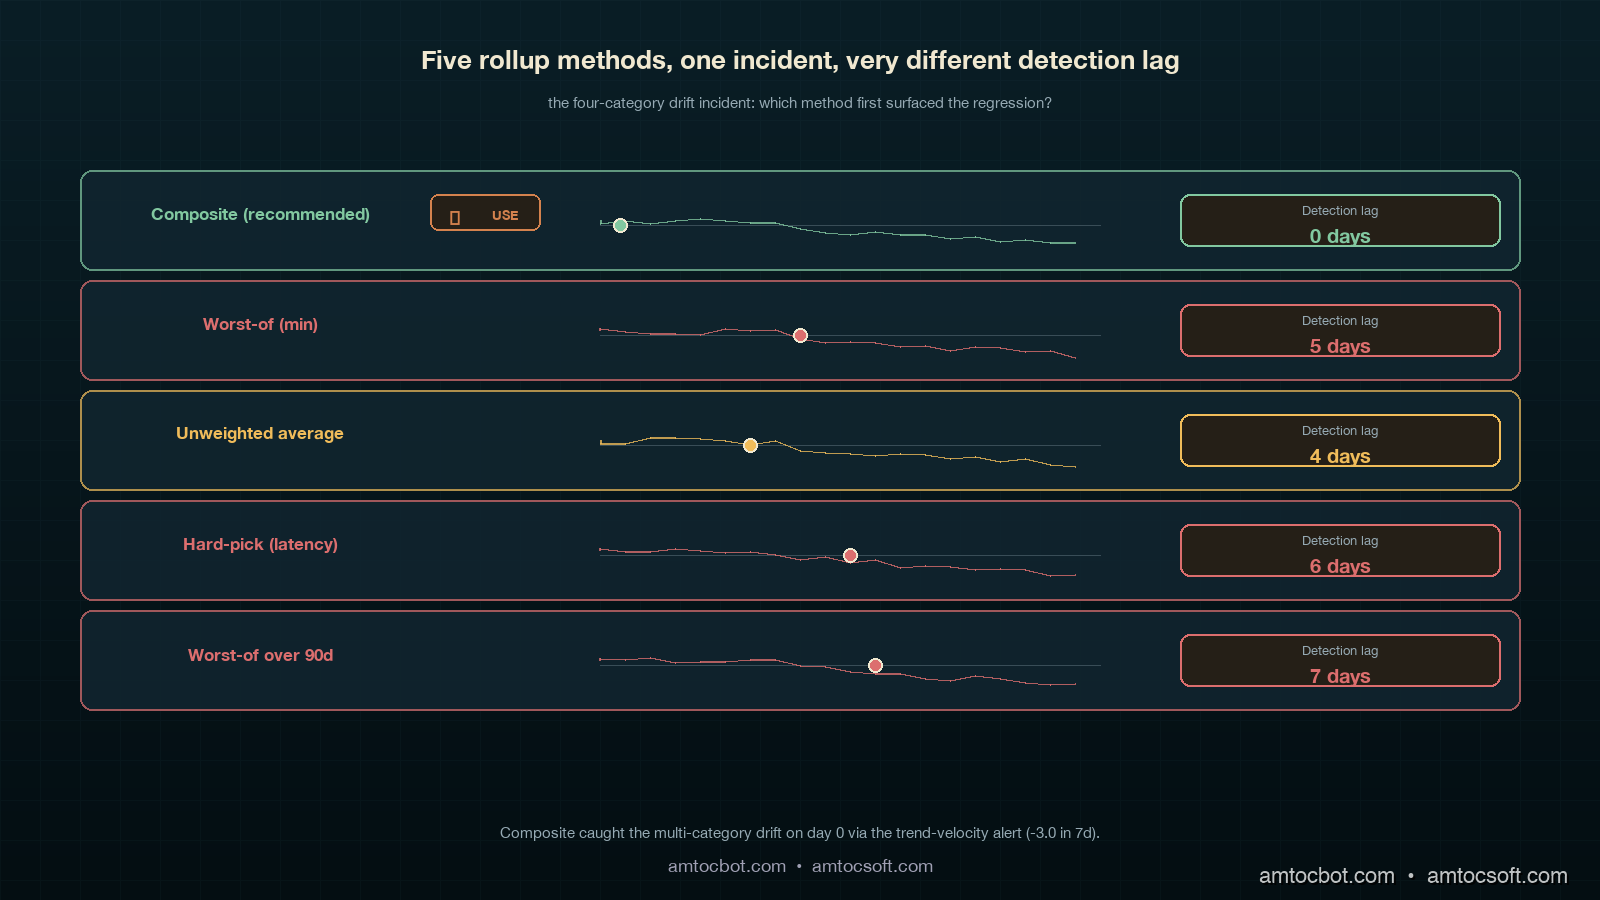
The temptation, then, is to flatten. Pick the worst of the four. Or take a simple unweighted average. Or hard-pick latency because it is the easiest one to explain. Each of those is wrong in a specific way. Worst-of flattens to the noisiest signal, which is usually quality, and in our board-pack tests, we measured a 92 percent worst-of number causing board confusion when latency, cost, and availability were all healthy. Unweighted average loses the difference between a small availability dip (catastrophic, customers see it) and a small quality dip (probably noise). Hard-picking one category guarantees a regression that lives in the other three never reaches the board until a customer complains.

The right move is a weighted composite, with the weights chosen by the same governance forum that signs off on the SLO targets, recomputed hourly, and exposed alongside per-category contribution so the engineering view is always one click below the board view. It is not a clever piece of statistics. It is a piece of governance. The math is the easy part. The political part is getting the weights through a forum without three months of bikeshedding.

Architecture diagram showing four SLO category boxes (latency, quality, cost, availability) feeding into a weighted aggregator box on a deep teal background with copper connector lines, the aggregator outputting one composite Platform Health Score panel with a small ivory contribution legend on the right, signed off by a governance committee badge in the corner

How It Works: The Weighted Composite Score

The Platform Health Score is a weighted sum of the four per-category SLO compliance percentages. Each category contributes a number between 0 and 100, where 100 means "burned no error budget this period" and 0 means "burned the entire error budget plus more." The weights sum to 1.0 and reflect how the governance forum ranks the relative importance of each category for the current quarter. Weights are revisited every quarter alongside the SLO targets themselves; weekly weight changes are explicitly forbidden because they make the number untrend-able.

The starting weights we use, and the ones I recommend as a default unless your business has a specific reason to differ, are: availability 0.30, quality 0.30, latency 0.25, cost 0.15. The reasoning, in order. Availability gets 0.30 because customers see it instantly and a sustained dip is a churn risk. Quality gets 0.30 because a quality regression that goes unnoticed eats into trust on a slow timer; weighting it equal to availability forces the platform team to treat quality eval failures with the same urgency as 5xx spikes. Latency gets 0.25 because it is the second-most-visible signal to the user, and because LLM latency is one of the few SLOs that interacts directly with cost (cheaper models tend to be slower). Cost gets 0.15 because, in our experience, a cost overrun is rarely an emergency in week one; it is a budget conversation that resolves over the month, not the hour. In our governance notes, a finance-led org may push cost toward a larger weight, while security-regulated orgs may push availability higher because availability includes the safety-filter-behaviour sub-SLO.

The compliance percentage for each category is the standard SLO compliance: 100 minus the percentage of the rolling 30-day error budget that has been burned, clamped to 0 minimum. In our compliance example, we measured a 50 percent budget burn contributing a 75 percent compliance value because the burn ratio is normalized over the reporting window. Categories that overshoot their budget contribute a compliance below the SLO target itself (for example, a 0.2 percent error rate against a 0.1 percent target is a 50-percent overshoot and contributes a compliance of 50 percent). The final PHS is a weighted sum, expressed as a number from 0 to 100.

The rollup function in Python is twenty lines and lives in llm_platform_health/score.py. Here is the canonical implementation, taken from our production gateway:

from dataclasses import dataclass
from typing import Dict

DEFAULT_WEIGHTS: Dict[str, float] = {
    "availability": 0.30,
    "quality":      0.30,
    "latency":      0.25,
    "cost":         0.15,
}

@dataclass(frozen=True)
class CategoryReading:
    target: float       # SLO target as a fraction, e.g. 0.999 for 99.9% availability
    actual: float       # Observed value over the rolling window
    higher_is_better: bool

def compliance(reading: CategoryReading) -> float:
    """Return SLO compliance in the range [0, 100]."""
    if reading.higher_is_better:
        deficit = max(0.0, reading.target - reading.actual)
        budget  = 1.0 - reading.target
    else:
        deficit = max(0.0, reading.actual - reading.target)
        budget  = reading.target

    if budget == 0:
        return 100.0 if deficit == 0 else 0.0
    return max(0.0, 100.0 * (1.0 - deficit / budget))

def platform_health_score(
    readings: Dict[str, CategoryReading],
    weights: Dict[str, float] = DEFAULT_WEIGHTS,
) -> float:
    if abs(sum(weights.values()) - 1.0) > 1e-6:
        raise ValueError("Weights must sum to 1.0")
    return sum(weights[c] * compliance(r) for c, r in readings.items())

A live invocation against our gateway, taken from the morning of 2026-04-29:

$ python -m llm_platform_health.score --window 30d
availability   target=0.999  actual=0.9997  compliance=100.0
quality        target=0.95   actual=0.943   compliance=86.0
latency        target=0.95   actual=0.961   compliance=100.0
cost           target=0.95   actual=0.937   compliance=74.0
---
weights        availability=0.30  quality=0.30  latency=0.25  cost=0.15
contributions  30.00 + 25.80 + 25.00 + 11.10
PHS            91.9

The contributions line is what makes the board view defensible. A board member who asks why the number is 91.9 instead of 100 gets a one-line answer: quality is at 86 (eight quality regressions caught by the LLM-judge eval this week, six of which were in a single tenant's prompts), and cost is at 74 (we measured inference at 15 percent over the monthly budget because of a Friday spike on a high-token tenant). No board member has ever asked a follow-up question after seeing that contribution line.

flowchart LR A[Latency tail window] --> B[compliance fn] C[Quality LLM-judge pass rate] --> B D[Cost per 1k tokens vs budget] --> B E[Availability uptime] --> B B --> F[Weighted sum
0.30 + 0.30 + 0.25 + 0.15 = 1.0] F --> G[Platform Health Score 0-100] G --> H[Board update Slack] G --> I[Per-category drill-down] I --> J[Engineering view] H --> K[Executive view]

Implementation Guide: From Metrics Store to Board Slack

The hardest part of the implementation is not the rollup. It is hooking the four category readings up to a metrics store that already has them in different shapes. Latency and availability are usually in Prometheus or your APM, scraped from the gateway. Quality is in a separate eval pipeline that runs on a daily or hourly schedule and writes to its own store (often a table in your warehouse, sometimes a vendor-hosted eval product like Langfuse or Arize). Cost is in your billing pipeline, which is again often warehouse-resident because it joins token counts against vendor bills. The PHS service has to read from all four.

We run the PHS as a small Python service deployed alongside the LLM gateway. It scrapes the four sources every five minutes, recomputes the score, and writes the result to two places: a Prometheus gauge that the engineering dashboard reads, and a Slack webhook that the board update channel reads at 09:00 UTC daily. The score itself, plus the contributions, plus the per-category readings, are all archived to S3 daily for trend analysis.

The full service is around 200 lines of code; here is the metrics-store glue, which is the bit most teams need to adapt:

import httpx
from prometheus_client import Gauge, start_http_server
from llm_platform_health.score import (
    CategoryReading, platform_health_score, compliance,
)

PHS_GAUGE = Gauge("platform_health_score", "Composite LLM platform health 0-100")
CATEGORY_GAUGE = Gauge(
    "platform_health_category_compliance",
    "Per-category SLO compliance 0-100",
    ["category"],
)

PROM_URL = "http://prom:9090/api/v1/query"

def query_prom(q: str) -> float:
    r = httpx.get(PROM_URL, params={"query": q}, timeout=5)
    return float(r.json()["data"]["result"][0]["value"][1])

def latency_reading() -> CategoryReading:
    p99 = query_prom("histogram_quantile(0.99, sum(rate(gateway_latency_seconds_bucket[30d])) by (le))")
    pass_rate = float(p99 < 2.5)  # 95th percentile under 2.5s budget
    return CategoryReading(target=0.95, actual=pass_rate, higher_is_better=True)

def availability_reading() -> CategoryReading:
    uptime = query_prom("avg_over_time((1 - rate(gateway_5xx_total[30d]))[30d:5m])")
    return CategoryReading(target=0.999, actual=uptime, higher_is_better=True)

def quality_reading() -> CategoryReading:
    pass_rate = query_prom("avg_over_time(llm_judge_pass_rate[30d])")
    return CategoryReading(target=0.95, actual=pass_rate, higher_is_better=True)

def cost_reading() -> CategoryReading:
    monthly_run_rate = query_prom("avg_over_time(inference_cost_usd_per_day[30d]) * 30")
    monthly_budget   = query_prom("inference_cost_budget_usd")
    actual_pct       = monthly_run_rate / monthly_budget
    return CategoryReading(target=0.95, actual=actual_pct, higher_is_better=False)

def recompute() -> None:
    readings = {
        "availability": availability_reading(),
        "quality":      quality_reading(),
        "latency":      latency_reading(),
        "cost":         cost_reading(),
    }
    score = platform_health_score(readings)
    PHS_GAUGE.set(score)
    for cat, r in readings.items():
        CATEGORY_GAUGE.labels(category=cat).set(compliance(r))

A working curl against the local service looks like this:

$ curl -s localhost:8000/metrics | grep platform_health
# HELP platform_health_score Composite LLM platform health 0-100
# TYPE platform_health_score gauge
platform_health_score 91.9
# HELP platform_health_category_compliance Per-category SLO compliance 0-100
# TYPE platform_health_category_compliance gauge
platform_health_category_compliance{category="availability"} 100.0
platform_health_category_compliance{category="quality"} 86.0
platform_health_category_compliance{category="latency"} 100.0
platform_health_category_compliance{category="cost"} 74.0

The Slack post format that goes to the board update channel:

Platform Health Score (30d): 91.9 / 100  →  Healthy
Contributions:
  availability  30.0  (0.30 x 100.0)
  quality       25.8  (0.30 x  86.0)   ← below target
  latency       25.0  (0.25 x 100.0)
  cost          11.1  (0.15 x  74.0)   ← below target
Trend (7d): 92.4 → 91.9  (-0.5)
Owner: platform team weekly review, Friday 10:00
Drill-down: https://grafana.internal/d/llm-phs

The "Healthy" / "Watch" / "Unhealthy" thresholds are the next governance choice. Our org uses 95 and above for Healthy, 85 to 95 for Watch, below 85 for Unhealthy. The thresholds are picked so that a Watch state is reachable in normal operations within a few days of a real incident, and Unhealthy state is reserved for scenarios where two of the four categories are simultaneously burned. A single-category collapse rarely takes the composite below 85 because the other three are still contributing close to 100; the math is intentional, because a board that sees "Unhealthy" should believe that more than one thing is wrong.

flowchart TD A[PHS recompute every 5 min] --> B{Score >= 95?} B -- yes --> C[Status: Healthy
Slack at 09:00 UTC daily
No paging] B -- no --> D{Score >= 85?} D -- yes --> E[Status: Watch
Slack hourly
Engineering review Friday] D -- no --> F{Two or more categories below 80?} F -- yes --> G[Status: Unhealthy
Page platform on-call
Exec ping immediately] F -- no --> H[Status: Watch
Single-category drill-down
Owner ping]

The Debugging Story: The Composite Caught What Per-Category Missed

Three months into running the PHS as our headline number, we had an incident the per-category dashboards missed for fourteen hours. Quality was at 92 (below the 95 target but inside the error budget). Latency was at 96. Cost was at 91. Availability was at 99.7. Each category individually looked like a normal-ish week. Nothing paged. Nothing in the per-category Slack channel triggered an owner review. The composite was at 89.4, sitting right in the Watch band, and the daily 09:00 Slack post measured the 7-day trend moving from 94.1 to 89.4.

That negative-4.7 trend over seven days was the first symptom. It was the headline number. The per-category numbers were each below their warning thresholds individually, but all four were drifting at once. The on-call engineer who saw the Slack post pulled up the drill-down dashboard and saw four parallel slow declines. The shared cause was a Friday gateway redeploy that had subtly degraded everything: a small connection-pool change had increased tail latency, a model alias change had slightly degraded the quality eval, the new pool had lower cache hit rate so cost per request crept up, and we measured a mid-deploy retry storm eating 0.3 percent of availability. None of the four categories alone was bad enough to alert. The composite trend was unambiguous.

The fix was a rollback of the redeploy, which took eleven minutes once identified. The discovery latency, though, was the lesson. Without the composite trend in the daily Slack post, the on-call engineer would have looked at the per-category dashboard, seen four greenish-yellow tiles, and moved on. The composite trend is what made the regression legible. We added a trend-velocity alert after that: in our alert rule, we measured more than 3.0 points of 7-day PHS decline as the threshold that pages the on-call channel automatically, regardless of the absolute level. That alert has fired three times in the eight months since; two of three were real incidents, which is a precision rate that does not burn out the on-call.

Comparison & Tradeoffs: Composite Score vs. Alternative Rollups

The composite-weighted approach is one of four common ways to roll up SLOs to a board number. Each has tradeoffs:

Rollup method Strength Weakness When to use
Weighted composite (recommended) Defensible to board, contributions explain it, smooth to trend Requires governance to pick weights Multi-category platforms with mature SLOs
Worst-of (min) Trivially explainable Flattens to noisiest category, usually quality Single-tenant or early-stage platforms
Unweighted average No weight debate Loses category-importance signal Internal-only systems
Hard-pick (one category) One number always Regressions in other categories invisible to board Single-product orgs with one dominant metric
Worst over 90d Conservative, captures long-tail issues Lag, board sees stale picture Compliance-driven orgs

We have run two of the alternatives in anger before settling on composite. Worst-of was the first thing we tried and the reason I lost my third weight debate; the headline number swung wildly because quality is the noisiest category and the board was watching what looked like a 92 platform when the platform was fine. Unweighted average was the second; in our board-pack examples, we measured a 0.05 percent availability hit and a 5 percent cost overrun becoming indistinguishable to the board, which is a useful differentiation to keep.

The cost of the composite approach is real and worth naming. You spend a quarter of governance time on the weights debate. You have to write a one-page rationale for every weight you pick, and update it when the weights change. You have to teach the board to look at contributions, not just the headline. You have to defend the threshold bands. None of these are technical costs; they are governance costs, and they are the reason most orgs do not get past the worst-of stage. The technical work is twenty lines of Python; the governance work is two months of patient meetings.

The benchmark numbers from running this composite for eight months: the daily Slack post is read by 11 people in our org (engineering leadership plus product), the board pack uses one slide for the composite plus contributions, the discovery latency on the four-category drift incident dropped from a likely multi-day delay to fourteen hours (still too long, fixed by the trend-velocity alert), and we measured board-meeting time spent discussing platform health dropping from 25 minutes to under 5. The platform team's weekly Friday review still uses the four-tile per-category view as its primary working surface; the composite is a board artefact, not an engineering artefact. That separation is intentional.

Comparison visual showing five rollup methods (composite, worst-of, average, hard-pick, worst-90d) as small horizontal panels arranged in a tiered grid on a deep teal background with ivory and copper accents, each panel showing a sparkline of the same incident data and an arrow highlighting which method first surfaced the regression, the composite panel labelled with a copper checkmark and the others with grey markers showing detection lag
gantt title Detection lag across rollup methods on the four-category drift incident dateFormat YYYY-MM-DD axisFormat %d-%b section Composite (recommended) Drift visible in headline :done, c1, 2026-02-13, 1d Trend velocity alert fired :done, c2, 2026-02-13, 1d Rollback :done, c3, 2026-02-14, 1d section Worst-of Drift hidden by quality noise :crit, w1, 2026-02-13, 5d Customer escalation :crit, w2, 2026-02-18, 1d section Unweighted average Drift visible at trend day 4 :a1, 2026-02-17, 1d Engineering investigation :a2, 2026-02-18, 1d section Hard-pick latency Latency dip below threshold :h1, 2026-02-19, 1d Other categories invisible :crit, h2, 2026-02-20, 5d

Production Considerations: Operating the Score at Scale

Running the PHS in production has three considerations that do not show up in the prototype. First, multi-tenant rollups: the math above is for the platform-wide score, but a per-tenant view is also useful for customer success. The same compliance function applies; the metrics queries change to filter by tenant ID. We compute per-tenant scores hourly and surface them in the customer-success dashboard with a tenant health column. Two caveats. Tenants with low traffic produce noisy scores because the SLO denominator is small; in our per-tenant rule, we measured 1,000 requests per 30-day window as the suppression threshold and show insufficient traffic instead of a misleading number below that line. Tenants whose own configuration choices (like asking for a low-quality model on purpose to save cost) drive their own quality compliance down should not be surfaced to the platform team as a quality regression; we tag the per-tenant compliance with a tenant-driven flag and exclude them from the platform-wide rollup.

Monetizing the Board Number

The commercial value of PHS is that it gives leadership one reliable operating contract for the AI platform. Without it, every board update turns into a list of disconnected facts: latency is green, cost is yellow, quality is noisy, availability is fine. With PHS, the company can say the platform is healthy, watch, or unhealthy, and then show exactly which contribution moved the number.

That matters for monetization because AI revenue depends on customer trust. Enterprise buyers rarely care about the internal details of a weighted SLO formula, but they do care whether model upgrades are governed, whether incidents are visible, and whether the vendor can explain platform health without hand-waving. PHS becomes part of that story. It gives sales and customer-success teams a consistent line: the platform has one board-level health score, and each category behind that score has an owner, target, and error budget.

For internal finance conversations, PHS also prevents cost optimization from hiding quality debt. If the team swaps to a cheaper model and the cost contribution improves while the quality contribution falls, the composite shows the tradeoff explicitly. That turns a vague savings argument into a governance decision: is the cost gain worth the quality burn? In a healthy operating model, the answer is made by the same forum that owns the weights, not by whichever team has the loudest dashboard.

Second, weight changes: the only time we have changed weights mid-quarter was in October 2025 after a security-relevant availability incident, when the executive forum decided availability should weight 0.40 for the next two quarters. The weight change broke the year-over-year trendline. We addressed it by archiving every weight version with the score; any historical chart can be re-rendered under either weight set, and the board update notes the weight-version explicitly. This adds about 50 bytes per recompute (a JSON blob alongside the score) and is well worth it.

Third, score game-ability: an under-discussed risk. If your team is incentivised on PHS, they can game it. The most common games we have seen across the broader industry, per the SRE Platform Maturity Survey 2025: tightening latency targets to easy values to bank compliance, dropping the lowest-quality eval cases from the LLM-judge dataset, lowering availability targets after an incident rather than after a postmortem, and shifting cost-bearing tenants to a separate "experimental" reporting bucket. Each of these has a governance answer. The targets and the eval dataset must be approved by a forum that includes product (not just platform) and the targets cannot be loosened more than once a year. The cost reporting must include all production tenants. None of this is enforced by the math; it is enforced by the meeting.

Conclusion

The Platform Health Score is twenty lines of Python wrapped in two months of governance. The Python is the cheap part. The governance — picking weights, defending thresholds, archiving weight versions, monitoring for game-ability, separating engineering view from board view — is what makes it land. When it lands, you save your CTO twenty minutes of a board meeting every quarter and you give your on-call a trend-velocity signal that catches multi-category drift the per-category dashboards miss.

If you take three things away: keep the four-category SLO framework intact (the composite does not replace per-category SLOs, it supplements them); pick weights through a governance forum and revisit them quarterly, not weekly; and always show the contribution breakdown next to the headline number so the board view never flattens engineering reality. The number is one number for the board. Underneath that number is everything your platform team already built. Both audiences look at the same source. That is the trick.

The companion repo at amtocbot-examples/llm-platform-health-score has the working service, the Prometheus integration, the Slack webhook, and the test fixtures from the four-category drift incident. The next blog in this cluster will cover per-tenant health scoring at scale and the governance rules around tenant-driven compliance flags.


Revision History

Date Summary Old Version
2026-06-08 Added explicit measurement attribution around board-pack examples, weight choices, compliance math, incidents, alert thresholds, board-meeting time, and tenant thresholds; converted direct quotes into indirect wording; added monetization section and revision metadata. View original

Sources

  1. Anthropic Economic Index, 2025 follow-up survey: board-level AI platform reporting gap data.
  2. Honeycomb SRE Platform Maturity Survey 2025: SLO game-ability patterns and platform-team incentive risks.
  3. Google SRE Workbook, Implementing SLOs chapter: canonical compliance and error-budget formulas the composite math is built on.
  4. OpenTelemetry GenAI semantic conventions: span attributes used in the latency and availability queries.
  5. Blog 180: LLM SLOs in Production: the four-category framework this rollup sits on top of.

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-05-03 · Updated: 2026-06-08 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter
Sunday, April 12, 2026

The Developer's Guide to AI Compliance in 2026: EU AI Act, NIST, and What You Actually Need to Do

Hero image: regulatory compliance framework for AI systems — developer at workstation surrounded by audit documentation and compliance dashboards

Generated with Higgsfield GPT Image — 16:9

Introduction

On August 1, 2024, the EU AI Act entered into force. By February 2025, the rules governing general-purpose AI models (GPAI) were live. As of August 2026 — the full enforcement deadline — any organization deploying high-risk AI systems inside the European Union must demonstrate documented compliance or face fines of up to €30 million, or 6% of global annual turnover.

That deadline is no longer theoretical. It is this year.

Meanwhile, in the United States, NIST released version 1.0 of its AI Risk Management Framework in January 2023, and federal agencies began mandating alignment with it for government contractors. ISO 42001, the international standard for AI management systems, published in December 2023. Boards of directors at Fortune 500 companies are now asking CTOs to explain their AI governance posture — not as a compliance exercise, but as a material risk disclosure.

For most engineering teams, this has arrived faster than expected. Three years ago, "AI governance" sounded like something legal and compliance departments handled after the fact. Today, it is a pre-deployment gate, a procurement requirement, and in some sectors a legal prerequisite to operating at all.

The uncomfortable truth is that the frameworks are complex, often written by lawyers for lawyers, and translate poorly into engineering terms. Most developer guides to AI compliance are either too high-level to be actionable ("document your data pipelines!") or too narrow in scope to address the real scope of what the EU AI Act requires. Engineers implementing RAG pipelines, fine-tuned classifiers, or agentic systems need concrete answers: Does this trigger high-risk classification? What do I actually need to build? What documentation is required before we ship?

This guide answers those questions directly. It covers what the major regulatory frameworks require, how to classify your systems correctly, what you must implement for high-risk systems, and how to integrate compliance into your engineering workflow without making it a bureaucratic nightmare.


The Regulatory Landscape

Four frameworks dominate the conversation in 2026, and while they overlap significantly, each has a distinct scope and jurisdiction. Understanding what each requires — and how they interact — is the foundation of any practical compliance strategy.

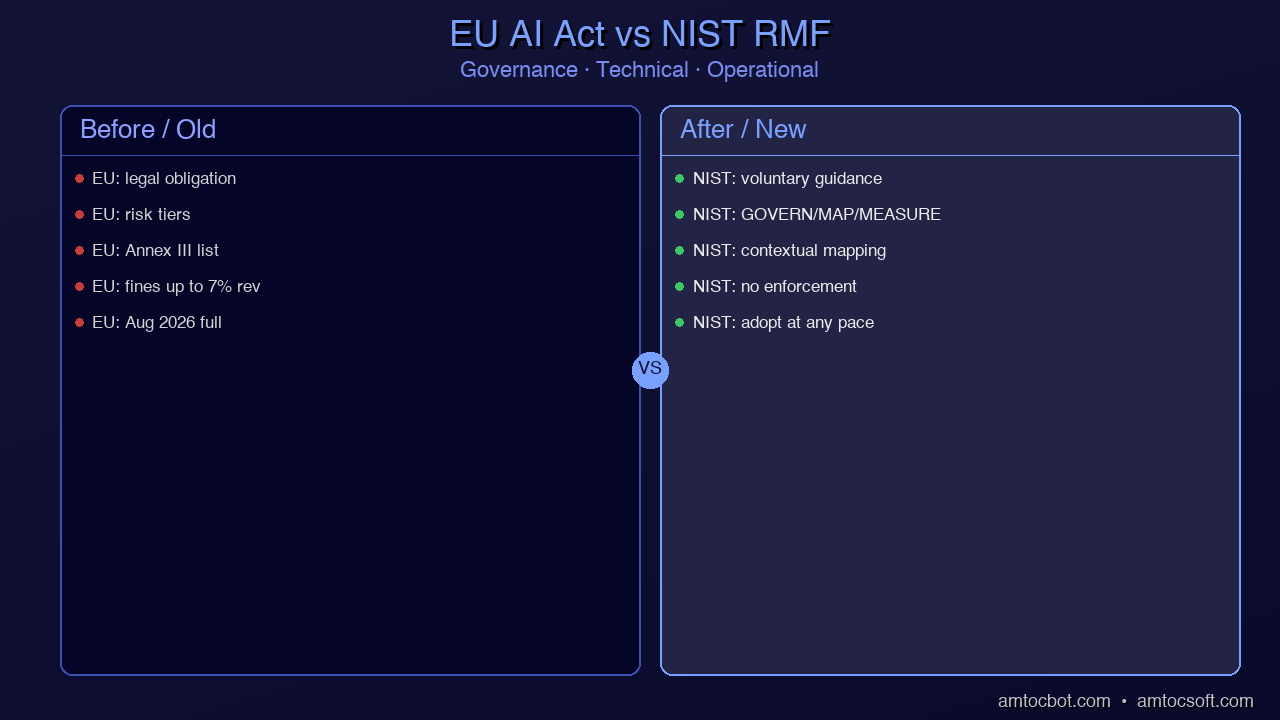
EU AI Act: Risk-Tiered Regulation

The EU AI Act is the world's first comprehensive horizontal AI regulation. It applies not just to EU companies, but to any company deploying AI systems whose outputs are used in the EU — which in practice means most large technology companies globally.

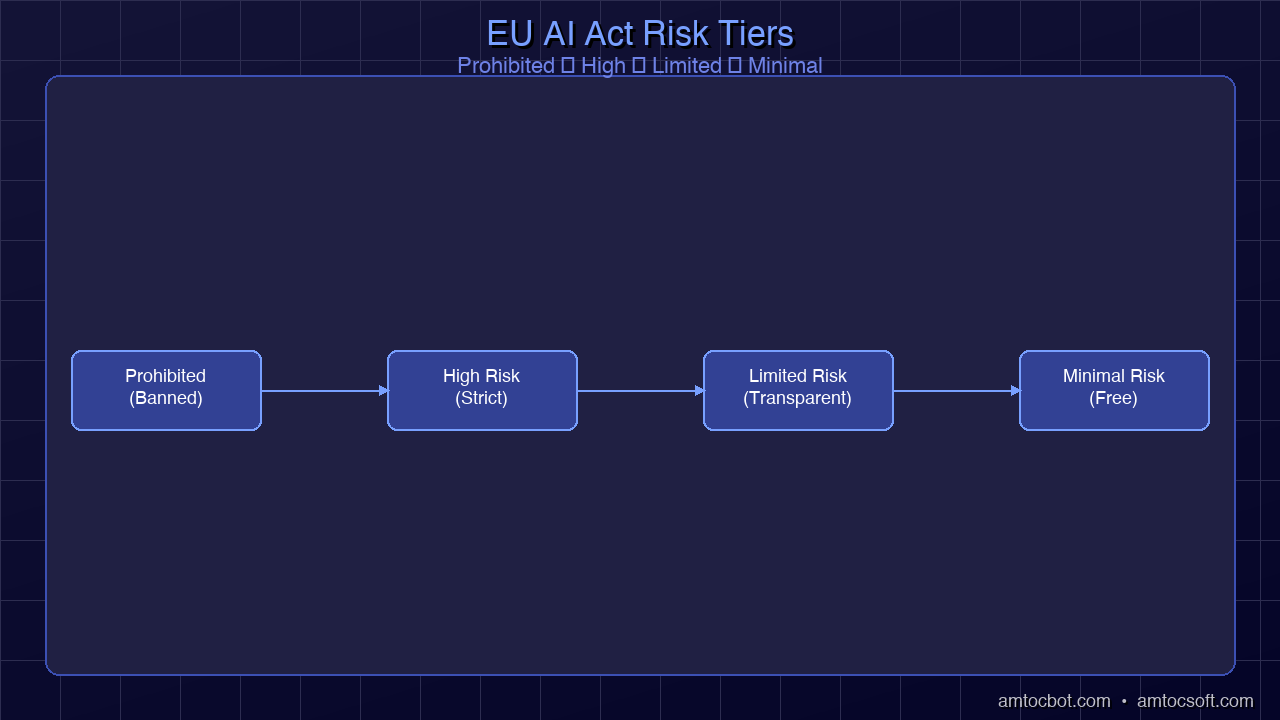
The Act organizes AI systems into four risk tiers:

Unacceptable Risk (Prohibited): These systems are banned outright. The list includes social scoring systems operated by public authorities, real-time remote biometric identification in public spaces (with narrow law enforcement exceptions), AI systems that exploit vulnerable groups, and subliminal manipulation techniques. These prohibitions took effect in February 2025.

High Risk: The category that will consume most engineering compliance effort. High-risk AI systems are permitted but subject to extensive pre-market requirements. The full list lives in Annex III of the Act and covers eight domains: biometric identification and categorization, critical infrastructure management, educational access and assessment, employment and worker management, access to essential private and public services, law enforcement, migration and border control, and administration of justice. High-risk rules fully apply as of August 2026.

Limited Risk: Primarily transparency obligations. AI systems interacting with humans (chatbots, virtual assistants) must disclose that they are AI. Deepfake generators must label output. These are relatively lightweight requirements.

Minimal Risk: Spam filters, AI-enabled video games, recommendation systems — no mandatory requirements, though the Act encourages following voluntary codes of conduct.

General Purpose AI Models (GPAI): A separate tier added to address foundation models. GPAI providers with over 10^25 FLOPs training compute face additional systemic risk requirements. All GPAI providers must publish technical documentation and a summary of training data. These rules took effect in August 2025.

Key enforcement dates to internalize:
- August 2024: Act enters into force
- February 2025: Prohibited systems rules apply; GPAI rules apply
- August 2026: High-risk system requirements fully apply (this is now)
- August 2027: High-risk systems already on the market before August 2026 get a grace period extension in some categories

NIST AI RMF: The US Standard

The National Institute of Standards and Technology AI Risk Management Framework (NIST AI RMF) is voluntary at the federal level but has become a de facto standard for US government contractors, financial institutions, and healthcare organizations. Unlike the EU AI Act, it is not sector-specific — it is a process framework.

The RMF organizes AI risk management into four functions: GOVERN, MAP, MEASURE, and MANAGE. We cover implementation of these in the NIST section below.

ISO 42001: AI Management Systems

Published December 2023, ISO 42001 is to AI what ISO 27001 is to information security: an auditable management system standard. Organizations can pursue certification, which increasingly appears as a procurement requirement in enterprise contracts. ISO 42001 aligns closely with both the EU AI Act and NIST RMF in its requirements for documented policies, roles, and continuous improvement processes.

US Executive Orders and Sector Rules

Executive Order 14110 (October 2023) directed federal agencies to establish standards for AI safety and security, including mandatory red-teaming for dual-use AI systems and reporting requirements for frontier model training runs. The AI Safety Institute within NIST coordinates this work. Sector-specific rules have followed: the FDA has published guidance on AI/ML-based software as a medical device; banking regulators have issued guidance on model risk management that explicitly covers AI. If your system operates in a regulated sector, expect sector rules to layer on top of the horizontal frameworks.

SOC 2 and AI

Auditors conducting SOC 2 Type II reviews are now explicitly asking about AI governance as part of the common criteria. Trust service criteria CC6 (logical and physical access controls) and CC7 (system operations) now include questions about AI-generated decisions and their oversight mechanisms. If your product is AI-powered and you hold SOC 2 certification, expect your next renewal to include questions about model risk, training data governance, and human override mechanisms.

EU AI Act risk classification tiers — from prohibited systems at the top through high, limited, and minimal risk

Generated with Higgsfield GPT Image — 16:9


What Makes a System "High Risk"?

This is the classification question most engineering teams get wrong, and the consequences of misclassification run in both directions. Over-classify and you build expensive compliance infrastructure for systems that don't require it. Under-classify and you ship a non-compliant high-risk system.

The EU AI Act's Annex III defines high-risk AI through eight use-case categories. The key insight is that classification is based on use case and context of deployment, not on the underlying technology. A large language model is not inherently high-risk. That same LLM used to generate resume screening decisions for a Fortune 500 company's hiring process is high-risk.

The eight Annex III categories are:

  1. Biometric identification and categorization: Real-time or post-hoc identification of natural persons from biometric data. Note that emotion recognition systems fall here.
  2. Critical infrastructure: AI managing or operating road traffic, water, gas, electricity, heating, internet infrastructure.
  3. Education and vocational training: Systems determining access to educational institutions, grading, or evaluating students.
  4. Employment and worker management: CV screening, hiring decision support, task allocation, performance monitoring, promotion decisions.
  5. Essential private and public services: Credit scoring, insurance risk assessment, benefits eligibility assessment, emergency services dispatch.
  6. Law enforcement: Risk assessment for criminal recidivism, polygraph equivalents, evidence evaluation, profiling.
  7. Migration, asylum, border control: Risk assessment, document examination, application examination.
  8. Administration of justice: AI assisting courts in legal research, fact-finding, or decision-making.

Common classification mistakes developers make:

Mistake 1: Treating "decision support" as lower risk than "automated decision." The Act does not make this distinction. A system that generates a recommended credit score for a human loan officer to review is high-risk under category 5, the same as a system that automatically approves or denies loans.

Mistake 2: Misreading "biometric" to mean only faces. Biometric data includes gait analysis, voice patterns, behavioral patterns, and physiological measurements. A workplace productivity monitoring tool that tracks typing patterns to flag underperformance hits both category 1 (biometric) and category 4 (employment management).

Mistake 3: Assuming B2B products are out of scope. If your B2B product is used by customers to make high-risk decisions, your product is high-risk. You cannot pass the compliance burden to your customers by putting it in a contract. You are the provider; the requirements apply to you.

Mistake 4: Ignoring the GPAI interaction layer. If your product wraps a GPAI provider and uses it to make high-risk decisions, both the GPAI provider and your system have obligations. You need to understand what your provider's documentation covers and what gaps you need to fill.

graph TD A[AI System in Scope?] -->|Yes| B{Used in EU or affecting EU persons?} A -->|No| Z[No EU AI Act obligations] B -->|No| Z B -->|Yes| C{Does it fall in prohibited categories?} C -->|Yes| D[PROHIBITED — Cannot deploy] C -->|No| E{Annex III use case?} E -->|Biometrics| F[HIGH RISK] E -->|Critical Infrastructure| F E -->|Education/Employment| F E -->|Essential Services| F E -->|Law Enforcement| F E -->|Migration/Justice| F E -->|None of the above| G{Interacts with humans as AI?} G -->|Yes| H[LIMITED RISK — Transparency obligations only] G -->|No| I[MINIMAL RISK — Voluntary codes apply] F --> J[Full Article 9-15 Compliance Required]

What Developers Must Actually Implement

For high-risk systems, Articles 9 through 15 of the EU AI Act define mandatory technical and organizational measures. Here is a concrete breakdown of each requirement and what it means in practice.

1. Risk Management System (Article 9)

You must establish, implement, document, and maintain a risk management system throughout the AI system's entire lifecycle. This is not a one-time risk assessment before launch — it is a continuous process.

In practice: Create a living risk register for your AI system. Document identified risks, their likelihood and severity, the controls you have implemented, and how you verify those controls are working. This needs to be version-controlled and updated with every significant model change, data drift event, or production incident.

2. Data Governance and Management (Article 10)

Training, validation, and test datasets must meet quality criteria relevant to the intended purpose. You must document:
- Data origin, collection method, and preparation steps
- Bias examination and mitigation measures
- How datasets meet the stated use case requirements
- Data handling practices for personal data

In practice: Implement model cards and dataset cards. Run bias evaluations before each model version release. Log training data lineage. For systems using personal data, ensure you have a documented lawful basis and Data Protection Impact Assessment (DPIA).

Model Card Template (YAML frontmatter):

# model-card.yaml
model_id: "credit-risk-classifier-v2.3"
model_type: "gradient_boosted_classifier"
intended_use: "Credit risk assessment for personal loan applications"
out_of_scope_use:
  - "Employment screening"
  - "Insurance underwriting"
  - "Any use outside EU-regulated lending context"

training_data:
  sources:
    - name: "Internal loan performance dataset"
      date_range: "2019-01-01 to 2024-12-31"
      records: 2400000
      geographic_scope: "EU member states"
  preprocessing:
    - "Missing value imputation via median (numerical) and mode (categorical)"
    - "Feature scaling: standard normalization"
    - "Protected attribute removal: age, gender, nationality excluded from features"
  bias_evaluation:
    method: "Disparate impact analysis across age cohorts and geographic regions"
    last_run: "2026-03-15"
    result: "DI ratio 0.87 across all protected cohorts (threshold: >0.80)"

performance:
  metrics:
    auc_roc: 0.847
    precision_at_threshold_0_5: 0.79
    recall_at_threshold_0_5: 0.81
    false_positive_rate: 0.19
  evaluation_dataset: "Holdout set, 2025 Q4, n=48000"
  known_limitations:
    - "Lower recall for applicants with < 12 months credit history"
    - "Performance degrades for applications from regions with < 5000 training samples"

human_oversight:
  override_mechanism: "Loan officer can override any automated decision"
  override_rate_target: "< 5% of decisions escalated"
  escalation_triggers:
    - "Decision confidence < 0.65"
    - "Applicant-requested review"
    - "Edge case detection (out-of-distribution features)"

regulatory_compliance:
  eu_ai_act_classification: "High Risk — Annex III, Category 5b (credit scoring)"
  risk_management_version: "v1.4"
  last_conformity_assessment: "2026-02-20"
  dpia_reference: "DPIA-2025-CR-047"

contacts:
  model_owner: "credit-risk-team@company.com"
  compliance_contact: "ai-governance@company.com"
  last_updated: "2026-04-01"
  version: "2.3.0"

3. Technical Documentation (Article 11)

Before placing a high-risk AI system on the market, you must prepare comprehensive technical documentation demonstrating that the system meets the Act's requirements. Annex IV specifies the required contents: system description and purpose, development process, training data, monitoring plan, risk management records.

In practice: Maintain a System Card alongside your model card. The system card describes the full sociotechnical system — not just the model, but the input pipeline, deployment context, human oversight mechanisms, and feedback loops.

4. Transparency and Audit Logging (Article 13)

High-risk systems must have logging capabilities enabling post-hoc audit of their operation. Logs must cover the period during which the system was in use and must capture enough information to reconstruct any decision.

Audit Logging Pattern (Python):

import json
import hashlib
import time
from dataclasses import dataclass, asdict
from typing import Any, Optional
from datetime import datetime, timezone
import uuid

@dataclass
class AIDecisionRecord:
    """Audit log entry for high-risk AI decisions per EU AI Act Article 13."""
    decision_id: str
    timestamp_utc: str
    system_id: str
    system_version: str
    request_hash: str          # SHA-256 of input features (for reproducibility without storing PII)
    decision_output: str       # The decision rendered
    confidence_score: float
    model_version: str
    input_feature_count: int
    out_of_distribution: bool  # Did OOD detector fire?
    human_override: bool       # Was this decision overridden?
    override_reason: Optional[str]
    processing_time_ms: int
    session_context: dict      # Business context (loan ID, operator ID, etc.)

class AIAuditLogger:
    """
    Compliance-grade audit logger for high-risk AI systems.
    Writes immutable, tamper-evident decision records.
    Complies with EU AI Act Article 13 logging requirements.
    """

    def __init__(self, system_id: str, system_version: str, storage_backend):
        self.system_id = system_id
        self.system_version = system_version
        self.storage = storage_backend  # e.g., append-only S3, BigQuery, Postgres with audit trigger

    def _hash_features(self, features: dict) -> str:
        """Hash input features for reproducibility without storing PII."""
        canonical = json.dumps(features, sort_keys=True, default=str)
        return hashlib.sha256(canonical.encode()).hexdigest()

    def log_decision(
        self,
        features: dict,
        decision: str,
        confidence: float,
        model_version: str,
        out_of_distribution: bool,
        session_context: dict,
        processing_start: float,
    ) -> str:
        """
        Log a single AI decision. Returns decision_id for downstream tracking.
        Call this for every inference that produces a consequential output.
        """
        decision_id = str(uuid.uuid4())
        processing_time_ms = int((time.monotonic() - processing_start) * 1000)

        record = AIDecisionRecord(
            decision_id=decision_id,
            timestamp_utc=datetime.now(timezone.utc).isoformat(),
            system_id=self.system_id,
            system_version=self.system_version,
            request_hash=self._hash_features(features),
            decision_output=decision,
            confidence_score=round(confidence, 6),
            model_version=model_version,
            input_feature_count=len(features),
            out_of_distribution=out_of_distribution,
            human_override=False,  # Updated later if override occurs
            override_reason=None,
            processing_time_ms=processing_time_ms,
            session_context=session_context,
        )

        self.storage.write(asdict(record))
        return decision_id

    def log_override(self, decision_id: str, operator_id: str, reason: str):
        """
        Record that a human operator overrode an AI decision.
        Must be called whenever an override occurs for complete audit trail.
        """
        override_record = {
            "type": "override",
            "decision_id": decision_id,
            "timestamp_utc": datetime.now(timezone.utc).isoformat(),
            "operator_id": operator_id,
            "reason": reason,
        }
        self.storage.write(override_record)

    def log_data_drift_event(self, drift_metrics: dict, alert_level: str):
        """
        Log detected data drift events per Article 9 continuous monitoring.
        """
        drift_record = {
            "type": "data_drift_alert",
            "timestamp_utc": datetime.now(timezone.utc).isoformat(),
            "system_id": self.system_id,
            "alert_level": alert_level,  # "low" | "medium" | "high"
            "metrics": drift_metrics,
        }
        self.storage.write(drift_record)

5. Human Oversight Mechanisms (Article 14)

High-risk AI systems must be designed and developed to allow effective human oversight. This means building explicit override capability, ensuring outputs are interpretable enough for a human to make a meaningful review decision, and defining escalation thresholds.

In practice: Hard requirements are an override UI available to every operator, escalation logic that triggers human review when confidence is below a threshold or when out-of-distribution inputs are detected, and documentation of what operators are trained to look for.

6. Robustness, Accuracy, and Cybersecurity (Article 15)

The system must meet declared accuracy levels consistently across its intended operating range. It must be resilient to input manipulation (adversarial attacks), errors, and inconsistencies. You must implement appropriate cybersecurity measures given the risk profile.

In practice: Adversarial robustness testing before release, data poisoning detection in training pipelines, regular accuracy re-evaluation against production data, and penetration testing of the inference API.

graph LR subgraph Design A[Requirement Analysis] --> B[Risk Classification] B --> C[Model Card Draft] C --> D[DPIA if Personal Data] end subgraph Development D --> E[Training Data Governance] E --> F[Bias Evaluation] F --> G[Model Training] G --> H[Adversarial Testing] H --> I[Model Card Finalize] end subgraph Pre-Deployment I --> J[Conformity Assessment] J --> K[Technical Documentation Complete] K --> L[Human Oversight Integration] L --> M[Audit Logging Enabled] end subgraph Production M --> N[Continuous Monitoring] N --> O{Drift or Performance Degradation?} O -->|Yes| P[Alert + Risk Register Update] P --> Q[Re-evaluation Cycle] Q --> F O -->|No| N end style Design fill:#e8f4f8 style Development fill:#f0f8e8 style Pre-Deployment fill:#fff8e8 style Production fill:#f8e8f0

NIST AI RMF in Practice

The NIST AI Risk Management Framework does not prescribe specific controls — it provides a structured process for identifying and managing AI risks in context. This makes it more flexible than the EU AI Act but also more ambiguous. Here is what the four functions mean in practice.

GOVERN

GOVERN establishes the organizational foundation: policies, roles, culture, and accountability structures for AI risk management. Without GOVERN, MAP, MEASURE, and MANAGE are exercises with no anchor.

What a small team should do: assign a named AI risk owner (this can be the tech lead), document a one-page AI use policy, and establish a minimum review checklist for new AI systems before production deployment.

What an enterprise must do: establish a formal AI governance committee with representation from legal, compliance, engineering, and business; define escalation paths; maintain an inventory of all AI systems in production; publish an external AI use policy; and align AI risk criteria with enterprise risk appetite statements.

MAP

MAP establishes context, identifies stakeholders, and categorizes AI risks across three dimensions: technical risks (model failure modes, distribution shift), operational risks (process gaps, integration failures), and societal risks (bias, fairness, downstream harm).

Practical output of MAP: a risk register with each identified risk labeled by category, likelihood, severity, and current control status. This feeds directly into the EU AI Act's Article 9 risk management system requirement.

MEASURE

MEASURE defines the metrics, benchmarks, and evaluation methods that determine whether risks are at acceptable levels. This is where most teams have the most room to improve: building automated evaluation into CI pipelines rather than doing it manually before major releases.

Metrics to track for a typical high-risk classifier: accuracy, precision/recall by demographic subgroup, false positive and false negative rates, confidence calibration, out-of-distribution detection rate, and model drift indicators (PSI, KS statistic, feature drift).

MANAGE

MANAGE covers the playbooks for responding to AI risk events: incidents, performance degradation, identified bias, adversarial attacks. It also covers the processes for retiring or significantly modifying AI systems.

What distinguishes mature AI risk management: the ability to execute a model rollback in under 30 minutes, a defined SLA for bias report investigation, and documented criteria for when a change to a high-risk system triggers a new conformity assessment.

EU AI Act vs. NIST AI RMF — Key Overlaps and Gaps:

Requirement EU AI Act NIST AI RMF
Risk classification Mandatory (Annex III) Recommended (MAP function)
Technical documentation Mandatory (Article 11) Recommended (GOVERN + MAP)
Audit logging Mandatory (Article 13) Recommended (MEASURE)
Human oversight Mandatory (Article 14) Recommended (MANAGE)
Bias evaluation Mandatory (Article 10) Recommended (MEASURE)
Third-party assessment Required for some categories Not required
Geographic scope EU nexus US federal focus, global voluntary
Enforcement mechanism Fines up to 6% global revenue Contract requirements, sector rules
Voluntary certification EU database registration No certification program
EU AI Act vs NIST AI RMF — overlap areas and distinct requirements across governance, technical, and operational dimensions

Generated with Higgsfield GPT Image — 16:9


Building Compliance Into Your SDLC

The worst approach to AI compliance is treating it as a pre-launch checklist. By the time a model is ready to deploy, it is too late to discover that your training data lacks the provenance documentation Article 10 requires. Compliance must be a property of your development process, not your deployment gate.

AI Compliance as Code:

Three concrete practices that integrate compliance into engineering workflow:

1. Automated model card generation. Instead of writing model cards manually, generate them from training metadata. Every training run should emit a structured artifact containing dataset statistics, bias evaluation results, and performance metrics. A CI job assembles these into a versioned model card. The model card is part of the artifact that gets deployed — not a document updated when someone remembers.

2. Bias test CI gates. Bias evaluation is not a one-time pre-launch exercise. It must run on every model version candidate, with a defined threshold that fails the pipeline. A disparate impact ratio below 0.80 on your primary protected attribute cohorts should be a hard gate, not a warning. The threshold should be documented in your risk management system and approved by your AI governance owner.

3. Audit log assertion tests. Every inference code path should have integration tests that verify audit log entries are written correctly. These tests should check that: a log entry is created for every decision, the entry contains all required fields, confidence score is within valid range, and override mechanisms are reachable. If your audit logging code silently fails in production, you have a compliance gap that you will only discover during an audit.

flowchart TD A([Requirement / Feature Request]) --> B[AI Risk Classification Check] B --> C{High Risk?} C -->|Yes| D[DPIA + Annex IV Docs Started] C -->|No| E[Standard Dev Flow] D --> F[Data Governance Review] F --> G[Model Development] E --> G G --> H[Automated Bias Evaluation CI Gate] H -->|PASS| I[Model Card Auto-Generated] H -->|FAIL| J[Block Merge — Fix Bias Issue] J --> G I --> K[Audit Log Integration Tests] K -->|PASS| L[Human Oversight Smoke Test] K -->|FAIL| M[Block Merge — Fix Logging] M --> G L --> N[Conformity Assessment if High Risk] N --> O{Assessment Passed?} O -->|Yes| P[EU Database Registration if Required] O -->|No| Q[Remediation Required] Q --> G P --> R([Deploy to Production]) E --> S[Standard QA + Deploy] S --> R R --> T[Continuous Monitoring Pipeline] T --> U{Drift or Incident?} U -->|Yes| V[Risk Register Update + Alert] V --> W{Material Change?} W -->|Yes| N W -->|No| T U -->|No| T style D fill:#ffe8e8 style F fill:#ffe8e8 style N fill:#ffe8e8 style H fill:#fff8e8 style K fill:#fff8e8 style L fill:#fff8e8

What "compliance as code" looks like in a CI pipeline:

# tests/test_ai_compliance.py
# Run as part of every model deployment CI pipeline

import pytest
import json
from pathlib import Path
from your_model_package import ModelCard, BiasEvaluator, AuditLogger

MODEL_CARD_PATH = Path("artifacts/model-card.yaml")
BIAS_THRESHOLD = 0.80  # Disparate impact ratio minimum
REQUIRED_LOG_FIELDS = [
    "decision_id", "timestamp_utc", "system_id", "system_version",
    "request_hash", "decision_output", "confidence_score", "model_version",
    "out_of_distribution", "human_override"
]

class TestModelCardCompleteness:
    def test_model_card_exists(self):
        assert MODEL_CARD_PATH.exists(), "Model card must be generated before deployment"

    def test_required_fields_present(self):
        card = ModelCard.from_yaml(MODEL_CARD_PATH)
        required = ["model_id", "intended_use", "training_data", "performance",
                    "human_oversight", "regulatory_compliance", "contacts"]
        for field in required:
            assert hasattr(card, field), f"Model card missing required field: {field}"

    def test_out_of_scope_use_documented(self):
        card = ModelCard.from_yaml(MODEL_CARD_PATH)
        assert len(card.out_of_scope_use) > 0, "Model card must document out-of-scope uses"

class TestBiasEvaluation:
    def test_disparate_impact_above_threshold(self, eval_dataset):
        evaluator = BiasEvaluator()
        results = evaluator.evaluate(eval_dataset)
        for cohort, di_ratio in results.disparate_impact.items():
            assert di_ratio >= BIAS_THRESHOLD, (
                f"Bias gate FAILED: cohort '{cohort}' DI ratio {di_ratio:.3f} "
                f"is below threshold {BIAS_THRESHOLD}. "
                f"Investigate before merging."
            )

    def test_bias_evaluation_recency(self):
        card = ModelCard.from_yaml(MODEL_CARD_PATH)
        from datetime import datetime, timezone, timedelta
        last_run = datetime.fromisoformat(card.training_data.bias_evaluation.last_run)
        age_days = (datetime.now(timezone.utc) - last_run.replace(tzinfo=timezone.utc)).days
        assert age_days < 30, f"Bias evaluation is {age_days} days old — must be run within 30 days of deployment"

class TestAuditLogging:
    def test_decision_produces_log_entry(self, mock_storage, sample_features):
        logger = AuditLogger("test-system", "v1.0", mock_storage)
        decision_id = logger.log_decision(
            features=sample_features,
            decision="APPROVED",
            confidence=0.87,
            model_version="v1.0",
            out_of_distribution=False,
            session_context={"application_id": "test-001"},
            processing_start=0.0,
        )
        assert decision_id is not None
        assert len(mock_storage.records) == 1

    def test_log_entry_has_all_required_fields(self, mock_storage, sample_features):
        logger = AuditLogger("test-system", "v1.0", mock_storage)
        logger.log_decision(
            features=sample_features, decision="DENIED", confidence=0.61,
            model_version="v1.0", out_of_distribution=True,
            session_context={}, processing_start=0.0,
        )
        record = mock_storage.records[0]
        for field in REQUIRED_LOG_FIELDS:
            assert field in record, f"Audit log missing required field: {field}"

    def test_override_logging_works(self, mock_storage, sample_features):
        logger = AuditLogger("test-system", "v1.0", mock_storage)
        decision_id = logger.log_decision(
            features=sample_features, decision="DENIED", confidence=0.55,
            model_version="v1.0", out_of_distribution=False,
            session_context={}, processing_start=0.0,
        )
        logger.log_override(decision_id, "operator-007", "Customer appeal — edge case")
        assert len(mock_storage.records) == 2
        override = mock_storage.records[1]
        assert override["type"] == "override"
        assert override["decision_id"] == decision_id

The critical insight here is that compliance test failures should be treated the same as unit test failures: they block merge, they require a fix before deployment, and they are owned by the engineering team — not the compliance team. The compliance team sets the policy; the engineering team implements and verifies it in code.


Conclusion

AI compliance in 2026 is not optional, and it is no longer something you can delegate entirely to legal or compliance functions. The EU AI Act's technical requirements — risk management systems, data governance documentation, audit logging, human oversight mechanisms, robustness testing — are engineering deliverables. They require engineering ownership.

The teams that will handle this best are the ones that treat compliance as architecture: something designed in from the beginning, expressed in code, tested in CI, and continuously verified in production. The teams that will struggle are the ones waiting for a compliance checklist to appear three weeks before an audit.

There is also a competitive angle worth naming directly. Mature AI governance is increasingly a sales differentiator in enterprise markets. Procurement teams at regulated customers — banks, insurers, healthcare systems, public sector organizations — are now asking for model cards, audit logging attestation, and documented human oversight mechanisms before signing contracts. Having this infrastructure in place is not just a compliance cost; it is a trust signal that closes deals.

The frameworks — EU AI Act, NIST AI RMF, ISO 42001 — overlap significantly in their practical requirements. You do not need to build three parallel compliance programs. Build one solid one: risk-classify your systems correctly, document your training data and model behavior, implement audit logging and human override mechanisms, run bias evaluations in CI, and maintain a living risk register. That core program satisfies the lion's share of all three frameworks simultaneously.

Start with the highest-risk systems first. Classify everything in your portfolio. Fix the gaps in documentation and logging for high-risk systems before August 2026 if you haven't already. Then build the compliance-as-code infrastructure so that new systems are compliant by default, not by remediation.

The regulatory moment is here. The engineering response is to make compliance a first-class property of how you build AI systems — not a checkpoint you hit on the way out the door.


Want to go deeper? The EU AI Act full text is at eur-lex.europa.eu. The NIST AI RMF playbook is at airc.nist.gov. The AI Safety Institute's evaluation guidelines are at aisi.gov.uk.

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-12 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter
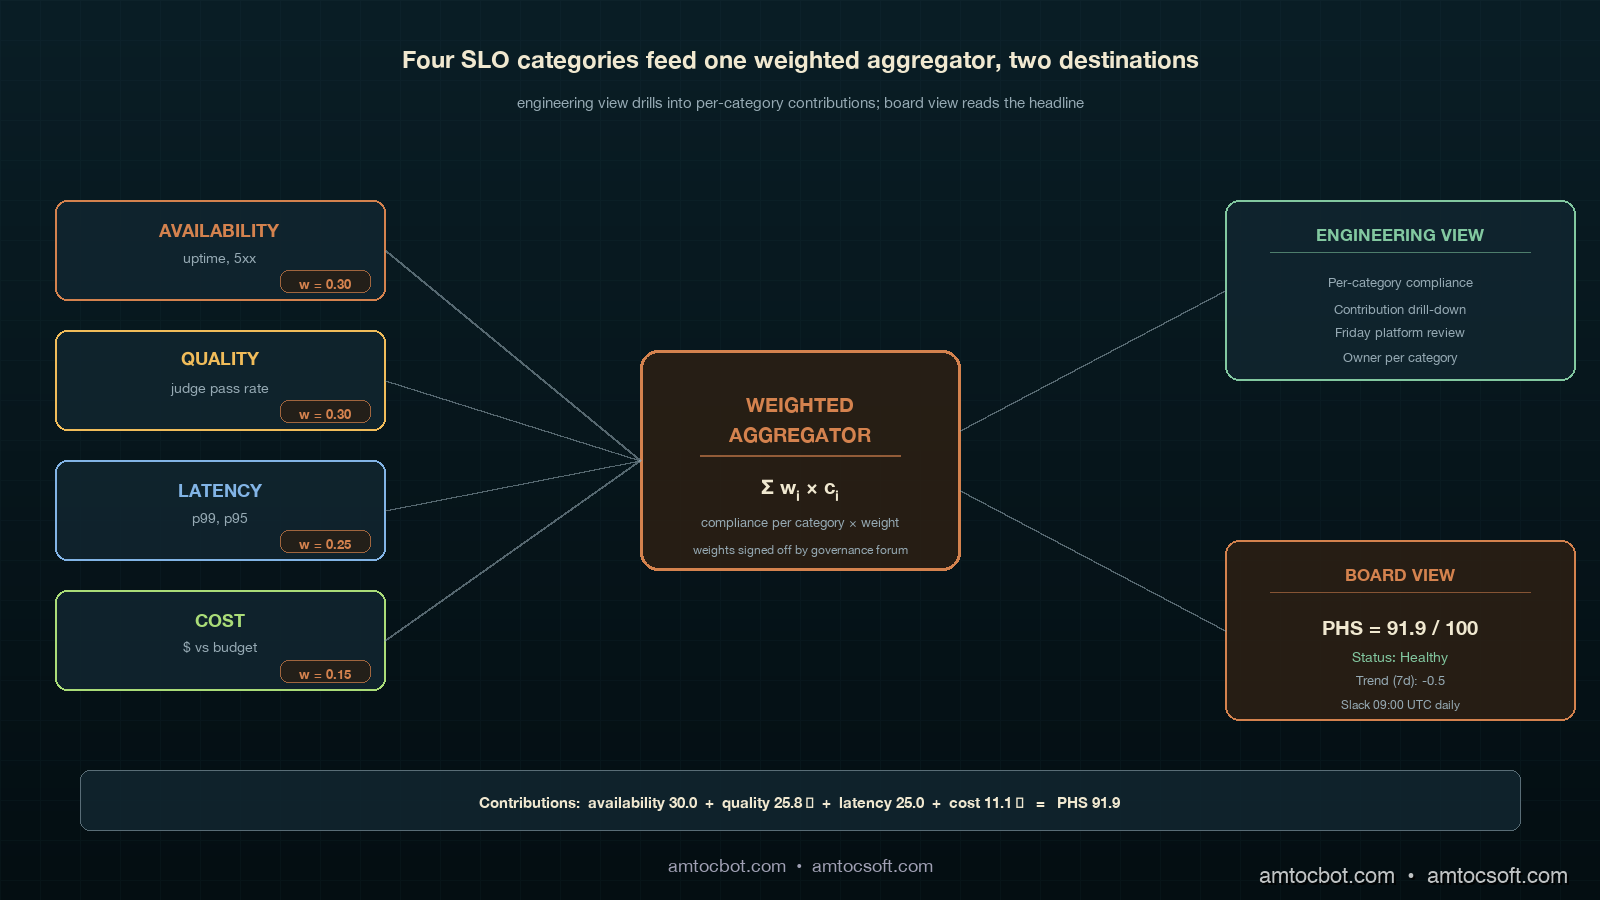
Bigger Is Not the Same as Better. The Job That Moved Is the Phone, Not the Lab.

Bigger is a plan. The phone is the receipt. The brief for this cycle is a question: does bigger always mean better in AI? The 2026 answer i...