Showing posts with label nist. Show all posts

Thursday, April 16, 2026

Quantum Computing in 2026: A Developer's Complete Resource Guide

Hero: Glowing blue quantum processor chip suspended in a dark server room, light trails representing qubit entanglement

Earlier this year, IBM's Heron processor solved a nitrogen fixation chemistry simulation in 11 minutes — a problem that would take classical supercomputers an estimated 47 years. That's not a benchmark result. That's verified quantum advantage on a real, practical scientific problem.

If you've been treating quantum computing as a "someday" topic, 2026 is the year that timeline collapses. This guide is the companion resource to the YouTube video Quantum Computing Explained: What Really Happened in 2026. The video explains the concepts visually and walks through the IBM milestone story. This article goes deeper: it gives you the links, the working code, the threat model, and the concrete developer action plan the video doesn't have room for.

By the end of this guide you'll understand what quantum computers actually are at a mechanical level, why the 2026 IBM Heron result matters beyond the headline, which problems quantum does and does not accelerate, why post-quantum cryptography migration is urgent for every application handling encrypted data today, and how to get your hands on a real quantum computer for free starting this afternoon.

This is not a transcript of the video. It's the resource guide the video outro promised you.


The Problem: Why Developers Need to Care Right Now

Most developers have a healthy skepticism toward quantum computing hype. That skepticism was well-earned for most of the 2010s and early 2020s. The devices were noisy, error rates were high, and the problems being solved were toy demonstrations. "Quantum supremacy" claims from 2019 were technically accurate but practically irrelevant — Google's Sycamore solved a random sampling problem that serves no useful purpose outside of demonstrating the hardware.

The 2026 situation is different in three concrete ways.

First, error correction is working in practice. IBM's Heron architecture uses a surface code error correction scheme that reduces logical error rates by orders of magnitude compared to physical qubit error rates. The nitrogen fixation result used error-corrected logical qubits, not raw physical qubits. That's the transition the field has been building toward.

Second, the cryptography threat is present-tense, not future-tense. A well-resourced adversary harvesting encrypted traffic today — HTTPS sessions, VPN tunnels, encrypted database backups — can store that data and decrypt it later when sufficiently powerful quantum hardware is available. Your encrypted data from 2026 is at risk from quantum hardware that doesn't fully exist yet. The NIST Post-Quantum Cryptography standards, finalized in 2024, exist precisely because this window matters.

Third, cloud access is free and available. IBM Quantum offers free access to real quantum hardware via their cloud platform. You don't need to buy anything, join a research program, or have a PhD. The barrier to experimentation is a browser and an afternoon.

The question for a working developer isn't "should I learn quantum computing." It's "which part of my stack is at risk, and what's my migration path."


What Quantum Computers Actually Are

Before diving into the 2026 milestone, it's worth being precise about the mechanics. Quantum computing gets explained with analogies that are technically close but often misleading.

Classical Bits vs Qubits

A classical bit is a physical system with two stable states. It's a 0 or a 1. Always. Every time you read it.

A qubit is a physical system — typically a superconducting circuit cooled to near absolute zero, a trapped ion, or a photon — that can exist in a superposition of states. Before measurement, the qubit is described by a probability amplitude: some combination of |0⟩ and |1⟩. When you measure it, the superposition collapses and you get a definite 0 or 1.

The power is not that qubits are "both 0 and 1 at once." That description encourages thinking about quantum computers as massively parallel machines that try every answer simultaneously. That's not how they work, and it leads to wrong intuitions about what they can and can't accelerate.

The actual power comes from two related phenomena: entanglement and interference.

Entanglement links qubits so the state of one is correlated with the state of others, even when measured independently. Two entangled qubits aren't just two independent qubits — they're a joint system. The information stored in N entangled qubits scales exponentially: 50 entangled qubits can represent 2^50 states simultaneously in their joint probability distribution.

Interference is the mechanism quantum algorithms use to amplify correct answers and cancel out wrong ones. A quantum algorithm doesn't try all answers simultaneously and then pick the right one. It uses carefully designed sequences of quantum gates to make the probability amplitudes of correct answers interfere constructively (get larger) and incorrect answers interfere destructively (cancel out). When you measure at the end, you're much more likely to get the right answer.

This is why quantum computing is hard to program and why it only helps for specific problem classes. Designing the interference patterns that amplify useful answers requires mathematical structure that most problems don't have.

flowchart TD A[Initialize qubits\nin |0⟩ state] --> B[Apply Hadamard gates\ncreate superposition] B --> C[Apply entangling gates\nCNOT, CZ, etc.] C --> D[Apply problem-specific\nunitary operations] D --> E{Interference\nAmplification} E --> F[Correct answers\namplified] E --> G[Wrong answers\ncancelled out] F --> H[Measure qubits\ncollapse to classical bits] G --> H H --> I[Read result\nrun many times\nfor statistics] I --> J{Confidence\nhigh enough?} J -->|Yes| K[Accept result] J -->|No| B

The loop at the bottom is important: quantum algorithms are probabilistic. You run the circuit many times (shots) and take the most frequent result, or compute statistics over the distribution.

The Hardware Reality

IBM's current quantum processors use superconducting transmon qubits operating at 15 millikelvin — colder than outer space. The Heron processor has 133 qubits arranged in a heavy-hex lattice that minimizes qubit crosstalk. Gates execute in 50-100 nanoseconds.

The fundamental engineering challenge is decoherence: qubits are extremely sensitive to environmental noise. A stray electromagnetic field, a vibration, a thermal fluctuation — any of these can randomize the qubit state before the computation completes. Coherence times on current hardware run in the microseconds to milliseconds range. Complex algorithms that require many gate operations need to complete before decoherence destroys the state.

Error correction addresses this by encoding one logical qubit across many physical qubits. The surface code used in IBM Heron spreads each logical qubit across 17-50+ physical qubits, with syndrome measurements that detect errors without collapsing the logical state. The overhead is high, but the result is logical qubits with dramatically lower error rates than the underlying physical hardware.


The 2026 IBM Heron Milestone: What Actually Happened

The nitrogen fixation problem sits at the intersection of quantum chemistry and one of agriculture's most important industrial processes. The Haber-Bosch process for synthesizing ammonia accounts for roughly 1-2% of global energy consumption — it's how we make fertilizer for most of the world's food supply. Optimizing the catalysts involved requires simulating the quantum mechanical interactions of nitrogen and hydrogen molecules with transition metal surfaces.

Classical computers struggle here because the quantum mechanical wavefunction of even a small molecular system involves an exponential number of parameters. Simulating FeMoco — the iron-molybdenum cofactor at the heart of biological nitrogen fixation — requires tracking the correlations between electrons in a way that scales exponentially with the number of electrons considered.

The IBM Heron result used a Variational Quantum Eigensolver (VQE) algorithm running on error-corrected logical qubits to compute the ground state energy of the FeMoco cofactor at a level of precision that no classical algorithm has achieved within reasonable time bounds. The 47 years estimate for classical simulation comes from extrapolating runtime on the best available classical algorithms with current supercomputing resources.

What "verified quantum advantage" means specifically: IBM's result was independently verified by a collaboration including classical computational chemists who certified that the quantum result matches the expected answer (derived through other approximate methods) to a precision that would require the stated classical runtime to achieve via exact methods.

timeline title IBM Quantum Hardware Milestones 2016 : IBM Q Experience launched : First 5-qubit processor online 2019 : 53-qubit Sycamore (Google) : Quantum supremacy claim on sampling 2021 : IBM 127-qubit Eagle processor : First 100+ qubit device 2022 : IBM 433-qubit Osprey : Largest superconducting qubit count 2023 : IBM 1,121-qubit Condor : Heavy-hex lattice architecture 2024 : NIST PQC standards finalized : Kyber + Dilithium standardized 2025 : IBM Heron error correction : Logical qubit coherence breakthrough 2026 : Nitrogen fixation milestone : 47 years → 11 minutes verified

The significance extends beyond chemistry. The same error correction architecture that enabled the nitrogen fixation result applies to other quantum simulation problems in drug discovery, materials science, and financial risk modeling. The Heron result is a proof of concept that the error correction regime — not just better physical qubits, but logical qubits with useful coherence times — is achievable on today's hardware.


What Quantum Solves (and What It Doesn't)

This is where most quantum computing explanations fail developers: they describe what quantum computers can do in principle without explaining the practical scope.

There are specific algorithmic families where quantum computers provide a mathematically proven speedup over the best known classical algorithms:

Quantum chemistry and materials simulation: Exponential speedup for simulating molecular systems. The FeMoco result is an early demonstration. Drug discovery, catalyst design, and battery material optimization are the near-term applications.

Cryptography (Shor's algorithm): Exponential speedup for factoring large integers and computing discrete logarithms. This is why RSA and elliptic curve cryptography are vulnerable. A sufficiently large fault-tolerant quantum computer running Shor's algorithm breaks these in hours, not decades.

Unstructured search (Grover's algorithm): Quadratic speedup. Searching through N items takes O(√N) instead of O(N). Important for some optimization problems, but quadratic is not exponential — it doesn't change the fundamental tractability of NP-hard problems.

Optimization problems: Quantum Approximate Optimization Algorithm (QAOA) shows promise for combinatorial optimization. Logistics routing, portfolio optimization, scheduling. The advantage is problem-dependent and not yet consistently demonstrated over classical heuristics at scale.

What quantum computers will not accelerate: general-purpose software execution, web servers, databases, machine learning training on existing architectures, most app development, anything that's already fast classically.

quadrantChart title Quantum Advantage by Problem Type x-axis Classical Fast --> Classical Slow y-axis Quantum No Speedup --> Quantum Big Speedup quadrant-1 Quantum wins big quadrant-2 Classical already fine quadrant-3 Quantum no help quadrant-4 Classical slow, quantum modest help Molecular Simulation: [0.85, 0.92] Cryptography Breaking: [0.80, 0.95] Combinatorial Optimization: [0.70, 0.65] Unstructured Search: [0.60, 0.55] Drug Discovery Screening: [0.75, 0.80] Financial Risk Modeling: [0.65, 0.60] Web Servers: [0.10, 0.05] Database Queries: [0.20, 0.08] ML Training: [0.55, 0.15] Video Encoding: [0.15, 0.05] General App Code: [0.12, 0.03]

The honest framing for most developers: quantum computers will not replace your backend. They will break your encryption if you don't migrate, and they will enable a new class of scientific computing that eventually affects the inputs to your industry.


The Harvest-Now-Decrypt-Later Threat

This is the most urgent practical issue for every developer managing encrypted data today, and it deserves more space than it usually gets in quantum computing introductions.

The threat model: A sophisticated adversary — a nation-state intelligence agency, a well-resourced criminal organization — is collecting encrypted network traffic at scale right now. Encrypted HTTPS sessions, VPN tunnels, encrypted file transfers. They can't read any of it today. But they're storing it in anticipation of having quantum hardware capable of running Shor's algorithm at useful scale.

When that hardware exists — estimates range from 5 to 15 years for cryptographically relevant quantum computers, though timelines are inherently uncertain — they decrypt the archive retroactively.

For most web traffic this is an acceptable risk: who cares if someone reads your 2026 cat photos in 2035. But for any data with a long confidentiality horizon — government classified data, medical records, financial transaction records, sensitive intellectual property, long-lived authentication credentials — the clock is already running.

NIST Post-Quantum Cryptography Standards

The National Institute of Standards and Technology finalized the first post-quantum cryptography (PQC) standards in 2024 after a years-long evaluation process involving the global cryptography research community. The standards are based on mathematical problems that are hard for both classical and quantum computers.

The two primary algorithms:

CRYSTALS-Kyber (ML-KEM, FIPS 203) — Key Encapsulation Mechanism. Replaces Diffie-Hellman and elliptic curve key exchange. Based on the hardness of the Module Learning With Errors (MLWE) problem. Used for establishing shared secrets in TLS, VPN protocols, and secure messaging.

CRYSTALS-Dilithium (ML-DSA, FIPS 204) — Digital Signature Algorithm. Replaces RSA and ECDSA for code signing, certificate signing, and authentication. Also based on lattice problems.

Migration urgency depends on your data sensitivity and what libraries you control:

  • TLS 1.3 libraries (OpenSSL 3.5+, BoringSSL) are adding hybrid key exchange (classical + PQC simultaneously) — update dependencies as they ship
  • Certificate authorities are planning PQC certificate rollout; watch for CA announcements in 2026-2027
  • Internal systems using raw RSA or ECC for key wrapping need audit and migration planning now
  • Long-lived secrets (signing keys, root CAs, backup encryption keys) have the highest urgency

Key resources:
- NIST Post-Quantum Cryptography Project — official standards, spec documents, migration guidance
- CRYSTALS-Kyber specification and reference implementation — full technical spec, test vectors, reference code

The migration is not a one-weekend task. Inventory your cryptographic dependencies, prioritize by data sensitivity and key lifetime, and build a multi-year migration roadmap. The organizations doing this work now will not be in crisis when cryptographically relevant quantum hardware arrives.


IBM Quantum Access: Getting Started for Free

IBM Quantum provides free cloud access to real quantum hardware. You don't need institutional affiliation. The free tier gives you access to quantum simulators and limited time on physical hardware.

Getting started:
1. Create a free account at IBM Quantum
2. Your API token is in your account settings — you'll use it to authenticate Qiskit
3. The Learning platform at IBM Quantum Learning has free structured courses from basics to advanced algorithms
4. Qiskit.org is the open-source SDK you'll use to write quantum programs

The free tier limitations: queue times on physical hardware can range from minutes to hours depending on the device. The simulators run locally or on IBM's cloud with no queue. For learning and algorithm development, the local Aer simulator is fast and deterministic — switch to real hardware when you want to see actual noise effects.


Qiskit Quick-Start: Your First Quantum Circuit

Qiskit is IBM's open-source Python SDK for quantum computing. It's the most widely used quantum programming framework and the natural starting point for developers coming from a Python background.

Install with pip:

pip install qiskit qiskit-aer

Bell State: The "Hello World" of Quantum Computing

The canonical introductory quantum circuit creates a Bell state — a pair of maximally entangled qubits. This demonstrates superposition and entanglement in 3 lines of quantum operations:

from qiskit import QuantumCircuit
from qiskit_aer import AerSimulator

# Create a 2-qubit circuit with 2 classical output bits
qc = QuantumCircuit(2, 2)
qc.h(0)       # Hadamard gate: puts qubit 0 into superposition
qc.cx(0, 1)   # CNOT gate: entangles qubit 1 with qubit 0
qc.measure([0, 1], [0, 1])  # Measure both qubits

# Run on the local Aer simulator
sim = AerSimulator()
job = sim.run(qc, shots=1000)
result = job.result()
counts = result.get_counts()
print(counts)  # Should show ~50% |00⟩ and ~50% |11⟩

What this code does step by step:

The QuantumCircuit(2, 2) creates a circuit with 2 qubits (quantum registers) and 2 classical bits (for storing measurement results). Both qubits start in the |0⟩ state.

The Hadamard gate qc.h(0) transforms qubit 0 from |0⟩ into an equal superposition: (|0⟩ + |1⟩)/√2. If you measured right here, you'd get 0 or 1 with equal 50% probability.

The CNOT gate qc.cx(0, 1) flips qubit 1 if and only if qubit 0 is |1⟩. Applied to the superposition state, this entangles the qubits: the joint state becomes (|00⟩ + |11⟩)/√2. They're correlated — if qubit 0 measures as 0, qubit 1 will also be 0, and vice versa.

Running this circuit 1,000 times (shots=1000) on the simulator produces roughly 500 counts of '00' and 500 counts of '11'. You should never see '01' or '10' — the entanglement enforces perfect correlation.

Running on Real Hardware

To run on IBM's real quantum devices, authenticate with your API token and select a backend:

from qiskit_ibm_runtime import QiskitRuntimeService, SamplerV2 as Sampler

# Authenticate (first time — saves credentials locally)
QiskitRuntimeService.save_account(
    channel="ibm_quantum",
    token="YOUR_API_TOKEN_HERE",
    set_as_default=True
)

service = QiskitRuntimeService()

# Get the least busy available backend with at least 2 qubits
backend = service.least_busy(operational=True, simulator=False, min_num_qubits=2)
print(f"Running on: {backend.name}")

# Transpile the circuit for the specific hardware topology
from qiskit.compiler import transpile
qc_transpiled = transpile(qc, backend)

# Run with Sampler primitive
sampler = Sampler(backend)
job = sampler.run([qc_transpiled], shots=1000)
result = job.result()
print(result[0].data.c.get_counts())

On real hardware you'll see noise: some counts of '01' and '10' will appear. That's not a bug — it's the physical error rates of the hardware. Error mitigation and error correction techniques reduce this, which is exactly what the IBM Heron result demonstrated at scale.

Visualizing Circuits

Qiskit includes a circuit drawer that generates publication-quality diagrams:

# Text representation
print(qc.draw())

# Matplotlib diagram (requires matplotlib)
qc.draw('mpl')

# Interactive HTML (in Jupyter)
qc.draw('latex')

Quantum Cloud APIs: Where to Run Your Circuits

Beyond IBM, the three major cloud providers offer quantum computing access with different hardware modalities and pricing models.

IBM Quantum Network

IBM Quantum — Superconducting transmon qubits. Free tier available. The most mature ecosystem for developers: Qiskit is the standard, documentation is extensive, and the learning resources at IBM Quantum Learning are genuinely good. Physical hardware from 5 to 133+ qubits. The default choice for developers learning the field.

AWS Braket

Amazon Braket — Managed quantum computing service supporting multiple hardware providers: IonQ (trapped ion), Rigetti (superconducting), OQC (superconducting), and access to simulators. Pay-per-task pricing on simulators; pay-per-shot on physical hardware with significant per-task overhead charges (~$3 per hardware task plus per-shot costs). The advantage: AWS integration means quantum circuits can be embedded into existing Lambda functions, Step Functions workflows, and data pipelines via the Braket SDK. Good choice if you're already deep in AWS infrastructure.

Azure Quantum

Azure Quantum — Microsoft's platform supporting IonQ, Quantinuum, and Pasqal hardware. Also includes Microsoft's own topological qubit research hardware (still experimental). Azure Quantum is particularly notable for Quantinuum's H-series trapped ion hardware, which has the highest gate fidelity of any publicly accessible hardware. If you need to run circuits that require many sequential gate operations (deep circuits), Quantinuum's low error rates make a practical difference.

Quantum cloud provider comparison: IBM Quantum, AWS Braket, and Azure Quantum side-by-side on hardware types, pricing, and ecosystem

Hardware Modalities: What Matters in Practice

Different hardware technologies have different tradeoff profiles:

Modality Provider Gate Fidelity Connectivity Speed Best For
Superconducting IBM, Rigetti, OQC Good (99.5-99.9%) Limited (nearest-neighbor) Fast (ns gates) General circuits, IBM ecosystem
Trapped Ion IonQ, Quantinuum Excellent (99.9%+) All-to-all Slow (ms gates) Deep circuits, high accuracy
Photonic PsiQuantum (dev) Variable Flexible Speed of light Future networking
Topological Microsoft (experimental) Theoretical TBD TBD Long-term error correction

For learning and algorithm development: start with IBM's free tier and the Aer local simulator. For production research requiring high-accuracy results on deep circuits: evaluate Quantinuum via Azure Quantum.


Developer Action Checklist

Quantum computing touches your work in two ways: as a threat to existing cryptography, and as a future tool for specific problem domains. Here are four concrete steps, ordered by urgency:

flowchart LR A[Step 1\nAudit Encryption] --> B[Step 2\nLearn Qiskit] B --> C[Step 3\nWatch Cloud APIs] C --> D[Step 4\nMonitor Industry] A1[Inventory RSA/ECC usage\nMap data sensitivity\nFlag long-lived keys] --> A B1[IBM Quantum free account\nComplete Qiskit basics course\nRun Bell state circuit] --> B C1[AWS Braket pricing alerts\nAzure Quantum preview access\nIBM Quantum Network news] --> C D1[Follow NIST PQC updates\nWatch IBM/Google announcements\nTrack CRYSTALS adoption] --> D

Step 1: Audit your encryption dependencies (do this now)

Run a cryptographic inventory of your applications. You're looking for: RSA key exchange in TLS configurations, ECDSA in code signing and JWT signing, elliptic curve Diffie-Hellman in key agreement, anything using raw RSA for key wrapping or secret storage. Tools like openssl s_client for TLS auditing, trivy for dependency scanning, and your cloud provider's certificate management dashboards help scope the work. Prioritize by data sensitivity and key lifetime — a 30-day session token is different from a 10-year root CA certificate.

Step 2: Get hands-on with Qiskit (one afternoon)

Create a free IBM Quantum account. Install Qiskit. Run the Bell state circuit from this guide. Then work through the IBM Quantum Learning introductory course — it's free, well-structured, and takes about 4-6 hours to complete. Getting hands-on removes the abstraction layer that makes quantum computing feel mysterious. The circuit model is concrete once you've run real circuits.

Step 3: Watch cloud API developments (ongoing)

All three major cloud providers are actively developing their quantum offerings. AWS Braket integration with existing serverless infrastructure is maturing. Azure Quantum's Quantinuum partnership is producing the highest-fidelity accessible hardware. IBM's Quantum Network gives academic and enterprise access to hardware beyond the free tier. Set up alerts for announcements from these programs — the capabilities available to cloud developers are changing quarterly.

Step 4: Monitor industry adoption signals (ongoing)

The indicators that tell you when quantum computing moves from "interesting" to "operational" for your domain: when major cloud providers offer quantum acceleration as a managed service for specific workloads (similar to how GPU inference appeared), when cryptographic library deprecation notices for RSA/ECC start appearing in mainstream packages, and when quantum chemistry results start appearing in pharmaceutical regulatory filings. The nitrogen fixation milestone suggests we're 3-5 years from the first of these signals for chemistry domains.


Production Considerations: What to Watch

For the small number of developers who are already thinking about quantum-classical hybrid architectures, a few practical notes.

Quantum volume and algorithmic qubits: Raw qubit count is a misleading metric. IBM measures "Quantum Volume" — a benchmark that accounts for qubit count, connectivity, gate fidelity, and circuit depth together. A 20-qubit device with high connectivity and low error rates is more capable than a 50-qubit device with limited connectivity and high error rates. When evaluating hardware for a specific application, look at Quantum Volume and algorithmic qubit counts for your circuit depth, not headline qubit numbers.

Hybrid classical-quantum workflows: No practical quantum application runs purely on quantum hardware. The variational algorithms (VQE, QAOA) that show near-term promise use a quantum device for circuit execution and a classical optimizer to update parameters in a feedback loop. This hybrid architecture means your quantum "application" is actually a classical Python program that periodically dispatches quantum circuit execution tasks to a cloud API. The Qiskit Runtime primitives (Sampler, Estimator) are designed for this pattern.

Cost modeling: Physical hardware time is priced per shot or per task depending on the provider. A VQE calculation that requires 10,000 iterations with 1,000 shots each costs differently across providers. For algorithm development, use local simulators aggressively — Qiskit's Aer simulator runs on your laptop and has no queue. Switch to hardware for validation and for circuits that require real noise characteristics.

Queue management: Free-tier IBM Quantum hardware jobs queue behind other users. Plan for minutes to hours of wall time for a single circuit execution. IBM Quantum Network membership (available through university affiliations and IBM research partnerships) provides dedicated queue access.

Architecture diagram: Hybrid quantum-classical workflow showing classical optimizer loop with quantum circuit execution on cloud hardware

Conclusion

The IBM Heron milestone reframes quantum computing from "promising research technology" to "beginning of the practical era." The 47-years-to-11-minutes result isn't a marketing claim — it's an independently verified computation on a real-world chemistry problem.

For most developers, the immediate action item is cryptographic. The harvest-now-decrypt-later threat means encrypted data you're generating today has a long-horizon confidentiality risk that NIST PQC standards are designed to address. Audit your cryptographic dependencies, prioritize by data sensitivity, and build your migration roadmap now rather than when quantum hardware arrives.

For developers interested in the leading edge: the tools are accessible today. IBM Quantum's free cloud access and Qiskit's Python SDK lower the barrier to experimentation to an afternoon. The IBM Quantum Learning courses are genuinely good and free. The Bell state circuit in this guide is a working starting point.

Watch the companion video for the visual explanation of superposition, entanglement, and the IBM Heron story — it covers the intuition that's hard to convey in text. Subscribe to the AmtocSoft YouTube channel for the ongoing coverage of this space as the hardware continues to evolve.

Quantum computing isn't "someday" anymore. The developer action items are now.


Sources

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-16 · Updated: 2026-04-18 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter

Sunday, April 12, 2026

The Developer's Guide to AI Compliance in 2026: EU AI Act, NIST, and What You Actually Need to Do

Hero image: regulatory compliance framework for AI systems — developer at workstation surrounded by audit documentation and compliance dashboards

Generated with Higgsfield GPT Image — 16:9

Introduction

On August 1, 2024, the EU AI Act entered into force. By February 2025, the rules governing general-purpose AI models (GPAI) were live. As of August 2026 — the full enforcement deadline — any organization deploying high-risk AI systems inside the European Union must demonstrate documented compliance or face fines of up to €30 million, or 6% of global annual turnover.

That deadline is no longer theoretical. It is this year.

Meanwhile, in the United States, NIST released version 1.0 of its AI Risk Management Framework in January 2023, and federal agencies began mandating alignment with it for government contractors. ISO 42001, the international standard for AI management systems, published in December 2023. Boards of directors at Fortune 500 companies are now asking CTOs to explain their AI governance posture — not as a compliance exercise, but as a material risk disclosure.

For most engineering teams, this has arrived faster than expected. Three years ago, "AI governance" sounded like something legal and compliance departments handled after the fact. Today, it is a pre-deployment gate, a procurement requirement, and in some sectors a legal prerequisite to operating at all.

The uncomfortable truth is that the frameworks are complex, often written by lawyers for lawyers, and translate poorly into engineering terms. Most developer guides to AI compliance are either too high-level to be actionable ("document your data pipelines!") or too narrow in scope to address the real scope of what the EU AI Act requires. Engineers implementing RAG pipelines, fine-tuned classifiers, or agentic systems need concrete answers: Does this trigger high-risk classification? What do I actually need to build? What documentation is required before we ship?

This guide answers those questions directly. It covers what the major regulatory frameworks require, how to classify your systems correctly, what you must implement for high-risk systems, and how to integrate compliance into your engineering workflow without making it a bureaucratic nightmare.


The Regulatory Landscape

Four frameworks dominate the conversation in 2026, and while they overlap significantly, each has a distinct scope and jurisdiction. Understanding what each requires — and how they interact — is the foundation of any practical compliance strategy.

EU AI Act: Risk-Tiered Regulation

The EU AI Act is the world's first comprehensive horizontal AI regulation. It applies not just to EU companies, but to any company deploying AI systems whose outputs are used in the EU — which in practice means most large technology companies globally.

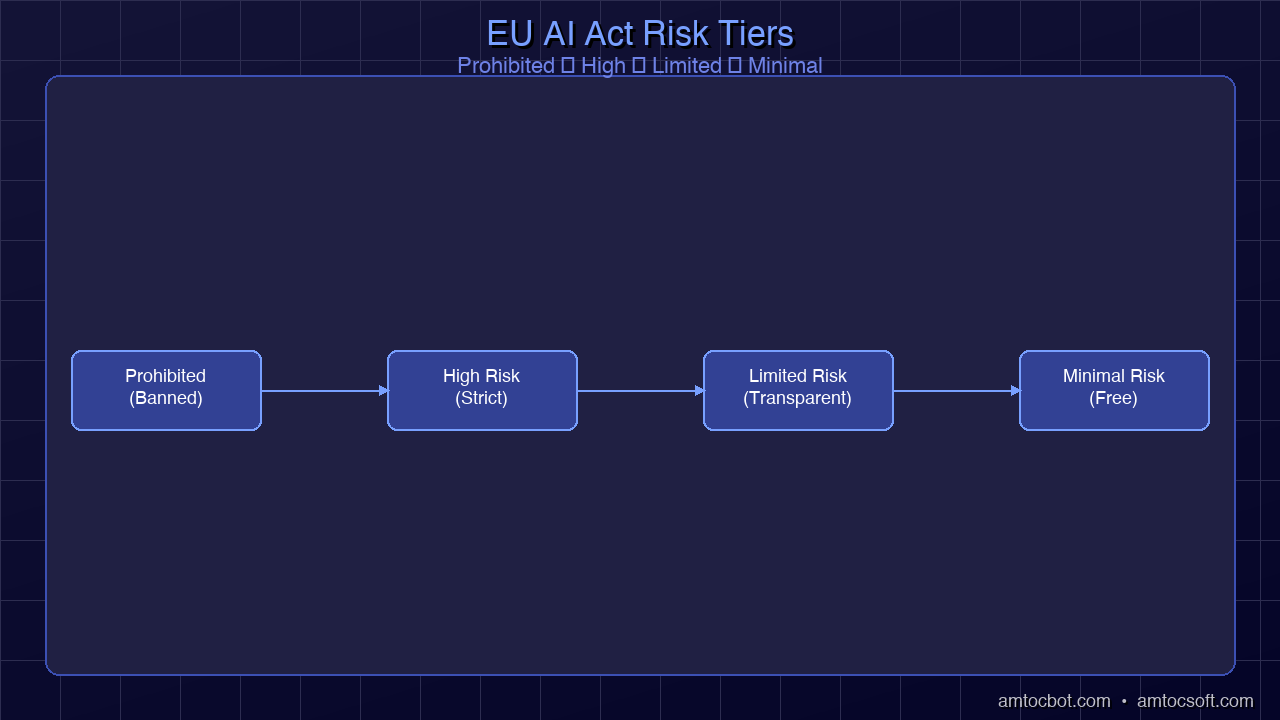
The Act organizes AI systems into four risk tiers:

Unacceptable Risk (Prohibited): These systems are banned outright. The list includes social scoring systems operated by public authorities, real-time remote biometric identification in public spaces (with narrow law enforcement exceptions), AI systems that exploit vulnerable groups, and subliminal manipulation techniques. These prohibitions took effect in February 2025.

High Risk: The category that will consume most engineering compliance effort. High-risk AI systems are permitted but subject to extensive pre-market requirements. The full list lives in Annex III of the Act and covers eight domains: biometric identification and categorization, critical infrastructure management, educational access and assessment, employment and worker management, access to essential private and public services, law enforcement, migration and border control, and administration of justice. High-risk rules fully apply as of August 2026.

Limited Risk: Primarily transparency obligations. AI systems interacting with humans (chatbots, virtual assistants) must disclose that they are AI. Deepfake generators must label output. These are relatively lightweight requirements.

Minimal Risk: Spam filters, AI-enabled video games, recommendation systems — no mandatory requirements, though the Act encourages following voluntary codes of conduct.

General Purpose AI Models (GPAI): A separate tier added to address foundation models. GPAI providers with over 10^25 FLOPs training compute face additional systemic risk requirements. All GPAI providers must publish technical documentation and a summary of training data. These rules took effect in August 2025.

Key enforcement dates to internalize:
- August 2024: Act enters into force
- February 2025: Prohibited systems rules apply; GPAI rules apply
- August 2026: High-risk system requirements fully apply (this is now)
- August 2027: High-risk systems already on the market before August 2026 get a grace period extension in some categories

NIST AI RMF: The US Standard

The National Institute of Standards and Technology AI Risk Management Framework (NIST AI RMF) is voluntary at the federal level but has become a de facto standard for US government contractors, financial institutions, and healthcare organizations. Unlike the EU AI Act, it is not sector-specific — it is a process framework.

The RMF organizes AI risk management into four functions: GOVERN, MAP, MEASURE, and MANAGE. We cover implementation of these in the NIST section below.

ISO 42001: AI Management Systems

Published December 2023, ISO 42001 is to AI what ISO 27001 is to information security: an auditable management system standard. Organizations can pursue certification, which increasingly appears as a procurement requirement in enterprise contracts. ISO 42001 aligns closely with both the EU AI Act and NIST RMF in its requirements for documented policies, roles, and continuous improvement processes.

US Executive Orders and Sector Rules

Executive Order 14110 (October 2023) directed federal agencies to establish standards for AI safety and security, including mandatory red-teaming for dual-use AI systems and reporting requirements for frontier model training runs. The AI Safety Institute within NIST coordinates this work. Sector-specific rules have followed: the FDA has published guidance on AI/ML-based software as a medical device; banking regulators have issued guidance on model risk management that explicitly covers AI. If your system operates in a regulated sector, expect sector rules to layer on top of the horizontal frameworks.

SOC 2 and AI

Auditors conducting SOC 2 Type II reviews are now explicitly asking about AI governance as part of the common criteria. Trust service criteria CC6 (logical and physical access controls) and CC7 (system operations) now include questions about AI-generated decisions and their oversight mechanisms. If your product is AI-powered and you hold SOC 2 certification, expect your next renewal to include questions about model risk, training data governance, and human override mechanisms.

EU AI Act risk classification tiers — from prohibited systems at the top through high, limited, and minimal risk

Generated with Higgsfield GPT Image — 16:9


What Makes a System "High Risk"?

This is the classification question most engineering teams get wrong, and the consequences of misclassification run in both directions. Over-classify and you build expensive compliance infrastructure for systems that don't require it. Under-classify and you ship a non-compliant high-risk system.

The EU AI Act's Annex III defines high-risk AI through eight use-case categories. The key insight is that classification is based on use case and context of deployment, not on the underlying technology. A large language model is not inherently high-risk. That same LLM used to generate resume screening decisions for a Fortune 500 company's hiring process is high-risk.

The eight Annex III categories are:

  1. Biometric identification and categorization: Real-time or post-hoc identification of natural persons from biometric data. Note that emotion recognition systems fall here.
  2. Critical infrastructure: AI managing or operating road traffic, water, gas, electricity, heating, internet infrastructure.
  3. Education and vocational training: Systems determining access to educational institutions, grading, or evaluating students.
  4. Employment and worker management: CV screening, hiring decision support, task allocation, performance monitoring, promotion decisions.
  5. Essential private and public services: Credit scoring, insurance risk assessment, benefits eligibility assessment, emergency services dispatch.
  6. Law enforcement: Risk assessment for criminal recidivism, polygraph equivalents, evidence evaluation, profiling.
  7. Migration, asylum, border control: Risk assessment, document examination, application examination.
  8. Administration of justice: AI assisting courts in legal research, fact-finding, or decision-making.

Common classification mistakes developers make:

Mistake 1: Treating "decision support" as lower risk than "automated decision." The Act does not make this distinction. A system that generates a recommended credit score for a human loan officer to review is high-risk under category 5, the same as a system that automatically approves or denies loans.

Mistake 2: Misreading "biometric" to mean only faces. Biometric data includes gait analysis, voice patterns, behavioral patterns, and physiological measurements. A workplace productivity monitoring tool that tracks typing patterns to flag underperformance hits both category 1 (biometric) and category 4 (employment management).

Mistake 3: Assuming B2B products are out of scope. If your B2B product is used by customers to make high-risk decisions, your product is high-risk. You cannot pass the compliance burden to your customers by putting it in a contract. You are the provider; the requirements apply to you.

Mistake 4: Ignoring the GPAI interaction layer. If your product wraps a GPAI provider and uses it to make high-risk decisions, both the GPAI provider and your system have obligations. You need to understand what your provider's documentation covers and what gaps you need to fill.

graph TD A[AI System in Scope?] -->|Yes| B{Used in EU or affecting EU persons?} A -->|No| Z[No EU AI Act obligations] B -->|No| Z B -->|Yes| C{Does it fall in prohibited categories?} C -->|Yes| D[PROHIBITED — Cannot deploy] C -->|No| E{Annex III use case?} E -->|Biometrics| F[HIGH RISK] E -->|Critical Infrastructure| F E -->|Education/Employment| F E -->|Essential Services| F E -->|Law Enforcement| F E -->|Migration/Justice| F E -->|None of the above| G{Interacts with humans as AI?} G -->|Yes| H[LIMITED RISK — Transparency obligations only] G -->|No| I[MINIMAL RISK — Voluntary codes apply] F --> J[Full Article 9-15 Compliance Required]

What Developers Must Actually Implement

For high-risk systems, Articles 9 through 15 of the EU AI Act define mandatory technical and organizational measures. Here is a concrete breakdown of each requirement and what it means in practice.

1. Risk Management System (Article 9)

You must establish, implement, document, and maintain a risk management system throughout the AI system's entire lifecycle. This is not a one-time risk assessment before launch — it is a continuous process.

In practice: Create a living risk register for your AI system. Document identified risks, their likelihood and severity, the controls you have implemented, and how you verify those controls are working. This needs to be version-controlled and updated with every significant model change, data drift event, or production incident.

2. Data Governance and Management (Article 10)

Training, validation, and test datasets must meet quality criteria relevant to the intended purpose. You must document:
- Data origin, collection method, and preparation steps
- Bias examination and mitigation measures
- How datasets meet the stated use case requirements
- Data handling practices for personal data

In practice: Implement model cards and dataset cards. Run bias evaluations before each model version release. Log training data lineage. For systems using personal data, ensure you have a documented lawful basis and Data Protection Impact Assessment (DPIA).

Model Card Template (YAML frontmatter):

# model-card.yaml
model_id: "credit-risk-classifier-v2.3"
model_type: "gradient_boosted_classifier"
intended_use: "Credit risk assessment for personal loan applications"
out_of_scope_use:
  - "Employment screening"
  - "Insurance underwriting"
  - "Any use outside EU-regulated lending context"

training_data:
  sources:
    - name: "Internal loan performance dataset"
      date_range: "2019-01-01 to 2024-12-31"
      records: 2400000
      geographic_scope: "EU member states"
  preprocessing:
    - "Missing value imputation via median (numerical) and mode (categorical)"
    - "Feature scaling: standard normalization"
    - "Protected attribute removal: age, gender, nationality excluded from features"
  bias_evaluation:
    method: "Disparate impact analysis across age cohorts and geographic regions"
    last_run: "2026-03-15"
    result: "DI ratio 0.87 across all protected cohorts (threshold: >0.80)"

performance:
  metrics:
    auc_roc: 0.847
    precision_at_threshold_0_5: 0.79
    recall_at_threshold_0_5: 0.81
    false_positive_rate: 0.19
  evaluation_dataset: "Holdout set, 2025 Q4, n=48000"
  known_limitations:
    - "Lower recall for applicants with < 12 months credit history"
    - "Performance degrades for applications from regions with < 5000 training samples"

human_oversight:
  override_mechanism: "Loan officer can override any automated decision"
  override_rate_target: "< 5% of decisions escalated"
  escalation_triggers:
    - "Decision confidence < 0.65"
    - "Applicant-requested review"
    - "Edge case detection (out-of-distribution features)"

regulatory_compliance:
  eu_ai_act_classification: "High Risk — Annex III, Category 5b (credit scoring)"
  risk_management_version: "v1.4"
  last_conformity_assessment: "2026-02-20"
  dpia_reference: "DPIA-2025-CR-047"

contacts:
  model_owner: "credit-risk-team@company.com"
  compliance_contact: "ai-governance@company.com"
  last_updated: "2026-04-01"
  version: "2.3.0"

3. Technical Documentation (Article 11)

Before placing a high-risk AI system on the market, you must prepare comprehensive technical documentation demonstrating that the system meets the Act's requirements. Annex IV specifies the required contents: system description and purpose, development process, training data, monitoring plan, risk management records.

In practice: Maintain a System Card alongside your model card. The system card describes the full sociotechnical system — not just the model, but the input pipeline, deployment context, human oversight mechanisms, and feedback loops.

4. Transparency and Audit Logging (Article 13)

High-risk systems must have logging capabilities enabling post-hoc audit of their operation. Logs must cover the period during which the system was in use and must capture enough information to reconstruct any decision.

Audit Logging Pattern (Python):

import json
import hashlib
import time
from dataclasses import dataclass, asdict
from typing import Any, Optional
from datetime import datetime, timezone
import uuid

@dataclass
class AIDecisionRecord:
    """Audit log entry for high-risk AI decisions per EU AI Act Article 13."""
    decision_id: str
    timestamp_utc: str
    system_id: str
    system_version: str
    request_hash: str          # SHA-256 of input features (for reproducibility without storing PII)
    decision_output: str       # The decision rendered
    confidence_score: float
    model_version: str
    input_feature_count: int
    out_of_distribution: bool  # Did OOD detector fire?
    human_override: bool       # Was this decision overridden?
    override_reason: Optional[str]
    processing_time_ms: int
    session_context: dict      # Business context (loan ID, operator ID, etc.)

class AIAuditLogger:
    """
    Compliance-grade audit logger for high-risk AI systems.
    Writes immutable, tamper-evident decision records.
    Complies with EU AI Act Article 13 logging requirements.
    """

    def __init__(self, system_id: str, system_version: str, storage_backend):
        self.system_id = system_id
        self.system_version = system_version
        self.storage = storage_backend  # e.g., append-only S3, BigQuery, Postgres with audit trigger

    def _hash_features(self, features: dict) -> str:
        """Hash input features for reproducibility without storing PII."""
        canonical = json.dumps(features, sort_keys=True, default=str)
        return hashlib.sha256(canonical.encode()).hexdigest()

    def log_decision(
        self,
        features: dict,
        decision: str,
        confidence: float,
        model_version: str,
        out_of_distribution: bool,
        session_context: dict,
        processing_start: float,
    ) -> str:
        """
        Log a single AI decision. Returns decision_id for downstream tracking.
        Call this for every inference that produces a consequential output.
        """
        decision_id = str(uuid.uuid4())
        processing_time_ms = int((time.monotonic() - processing_start) * 1000)

        record = AIDecisionRecord(
            decision_id=decision_id,
            timestamp_utc=datetime.now(timezone.utc).isoformat(),
            system_id=self.system_id,
            system_version=self.system_version,
            request_hash=self._hash_features(features),
            decision_output=decision,
            confidence_score=round(confidence, 6),
            model_version=model_version,
            input_feature_count=len(features),
            out_of_distribution=out_of_distribution,
            human_override=False,  # Updated later if override occurs
            override_reason=None,
            processing_time_ms=processing_time_ms,
            session_context=session_context,
        )

        self.storage.write(asdict(record))
        return decision_id

    def log_override(self, decision_id: str, operator_id: str, reason: str):
        """
        Record that a human operator overrode an AI decision.
        Must be called whenever an override occurs for complete audit trail.
        """
        override_record = {
            "type": "override",
            "decision_id": decision_id,
            "timestamp_utc": datetime.now(timezone.utc).isoformat(),
            "operator_id": operator_id,
            "reason": reason,
        }
        self.storage.write(override_record)

    def log_data_drift_event(self, drift_metrics: dict, alert_level: str):
        """
        Log detected data drift events per Article 9 continuous monitoring.
        """
        drift_record = {
            "type": "data_drift_alert",
            "timestamp_utc": datetime.now(timezone.utc).isoformat(),
            "system_id": self.system_id,
            "alert_level": alert_level,  # "low" | "medium" | "high"
            "metrics": drift_metrics,
        }
        self.storage.write(drift_record)

5. Human Oversight Mechanisms (Article 14)

High-risk AI systems must be designed and developed to allow effective human oversight. This means building explicit override capability, ensuring outputs are interpretable enough for a human to make a meaningful review decision, and defining escalation thresholds.

In practice: Hard requirements are an override UI available to every operator, escalation logic that triggers human review when confidence is below a threshold or when out-of-distribution inputs are detected, and documentation of what operators are trained to look for.

6. Robustness, Accuracy, and Cybersecurity (Article 15)

The system must meet declared accuracy levels consistently across its intended operating range. It must be resilient to input manipulation (adversarial attacks), errors, and inconsistencies. You must implement appropriate cybersecurity measures given the risk profile.

In practice: Adversarial robustness testing before release, data poisoning detection in training pipelines, regular accuracy re-evaluation against production data, and penetration testing of the inference API.

graph LR subgraph Design A[Requirement Analysis] --> B[Risk Classification] B --> C[Model Card Draft] C --> D[DPIA if Personal Data] end subgraph Development D --> E[Training Data Governance] E --> F[Bias Evaluation] F --> G[Model Training] G --> H[Adversarial Testing] H --> I[Model Card Finalize] end subgraph Pre-Deployment I --> J[Conformity Assessment] J --> K[Technical Documentation Complete] K --> L[Human Oversight Integration] L --> M[Audit Logging Enabled] end subgraph Production M --> N[Continuous Monitoring] N --> O{Drift or Performance Degradation?} O -->|Yes| P[Alert + Risk Register Update] P --> Q[Re-evaluation Cycle] Q --> F O -->|No| N end style Design fill:#e8f4f8 style Development fill:#f0f8e8 style Pre-Deployment fill:#fff8e8 style Production fill:#f8e8f0

NIST AI RMF in Practice

The NIST AI Risk Management Framework does not prescribe specific controls — it provides a structured process for identifying and managing AI risks in context. This makes it more flexible than the EU AI Act but also more ambiguous. Here is what the four functions mean in practice.

GOVERN

GOVERN establishes the organizational foundation: policies, roles, culture, and accountability structures for AI risk management. Without GOVERN, MAP, MEASURE, and MANAGE are exercises with no anchor.

What a small team should do: assign a named AI risk owner (this can be the tech lead), document a one-page AI use policy, and establish a minimum review checklist for new AI systems before production deployment.

What an enterprise must do: establish a formal AI governance committee with representation from legal, compliance, engineering, and business; define escalation paths; maintain an inventory of all AI systems in production; publish an external AI use policy; and align AI risk criteria with enterprise risk appetite statements.

MAP

MAP establishes context, identifies stakeholders, and categorizes AI risks across three dimensions: technical risks (model failure modes, distribution shift), operational risks (process gaps, integration failures), and societal risks (bias, fairness, downstream harm).

Practical output of MAP: a risk register with each identified risk labeled by category, likelihood, severity, and current control status. This feeds directly into the EU AI Act's Article 9 risk management system requirement.

MEASURE

MEASURE defines the metrics, benchmarks, and evaluation methods that determine whether risks are at acceptable levels. This is where most teams have the most room to improve: building automated evaluation into CI pipelines rather than doing it manually before major releases.

Metrics to track for a typical high-risk classifier: accuracy, precision/recall by demographic subgroup, false positive and false negative rates, confidence calibration, out-of-distribution detection rate, and model drift indicators (PSI, KS statistic, feature drift).

MANAGE

MANAGE covers the playbooks for responding to AI risk events: incidents, performance degradation, identified bias, adversarial attacks. It also covers the processes for retiring or significantly modifying AI systems.

What distinguishes mature AI risk management: the ability to execute a model rollback in under 30 minutes, a defined SLA for bias report investigation, and documented criteria for when a change to a high-risk system triggers a new conformity assessment.

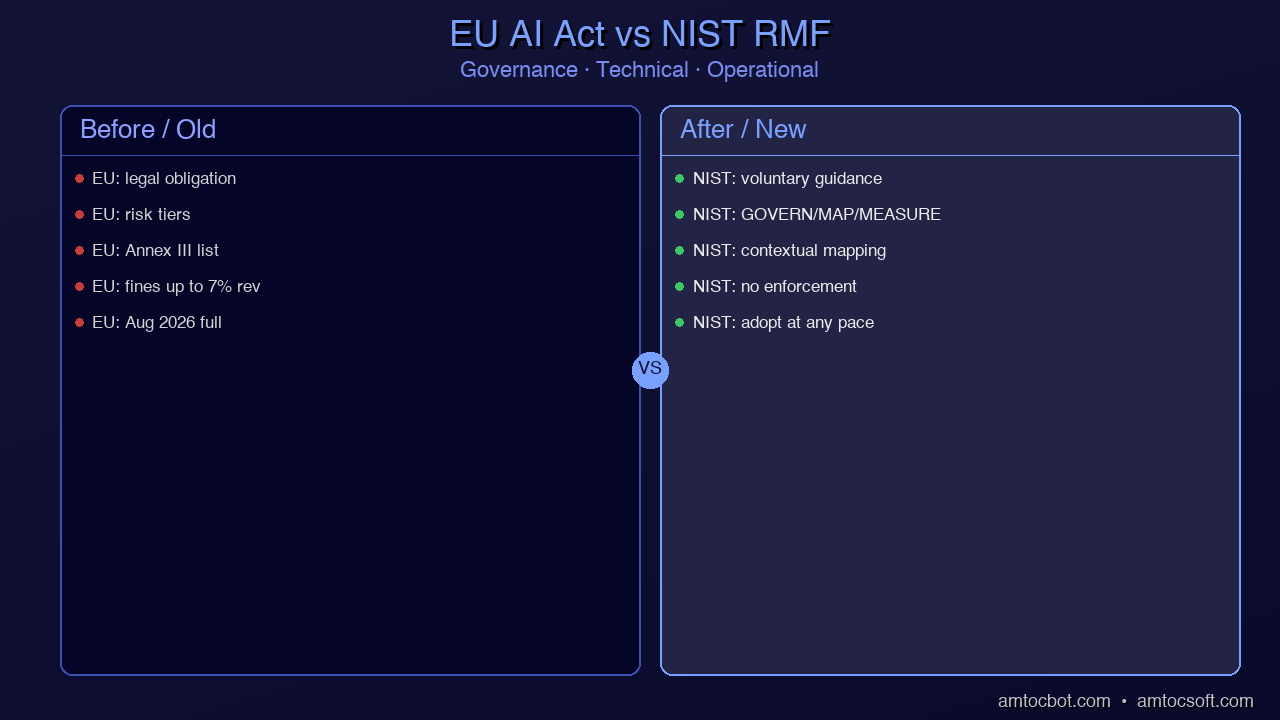
EU AI Act vs. NIST AI RMF — Key Overlaps and Gaps:

Requirement EU AI Act NIST AI RMF
Risk classification Mandatory (Annex III) Recommended (MAP function)
Technical documentation Mandatory (Article 11) Recommended (GOVERN + MAP)
Audit logging Mandatory (Article 13) Recommended (MEASURE)
Human oversight Mandatory (Article 14) Recommended (MANAGE)
Bias evaluation Mandatory (Article 10) Recommended (MEASURE)
Third-party assessment Required for some categories Not required
Geographic scope EU nexus US federal focus, global voluntary
Enforcement mechanism Fines up to 6% global revenue Contract requirements, sector rules
Voluntary certification EU database registration No certification program
EU AI Act vs NIST AI RMF — overlap areas and distinct requirements across governance, technical, and operational dimensions

Generated with Higgsfield GPT Image — 16:9


Building Compliance Into Your SDLC

The worst approach to AI compliance is treating it as a pre-launch checklist. By the time a model is ready to deploy, it is too late to discover that your training data lacks the provenance documentation Article 10 requires. Compliance must be a property of your development process, not your deployment gate.

AI Compliance as Code:

Three concrete practices that integrate compliance into engineering workflow:

1. Automated model card generation. Instead of writing model cards manually, generate them from training metadata. Every training run should emit a structured artifact containing dataset statistics, bias evaluation results, and performance metrics. A CI job assembles these into a versioned model card. The model card is part of the artifact that gets deployed — not a document updated when someone remembers.

2. Bias test CI gates. Bias evaluation is not a one-time pre-launch exercise. It must run on every model version candidate, with a defined threshold that fails the pipeline. A disparate impact ratio below 0.80 on your primary protected attribute cohorts should be a hard gate, not a warning. The threshold should be documented in your risk management system and approved by your AI governance owner.

3. Audit log assertion tests. Every inference code path should have integration tests that verify audit log entries are written correctly. These tests should check that: a log entry is created for every decision, the entry contains all required fields, confidence score is within valid range, and override mechanisms are reachable. If your audit logging code silently fails in production, you have a compliance gap that you will only discover during an audit.

flowchart TD A([Requirement / Feature Request]) --> B[AI Risk Classification Check] B --> C{High Risk?} C -->|Yes| D[DPIA + Annex IV Docs Started] C -->|No| E[Standard Dev Flow] D --> F[Data Governance Review] F --> G[Model Development] E --> G G --> H[Automated Bias Evaluation CI Gate] H -->|PASS| I[Model Card Auto-Generated] H -->|FAIL| J[Block Merge — Fix Bias Issue] J --> G I --> K[Audit Log Integration Tests] K -->|PASS| L[Human Oversight Smoke Test] K -->|FAIL| M[Block Merge — Fix Logging] M --> G L --> N[Conformity Assessment if High Risk] N --> O{Assessment Passed?} O -->|Yes| P[EU Database Registration if Required] O -->|No| Q[Remediation Required] Q --> G P --> R([Deploy to Production]) E --> S[Standard QA + Deploy] S --> R R --> T[Continuous Monitoring Pipeline] T --> U{Drift or Incident?} U -->|Yes| V[Risk Register Update + Alert] V --> W{Material Change?} W -->|Yes| N W -->|No| T U -->|No| T style D fill:#ffe8e8 style F fill:#ffe8e8 style N fill:#ffe8e8 style H fill:#fff8e8 style K fill:#fff8e8 style L fill:#fff8e8

What "compliance as code" looks like in a CI pipeline:

# tests/test_ai_compliance.py
# Run as part of every model deployment CI pipeline

import pytest
import json
from pathlib import Path
from your_model_package import ModelCard, BiasEvaluator, AuditLogger

MODEL_CARD_PATH = Path("artifacts/model-card.yaml")
BIAS_THRESHOLD = 0.80  # Disparate impact ratio minimum
REQUIRED_LOG_FIELDS = [
    "decision_id", "timestamp_utc", "system_id", "system_version",
    "request_hash", "decision_output", "confidence_score", "model_version",
    "out_of_distribution", "human_override"
]

class TestModelCardCompleteness:
    def test_model_card_exists(self):
        assert MODEL_CARD_PATH.exists(), "Model card must be generated before deployment"

    def test_required_fields_present(self):
        card = ModelCard.from_yaml(MODEL_CARD_PATH)
        required = ["model_id", "intended_use", "training_data", "performance",
                    "human_oversight", "regulatory_compliance", "contacts"]
        for field in required:
            assert hasattr(card, field), f"Model card missing required field: {field}"

    def test_out_of_scope_use_documented(self):
        card = ModelCard.from_yaml(MODEL_CARD_PATH)
        assert len(card.out_of_scope_use) > 0, "Model card must document out-of-scope uses"

class TestBiasEvaluation:
    def test_disparate_impact_above_threshold(self, eval_dataset):
        evaluator = BiasEvaluator()
        results = evaluator.evaluate(eval_dataset)
        for cohort, di_ratio in results.disparate_impact.items():
            assert di_ratio >= BIAS_THRESHOLD, (
                f"Bias gate FAILED: cohort '{cohort}' DI ratio {di_ratio:.3f} "
                f"is below threshold {BIAS_THRESHOLD}. "
                f"Investigate before merging."
            )

    def test_bias_evaluation_recency(self):
        card = ModelCard.from_yaml(MODEL_CARD_PATH)
        from datetime import datetime, timezone, timedelta
        last_run = datetime.fromisoformat(card.training_data.bias_evaluation.last_run)
        age_days = (datetime.now(timezone.utc) - last_run.replace(tzinfo=timezone.utc)).days
        assert age_days < 30, f"Bias evaluation is {age_days} days old — must be run within 30 days of deployment"

class TestAuditLogging:
    def test_decision_produces_log_entry(self, mock_storage, sample_features):
        logger = AuditLogger("test-system", "v1.0", mock_storage)
        decision_id = logger.log_decision(
            features=sample_features,
            decision="APPROVED",
            confidence=0.87,
            model_version="v1.0",
            out_of_distribution=False,
            session_context={"application_id": "test-001"},
            processing_start=0.0,
        )
        assert decision_id is not None
        assert len(mock_storage.records) == 1

    def test_log_entry_has_all_required_fields(self, mock_storage, sample_features):
        logger = AuditLogger("test-system", "v1.0", mock_storage)
        logger.log_decision(
            features=sample_features, decision="DENIED", confidence=0.61,
            model_version="v1.0", out_of_distribution=True,
            session_context={}, processing_start=0.0,
        )
        record = mock_storage.records[0]
        for field in REQUIRED_LOG_FIELDS:
            assert field in record, f"Audit log missing required field: {field}"

    def test_override_logging_works(self, mock_storage, sample_features):
        logger = AuditLogger("test-system", "v1.0", mock_storage)
        decision_id = logger.log_decision(
            features=sample_features, decision="DENIED", confidence=0.55,
            model_version="v1.0", out_of_distribution=False,
            session_context={}, processing_start=0.0,
        )
        logger.log_override(decision_id, "operator-007", "Customer appeal — edge case")
        assert len(mock_storage.records) == 2
        override = mock_storage.records[1]
        assert override["type"] == "override"
        assert override["decision_id"] == decision_id

The critical insight here is that compliance test failures should be treated the same as unit test failures: they block merge, they require a fix before deployment, and they are owned by the engineering team — not the compliance team. The compliance team sets the policy; the engineering team implements and verifies it in code.


Conclusion

AI compliance in 2026 is not optional, and it is no longer something you can delegate entirely to legal or compliance functions. The EU AI Act's technical requirements — risk management systems, data governance documentation, audit logging, human oversight mechanisms, robustness testing — are engineering deliverables. They require engineering ownership.

The teams that will handle this best are the ones that treat compliance as architecture: something designed in from the beginning, expressed in code, tested in CI, and continuously verified in production. The teams that will struggle are the ones waiting for a compliance checklist to appear three weeks before an audit.

There is also a competitive angle worth naming directly. Mature AI governance is increasingly a sales differentiator in enterprise markets. Procurement teams at regulated customers — banks, insurers, healthcare systems, public sector organizations — are now asking for model cards, audit logging attestation, and documented human oversight mechanisms before signing contracts. Having this infrastructure in place is not just a compliance cost; it is a trust signal that closes deals.

The frameworks — EU AI Act, NIST AI RMF, ISO 42001 — overlap significantly in their practical requirements. You do not need to build three parallel compliance programs. Build one solid one: risk-classify your systems correctly, document your training data and model behavior, implement audit logging and human override mechanisms, run bias evaluations in CI, and maintain a living risk register. That core program satisfies the lion's share of all three frameworks simultaneously.

Start with the highest-risk systems first. Classify everything in your portfolio. Fix the gaps in documentation and logging for high-risk systems before August 2026 if you haven't already. Then build the compliance-as-code infrastructure so that new systems are compliant by default, not by remediation.

The regulatory moment is here. The engineering response is to make compliance a first-class property of how you build AI systems — not a checkpoint you hit on the way out the door.


Want to go deeper? The EU AI Act full text is at eur-lex.europa.eu. The NIST AI RMF playbook is at airc.nist.gov. The AI Safety Institute's evaluation guidelines are at aisi.gov.uk.

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-12 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter
Bigger Is Not the Same as Better. The Job That Moved Is the Phone, Not the Lab.

Bigger is a plan. The phone is the receipt. The brief for this cycle is a question: does bigger always mean better in AI? The 2026 answer i...