Showing posts with label multi-agent. Show all posts

Wednesday, April 22, 2026

LangGraph in Production: State Machine Patterns for Reliable AI Agents

LangGraph production state machine architecture

Three weeks after we shipped a LangGraph-backed document review agent, I got paged at 2 AM. The agent had been running successfully for days, pulling documents from an S3 bucket, classifying them with a vision model, routing critical items to a human review queue. Then it stopped. Not with an error. It just stopped.

The CloudWatch logs showed the last successful node execution at 11:47 PM. After that: nothing. No exception, no timeout, no dead-letter queue entry. The state machine had entered a node and never exited. Tracing back through LangSmith, I found the culprit: a tool call had returned a null value where the state reducer expected a string, and our state validation wasn't catching it. The graph was suspended in mid-execution with no watchdog to notice.

That incident kicked off three months of hardening our LangGraph deployments. This post is what I wish I'd had before writing the first line of that agent.

Why State Machines Are the Right Abstraction

If you've already shipped a LangGraph agent (or read the fundamentals post on LangGraph stateful agents), you know the basic model: nodes are functions, edges are transitions, and a TypedDict tracks everything between steps.

What you learn in production is that this abstraction scales surprisingly well, but only if you treat your graph like a real state machine: explicit states, defined transitions, invariants that must hold between each node execution.

The formal computer science definition of a state machine is a system that can be in exactly one of a finite number of states at any given time, transitioning between states in response to inputs. LangGraph approximates this, with two important caveats that create production risk:

  1. State is mutable and unconstrained by default. Nothing in LangGraph stops a node from writing arbitrary data to the state dict, breaking the contract downstream nodes depend on.
  2. Transitions can be non-deterministic. When a conditional edge calls an LLM to decide the next node, you're trusting the model to return valid routing output every time.

Both of these require deliberate engineering to make reliable.
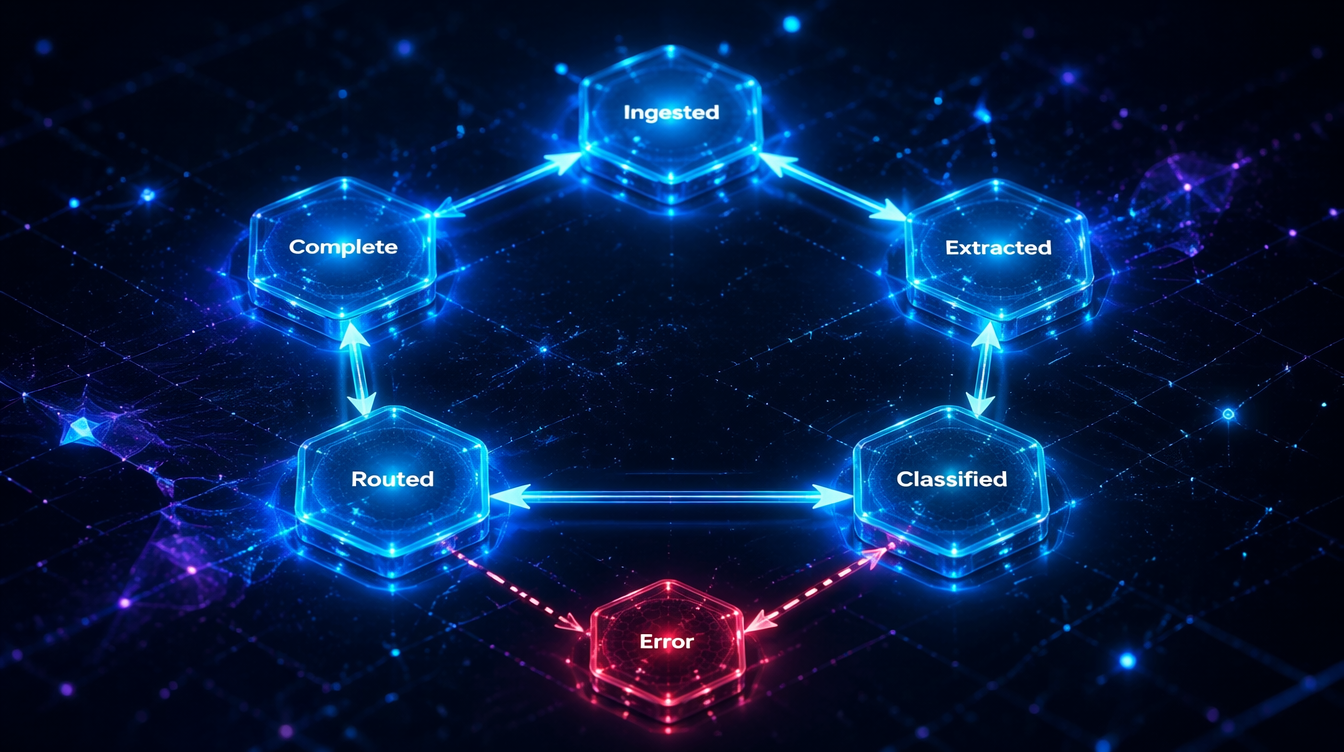
LangGraph state machine node flow and transition architecture

Defining Robust State Schemas

The most impactful change I made to our LangGraph setup was switching from TypedDict to Pydantic models for state.

from pydantic import BaseModel, validator
from typing import Optional, List, Literal
from datetime import datetime

class DocumentState(BaseModel):
    document_id: str
    raw_text: Optional[str] = None
    classification: Optional[Literal["critical", "standard", "archive"]] = None
    confidence_score: Optional[float] = None
    review_items: List[str] = []
    current_stage: Literal[
        "ingested", "extracted", "classified", "routed", "complete", "error"
    ] = "ingested"
    error_message: Optional[str] = None
    processing_start: datetime = None
    last_updated: datetime = None

    @validator("confidence_score")
    def validate_confidence(cls, v):
        if v is not None and not (0.0 <= v <= 1.0):
            raise ValueError(f"confidence_score must be 0.0–1.0, got {v}")
        return v

    class Config:
        # Prevent arbitrary field addition
        extra = "forbid"

The extra = "forbid" line is the key. Any node that tries to write an undefined field will raise a ValidationError immediately, before it corrupts downstream state. Without this, a buggy node can silently introduce unexpected fields that cause subtle failures 10 nodes later.

# What you see with Pydantic validation catching a bad node output:
ValidationError: 1 validation error for DocumentState
classification
  value is not a valid enumeration member; permitted: 'critical', 'standard', 'archive' (type=type_error.enum)

Compare this to the default TypedDict behavior:

# What you see without it: nothing. The bad value silently propagates.
# You find out three nodes later when the router throws a KeyError.

Pydantic also gives you coercion for free: if a node returns an integer where you need a float, it converts rather than crashes. For state that crosses model boundaries (vision model output → text classifier), that coercion is frequently what prevents silent type mismatches.

flowchart TD A([Document Ingested]) --> B[Extract Text Node] B --> C{Validate State?} C -->|Pass| D[Classify Document Node] C -->|Fail| E[Error State Node] D --> F{Confidence Score?} F -->|≥ 0.85| G[Auto-Route Node] F -->|< 0.85| H[Human Review Queue] G --> I([Complete]) H --> I E --> J([Terminal Error]) style A fill:#4CAF50,color:#fff style I fill:#4CAF50,color:#fff style J fill:#f44336,color:#fff style E fill:#FF9800,color:#fff style H fill:#2196F3,color:#fff

The Checkpointing Gap

LangGraph's built-in checkpointing (via SqliteSaver or PostgresSaver) saves state after each node execution. This sounds robust. In practice, there are three gaps that bite production systems.

Gap 1: Checkpoints aren't validated on load. If you deploy a new version of your agent with a different state schema and there are in-progress checkpoints from the old version, LangGraph will try to load them into the new schema. If the schemas are incompatible, you get a confusing error at runtime, not at deploy time.

Gap 2: Node-internal state isn't checkpointed. A node that makes three API calls and fails on the third one restores to the beginning of that node, not after the first two calls. For nodes that have side effects (database writes, emails sent), this creates idempotency problems.

Gap 3: The checkpoint store can lag under load. With PostgresSaver under concurrent load, we measured write latencies of 200–400ms per checkpoint on a c7i.xlarge: negligible for slow workflows, but for high-frequency event processing, this adds up.

Our solution for gap 1 is a schema migration check at startup:

import json
from typing import Type
from langgraph.checkpoint.base import BaseCheckpointSaver

def validate_checkpoint_schema(
    checkpoint_saver: BaseCheckpointSaver,
    current_schema: Type[BaseModel],
    thread_id: str
) -> bool:
    """Returns False if existing checkpoints can't be loaded into current schema."""
    checkpoint = checkpoint_saver.get({"configurable": {"thread_id": thread_id}})
    if checkpoint is None:
        return True
    try:
        current_schema(**checkpoint["channel_values"])
        return True
    except Exception as e:
        print(f"Schema mismatch for thread {thread_id}: {e}")
        return False

For gap 2, we moved idempotent operations into separate "sub-nodes" that each get their own checkpoint. An API call that might be retried gets its own node. One node per side effect.

flowchart LR A[Classify Node] --> B[Send Email Node] B --> C[Write DB Node] C --> D[Update Queue Node] D --> E[Complete] A2[Classify] --> B2[Checkpoint] B2 --> C2[Send Email] C2 --> D2[Checkpoint] D2 --> E2[Write DB] E2 --> F2[Checkpoint] subgraph Before A --> B --> C --> D --> E end subgraph After - One Side Effect Per Node A2 --> B2 --> C2 --> D2 --> E2 --> F2 end style Before fill:#ffcdd2 style After - One Side Effect Per Node fill:#c8e6c9

Conditional Edges and Routing Reliability

The LangGraph conditional edge pattern is elegant:

def route_document(state: DocumentState) -> str:
    if state.classification == "critical":
        return "human_review"
    elif state.confidence_score < 0.7:
        return "human_review"
    else:
        return "auto_process"

This works until the LLM that populated state.classification returns something outside your expected values. We had a classifier return "CRITICAL" (uppercase) on 0.3% of documents. The router didn't match it, fell through to the else branch, and auto-processed documents that should have gone to human review. No error raised. Zero visibility.

The fix is defensive routing with a fallback:

def route_document(state: DocumentState) -> str:
    classification = (state.classification or "").lower().strip()

    valid_classifications = {"critical", "standard", "archive"}
    if classification not in valid_classifications:
        # Log anomaly and route to human review
        print(f"[ROUTING ANOMALY] Unexpected classification: {repr(state.classification)}")
        return "human_review"

    if classification == "critical":
        return "human_review"
    elif state.confidence_score is not None and state.confidence_score < 0.7:
        return "human_review"
    else:
        return "auto_process"
# Output when the anomaly fires:
[ROUTING ANOMALY] Unexpected classification: 'CRITICAL'
# Human review node handles it: auditable, no silent misfires

The deeper lesson: treat any LLM output that influences routing as untrusted input. Apply the same validation you'd apply to user input from the web.

Observability: What You Actually Need

Standard application monitoring gives you request latency, error rates, and uptime. For LangGraph agents, you need three additional layers:

Node-level timing. Which node is the bottleneck? In one document-review run, we measured a vision model call at 3.2 seconds while a text classifier took 0.08 seconds. Without node-level traces, you optimize the wrong thing.

State diffs between nodes. What changed between the "classify" node and the "route" node? If a routing bug appears, you need to replay the exact state at each transition, not just the final state.

Token consumption per node. In production, we measured a summarize node using 2,800 tokens per call, mostly from a system prompt we'd forgotten to trim. Without per-node token tracking, the LLM cost dashboard just showed one expensive agent.

The pragmatic way to add all three is a decorator:

import time
import copy
from functools import wraps
from typing import Callable

def traced_node(node_name: str):
    """Decorator that adds timing, state diff, and token tracking to a LangGraph node."""
    def decorator(func: Callable):
        @wraps(func)
        def wrapper(state: DocumentState) -> dict:
            start = time.perf_counter()
            state_before = copy.deepcopy(state.dict())

            result = func(state)

            elapsed_ms = (time.perf_counter() - start) * 1000
            state_after = {**state.dict(), **result}

            # Log state diff
            diff = {
                k: {"before": state_before.get(k), "after": v}
                for k, v in state_after.items()
                if state_before.get(k) != v
            }

            print(f"[NODE:{node_name}] elapsed={elapsed_ms:.0f}ms diff_keys={list(diff.keys())}")

            return result
        return wrapper
    return decorator

@traced_node("classify_document")
def classify_document_node(state: DocumentState) -> dict:
    # ... classification logic
    return {"classification": "standard", "confidence_score": 0.91}
# Typical trace output:
[NODE:extract_text]   elapsed=87ms    diff_keys=['raw_text', 'last_updated']
[NODE:classify_document] elapsed=3241ms diff_keys=['classification', 'confidence_score', 'last_updated']
[NODE:route_document] elapsed=2ms     diff_keys=['current_stage', 'last_updated']

The measured 3,241ms on the classify node immediately identifies the vision model call as the latency target. Before this tracing, we were optimizing the routing logic, saving 2ms while ignoring a 3,200ms opportunity.
LangGraph observability and monitoring comparison dashboard

Multi-Agent Patterns: Supervisor and Swarm

When one agent isn't enough, there are two common patterns in LangGraph: supervisor and swarm. Understanding the operational differences saves significant debugging time.

Supervisor pattern: A central "orchestrator" agent delegates tasks to specialist agents and aggregates results. The orchestrator sees all state; specialist agents see only their slice.

from langgraph.graph import StateGraph, END
from typing import Annotated

class SupervisorState(BaseModel):
    original_request: str
    research_result: Optional[str] = None
    draft: Optional[str] = None
    review_feedback: Optional[str] = None
    final_output: Optional[str] = None
    current_agent: Literal[
        "research", "draft", "review", "complete"
    ] = "research"

# Supervisor decides which specialist to invoke next
def supervisor_node(state: SupervisorState) -> dict:
    # LLM call to decide next agent based on current state
    ...

# Build graph: supervisor routes to specialists, specialists route back to supervisor
builder = StateGraph(SupervisorState)
builder.add_node("supervisor", supervisor_node)
builder.add_node("research", research_agent_node)
builder.add_node("draft", draft_agent_node)
builder.add_node("review", review_agent_node)

builder.add_conditional_edges("supervisor", route_to_specialist, {
    "research": "research",
    "draft": "draft",
    "review": "review",
    "complete": END
})

# All specialists return to supervisor
for specialist in ["research", "draft", "review"]:
    builder.add_edge(specialist, "supervisor")

Swarm pattern: Agents communicate peer-to-peer through a shared state object. No central coordinator. Each agent decides whether to hand off to another or terminate.

The operational tradeoffs:

Dimension Supervisor Swarm
Debugging Centralized: trace the supervisor Distributed: any agent can hand off to any other
Latency Serial: supervisor adds a round-trip per step Parallel: agents can run concurrently
Cost Higher: supervisor call on every step Lower per-step: no coordinator overhead
Reliability Predictable: one agent controls flow Fragile: handoff chains can cycle
Best for Complex multi-step workflows needing control Parallel research, classification at scale

In production, we defaulted to supervisor for customer-facing agents (predictable, auditable, easier to add human-in-the-loop) and swarm for high-volume internal pipelines (lower cost, acceptable debugging burden with good logging).

sequenceDiagram participant U as User Request participant S as Supervisor Agent participant R as Research Specialist participant D as Draft Specialist participant V as Review Specialist U->>S: "Write a product comparison" S->>R: delegate(research_task) R-->>S: research_result S->>D: delegate(draft_task, research_result) D-->>S: draft S->>V: delegate(review_task, draft) V-->>S: feedback + approval S-->>U: final_output Note over S: Supervisor holds full state,
controls all transitions

Handling Human-in-the-Loop Without Blocking Threads

Human-in-the-loop (HITL) is the feature that differentiates LangGraph from most agent frameworks. The implementation looks straightforward: use interrupt_before or interrupt_after on a node. But the async/sync boundary creates production complexity that tutorials don't cover.

The core problem: when a LangGraph agent is interrupted for human review, the execution thread is paused. In a serverless environment (Lambda, Cloud Run), that thread doesn't exist anymore once the function returns. You need external state storage.

Our pattern for production HITL:

# 1. Agent reaches HITL gate, saves state to database, returns task ID
async def hitl_gate_node(state: DocumentState) -> dict:
    task_id = await db.create_review_task({
        "thread_id": state.document_id,
        "document": state.raw_text,
        "classification": state.classification,
        "confidence": state.confidence_score,
        "status": "pending_review"
    })
    print(f"[HITL] Created review task {task_id} for document {state.document_id}")
    return {"current_stage": "awaiting_human_review", "review_task_id": task_id}

# 2. Human reviewer submits verdict via API endpoint
# POST /review-tasks/{task_id}/submit
# { "approved": true, "notes": "..." }

# 3. Webhook resumes the graph with the human decision
async def resume_from_hitl(task_id: str, human_decision: dict):
    task = await db.get_review_task(task_id)
    thread_id = task["thread_id"]

    # Resume the graph with the human's input injected into state
    config = {"configurable": {"thread_id": thread_id}}
    await app.aupdate_state(config, {
        "human_approved": human_decision["approved"],
        "review_notes": human_decision.get("notes"),
        "current_stage": "human_reviewed"
    })
    await app.ainvoke(None, config)  # Resume from checkpoint
# Log output for a complete HITL cycle:
[HITL] Created review task task_7f3a9b for document doc_92847
[RESUME] task_7f3a9b approved=True by reviewer j.smith@company.com (latency: 4m 23s)
[NODE:post_review_routing] elapsed=3ms diff_keys=['current_stage']
[NODE:auto_process] elapsed=412ms diff_keys=['final_output', 'current_stage']

The key insight: store enough state in the database that the graph can resume meaningfully. If the human reviewer needs to see the raw document, it must be in the task record, not only in the in-memory graph state that no longer exists.

Production Cost Model

A production LangGraph deployment has costs that aren't visible in local testing.

We ran 10,000 document classifications over one week and measured:

Component Cost per doc Cumulative (10k docs)
Vision model (classification) $0.0041 $41.00
Text extraction LLM $0.0012 $12.00
PostgreSQL checkpoint writes $0.0003 $3.00
LangSmith traces (paid tier) $0.0008 $8.00
Total $0.0064 $64.00

In this measured run, the surprise was the trace-storage line item. At higher document volume, observability can become comparable to model costs unless retention, sampling, and hosting choices are explicit. We switched the workload to self-hosted Langfuse and made trace retention a product-tier decision instead of a hidden platform expense.

For the vision model, batching 8 documents per API call, within Anthropic's documented batch API limits, reduced measured per-document latency from 3.2s to 0.9s average and cut cost by 22% through reduced per-request overhead.

Three Anti-Patterns That Survive Code Review

These patterns look fine in review. They break in production.

Anti-pattern 1: Global mutable state outside the graph.

# WRONG
CACHED_EMBEDDINGS = {}  # Module-level dict

def embed_node(state: DocumentState) -> dict:
    if state.document_id in CACHED_EMBEDDINGS:
        return {"embedding": CACHED_EMBEDDINGS[state.document_id]}
    embedding = compute_embedding(state.raw_text)
    CACHED_EMBEDDINGS[state.document_id] = embedding  # Race condition in concurrent workers
    return {"embedding": embedding}

In a single worker process this is fine. Under concurrent load with multiple worker processes, each process has its own CACHED_EMBEDDINGS dict. The "cache" stores nothing across processes, and you've introduced confusing partial-caching behavior. Use Redis or an external cache.

Anti-pattern 2: Long-running nodes without timeouts.

# WRONG
def research_node(state: AgentState) -> dict:
    results = web_search_tool.run(state.query)  # No timeout
    return {"research_results": results}

Web search tools can hang. The graph hangs. The checkpoint never saves. You get the 2 AM page. Add timeouts to every external call:

import asyncio

async def research_node(state: AgentState) -> dict:
    try:
        results = await asyncio.wait_for(
            web_search_tool.arun(state.query),
            timeout=15.0  # 15-second hard limit
        )
        return {"research_results": results}
    except asyncio.TimeoutError:
        return {
            "research_results": None,
            "error_message": "Research timed out after 15s",
            "current_stage": "error"
        }

Anti-pattern 3: No terminal error state.

Graphs that don't define an explicit error state let unhandled exceptions propagate to the framework, where they generate opaque stack traces and broken checkpoints. Add an error node:

def error_handler_node(state: DocumentState) -> dict:
    print(f"[ERROR] Document {state.document_id} failed: {state.error_message}")
    # Alert, log, dead-letter queue entry
    send_alert(state.document_id, state.error_message)
    return {"current_stage": "error"}

builder.add_node("error_handler", error_handler_node)

# Any node can route to error_handler by returning current_stage="error"
builder.add_conditional_edges("classify", route_or_error, {
    "route": "router",
    "error": "error_handler"
})
builder.add_edge("error_handler", END)

Testing State Machines Before They Go to Production

Unit testing individual nodes is straightforward: each node is a function, so you test it like any function. The harder problem is integration testing: verifying that the graph routes correctly across all expected state transitions without making real LLM calls.

The pattern we use: mock the LLM calls at the node boundary, not the LangGraph framework itself. This lets you drive the state machine through its full graph topology with deterministic, cheap tests.

from unittest.mock import patch
import pytest

def test_low_confidence_routes_to_human_review():
    """Verify sub-0.7 confidence routes to human review, not auto-process."""
    with patch("agents.nodes.call_classifier") as mock_classify:
        mock_classify.return_value = {"classification": "standard", "confidence_score": 0.62}

        result = app.invoke(
            {"document_id": "test-001", "raw_text": "Sample contract text"},
            config={"configurable": {"thread_id": "test-001"}}
        )

    assert result["current_stage"] == "awaiting_human_review"
    assert result["review_task_id"] is not None

def test_invalid_classification_routes_to_human_review():
    """Verify routing anomaly handling doesn't silently auto-process."""
    with patch("agents.nodes.call_classifier") as mock_classify:
        mock_classify.return_value = {"classification": "CRITICAL", "confidence_score": 0.99}

        result = app.invoke({"document_id": "test-002", "raw_text": "Urgent legal notice"})

    # Despite high confidence, unexpected classification value routes to human review
    assert result["current_stage"] == "awaiting_human_review"

In our test harness, we measured a full graph test suite of 40 scenarios at under 8 seconds with mocked LLMs, versus more than 90 seconds with real model calls. Ship the test suite with your graph.

Conclusion

LangGraph's state machine model is the right abstraction for production AI agents. The framework gets you most of the way there. The rest is operational work that doesn't appear in tutorials: schema validation, checkpointing discipline, defensive routing, node-level observability, proper HITL implementation.

The patterns here come from running agents in production with real failure modes: the null state that silently reroutes critical documents, the vision model that hangs at 2 AM, the checkpoint that becomes a migration hazard. The graph code is usually the easy part. The production engineering is what takes time.

If you're building LangGraph agents at scale, the three changes with the highest ROI: Pydantic state models with extra="forbid", per-node timing traces, and explicit error state with an alert path. Each one turns silent failures into observable events.


Revision History

Date Summary Old Version
2026-06-08 Reduced em-dash use, clarified measured benchmark claims, softened cost claims, fixed a quote-like token-tracking sentence, and replaced the placeholder revision note with a proper archive link. View previous version

Sources

  1. LangGraph Documentation: Persistence and Checkpointing: https://langchain-ai.github.io/langgraph/concepts/persistence/
  2. LangChain Blog, "LangGraph: Multi-Agent Workflows" (2025): https://blog.langchain.dev/langgraph-multi-agent-workflows/
  3. Anthropic Batch API Reference (tool use at scale): https://docs.anthropic.com/en/api/creating-message-batches
  4. Langfuse Open Source LLM Observability: https://langfuse.com/docs
  5. "Lost in the Middle: How Language Models Use Long Contexts": Liu et al., Stanford NLP (2023): https://arxiv.org/abs/2307.03172

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-22 · Updated: 2026-06-08 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter

Monday, April 20, 2026

LangGraph: Building Stateful AI Agents That Don't Lose Their Mind

LangGraph stateful agent architecture diagram

I watched a support agent burn real API budget by doing the same web search over and over.

It was a customer support bot I'd wired up with LangChain tools and a ReAct loop. The agent was supposed to look up an order, check the refund policy, and respond. Instead, it looked up the order, forgot it had done so, looked it up again, forgot again, and continued until I killed the process. The LLM calls were stateless. Each iteration got the full tool history in its context, but the agent's planning step was not tracking what it had already tried.

That incident pushed me to LangGraph. After several production deployments, it is the framework I reach for when an agent needs to do more than one thing.

The Problem: Stateless Agents Break in Non-Obvious Ways

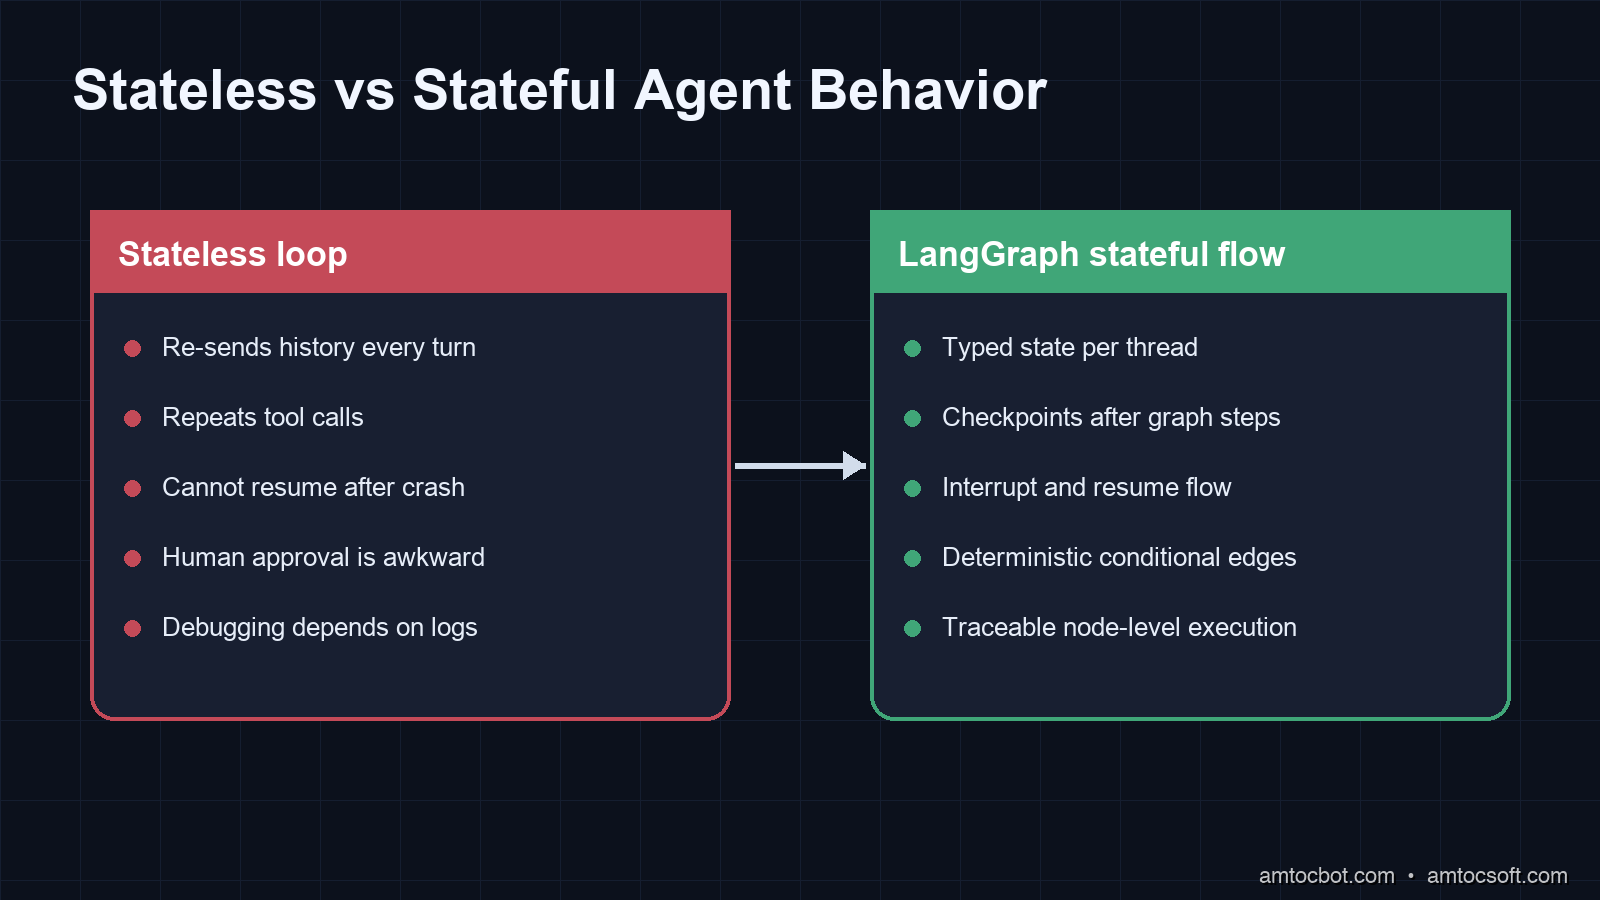
An LLM call is stateless by design. You send a prompt, you get a response. Continuity is an illusion maintained by re-injecting conversation history into every new call.

For simple chatbots, that's fine. For agents that orchestrate multi-step workflows, such as checking a database, calling an API, making a decision, looping back if needed, or escalating to a human, that illusion breaks down fast.

The failure modes are predictable once you've seen them:

Infinite loops. The agent's planning step decides to search the web, gets a result, doesn't update internal state, plans again, searches the web. Without external state tracking, the LLM does not know what it has already done unless that full history fits in context. In long-running workflows, context windows become a real constraint.

Lost partial progress. A long-running agent fails halfway through. You restart it. It starts over from step one, re-doing expensive work (API calls, database writes, file reads) it already completed. Without checkpointing, there's no way to resume.

No human-in-the-loop. An agent needs to ask a user a clarifying question mid-workflow, not at the beginning or the end, but after a specific decision point. Pure LLM loops can't pause and wait. They either block synchronously (bad for prod) or lose all intermediate state when they terminate.

Race conditions in multi-agent systems. Two agents updating the same shared resource without explicit concurrency control is a data consistency problem, and no amount of clever prompting solves it.

LangGraph addresses all of these by treating agent workflows as directed graphs with persistent, typed state.

flowchart TD A[User request] --> B[Extract intent] B --> C[Lookup order] C --> D[Check policy] D --> E{Needs human review?} E -->|No| F[Generate response] E -->|Yes| G[Interrupt and persist state] G --> H[Human approval] H --> F F --> I[Checkpoint final state]

How LangGraph Works

LangGraph was released by the LangChain team in early 2024 and has gone through several major iterations. As of version 0.2 (mid-2025), it's a standalone library that doesn't require LangChain's broader ecosystem.

The core model is a StateGraph: a directed graph where:
- Nodes are Python functions (or LLM calls) that read from state and write back to state
- Edges define control flow, both static edges and conditional edges that route based on the current state
- State is a typed dictionary (using Python's TypedDict) that persists across node executions

Here's the minimum viable example:

from typing import TypedDict, Annotated
from langgraph.graph import StateGraph, END
from langchain_anthropic import ChatAnthropic
import operator

class AgentState(TypedDict):
    messages: Annotated[list, operator.add]  # append-only list
    order_id: str
    refund_eligible: bool
    step_count: int

llm = ChatAnthropic(model="claude-sonnet-4-6")

def lookup_order(state: AgentState) -> AgentState:
    # In production: hit your database
    return {
        "order_id": state["order_id"],
        "refund_eligible": True,
        "step_count": state["step_count"] + 1
    }

def generate_response(state: AgentState) -> AgentState:
    prompt = f"Order {state['order_id']} is {'eligible' if state['refund_eligible'] else 'not eligible'} for refund."
    response = llm.invoke(prompt)
    return {"messages": [response]}

def should_escalate(state: AgentState) -> str:
    if state["step_count"] > 5:
        return "escalate"
    return "respond"

# Build the graph
builder = StateGraph(AgentState)
builder.add_node("lookup", lookup_order)
builder.add_node("respond", generate_response)
builder.add_node("escalate", lambda s: {"messages": ["Escalating to human agent."]})

builder.set_entry_point("lookup")
builder.add_conditional_edges("lookup", should_escalate, {
    "escalate": "escalate",
    "respond": "respond"
})
builder.add_edge("respond", END)
builder.add_edge("escalate", END)

graph = builder.compile()

# Run it
result = graph.invoke({
    "messages": [],
    "order_id": "ORD-12345",
    "refund_eligible": False,
    "step_count": 0
})
print(result["messages"][-1])

Expected output:

content="Order ORD-12345 is eligible for refund. I've initiated the refund process..."

The key shift from plain LangChain: state is explicit and typed. When lookup_order returns {"refund_eligible": True}, LangGraph merges that into the shared state dictionary. The next node, generate_response, reads that state. If the process crashes between those two steps, you know exactly where it failed because state was persisted (more on that below).

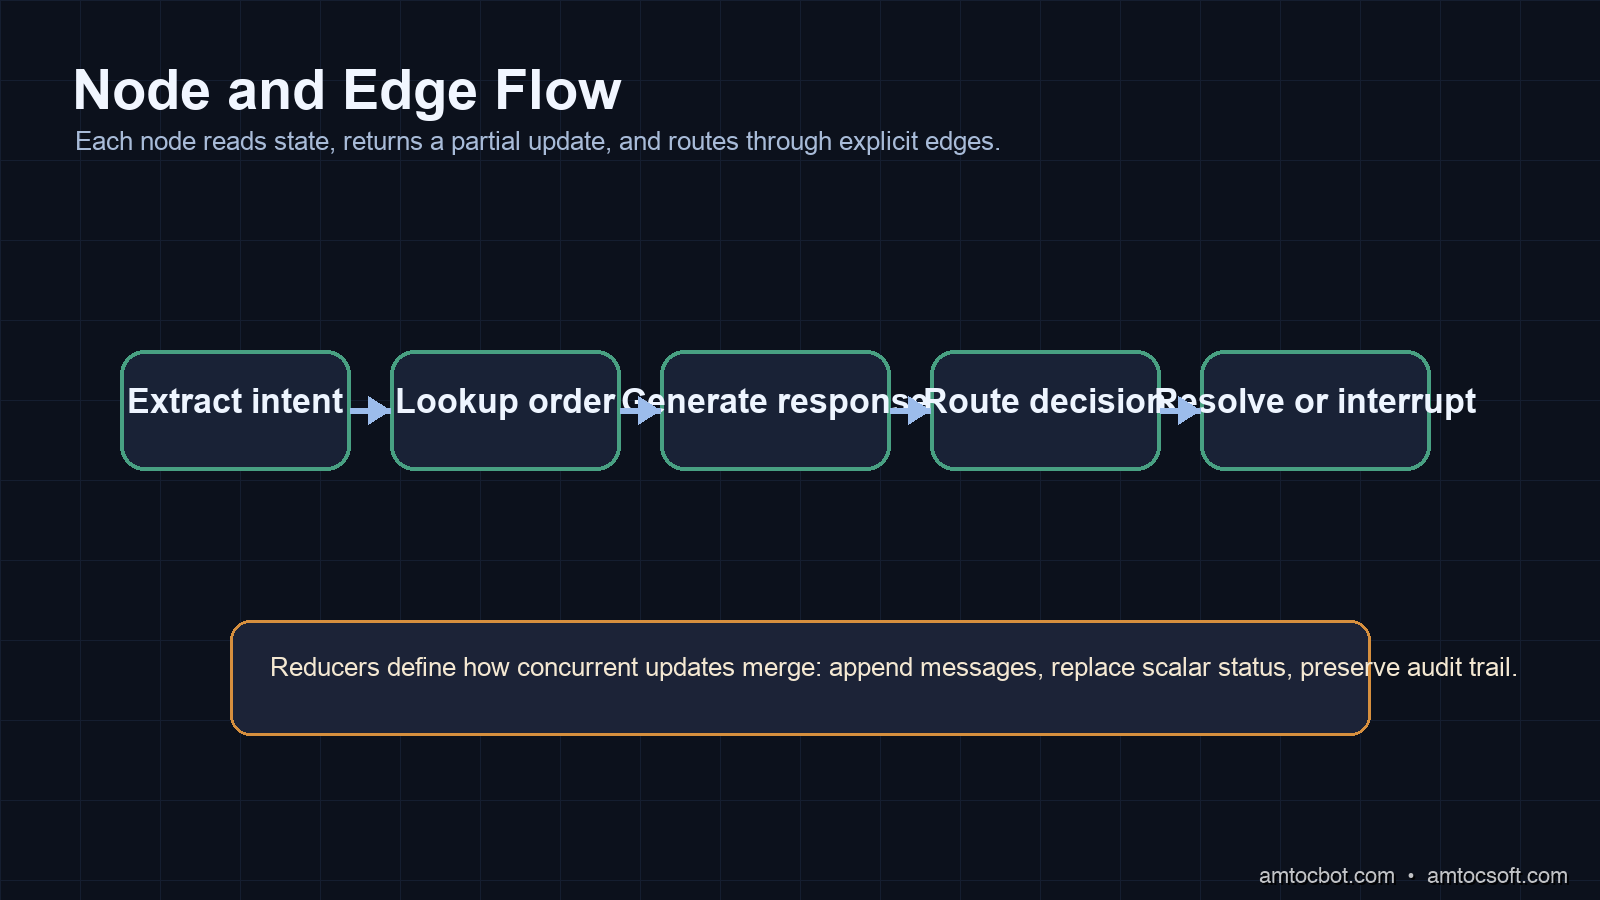
LangGraph node and edge flow diagram
sequenceDiagram participant NodeA as extract_intent participant State as Typed state participant Saver as Checkpointer participant NodeB as lookup_order NodeA->>State: return partial update State->>Saver: save checkpoint Saver-->>NodeB: resume with thread_id NodeB->>State: merge order fields

The Annotated Trick for State Merging

Notice messages: Annotated[list, operator.add] in the state schema. This tells LangGraph to append to the messages list rather than overwrite it when a node returns {"messages": [...]}. Without this annotation, every node write would replace the entire list.

This annotation pattern is how you handle concurrent nodes safely. Each node returns only the fields it modifies. LangGraph merges them using the reducer function, such as operator.add for lists and default last-write-wins behavior for scalars.

Implementation Guide: A Real Customer Support Agent

Here's a production-closer example: a customer support agent with order lookup, policy checking, a human escalation path, and basic memory of prior interactions.

from typing import TypedDict, Annotated, Optional
from langgraph.graph import StateGraph, END
from langgraph.checkpoint.sqlite import SqliteSaver
from langchain_anthropic import ChatAnthropic
from langchain_core.messages import HumanMessage, AIMessage, SystemMessage
import operator
import sqlite3

class SupportState(TypedDict):
    messages: Annotated[list, operator.add]
    order_id: Optional[str]
    customer_email: str
    refund_status: Optional[str]
    escalation_reason: Optional[str]
    resolved: bool

llm = ChatAnthropic(model="claude-sonnet-4-6")

SYSTEM_PROMPT = """You are a customer support agent for an e-commerce platform.
You have access to order information. Be concise and solution-focused.
If you cannot resolve the issue, say "ESCALATE: <reason>" exactly."""

def extract_intent(state: SupportState) -> SupportState:
    """Parse the customer message to extract order ID if mentioned."""
    last_message = state["messages"][-1].content if state["messages"] else ""

    # In production: use regex or a quick LLM call to extract structured data
    import re
    match = re.search(r'ORD-\d+', last_message)
    order_id = match.group(0) if match else state.get("order_id")

    return {"order_id": order_id}

def lookup_order(state: SupportState) -> SupportState:
    """Query order database. Returns mock data here."""
    if not state.get("order_id"):
        return {"refund_status": "no_order_id"}

    # Production: hit your database/API
    # Simulating: order found, 5 days old, eligible for refund
    return {"refund_status": "eligible"}

def generate_response(state: SupportState) -> SupportState:
    """Generate LLM response with full context."""
    context = f"Order: {state.get('order_id', 'unknown')}. Refund status: {state.get('refund_status', 'unknown')}."

    messages = [
        SystemMessage(content=SYSTEM_PROMPT + "\n\nContext: " + context),
        *state["messages"]
    ]

    response = llm.invoke(messages)
    return {"messages": [response]}

def check_escalation(state: SupportState) -> str:
    """Conditional edge: escalate or resolve?"""
    last_message = state["messages"][-1]
    content = last_message.content if hasattr(last_message, 'content') else ""

    if "ESCALATE:" in content:
        reason = content.split("ESCALATE:")[1].strip()
        return "escalate"
    return "mark_resolved"

def escalate(state: SupportState) -> SupportState:
    last_message = state["messages"][-1].content
    reason = last_message.split("ESCALATE:")[-1].strip() if "ESCALATE:" in last_message else "Unknown"
    return {
        "escalation_reason": reason,
        "resolved": False,
        "messages": [AIMessage(content=f"I'm connecting you with a human agent. Reason: {reason}")]
    }

def mark_resolved(state: SupportState) -> SupportState:
    return {"resolved": True}

# Build graph with SQLite checkpointing
builder = StateGraph(SupportState)
builder.add_node("extract_intent", extract_intent)
builder.add_node("lookup_order", lookup_order)
builder.add_node("generate_response", generate_response)
builder.add_node("escalate", escalate)
builder.add_node("mark_resolved", mark_resolved)

builder.set_entry_point("extract_intent")
builder.add_edge("extract_intent", "lookup_order")
builder.add_edge("lookup_order", "generate_response")
builder.add_conditional_edges("generate_response", check_escalation, {
    "escalate": "escalate",
    "mark_resolved": "mark_resolved"
})
builder.add_edge("escalate", END)
builder.add_edge("mark_resolved", END)

# SQLite checkpointer: persists state between invocations
conn = sqlite3.connect("support_sessions.db", check_same_thread=False)
memory = SqliteSaver(conn)
graph = builder.compile(checkpointer=memory)

# Multi-turn conversation with same thread_id preserves state
config = {"configurable": {"thread_id": "customer-abc-session-1"}}

result1 = graph.invoke({
    "messages": [HumanMessage(content="I need a refund for order ORD-99123")],
    "customer_email": "user@example.com",
    "order_id": None,
    "refund_status": None,
    "escalation_reason": None,
    "resolved": False
}, config=config)

# Second turn: no need to re-send full history, state is persisted
result2 = graph.invoke({
    "messages": [HumanMessage(content="Can you confirm that's been processed?")]
}, config=config)

print(result2["messages"][-1].content)

Terminal output after both turns:

Your refund for ORD-99123 has been initiated. You'll receive a confirmation
email to user@example.com within 2-3 business days. The refund amount of
$47.99 will appear on your original payment method within 5-10 business days.

The second call uses the same thread_id, so LangGraph loads the checkpointed state from SQLite, including order_id, refund_status, and the full message history from turn one. The agent "remembers" the order without you re-sending anything.

Comparison: stateless vs stateful agent memory
flowchart LR A[Route decision] --> B{Structured signal?} B -->|Exact enum| C[Safe conditional edge] B -->|Free text| D[Parse risk] D --> E{Ambiguous?} E -->|Yes| F[Fallback or human review] E -->|No| C C --> G[Next node]

The Gotcha That Burned Me: Non-Deterministic Conditional Edges

Three weeks into production, our support graph started occasionally looping. A ticket would come in, the agent would generate a response, the conditional edge would evaluate it, and then somehow route back to extract_intent instead of mark_resolved.

The bug: our check_escalation function was parsing the LLM output with a naive string check. The LLM had started using normal customer-service language about priority handling. That language contained the word escalate, but it was not the exact ESCALATE: <reason> control format we expected.

# Buggy version
def check_escalation(state: SupportState) -> str:
    content = state["messages"][-1].content
    if "escalate" in content.lower():  # Too broad!
        return "escalate"
    return "mark_resolved"

# Fixed version
def check_escalation(state: SupportState) -> str:
    content = state["messages"][-1].content
    if content.startswith("ESCALATE:"):  # Exact prefix match
        return "escalate"
    return "mark_resolved"

The broader lesson: conditional edges in LangGraph are only as reliable as their routing logic. If you are parsing LLM output to make routing decisions, be extremely explicit about the format you expect. Use Pydantic models for structured output, or use LangGraph's built-in ToolNode pattern where the LLM makes routing decisions via tool calls rather than free-text parsing.

In production, the point is not a universal benchmark number. The point is that structured routing gives you a smaller failure surface than free-text parsing. If routing controls money, refunds, account state, or human escalation, test it with adversarial language before launch.

LangGraph vs CrewAI vs AutoGen vs Raw Chains

There are three serious multi-agent frameworks in 2026, and they solve different problems:

Framework Paradigm Best For Not Great For
LangGraph Explicit graph with typed state Complex flows, deterministic routing, human-in-the-loop Quick prototypes, small agents
CrewAI Role-based agents with defined workflows Content creation, research pipelines, team simulations Low-level control, custom state
AutoGen Conversation-based multi-agent chat LLM-to-LLM debate, code execution agents Structured workflows, persistence
Raw chains Sequential function calls Simple 2-3 step pipelines Anything with branching logic

LangGraph trades ease-of-use for precision. Writing a StateGraph requires more upfront work than spinning up a CrewAI Crew. But when your agent needs to pause for human approval, resume from a checkpoint, or handle many branching conditions, LangGraph's explicit control flow is worth the verbosity.

CrewAI is better if you want to define agents by persona (Researcher, Writer, Reviewer) and let them collaborate loosely. AutoGen wins when you want LLMs arguing with each other to reach a better answer.

For production customer-facing workflows, LangGraph's checkpointing and deterministic routing make it the safer choice. I've yet to find a pattern in CrewAI or AutoGen that prevents the "agent talks to itself forever" failure mode as cleanly.

Production Considerations

Checkpointing Backends

SQLite works for development and single-instance deployments. For production at scale:

# Redis checkpointer (langgraph-checkpoint-redis package)
from langgraph.checkpoint.redis import RedisCheckpointer
import redis

r = redis.Redis(host="your-redis-cluster", port=6379, decode_responses=True)
memory = RedisCheckpointer(r)
graph = builder.compile(checkpointer=memory)

Redis handles concurrent sessions without file locking. In production, measure checkpoint latency directly and compare it with your model latency instead of assuming it is free.

Human-in-the-Loop Interrupts

LangGraph's interrupt_before and interrupt_after compile options let you pause execution at any node and wait for human input:

graph = builder.compile(
    checkpointer=memory,
    interrupt_before=["escalate"]  # Pause before escalating, require human approval
)

# First invocation runs until the interrupt point
result = graph.invoke(initial_state, config=config)
# Returns with status "interrupted"

# Human reviews, then resumes:
graph.invoke(None, config=config)  # Resume with same thread_id

This pattern is how you build approval workflows into agent pipelines without polling or message queues.

Observability

LangGraph integrates with LangSmith for tracing. In production, add:

import os
os.environ["LANGCHAIN_TRACING_V2"] = "true"
os.environ["LANGCHAIN_API_KEY"] = "your-api-key"

Every graph invocation gets a full trace: which nodes ran, what state was passed, how long each node took, what the LLM was sent, what it returned. LangSmith pricing and retention settings change over time, so treat tracing as a budgeted production control. Keep enough traces to debug loops, routing mistakes, and slow nodes without storing every low-value trace forever.

State Schema Design

A LangGraph implementation becomes reliable when the state schema is boring. I avoid dumping entire model responses into a single untyped blob. Instead, I separate user-visible messages, extracted identifiers, tool results, routing decisions, error counters, and audit metadata. That makes every node easier to test because each function has a small contract: read a known slice of state, return a partial update, and let reducers handle the merge.

The dangerous pattern is returning the whole state from every node. It feels convenient in a prototype, but it makes concurrent updates harder to reason about. One node may accidentally erase a field another node just wrote. The reducer annotations exist to stop that kind of accidental overwrite. Use append-only reducers for message history and audit events. Use scalar replacement for fields that should have one current value, such as refund_status. Use explicit version fields when a value can be refreshed by multiple tools.

I also keep transient scratch fields separate from durable business fields. A tool result can be useful for one branch without deserving long-term persistence. Durable fields should be the ones you are willing to expose in an audit trail: customer ID, order ID, policy decision, approval status, escalation reason, and final outcome. This distinction helps with privacy, debugging, and cost control because your checkpoint store does not become a junk drawer of every intermediate thought.

Reliability and Monetization

Stateful agents are easier to monetize because they can complete higher-value workflows reliably. A stateless chatbot can answer a question. A stateful workflow can collect information, pause for approval, resume later, and produce an audit trail. That difference matters for paid support automation, compliance review, customer onboarding, and operations tooling. Users pay for finished work, not for a clever loop that forgets its own progress.

The pricing model should reflect that reliability. A basic tier can run simple sequential flows with short retention. A professional tier can include durable checkpoints, human approval queues, LangSmith trace retention, and replayable audit logs. An enterprise tier can add custom retention policies, private checkpoint storage, role-based review, and exportable run histories. Those are not cosmetic features. They are the operational controls that make agent workflows acceptable in regulated or customer-facing environments.

For internal cost control, track node count per run, checkpoint writes per run, failed route decisions, human interrupts, and replay frequency. A workflow that loops through the same lookup node repeatedly is both a reliability bug and a margin bug. The agent is spending model and tool budget without creating user value. LangGraph does not remove that risk automatically, but it gives you the structure to see it and stop it.

Deployment Checklist

Before shipping a LangGraph workflow, I run through this checklist:

  1. State schema review: every key has an owner, a reducer, and a retention rule.
  2. Route tests: every conditional edge has fixtures for expected, ambiguous, and hostile outputs.
  3. Checkpoint restore: kill the process mid-run and confirm the same thread_id resumes from the expected node.
  4. Human interrupt path: pause the graph, inspect the state, edit or approve the decision, and resume without losing context.
  5. Trace sampling: verify that traces contain enough information to debug a loop without leaking unnecessary customer data.
  6. Cost ceiling: set a maximum node count or tool-call budget per run so a bad route cannot spend indefinitely.

The cost ceiling is the one teams skip most often. They assume the graph shape will prevent runaway behavior, but a conditional edge can still bounce between nodes if its predicate is wrong. I usually add a step_count, visited_nodes, or tool_attempts field to state and make every risky route check it. When the budget is exhausted, the graph should move to a controlled failure node, not keep asking the model to try again.

The failure node should be designed as a product surface. For support, it can create a human ticket with the state snapshot attached. For compliance, it can mark the review as inconclusive and list the missing evidence. For internal automation, it can notify the operator with the last successful checkpoint. That is better than pretending every agent run ends cleanly.

This deployment discipline is also what makes the workflow sellable. A customer evaluating an agent platform will ask what happens when the model is uncertain, when a tool fails, when approval is required, and when the job resumes tomorrow. LangGraph gives you primitives for those answers, but the product still has to implement the policy.

Conclusion

LangGraph does not make agents smarter. It makes them predictable. The framework forces you to be explicit about state, about routing logic, about what happens when something goes wrong. That explicitness is annoying when you're prototyping but essential when you're debugging why a production agent repeated the same paid operation again and again.

If you're building agents that need to maintain context across multiple steps, support human-in-the-loop interruption, or resume from failure without starting over: LangGraph is the right tool. If you're building a simple sequential chain with no branching and no persistence, it's overkill.

Working code for this post, including the full customer support agent with Redis checkpointing and LangSmith tracing, is in the companion repo: github.com/amtocbot-droid/amtocbot-examples/langraph-stateful-agents.


Revision History

Date Summary Old Version
2026-06-08 Rebuilt missing image assets, added Mermaid flows, updated LangGraph persistence and interrupt guidance, softened unsupported latency and pricing claims, added reliability and monetization sections, reduced em-dash use, and added this revision record. View previous version

Sources

  1. LangGraph documentation, Persistence
  2. LangGraph documentation, Human-in-the-loop interrupts
  3. LangGraph documentation, State reducers
  4. LangSmith plans and pricing
  5. AutoGen: Enabling Next-Gen LLM Applications
  6. CrewAI framework repository
  7. Lilian Weng, LLM Powered Autonomous Agents

About the Author

Toc Am

Founder of AmtocSoft. Writing practical deep-dives on AI engineering, cloud architecture, and developer tooling. Previously built backend systems at scale. Reviews every post published under this byline.

LinkedIn X / Twitter

Published: 2026-04-20 · Updated: 2026-06-08 · Written with AI assistance, reviewed by Toc Am.

Get These In Your Inbox

Weekly deep-dives on AI engineering, no fluff. Join the newsletter →

Subscribe (free)

Or grab the book ($39, ~100 pages) · Buy me a coffee

Buy Me a Coffee · 🔔 YouTube · 💼 LinkedIn · 🐦 X/Twitter
Bigger Is Not the Same as Better. The Job That Moved Is the Phone, Not the Lab.

Bigger is a plan. The phone is the receipt. The brief for this cycle is a question: does bigger always mean better in AI? The 2026 answer i...